

Parsing Models Overview
A Document Pre-Trained Transformer (DPT) is the model that powers the parsing capabilities of the ADE Parsing APIs. The DPT identifies document layouts and chunks, then generates descriptive explanations (captions) for those chunks.Availability
The ability to select a Document Pre-Trained Transformer is available:- in the Playground
- when calling the ADE Parse or Parse Jobs APIs
- when using the Python and TypeScript libraries
Model Versions and Snapshots
The following table lists the availablemodel values for the ADE Parse and ADE Async Parse API:
The
dpt-1 and dpt-2-mini models are deprecated. Use dpt-2 instead.Why Model Versioning Matters
When integrating the API, you have two options for specifying the model:- Use a general model name (like
dpt-2ordpt-2-latest) to always get the newest version. This automatically give you improvements and updates, but parsing results may change when new model versions are released - Use a specific snapshot (like
dpt-2-20250919) to pin to an exact model version. This keeps parsing results consistent until the snapshot is retired or migrated, but you won’t receive improvements.
dpt-2 in production, your application may produce different results when we release model updates. Consider whether you need consistent results or prefer to receive the latest improvements.
Understanding Snapshots and -latest
Snapshots are versions of a model released on specific dates. A snapshot keeps the same parsing behavior until it is retired or migrated to a newer snapshot. For the current migration, go to dpt-2-20260903. The latest suffix points to the current default snapshot of that model. The default is not always the newest snapshot. For example,dpt-2-latest does not point to dpt-2-20260903 until your organization moves.
DPT-2
DPT-2 was introduced in September 2025. It builds upon an earlier model, and offers these advanced features:- Agentic Table Captioning: DPT-2 can parse large, complex, no-gridline, and merged-cell tables with unprecedented fidelity. Every cell is preserved, aligned, and made accessible—enabling cell-level grounding so you know exactly where values came from.
- Refined Figure Captioning: Logos, seals, and small figures are now identified precisely and concisely, eliminating the noise of verbose descriptions.
- Smarter Layout Detection: Fewer chunks are missed, even in messy scans. DPT-2 can even detect stamps inside tables and process them separately—critical for compliance workflows.
- Expanded Chunk Ontology: Beyond text, tables, and figures, DPT-2 now recognizes attestation (signatures, stamps, seals), ID cards, logos, barcodes, and QR codes—ensuring all document elements are classified consistently. To learn more, go to Chunk Types.
dpt-2-20260903
Thedpt-2-20260903 snapshot runs DPT-2 on an updated underlying model. One of our third-party model providers is retiring the model that earlier snapshots use, so every organization moves to this snapshot.
- Output close to earlier snapshots: The snapshot is tuned to match earlier DPT-2 output. Some documents return different text or table formatting.
- No confidence scores: The
confidencefield in the Parse response isnull.
When Your Organization Moves
Organizations on subscription and enterprise plans move todpt-2-20260903 on October 7, 2026. After your organization moves, dpt-2, dpt-2-latest, and every pinned DPT-2 snapshot run on dpt-2-20260903.
Until then, dpt-2 and dpt-2-latest do not change. To test your own documents first, set model to dpt-2-20260903.
dpt-2-20260410
Thedpt-2-20260410 snapshot builds on previous DPT-2 snapshots with these improvements:
- Improved cell parsing in forms and tables: Text positioned at different locations within a cell is now captured more completely.
- Improved column alignment in complex tables: Cell data now more accurately aligns with its corresponding column headers.
dpt-2-20260302
Thedpt-2-20260302 snapshot builds on previous DPT-2 snapshots with several improvements, including:
- Table boundary detection: Tables that were previously split into multiple chunks are now correctly identified as a single table.
- Improved large table accuracy: Large tables are now parsed more accurately.
- Special characters returned as Unicode: Characters such as asterisks are now returned as their Unicode characters (for example,
*) rather than as spelled-out strings likeasterisk.
DPT-2 Availability
The DPT-2 can be used in these API endpoints:Set the Model in the API
When calling the ADE Parse or ADE Parse Jobs endpoint, you can set the model using themodel parameter.
If you omit the model parameter, the API will use the latest snapshot of the dpt-2 model.
For example, run the command below to use the latest snapshot of DPT-2.
Set the Model with the Library
When using the ade-python library, you can set the model using themodel parameter in the parse() function.
If you omit the model parameter, the library will use the latest snapshot of the dpt-2 model.
For example, use this code to parse a document with the latest snapshot of DPT-2:
Set the Model in the Playground
The Playground’s Model drop-down defaults to DPT-3 Pro, the ADE Gen2 model. To select a DPT-2 parsing model instead:- Open a project in the Playground.
- Click the Parse tab.
- In the top-right corner of the parse result panel, click Config.
- From the Model drop-down, select the model you want to use.
- Click Re-run all files.
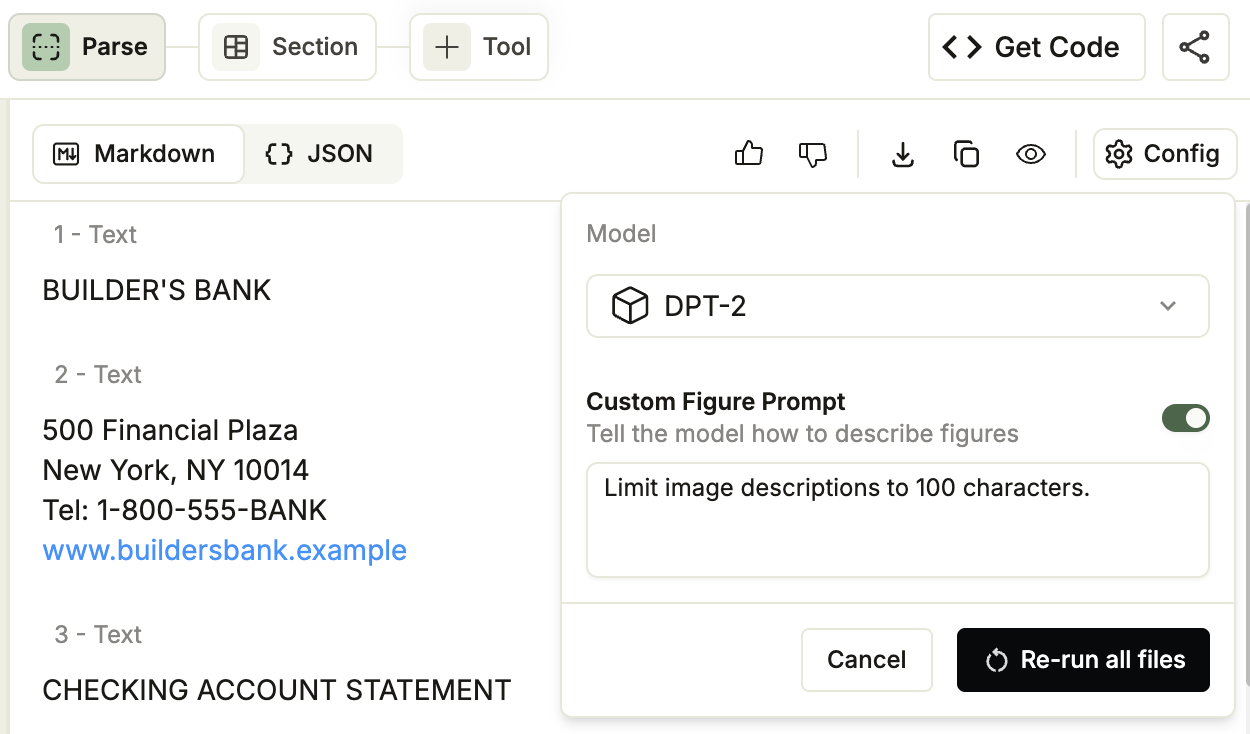
Switching the model re-parses every file in the project. If you switch back to a model that was already applied to the project, the Playground reuses the cached parse results instead of re-parsing.