# LandingAI > Documentation for Agentic Document Extraction (ADE), LandingAI's document intelligence platform that converts documents into structured data. # Home Source: https://docs.landing.ai/index

Parse Documents with Agentic Document Extraction

Learn how to get started with [Agentic Document Extraction](https://ade.landing.ai/).
Make your first API call: parse a document and get structured Markdown back. Upload a document in your browser to see results immediately. No code required.
## Use ADE in Your Code
Parse and extract your own documents from the terminal, and script them into a pipeline. Teach your coding agent to parse, extract, and build document pipelines with ADE. Parse, extract, and handle results from Python. Parse, extract, and handle results from TypeScript. Integrate using the Parse API. Drive ADE from an AI coding agent with the CLI, skills, and the docs MCP server.
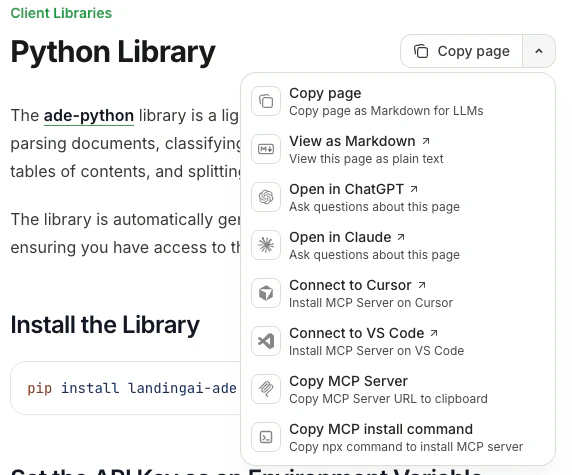
# Overview Source: https://docs.landing.ai/dpt3/overview Learn how ADE converts documents into structured data and when to use the Parse, Extract, and Ground APIs. [Agentic Document Extraction](https://ade.landing.ai/) (ADE) is a document intelligence platform that converts documents into reliable, structured data. Use the structured data to build retrieval-augmented generation (RAG) applications, power intelligent search systems, extract key information, and automate document processing. ADE is powered by the **DPT-3** family of models, built for the era of AI agents and agentic workflows and designed around feedback from users running document-intensive workloads. ## How ADE Works Agentic Document Extraction provides three APIs for document processing: [Parse](./parse), [Extract](./extract), and [Ground](./ground). Most workflows start with **Parse**, which converts a document into structured data. After parsing, you can use **Extract** to pull specific data fields from the Markdown, and **Ground** to map each extracted field back to its location on the page. | API | Description | When to Use | | -------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------- | | [Parse](./parse) | Converts PDFs, images, and Office text documents and presentations into reading-order Markdown, a hierarchical structure of pages and blocks, and per-block grounding. | Use to convert documents into structured data for downstream applications, such as RAG, search, and agents.

Most workflows start here. | | [Extract](./extract) | Pulls specific data fields from Markdown using schema-based extraction. | Use when you need the values of specific fields.

Works best on Parse output. | | [Ground](./ground) | Maps each extracted field back to the blocks it was quoted from, returning block ids, page numbers, and bounding boxes. | Use when you need to highlight, cite, or review where extracted values appear on the page.

Runs on Parse and Extract output. | Parse and Extract each run as [synchronous requests or async jobs](./sync-async). Use [Parse Jobs](./parse-async) and [Extract Jobs](./extract-async) for large files and background pipelines. Ground always runs synchronously and consumes no credits. ## Key Capabilities * **Designed for agent systems.** Built around how downstream AI agents consume document data: semantic block ids, predictable hierarchy, and Markdown ranges so you can map results back to source. * **Hierarchical layout model.** The structured output is a nested hierarchy: pages, blocks on each page, and cells within tables. * **Fine-grained visual grounding.** Bounding boxes for every block, plus per-line or per-word boxes through each block's atomic grounding, so you can highlight or extract content at the line or word level. * **Clean, standardized Markdown.** Structured figure elements with classification labels, bracketed attestation and scan-code labels, and standardized checkboxes. ## Important to Know * Parse supports **PDFs, images, and Office text documents and presentations** (DOCX, PPTX, ODT, RTF). Spreadsheets (XLSX, CSV) and legacy binary Office files (DOC, PPT) are not supported; for those, use [Parse Gen1](/ade/parse). See [Supported File Types](./file-types). * **Password-protected files** are not supported. Decrypt the file and submit an unencrypted copy. * Upgrading from ADE Gen1? The endpoints and response shapes changed. See the [Migration Guide](./migration-guide). ## Find What You Need Pick a starting point based on what you want to do. See Parse in action without writing code. Upload a file in your browser. Make your first API call: parse a document and get structured Markdown back. Understand the response shape: pages, blocks, and grounding. Parse and extract your own documents from the terminal, with results saved on your machine. # Quickstart Source: https://docs.landing.ai/dpt3/quickstart Parse your first document as a Parse Job on the standard tier and get structured Markdown back. Get started with the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse) by parsing a sample customer due diligence form. You submit the document as a [Parse Job](./parse-async), then collect a structured Markdown rendering of it, ready for downstream workflows like RAG, search, or extraction. If you would rather not write the request yourself, the [CLI Quickstart](/cli/quickstart) gets the same result in two commands. ## Prerequisites * An Agentic Document Extraction [account](https://ade.landing.ai/) * An [API key](./agentic-api-key) ## Tutorial: Parse a Document The library reads your [API key](./agentic-api-key) from the `VISION_AGENT_API_KEY` environment variable. ```bash macOS/Linux theme={null} export VISION_AGENT_API_KEY="" ``` ```cmd Windows (Command Prompt) theme={null} set "VISION_AGENT_API_KEY=" ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY="" ``` Install the [ade-python](https://github.com/landing-ai/ade-python) library. ```bash theme={null} pip install landingai-ade ``` The `wait` method polls the job for you and returns it once it reaches a terminal state. Save the code block below as `parse.py`. ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document_url="https://docs.landing.ai/examples/kyc-form.pdf", service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id, raise_on_failure=True) with open("markdown-kyc-form.md", "w") as f: f.write(done.result.markdown) ``` Run the file you created. The script saves the parsed Markdown to `markdown-kyc-form.md` in the current directory. ```bash theme={null} python3 parse.py ``` The library reads your [API key](./agentic-api-key) from the `VISION_AGENT_API_KEY` environment variable. ```bash macOS/Linux theme={null} export VISION_AGENT_API_KEY="" ``` ```cmd Windows (Command Prompt) theme={null} set "VISION_AGENT_API_KEY=" ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY="" ``` Install the [ade-typescript](https://github.com/landing-ai/ade-typescript) library. ```bash theme={null} npm install landingai-ade ``` The `wait` method polls the job for you and returns it once it reaches a terminal state. Save the code block below as `parse.ts`. ```typescript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document_url: "https://docs.landing.ai/examples/kyc-form.pdf", service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id, { raiseOnFailure: true }); const parsed = done.result as LandingAIADE.V2ParseResponse; if (!parsed.markdown) { throw new Error(`Job ${job.job_id} returned no Markdown (status: ${done.status}).`); } fs.writeFileSync("markdown-kyc-form.md", parsed.markdown); ``` Run the file you created. The script saves the parsed Markdown to `markdown-kyc-form.md` in the current directory. ```bash theme={null} npx tsx parse.ts ``` Install [jq](https://jqlang.org/), a free third-party command-line tool that reads values out of the JSON responses. Some common install instructions are below; to see all installation methods, go to the [jq site](https://jqlang.org/download/). ```bash Mac theme={null} brew install jq ``` ```bash Windows theme={null} winget install jqlang.jq ``` ```bash Linux theme={null} sudo apt-get install jq ``` Submit the document and capture the `job_id` from the response into a shell variable. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key). ```bash theme={null} JOB_ID=$(curl -s -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document_url=https://docs.landing.ai/examples/kyc-form.pdf' \ -F 'service_tier=standard' | jq -r .job_id) ``` The request returns a `202` response carrying the `job_id`, the job's status, and its creation time: ```json theme={null} { "job_id": "parse-01m1cn0y1k88schxxtgz97vpw2", "status": "pending", "created_at": "2026-08-31T19:34:01.015456+00:00" } ``` Fetch the job and save the response to `parse-output.json`. Re-run this command until `status` reads `completed`. If it reads `failed`, stop and check the `error` field for the reason. ```bash theme={null} curl -s "https://api.ade.landing.ai/v2/parse/jobs/$JOB_ID" \ -H 'Authorization: Bearer YOUR_API_KEY' > parse-output.json jq -r .status parse-output.json ``` A finished job nests the parse output under `result`, so the Markdown is at `.result.markdown`. Save it to a file called `markdown-kyc-form.md`. ```bash theme={null} jq -r .result.markdown parse-output.json > markdown-kyc-form.md ``` ## Use the Markdown Open `markdown-kyc-form.md`. It holds the form as reading-order Markdown, ready for a RAG application, a search index, or an LLM prompt. To pull named fields out of it instead, pass it to [Extract](./extract). ## What's Next Understand the response shape in depth: pages, blocks, and grounding. Pull named fields out of this Markdown with a schema. See how credit usage is calculated per page. Status codes, errors, and how to resolve them. # Build with AI Agents Source: https://docs.landing.ai/ade/build-with-ai-agents Use ADE with AI agents and LLMs: run the ade CLI, install ADE skills, connect the MCP server, and access docs as llms.txt. Use Agentic Document Extraction (ADE) with AI agents, LLMs, and coding tools like Claude Code. If you're an AI agent or LLM, run the [ade CLI](#the-ade-cli) to do the work, and install the [ADE skills](#skills) or connect the [MCP server](#mcp-server-for-documentation) for compact, token-efficient access to ADE. This page covers: * [The ade CLI, which agents can drive directly](#the-ade-cli) * [ADE skills for AI coding agents](#skills) * [A documentation MCP server](#mcp-server-for-documentation) * [Shortcuts for connecting AI tools to docs pages](#shortcuts-for-connecting-ai-tools) * [Documentation pages in llms.txt format](#access-documentation-pages-as-llms-txt) * [Documentation pages as Markdown](#access-documentation-as-markdown) ## The ade CLI The [ade CLI](/cli/quickstart) parses documents and extracts fields from the command line. It ships as one self-contained binary, so there is no SDK or language runtime to install. Running `ade help --json` returns the whole command surface as a single JSON object, so an agent reads every command, flag, and exit code once instead of guessing at arguments. In an agent harness, set the `ADE_API_KEY` environment variable for credentials. See [Authentication](/cli/authentication) for the alternatives, and [Scripting and Automation](/cli/scripting-automation) for the payload shapes, exit codes, and free re-runs that make a retry safe. ## Skills Skills are instruction files that teach AI coding agents how to use Agentic Document Extraction effectively. LandingAI offers ADE skills in the [ADE Document Processing Skills](https://github.com/landing-ai/ade-document-processing-skills) repository. ### Install Skills via the Claude Code Plugin Claude Code users can install the ADE skills as a plugin, which is an extension that bundles skills, agents, and other capabilities. Run the following commands in Claude Code to install the ADE skills plugin: ```bash theme={null} /plugin marketplace add landing-ai/ade-document-processing-skills /plugin install ade-document-processing@ade-document-processing-skills ``` After installation, run the following command to activate the plugin: ```bash theme={null} /reload-plugins ``` ### Install Skills with Other Methods Different AI coding tools have different methods for installing skills. Check the documentation for your AI coding tool to learn how to install skill files. Depending on the installation method, you may need to download or clone the [ADE Document Processing Skills](https://github.com/landing-ai/ade-document-processing-skills) repository and copy the skill files to the relevant directories. ## MCP Server for Documentation The ADE MCP server connects AI tools to Agentic Document Extraction documentation and [ADE skills](#skills). When connected, your agent can search the documentation and access all ADE skills without additional setup. **MCP server URL:** `https://docs.landing.ai/mcp` Run the following command: ```bash theme={null} claude mcp add --transport http ade-docs https://docs.landing.ai/mcp ``` Go to **Settings** > **Connectors** and add the MCP server URL as a custom connector. Use the **Connect to Cursor** option in the [contextual menu](#shortcuts-for-connecting-ai-tools) on any docs page. Use the **Connect to VS Code** option in the [contextual menu](#shortcuts-for-connecting-ai-tools) on any docs page. ## Shortcuts for Connecting AI Tools Use the contextual menu on any docs page to connect to AI tools, copy content as Markdown, or install the ADE docs MCP server. Click the drop-down icon at the top of any page to open it. Contextual Menu | Option | What it does | | ------------------------ | ------------------------------------------------------- | | Copy page | Copies the page as Markdown | | View as Markdown | Opens the page in Markdown format | | Open in ChatGPT | Creates a ChatGPT conversation with the page as context | | Open in Claude | Creates a Claude conversation with the page as context | | Connect to Cursor | Installs the ADE docs MCP server in Cursor | | Connect to VS Code | Installs the ADE docs MCP server in VS Code | | Copy MCP server URL | Copies `https://docs.landing.ai/mcp` to your clipboard | | Copy MCP install command | Copies the MCP server install command to your clipboard | ## Access Documentation Pages as llms.txt Access an index of all Agentic Document Extraction documentation pages at [llms.txt](https://docs.landing.ai/llms.txt). For a combined file of all documentation content, use [llms-full.txt](https://docs.landing.ai/llms-full.txt). These files follow the [llms.txt standard](https://llmstxt.org) for AI tool consumption. ## Access Documentation as Markdown View any page as plain Markdown by adding `.md` to the page URL. # API Key Source: https://docs.landing.ai/dpt3/agentic-api-key Create an API key and set it for the client libraries or direct API calls. Calling the Agentic Document Extraction API requires an API key. * [Get your API key](#get-your-api-key) * [Set your API key when using a library](#set-your-api-key-when-using-a-library) * [Set your API key when calling the API directly](#set-your-api-key-when-calling-the-api-directly) ## Get Your API Key If using Agentic Document Extraction in the EU, get your API key [here](https://ade.eu-west-1.landing.ai/settings/api-key). Get your API key on the [API Key](https://ade.landing.ai/settings/api-key) page: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [API Key](https://ade.landing.ai/settings/api-key) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **API Key**). Navigate to API Key 3. If you're on a subscription plan, you can [create an API key](#create-api-keys) if needed. 4. Click the **Copy** icon to copy your API key. API Key ## Personal Plans (Explore Plans) Have One API Key The personal plan (the "Explore" plan) only has one API key. This API key cannot be deleted or revoked. The Explore plan type is designed for testing, prototyping, and hobby use. If you'd like to deploy to production and need more granular API key management, like the ability to create and revoke API keys, [upgrade](/ade/ade-pricing) to a subscription plan. If your API key is exposed or leaked and you'd like to request a new API key, contact [support@landing.ai](mailto:support@landing.ai) ## Create API Keys If you are on a Team or Enterprise plan, you can create multiple API keys for your organization to use. To create an API key: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [API Key](https://ade.landing.ai/settings/api-key) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **API Key**). Navigate to API Key 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click **Create Key**. 5. Enter a brief, descriptive name for the API key in the key name field. 6. Click **Create API Key**. 7. Click the **Copy** icon to copy the API key. 8. Click **Done** to close the pop-up. ## Revoke API Keys If you are on the Team or Enterprise plan, you can revoke API keys. A user with the Admin role can revoke any API key. A user with the Developer role can revoke only API keys they have created. To revoke an API key: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [API Key](https://ade.landing.ai/settings/api-key) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **API Key**). Navigate to API Key 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Locate the row for the API key. (You may need to search to narrow down the list of API keys.) 5. Click the **Settings** button (ellipses) and select **Revoke API Key**. Follow the on-screen prompts to complete the process. ## Set Your API Key When Using a Library The Python and TypeScript libraries read your API key from the `VISION_AGENT_API_KEY` environment variable. For installation and other ways to set the key, see the [Python](./ade-python) or [TypeScript](./ade-typescript) library page. Set the key before running your code: ```bash macOS/Linux theme={null} export VISION_AGENT_API_KEY="" ``` ```cmd Windows (Command Prompt) theme={null} set "VISION_AGENT_API_KEY=" ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY="" ``` ## Set Your API Key When Calling the API Directly Include the API key in request headers. To see code samples, go to [API](https://docs.landing.ai/api-reference/parse/ade-parse). ## Security Best Practices * Do not hard-code the API key in your source code, because others could see and use your API key. Passing a variable that holds the key (for example, from a secrets manager) is fine. ## Troubleshoot API Key Issues Use the troubleshooting tips in this section to resolve issues related to API keys. ### Error: Missing API Key If no API key is set by any method, the library raises an error when you create the client. The Python library raises this error: ```text theme={null} landingai_ade.LandingAiadeError: The apikey client option must be set either by passing apikey to the client or by setting the VISION_AGENT_API_KEY environment variable ``` The TypeScript library throws this error: ```text theme={null} LandingAIADEError: The VISION_AGENT_API_KEY environment variable is missing or empty; either provide it, or instantiate the LandingAIADE client with an apikey option, like new LandingAIADE({ apikey: 'My Apikey' }). ``` To resolve this issue, set the key using one of the supported methods. If you set the key in a `.env` file or as an environment variable and still get this error, see the .env File Issues and Environment Variable Issues sections. ### .env File Issues If you set the API key in the `.env` file but the environment variable is not loading, try these possible solutions to resolve this issue: * Check file location: The `.env` file should be in the same directory where you run your script. * Verify file format: No spaces around the equals sign: ``` # Correct VISION_AGENT_API_KEY= # Incorrect VISION_AGENT_API_KEY = ``` ### Environment Variable Issues If you set the API key as an environment variable and are encountering issues, try these possible solutions to resolve this issue: * Restart your application after setting environment variables. * Check variable name: Must be exactly `VISION_AGENT_API_KEY`. * Check if the environment variable is correct: ```bash macOS/Linux theme={null} echo $VISION_AGENT_API_KEY ``` ```cmd Windows (Command Prompt) theme={null} echo %VISION_AGENT_API_KEY% ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY ``` * Ensure that you apply the changes after setting, changing, or removing the environment variable: * **Linux/macOS**: Restart your terminal. If you added the variable to your `.zshrc` file, run `source ~/.zshrc`. * **Windows**: Close and reopen Command Prompt/PowerShell, or restart your IDE. ### Error: Missing Authorization Header This error occurs if the authorization header is not included when calling the API directly. To fix this, include the API header: ```python theme={null} headers = {"Authorization": f"Bearer {api_key}"} ``` ### Error: User Not Found, Please Check Your API Key This error occurs when the API key is entered incorrectly. To resolve this issue: * Verify the API key: Copy your key directly from the [dashboard](https://ade.landing.ai/settings/api-key). * Restart your environment: Close and reopen your terminal, IDE, or Jupyter notebook. # Migration Guide Source: https://docs.landing.ai/dpt3/migration-guide Migrate from ADE Gen1 to ADE Gen2, including the response changes you need to handle. The [Parse Gen2](https://docs.landing.ai/api-reference/parse/ade-parse) API is a redesign, not a version bump. The request you send changes very little, but the response is a new shape built around DPT-3. Plan to rewrite the code that reads the parse response; there is no field-for-field mapping from the Parse Gen1 API. This guide covers what changed and what to update. For the full response reference, see [Parse API Response](./parse-response). ## Confirm Your Input Formats Parse Gen2 accepts PDFs, images, and Office text documents and presentations (DOCX, PPTX, ODT, RTF). Office files are converted to PDF before parsing. If your pipeline depends on spreadsheets (XLSX, CSV) or legacy binary Office files (DOC, PPT), keep those workflows on Parse Gen1. See [Supported File Types](./file-types). Parse Gen2 also does not support password-protected files. Decrypt the file and submit an unencrypted copy, or keep those workflows on [Parse Gen1](/ade/ade-parse-password). ## What Changes at a Glance * **Your request:** mostly the same. A new endpoint, three removed parameters, and one new `options` parameter. * **Your response:** new. Flat `chunks` become a hierarchical `structure` tree in which every block carries its own grounding, and the Markdown is cleaner. * **Extraction workflows:** the [Extract Gen1](/ade/ade-extract) and [Section](/ade/ade-section) APIs consume the Gen1 parse shape. With the Parse Gen2 API, use the [Extract Gen2](./extract) API instead, which works directly on the Gen2 Markdown output. Section has no Gen2 equivalent; keep Section workflows on the Parse Gen1 API. ## Update Your Request The request contract is close to the Parse Gen1 API. Update the endpoint and adjust a few parameters. For the full `options` schema, see [Request Options](./parse-input#request-options). | Aspect | Parse Gen1 API (DPT-2) | Parse Gen2 API (DPT-3) | | ------------------------- | ---------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------ | | Endpoint | `POST /v1/ade/parse` | `POST /v2/parse` | | Authentication | Bearer API key | Bearer API key (unchanged) | | File input | `document` or `document_url` | `document` or `document_url` (unchanged) | | Model selection | `model` form field | `model` form field (unchanged); use a DPT-3 snapshot such as `dpt-3-pro-latest` | | Page or section splitting | `split` form field | Removed. Use `options.pages` to select pages to process (1-indexed). | | Figure prompts | `custom_prompts` form field | Removed. | | Password-protected PDFs | `password` form field | Moved to `options.password`, but password-protected files are not supported: providing a password returns HTTP 422. Decrypt the file before uploading. | | Output customization | Not available | `options`: select pages, set the table format, suppress block types from the Markdown, control grounding detail, and inline each block's Markdown. | ## Rework Your Response Handling This is where the work is. The top-level response fields are different, and the concepts behind them changed. ### Chunks Are Now Blocks Parsed units are now called **blocks**. The Parse Gen1 API called them chunks. The Parse Gen1 API returns a flat `chunks` array, where each chunk carries its own `markdown` and inline `grounding`. DPT-3 replaces this with a hierarchical `structure` tree: a `document` whose `children` are pages, and each page's `children` are the blocks on that page. Tables nest their cells (`table_cell`) as children. Block ids are semantic: `-`, with a per-type counter in reading order (`text-0`, `figure-0`, `table_cell-3`). They replace the Gen1 UUIDs and `{page}-{sequence}` table ids. Block ids are stable within a response but not across re-parses of the same document. ### Grounding Is Inline, and the Values Changed In the Parse Gen1 API, grounding lived both inline on each chunk and in a top-level `grounding` map keyed by chunk id. In DPT-3, there is no separate grounding map: every node in `structure` carries its own self-contained `grounding` object. See [Grounding](./parse-response#grounding-where-things-are). * **`page` numbers are 1-indexed.** The Parse Gen1 API used 0-indexed page numbers. In DPT-3, page 1 is the document's first page, everywhere: in each node's `grounding.page`, in `metadata.failed_pages`, and in the `options.pages` request selector. Table `row` and `col` positions stay 0-indexed. * **`range` locates the block in the Markdown.** Each grounding carries `{"start": n, "end": n}` offsets into the top-level `markdown` string, in Unicode code points (`start` inclusive, `end` exclusive). The Gen1 response had no equivalent; each chunk carried its own Markdown copy instead. * **`box` keys are renamed.** Coordinates are still normalized fractions of the page, from 0 to 1, but the keys change from `left`, `top`, `right`, `bottom` to `xmin`, `ymin`, `xmax`, `ymax`, with at most 5 decimal places. * **Fine-grained detail is new.** Leaf blocks add an `atomic_grounding` array: one entry per visual line with DPT-3 Pro, or one per word with DPT-3 Verity. See [Atomic Grounding](./parse-response#atomic-grounding). * **The Gen1 confidence fields are removed.** `confidence` and `low_confidence_spans` have no direct Gen2 equivalent. DPT-3 Verity returns a different signal: a per-word `confidence` on each atomic grounding entry. There is no per-block equivalent of the Gen1 per-chunk score. See [Word Confidence Scores](./parse-response#word-confidence-scores-dpt-3-verity). ### Markdown Is Cleaner The Parse Gen1 API embedded `` anchors and id attributes in the Markdown to link it to chunks, and wrapped visual chunks in non-standard tags (for example, `<::logo: ...::>`). DPT-3 returns clean Markdown with no embedded ids: * **Blocks link to the Markdown through ranges,** not anchors. Slice the `markdown` string with a block's `grounding.range` to get its text. * **Visual blocks are structured and labeled.** Figures render as HTML-style `
...
` elements containing transcribed text and generated `` blocks. Logos, scan codes, and attestations render as transcribed text with short bracketed labels; an attestation can carry more than one, such as `[STAMPED][SIGNED]`. See [Attestations](./parse-response#attestations). * **Page breaks are explicit.** A `` comment separates each page's content (absent in single-page documents). * **The output ends with a document ID.** The final line is ``, which the [Extract Gen2](./extract) API reads to link an extraction back to its parse job. * **Tables are standardized.** Tables use HTML by default (set `options.blocks.table.format="markdown"` for pipe syntax). ### One Markdown String Instead of Copies The Parse Gen1 API duplicated Markdown onto every chunk and split. DPT-3 returns the Markdown once, as the top-level `markdown` string, and every block points into it with its `grounding.range`. To get a block's text, slice the Markdown string with the range, or set [`options.inline_markdown`](./parse-input#request-options) to `true` to have every block carry its own `markdown` slice again. ## What Was Removed These Gen1 fields and parameters have no equivalent in ADE Gen2: * `chunks` and the per-chunk `markdown` (walk `structure` instead; get text through `grounding.range` or `options.inline_markdown`) * `splits` and the `split` parameter * `custom_prompts` * `password` as a top-level field (it moved to `options.password`, but password-protected files are not supported and providing it returns HTTP 422) * `confidence` and `low_confidence_spans` (DPT-3 Verity adds a different per-word `confidence` on atomic grounding entries) * The top-level `grounding` map (grounding is inline on each node) * Embedded `` anchors and id attributes in the Markdown ## Migration Checklist * Point requests at `POST /v2/parse`. * Remove the `split`, `custom_prompts`, and `password` parameters; add `options` if you need page selection or output control. * Stop reading `chunks`. Walk `structure.children` (pages) and their `children` (blocks) instead, or flatten the tree into a map by block `id`. * Read each block's location from its inline `grounding` object: `page`, `range`, and `box`. * Shift page-number logic from 0-indexed to 1-indexed, including any `options.pages` values you send. * Rename box keys: `left`, `top`, `right`, `bottom` become `xmin`, `ymin`, `xmax`, `ymax` (still normalized 0 to 1). * Get a block's text by slicing the top-level `markdown` with its `grounding.range`, or set `options.inline_markdown` to `true`. * Remove any logic that depends on the Gen1 `confidence` or `low_confidence_spans` fields. To score words with DPT-3 Verity, use the per-word `confidence` instead. * Update visual-block handling for the structured formats (`
` elements and bracketed labels such as `[SIGNED]`) instead of `<:: ... ::>` tags, and remove any code that parses `` anchors out of the Markdown. * If your workflow chained Parse with the Extract Gen1 API, move the extraction step to the [Extract Gen2](./extract) API. If it used Section, keep that workflow on the Parse Gen1 API. # Python Library Source: https://docs.landing.ai/dpt3/ade-python Process documents using the ADE Python library. The [ade-python](https://github.com/landing-ai/ade-python) library wraps the Agentic Document Extraction APIs so you can parse and extract documents from Python. The library is published as the `landingai-ade` package and generated from the API specification. The Gen2 APIs live under the `client.v2` sub-client. It exposes both processing modes: async jobs through `client.v2.parse_jobs` and `client.v2.extract_jobs`, and synchronous calls through `client.v2.parse` and `client.v2.extract`. Jobs accept larger documents, default to the lower-consumption `standard` service tier, and suit automated pipelines and background work. See [Sync vs Async Processing](./sync-async). ## Install the Library Requires Python 3.9 or later. ```bash theme={null} pip install landingai-ade ``` ## Set Your API Key The library reads your API key from the `VISION_AGENT_API_KEY` environment variable. [Generate an API key](./agentic-api-key) first, then set it using any of the methods below. Do not hard-code your API key in source files. ### Method 1: Set the API Key as an Environment Variable 1. Set the environment variable. To persist the key across sessions on macOS or Linux, add the `export` command to your shell profile (`.zshrc` or `.bashrc`), then run `source ~/.zshrc`. ```bash macOS/Linux theme={null} export VISION_AGENT_API_KEY="" ``` ```cmd Windows (Command Prompt) theme={null} set "VISION_AGENT_API_KEY=" ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY="" ``` 2. Initialize the client. It reads the `VISION_AGENT_API_KEY` environment variable automatically: ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() ``` ### Method 2: Store the API Key in a .env File Store your API key in a `.env` file. The library reads the key from the environment; it does not load `.env` files on its own, so use `python-dotenv` to load the file. 1. Install the `python-dotenv` package: ```bash theme={null} pip install python-dotenv ``` 2. Create a `.env` file in your project root and add your API key: ```bash theme={null} VISION_AGENT_API_KEY= ``` 3. Load the `.env` file before you initialize the client: ```python theme={null} from dotenv import load_dotenv from landingai_ade import LandingAIADE load_dotenv() # Populates the environment from .env. client = LandingAIADE() ``` ### Method 3: Set the API Key in a Notebook In IPython-based notebooks (Jupyter, JupyterLab, Google Colab, or Kaggle), set the key for the current session with the `%env` magic command. The key is cleared when the kernel restarts, and it is visible in the notebook file if you share or commit it. 1. In a notebook cell, set the environment variable: ```python theme={null} %env VISION_AGENT_API_KEY= ``` 2. Initialize the client in a later cell: ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() ``` ### API Key Precedence If the API key is set in more than one place, the library resolves it in this order (the first match wins): 1. The `apikey` passed to the client constructor. 2. The `VISION_AGENT_API_KEY` environment variable, whether you set it directly or loaded it from a `.env` file. A value already set in your environment is not overridden by a `.env` file. For help with missing-key errors, keys that fail to load, or keys that resolve to the wrong account, see [Troubleshoot API Key Issues](./agentic-api-key#troubleshoot-api-key-issues). ## Initialize the Client Create a client. It reads `VISION_AGENT_API_KEY` from the environment automatically. ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() ``` By default, the library uses the US endpoints. If your API key is from the EU region, set the `environment` parameter to `eu`. API keys are region-specific: an EU key works only with the EU environment. ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE(environment="eu") ``` For more about using Agentic Document Extraction in the EU, see [European Union (EU)](./eu). ## Parse a Document Use `client.v2.parse_jobs` to convert a document into Markdown, a structure tree, and per-element grounding. The sub-client exposes `create`, `get`, `list`, and `wait`. The `wait` method polls until the job reaches a terminal state and returns the finished job. Pass a local file as a `Path` with the `document` parameter, or a remote file with `document_url`. Setting `service_tier` to `standard` runs the job in the lane that consumes half the credits of `priority`. A finished job carries the parse output in `result`, a `V2ParseResponse` with `markdown`, `structure`, and `metadata`. For the full workflow and parameters, see [Parse Asynchronously](./parse-async). ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("document.pdf"), model="dpt-3-pro-latest", service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ## Extract Data Use `client.v2.extract_jobs` to pull structured fields from parsed Markdown. Provide the Markdown as a string with `markdown` (or a remote URL with `markdown_url`) and a schema. The `schema` parameter accepts a Pydantic model, a dictionary, or a JSON string. A finished job carries the extraction in `result`, a `V2ExtractResult` with `extraction`, `extraction_metadata`, `markdown`, and `metadata`. For the full workflow and parameters, see [Asynchronous Extraction](./extract-async). ```python theme={null} from pathlib import Path from pydantic import BaseModel, Field from landingai_ade import LandingAIADE class Financials(BaseModel): revenue: str = Field(description="Q1 2024 revenue") client = LandingAIADE() # Parse first to get Markdown, then extract. parse_job = client.v2.parse_jobs.create( document=Path("document.pdf"), model="dpt-3-pro-latest", service_tier="standard", ) parsed = client.v2.parse_jobs.wait(parse_job.job_id) extract_job = client.v2.extract_jobs.create( markdown=parsed.result.markdown, schema=Financials, service_tier="standard", ) extracted = client.v2.extract_jobs.wait(extract_job.job_id) print(extracted.result.extraction) ``` ## Set the Model Version The `model` parameter is optional. When you omit it, the API uses the latest DPT-3 Pro model. To select a family or pin a version, pass a model string such as `dpt-3-verity`, or a dated snapshot. See [Parsing Models](./parse-models). Responses parsed with `dpt-3-verity` include a `confidence` score on each word-level `atomic_grounding` entry. See [Word Confidence Scores](./parse-response#word-confidence-scores-dpt-3-verity). ```python theme={null} from pathlib import Path job = client.v2.parse_jobs.create( document=Path("document.pdf"), model="dpt-3-pro-latest", service_tier="standard", ) ``` ## Save Output to a File The job `create` methods do not accept `save_to`. To keep a job's output, write `result` to a file yourself, or pass `output_save_url` on `create` to have Agentic Document Extraction deliver the result straight to your own storage. See [Save Parsed Output to a URL](./parse-async#save-parsed-output-to-a-url). The synchronous `parse` and `extract` methods take an optional `save_to` parameter instead, which writes the full response to a JSON file. Pass it a directory to use an auto-generated file name, or a path ending in `.json` to choose the exact file. ```python theme={null} from pathlib import Path job = client.v2.parse_jobs.create( document=Path("document.pdf"), service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) Path("parse-output.json").write_text(done.result.model_dump_json(indent=2)) ``` ## Handle Errors The synchronous `parse` and `extract` methods raise `V2SyncTimeoutError` if the request exceeds the server's synchronous time limit (HTTP 504). For large documents, use the async jobs interface instead. When a parse partially succeeds (some pages fail), the API returns the full response with an HTTP 206 status, and the failed pages are listed in `metadata`. See [Troubleshoot Parsing](./parse-troubleshoot). The job `wait` method returns the finished job regardless of outcome, so check `job.status`. To raise instead when a job fails, pass `raise_on_failure=True`, which raises `JobFailedError`. If a job does not finish within the `timeout`, `wait` raises `JobWaitTimeoutError`. ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE from landingai_ade.lib.v2_errors import JobFailedError, JobWaitTimeoutError client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("document.pdf"), service_tier="standard", ) try: done = client.v2.parse_jobs.wait(job.job_id, timeout=600, raise_on_failure=True) print(done.result.markdown) except JobFailedError as error: print(f"Job failed: {error}") except JobWaitTimeoutError: print("Job did not finish in time; poll again with parse_jobs.get().") ``` ## Additional Resources * [Python library on GitHub](https://github.com/landing-ai/ade-python). The README covers client configuration not documented here, including retries, timeouts, the async client, logging, raw response access, and custom requests. * [API reference](https://docs.landing.ai/api-reference/parse/ade-parse) * [Parse Documents](./parse) and [Extract Data](./extract) # TypeScript Library Source: https://docs.landing.ai/dpt3/ade-typescript Process documents using the ADE TypeScript library. The [ade-typescript](https://github.com/landing-ai/ade-typescript) library wraps the Agentic Document Extraction APIs so you can parse and extract documents from TypeScript and JavaScript. The library is published as the `landingai-ade` package and generated from the API specification. The Gen2 APIs live under the `client.v2` sub-client. It exposes both processing modes: async jobs through `client.v2.parseJobs` and `client.v2.extractJobs`, and synchronous calls through `client.v2.parse` and `client.v2.extract`. Jobs accept larger documents, default to the lower-consumption `standard` service tier, and suit automated pipelines and background work. See [Sync vs Async Processing](./sync-async). ## Install the Library ```bash theme={null} npm install landingai-ade ``` ## Set Your API Key The library reads your API key from the `VISION_AGENT_API_KEY` environment variable. [Generate an API key](./agentic-api-key) first, then set it using any of the methods below. Do not hard-code your API key in source files. ### Method 1: Set the API Key as an Environment Variable 1. Set the environment variable. To persist the key across sessions on macOS or Linux, add the `export` command to your shell profile (`.zshrc` or `.bashrc`), then run `source ~/.zshrc`. ```bash macOS/Linux theme={null} export VISION_AGENT_API_KEY="" ``` ```cmd Windows (Command Prompt) theme={null} set "VISION_AGENT_API_KEY=" ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY="" ``` 2. Initialize the client. It reads the `VISION_AGENT_API_KEY` environment variable automatically: ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); ``` ### Method 2: Store the API Key in a .env File Store your API key in a `.env` file. The library reads the key from the environment; it does not load `.env` files on its own, so use the `dotenv` package to load the file. 1. Install the `dotenv` package: ```bash theme={null} npm install dotenv ``` 2. Create a `.env` file in your project root and add your API key: ```bash theme={null} VISION_AGENT_API_KEY= ``` 3. Load the `.env` file before you initialize the client: ```typescript theme={null} import "dotenv/config"; // Loads .env into process.env. import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); ``` In Node.js 20.6 or later, you can skip the `dotenv` package and run your script with `node --env-file=.env your-script.js`. ### API Key Precedence If the API key is set in more than one place, the library resolves it in this order (the first match wins): 1. The `apikey` passed to the client constructor. 2. The `VISION_AGENT_API_KEY` environment variable, whether you set it directly or loaded it from a `.env` file. A value already set in your environment is not overridden by a `.env` file. For help with missing-key errors, keys that fail to load, or keys that resolve to the wrong account, see [Troubleshoot API Key Issues](./agentic-api-key#troubleshoot-api-key-issues). ## Initialize the Client Create a client. It reads `VISION_AGENT_API_KEY` from the environment automatically. ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); ``` By default, the library uses the US endpoints. If your API key is from the EU region, set the `environment` option to `eu`. API keys are region-specific: an EU key works only with the EU environment. ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE({ environment: "eu" }); ``` For more about using Agentic Document Extraction in the EU, see [European Union (EU)](./eu). ## Parse a Document Use `client.v2.parseJobs` to convert a document into Markdown, a structure tree, and per-element grounding. The sub-client exposes `create`, `get`, `list`, and `wait`. The `wait` method polls until the job reaches a terminal state and returns the finished job. Pass a local file as a read stream with the `document` parameter, or a remote file with `document_url`. Setting `service_tier` to `standard` runs the job in the lane that consumes half the credits of `priority`. A finished job carries the parse output in `result`, a `V2ParseResponse` with `markdown`, `structure`, and `metadata`. For the full workflow and parameters, see [Parse Asynchronously](./parse-async). ```typescript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` ## Extract Data Use `client.v2.extractJobs` to pull structured fields from parsed Markdown. Provide the Markdown as a string with `markdown` (or a remote URL with `markdown_url`) and a schema. The `schema` parameter accepts a JSON Schema object or a JSON string. A finished job carries the extraction in `result`, a `V2ExtractResult` with `extraction`, `extraction_metadata`, `markdown`, and `metadata`. For the full workflow and parameters, see [Asynchronous Extraction](./extract-async). ```typescript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); // Parse first to get Markdown, then extract. const parseJob = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", service_tier: "standard", }); const parsed = await client.v2.parseJobs.wait(parseJob.job_id); const extractJob = await client.v2.extractJobs.create({ markdown: (parsed.result as LandingAIADE.V2ParseResponse).markdown, schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, service_tier: "standard", }); const extracted = await client.v2.extractJobs.wait(extractJob.job_id); console.log((extracted.result as LandingAIADE.V2ExtractResult).extraction); ``` To define a typed schema, use [Zod](https://zod.dev) (v4 or later) and pass `z.toJSONSchema(YourSchema)` as the `schema`. ## Set the Model Version The `model` parameter is optional. When you omit it, the API uses the latest DPT-3 Pro model. To select a family or pin a version, pass a model string such as `dpt-3-verity`, or a dated snapshot. See [Parsing Models](./parse-models). Responses parsed with `dpt-3-verity` include a `confidence` score on each word-level `atomic_grounding` entry. See [Word Confidence Scores](./parse-response#word-confidence-scores-dpt-3-verity). ```typescript theme={null} import fs from "fs"; const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", service_tier: "standard", }); ``` ## Save Output to a File The job `create` methods do not accept `saveTo`. To keep a job's output, write `result` to a file yourself, or pass `output_save_url` on `create` to have Agentic Document Extraction deliver the result straight to your own storage. See [Save Parsed Output to a URL](./parse-async#save-parsed-output-to-a-url). The synchronous `parse` and `extract` methods take an optional `saveTo` parameter instead, which writes the full response to a JSON file. Pass it a directory to use an auto-generated file name, or a path ending in `.json` to choose the exact file. ```typescript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); fs.writeFileSync("parse-output.json", JSON.stringify(done.result as LandingAIADE.V2ParseResponse, null, 2)); ``` ## Handle Errors The synchronous `parse` and `extract` methods throw `V2SyncTimeoutError` if the request exceeds the server's synchronous time limit (HTTP 504). For large documents, use the async jobs interface instead. When a parse partially succeeds (some pages fail), the API returns the full response with an HTTP 206 status, and the failed pages are listed in `metadata`. See [Troubleshoot Parsing](./parse-troubleshoot). The job `wait` method returns the finished job regardless of outcome, so check `job.status`. To throw instead when a job fails, pass `raiseOnFailure: true`, which throws `JobFailedError`. If a job does not finish within the `timeout`, `wait` throws `JobWaitTimeoutError`. These v2 helper errors do not extend `APIError`, so catch them by name. ```typescript theme={null} import fs from "fs"; import LandingAIADE, { JobFailedError, JobWaitTimeoutError } from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), service_tier: "standard", }); try { const done = await client.v2.parseJobs.wait(job.job_id, { timeout: 600000, raiseOnFailure: true }); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); } catch (error) { if (error instanceof JobFailedError) { console.error(`Job failed: ${error.message}`); } else if (error instanceof JobWaitTimeoutError) { console.error("Job did not finish in time; poll again with parseJobs.get()."); } else { throw error; } } ``` ## Additional Resources * [TypeScript library on GitHub](https://github.com/landing-ai/ade-typescript). The README covers client configuration not documented here, including retries, timeouts, logging, raw response access, and customizing the fetch client. * [API reference](https://docs.landing.ai/api-reference/parse/ade-parse) * [Parse Documents](./parse) and [Extract Data](./extract) # Parse Documents Source: https://docs.landing.ai/dpt3/parse Parse documents with the Parse API into Markdown, structured blocks, and per-block grounding. The [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse) converts a document into structured data for retrieval-augmented generation (RAG), search, extraction, or any downstream workflow. It returns a reading-order Markdown rendering of the document, a hierarchical structure of its pages and blocks, and per-block grounding that maps everything back to the source. ## How Parse Works You send a PDF, image, or Office document to the parse endpoint, optionally choosing a [parsing model](./parse-models) and customizing the parse with [options](./parse-input#request-options). The API returns a single JSON response containing the reading-order Markdown, the document structure, per-block grounding, and request metadata. See [Parse API Response](./parse-response) for the field-by-field reference. If you haven't made an API call yet, start with the [Quickstart](./quickstart) to get a real response to follow along with. ## Call the Parse API Send a document to the parse endpoint with a POST request. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key) and `document.pdf` with the path to your file. The [`options`](./parse-input#request-options) field is optional: the defaults suit most documents, so include it only to customize the parse (here, to process specific pages). ```bash cURL theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"pages":[1]}' ``` ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.v2.parse( document=Path("document.pdf"), model="dpt-3-pro-latest", options={"pages": [1]}, ) print(response.markdown) ``` ```typescript TypeScript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const response = await client.v2.parse({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", options: { pages: [1] }, }); console.log(response.markdown); ``` For the full request and response contract, see the [API reference](https://docs.landing.ai/api-reference/parse/ade-parse). # Parse Input Parameters Source: https://docs.landing.ai/dpt3/parse-input Set the document, model version, and options when calling the Parse API. The Parse API accepts a document, an optional model, and an optional `options` object. The same core fields work whether you [call it synchronously](https://docs.landing.ai/api-reference/parse/ade-parse) or create a [Parse Job](./parse-async), which takes a few additional parameters of its own. ## Sample Request Create a [Parse Job](./parse-async) on the `standard` service tier, then collect the parse results from the finished job. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key) and `document.pdf` with the path to your file. ```bash cURL theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"pages":[1]}' \ -F 'service_tier=standard' ``` ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("document.pdf"), model="dpt-3-pro-latest", options={"pages": [1]}, service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ```typescript TypeScript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", options: { pages: [1] }, service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` ## Parameters | Parameter | Required | Description | | ----------------- | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `document` | Conditional | The document to parse (PDF, image, or Office document), sent as an uploaded file. Provide either `document` or `document_url`. | | `document_url` | Conditional | A public URL that the API fetches the document from. Provide either `document` or `document_url`. | | `model` | No | The parsing model family and snapshot. Defaults to the latest DPT-3 Pro snapshot. See [Model Version](#model-version). | | `options` | No | A JSON object of optional settings. See [Request Options](#request-options). | | `service_tier` | No | Parse Jobs only: the tier the job runs on, either `standard` or `priority`. Defaults to `standard`. See [Choose a Service Tier](./parse-async#choose-a-service-tier). | | `output_save_url` | No | Parse Jobs only: a presigned URL the job delivers its output to, instead of returning it in `result`. See [Save Parsed Output to a URL](./parse-async#save-parsed-output-to-a-url). | ## Model Version The `model` form field selects the parsing model family and snapshot: * `dpt-3-pro`: the highest-quality model. Default. * `dpt-3-verity`: the lower-latency model for digitally created text documents. In preview. Requests that omit `model` use the latest DPT-3 Pro snapshot, and the response reports the resolved version in [`metadata.model_version`](./parse-response#metadata). For the full comparison, all accepted values, and guidance on pinning snapshots, see [Parsing Models](./parse-models). For example, this request selects the latest DPT-3 Pro snapshot: ```bash cURL highlight={4} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'service_tier=standard' ``` ## Request Options The optional `options` form field is a JSON object that customizes the response. All fields are optional; omitted fields take the defaults shown. | Field | Type | Default | Description | | ------------------------ | ------------------------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `pages` | `int[]` | `null` | 1-indexed page numbers to process. `null` processes all pages. Page numbers below 1 or beyond the document's last page return HTTP 422, and a single invalid value rejects the whole request. Skipped pages are absent from `structure.children`, and the Markdown has no gap marker; check each page's `grounding.page` to identify missing pages. | | `blocks..markdown` | `bool` | `true` | Whether to include the block type's content in the Markdown. Applies to `text`, `table`, `figure`, `marginalia`, `attestation`, `logo`, `scan_code`, and `card`. When `false`, visual types (`figure`, `logo`, `scan_code`, `card`, `attestation`) emit only a header line such as `> [!FIGURE]`; `text`, `table`, and `marginalia` emit nothing. Suppressed blocks still appear in `structure`, with a zero-length `range` and an empty `atomic_grounding` array. | | `blocks.table.format` | `"markdown"` or `"html"` | `"html"` | Table representation in the Markdown output. HTML preserves merged cells that pipe syntax cannot; `markdown` uses pipe syntax. | | `atomic_grounding` | `bool` | `true` | Whether to include the fine-grained `atomic_grounding` array on leaf blocks. Set `false` to omit the field from every node. On DPT-3 Verity, this also removes every `confidence` score, because the scores live on the word entries. | | `inline_markdown` | `bool` | `false` | When `true`, every structure node (the document root, each page, and each block, including table cells) carries its own `markdown` field with its slice of the top-level Markdown, so you don't have to slice by `range` yourself. Entries in `atomic_grounding` do not carry it. | | `password` | `string` | `null` | Not currently supported: encrypted PDFs are rejected, and providing a password returns HTTP 422. Decrypt the file and upload an unencrypted copy. | ### Example Options The following examples all parse the same sample calibration report, so you can see exactly what each option changes. For the complete, unmodified output, download the full default response (parsed with no options). Each example shows the full request with the relevant `options` line highlighted, followed by a trimmed view of the parse results the finished job returns in `result`. #### Process Specific Pages Pass `pages` to parse only the pages you need. Page numbers are 1-indexed: `1` is the document's first page. `metadata.page_count` still reports the full document length, while `structure.children` returns only the requested pages. ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@calibration-report.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"pages":[1,3]}' \ -F 'service_tier=standard' ``` ```python Python highlight={9} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("calibration-report.pdf"), model="dpt-3-pro-latest", options={"pages": [1, 3]}, service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ```typescript TypeScript highlight={9} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("calibration-report.pdf"), model: "dpt-3-pro-latest", options: { pages: [1, 3] }, service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` When you get the parse results, `page_count` counts all pages but `structure.children` holds only pages 1 and 3: ```json theme={null} { "metadata": { "page_count": 3, "failed_pages": [] // ... }, "structure": { "type": "document", "children": [ { "type": "page", "grounding": { "page": 1, "range": { "start": 0, "end": 1695 }, "box": { "xmin": 0, "ymin": 0, "xmax": 1, "ymax": 1 } }, "status": "ok", "children": [ /* ... */ ] }, { "type": "page", "grounding": { "page": 3, "range": { "start": 1716, "end": 3224 }, "box": { "xmin": 0, "ymin": 0, "xmax": 1, "ymax": 1 } }, "status": "ok", "children": [ /* ... */ ] } ] } } ``` #### Render Tables as Markdown Tables are returned as HTML by default. HTML preserves merged cells and nested layouts that pipe syntax cannot represent, such as the `Measured Value` header spanning the `As Found` and `As Left` columns in this calibration table: ```html theme={null}
Test PointNominal (V)Measured Value (V)As-Found Deviation (mV)Tolerance (±mV)Result
As FoundAs Left
TP-10.0000.0010.000+15Pass
TP-22.5002.5032.500+310Pass
TP-35.0005.0415.002+4120Fail
TP-47.5007.5127.503+1230Pass
TP-510.00010.01810.004+1840Pass
``` Set `blocks.table.format` to `markdown` to receive tables as pipe-syntax Markdown instead. Merged cells expand into empty adjacent cells: ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@calibration-report.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"blocks":{"table":{"format":"markdown"}}}' \ -F 'service_tier=standard' ``` ```python Python highlight={9} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("calibration-report.pdf"), model="dpt-3-pro-latest", options={"blocks": {"table": {"format": "markdown"}}}, service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ```typescript TypeScript highlight={9} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("calibration-report.pdf"), model: "dpt-3-pro-latest", options: { blocks: { table: { format: "markdown" } } }, service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` When you get the parse results, the `markdown` field carries the same table in pipe syntax, with the merged header flattened into empty cells: ```markdown theme={null} | Test Point | Nominal (V) | Measured Value (V) | | As-Found Deviation (mV) | Tolerance (±mV) | Result | |---|---|---|---|---|---|---| | | | As Found | As Left | | | | | TP-1 | 0.000 | 0.001 | 0.000 | +1 | 5 | Pass | | TP-2 | 2.500 | 2.503 | 2.500 | +3 | 10 | Pass | | TP-3 | 5.000 | 5.041 | 5.002 | +41 | 20 | Fail | | TP-4 | 7.500 | 7.512 | 7.503 | +12 | 30 | Pass | | TP-5 | 10.000 | 10.018 | 10.004 | +18 | 40 | Pass | ``` #### Suppress a Block Type Set a block type's `markdown` option to `false` to drop its content from the `markdown`. Suppressing a block type also speeds up parsing, because suppressed blocks skip model captioning. Here, figures are suppressed, so each figure collapses to a `> [!FIGURE]` header line. The figure still appears in `structure`, with a zero-length `range` and an empty `atomic_grounding` array. ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@calibration-report.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"blocks":{"figure":{"markdown":false}}}' \ -F 'service_tier=standard' ``` ```python Python highlight={9} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("calibration-report.pdf"), model="dpt-3-pro-latest", options={"blocks": {"figure": {"markdown": False}}}, service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ```typescript TypeScript highlight={9} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("calibration-report.pdf"), model: "dpt-3-pro-latest", options: { blocks: { figure: { markdown: false } } }, service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` When you get the parse results, the `markdown` field shows each figure as a header line instead of its content: ```markdown theme={null} AS-FOUND DEVIATION BY TEST POINT > [!FIGURE] ``` #### Omit Atomic Grounding Set `atomic_grounding` to `false` to drop the fine-grained `atomic_grounding` array from every block, leaving only the block-level `grounding`. Use this to reduce response size when you don't need the fine-grained coordinates. ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@calibration-report.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"atomic_grounding":false}' \ -F 'service_tier=standard' ``` ```python Python highlight={9} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("calibration-report.pdf"), model="dpt-3-pro-latest", options={"atomic_grounding": False}, service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ```typescript TypeScript highlight={9} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("calibration-report.pdf"), model: "dpt-3-pro-latest", options: { atomic_grounding: false }, service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` When you get the parse results, each block carries only its block-level grounding, and the `atomic_grounding` field is omitted entirely: ```json theme={null} { "type": "text", "id": "text-8", "grounding": { "page": 1, "range": { "start": 720, "end": 1169 }, "box": { "xmin": 0.0902, "ymin": 0.36545, "xmax": 0.9281, "ymax": 0.45273 } } } ``` #### Include Markdown on Each Node Set `inline_markdown` to `true` to add each node's slice of the document Markdown as a `markdown` field on the node itself, so you can read a block's text without slicing the top-level string by `range`. ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@calibration-report.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'options={"inline_markdown":true}' \ -F 'service_tier=standard' ``` ```python Python highlight={9} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("calibration-report.pdf"), model="dpt-3-pro-latest", options={"inline_markdown": True}, service_tier="standard", ) done = client.v2.parse_jobs.wait(job.job_id) print(done.result.markdown) ``` ```typescript TypeScript highlight={9} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("calibration-report.pdf"), model: "dpt-3-pro-latest", options: { inline_markdown: true }, service_tier: "standard", }); const done = await client.v2.parseJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ParseResponse).markdown); ``` When you get the parse results, every structure node (document, page, block, and table cell) carries its `markdown` slice. Entries in `atomic_grounding` do not. To get an entry's text, slice by its `range` or read the parent block's `markdown`: ```json theme={null} { "type": "text", "id": "text-0", "grounding": { "page": 1, "range": { "start": 0, "end": 27 }, "box": { "xmin": 0.08007, "ymin": 0.02051, "xmax": 0.7402, "ymax": 0.05965 } }, "markdown": "**Report No.** TVL-CAL-7731" } ``` # Parsing Models Source: https://docs.landing.ai/dpt3/parse-models Choose between DPT-3 Pro and DPT-3 Verity, and pin a model snapshot for consistent parsing results. A **Document Pre-Trained Transformer** (DPT) is the model that powers the [Parse API](./parse). The model identifies a document's layout, transcribes the content into Markdown in reading order, and records where every block sits on the page. The Parse API has two model families: * **DPT-3 Pro** delivers the highest parsing quality. This is the default model. * **DPT-3 Verity** parses digitally created text documents with lower latency and lower credit consumption. This model is in preview. Set the model with the `model` parameter on [Parse](./parse) and [Parse Jobs](./parse-async) requests. Requests that omit `model` use the latest DPT-3 Pro snapshot. ## DPT-3 Pro vs. DPT-3 Verity DPT-3 Pro and DPT-3 Verity both run on the same endpoints, accept the same [file types](./file-types), and return the same [response shape](./parse-response). They differ in what they read and what they return: DPT-3 Pro handles more document styles and content types, while DPT-3 Verity returns results faster, consumes fewer credits, and adds per-word confidence scores. | Capability | DPT-3 Verity | DPT-3 Pro | | -------------------------------------------------------- | -------------------------------------------- | --------- | | Scanned documents and handwriting | No | Yes | | Non-Latin scripts and math formulas | No | Yes | | Text and marginalia | Yes | Yes | | Tables | Yes | Yes | | Checkboxes | Yes | Yes | | Key-value pairs and form layouts | Less accurate | Yes | | Figure descriptions | Basic | Detailed | | Attestation, card, and scan code labels | Yes | Yes | | Markdown formatting (headings, bold, underline, italics) | No | Yes | | Atomic grounding granularity | Word | Line | | Confidence scores | Word level, for text, tables, and marginalia | No | ### DPT-3 Pro DPT-3 Pro is the default model and the right choice for most workloads. Use it for scanned or handwritten documents, non-Latin scripts, math formulas, and complex forms. It generates detailed descriptions for figures, formats the Markdown output with headings, bold, underline, and italics, and grounds text down to the visual line. ### DPT-3 Verity DPT-3 Verity is optimized for digitally created text documents, such as generated PDFs and Office files, and has lower latency than DPT-3 Pro. In the Markdown output, it often renders the bracketed descriptions of visual content (logos, scan codes, and the visual marks in attestations) as generic markers such as `[VISUAL_TEXT]` rather than descriptive phrases. DPT-3 Verity grounds text, marginalia, and table cells at the word level: the `atomic_grounding` array has one entry per word, and each entry carries a `confidence` value between 0 and 1 that reflects how certain the model is that it transcribed the word correctly. See [Atomic Grounding](./parse-response#atomic-grounding). DPT-3 Verity consumes fewer credits than DPT-3 Pro. For rates, see [Credit Consumption](./credit-consumption#parse). **DPT-3 Verity was renamed from DPT-3 Fast.** Requests that pin the earlier `dpt-3-fast` values keep working, so no code change is required. ## Model Versions and Snapshots The following table lists the available `model` values for [Parse](./parse) and [Parse Jobs](./parse-async): | Value | Behavior | | ------------------------------- | ----------------------------------------------------------------- | | `dpt-3-pro-latest` | The latest snapshot of DPT-3 Pro. This is the default. | | `dpt-3-pro` | Alias for `dpt-3-pro-latest`. | | `dpt-3-pro-20260710` | The snapshot of DPT-3 Pro generated on July 10, 2026. | | `dpt-3-verity-latest` | The latest snapshot of DPT-3 Verity. | | `dpt-3-verity` | Alias for `dpt-3-verity-latest`. | | `dpt-3-verity-20260804-preview` | The preview snapshot of DPT-3 Verity generated on August 4, 2026. | Some snapshots have been superseded: a newer snapshot replaced them, and they no longer appear in the table above. If you pin a superseded snapshot, your requests still succeed. The API resolves the name to the current snapshot and reports the current version in `metadata.model_version`. Update pinned code to a value from the table. ### Why Model Versioning Matters When integrating the API, you have two options for specifying the model: 1. **Use a general model name** (like `dpt-3-pro` or `dpt-3-pro-latest`) to always get the newest version. This automatically gives you improvements and updates, but parsing results may change when new model versions are released. 2. **Use a specific snapshot** (like `dpt-3-pro-20260710`) to pin to an exact model version. Your results stay consistent for as long as the snapshot is available, but you won't receive improvements. If you use only a general model name like `dpt-3-pro` in production, your application may produce different results when we release model updates. Consider whether you need consistent results or prefer to receive the latest improvements. ### Understanding Snapshots and -latest **Snapshots** are frozen versions of a model released on specific dates. A snapshot's parsing behavior never changes while it is available, making your results predictable. When a snapshot is superseded, its name resolves to the current snapshot instead of failing. The **latest** suffix always points to the most recent snapshot of that model family, and the bare family name is equivalent to `-latest`. Whichever form you send, the response reports the snapshot that actually ran in `metadata.model_version`, so pinned code can detect a change. ## Set the Model Supply the value in the `model` form field on the request. For the full request reference, see [Parse Input Parameters](./parse-input). To set the model in the Python and TypeScript libraries, see [Python Library](./ade-python) and [TypeScript Library](./ade-typescript). To select the model in the [Playground](./playground), use the model drop-down menu. For example, this request creates a Parse Job that uses the latest DPT-3 Pro snapshot: ```bash theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'service_tier=standard' ``` # Parse API Response Source: https://docs.landing.ai/dpt3/parse-response Read the Parse response: reading-order Markdown, document structure with per-block grounding, and metadata. A successful parse returns a JSON object with the reading-order Markdown, the document structure with per-block grounding, and request metadata. ## The Response Shape The response contains these top-level fields: | Field | Description | | ------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | [`markdown`](#markdown) | The complete document as a single Markdown string, in reading order. | | [`metadata`](#metadata) | Information about the job: model version, page count, duration, billing, and more. | | [`structure`](#structure-pages-and-blocks) | A `document` node whose `children` are pages. Each page's `children` are the blocks detected on that page. Every node below the root carries its location inline in a [`grounding`](#grounding-where-things-are) object. | ## Markdown The `markdown` field is a single string containing the document in reading order, following [CommonMark 0.31.2](https://spec.commonmark.org/0.31.2/) with a few extensions. Use it directly for RAG, search indexing, or anything that takes Markdown as input. Every `range` elsewhere in the response points into this string, using Unicode code point offsets as declared by [`metadata.range_units`](#metadata). Superscript and subscript text that is not part of a math formula is wrapped in `` and `` tags. When using [DPT-3 Pro](./parse-models), math formulas are transcribed as LaTeX, wrapped in `$...$` for inline math or `$$...$$` for display math, matching the original layout. | Block | Representation | | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Page break | `` appended after each page's content. Absent in single-page documents. | | Document ID | `` appended as the final line of the output. It carries the parse job's `job_id` so the [Extract API](./extract) can link an extract call back to the originating parse job. | | Table | HTML `` markup by default, which preserves merged cells. Use `options.blocks.table.format="markdown"` to emit pipe syntax instead; merged cells then expand into empty adjacent cells. | | Figure | An HTML-style figure element carrying a classification label: `
` wraps the figure's transcribed text and one or more generated `...` blocks. See [Figures](#figures). | | Logo | Transcribed text from the logo, with a brief bracketed description for the visual mark (for example, `[Logo with letter A inside shield]`). | | Card | Transcribed visible text content from the card. | | Scan code | A bracketed code type, followed by the decoded value when it is readable. For example, `[BARCODE]` followed by the digits on the next line. | | Attestation | One or more bracketed classification labels on a single header line (for example, `[STAMPED][SIGNED]`), followed by the transcribed content. Printed text is transcribed as prose; a visual-only mark is transcribed as a short bracketed description. See [Attestations](#attestations). | ### Figures A figure is wrapped in an HTML-style element whose `type` attribute is the classification label: `
...
`. Inside the element, the figure's visible text is transcribed, and generated descriptions of the visual content appear in `...` blocks. A `CHART` figure also transcribes the chart's data as an HTML `
`. The figure type labels are `CHART`, `FLOWCHART`, `DIAGRAM`, `ILLUSTRATION`, and `PHOTOGRAPH`, with `FIGURE` as the fallback. **Example** A bar chart could render like this: ```html theme={null}
Bar chart of quarterly revenue
``` ### Attestations An attestation is a block that has a signature, stamp, or seal. It renders as a header line of one or more bracketed type labels, followed by the block's transcribed content. The type labels are `SIGNED`, `E-SIGNED`, `STAMPED`, and `SEALED`. The type labels stack when a block has more than one. Within the content, readable text is transcribed as prose, and every visual mark is replaced by a short bracketed description of what it is. The model generates these descriptions, so treat their wording as variable rather than a fixed set of labels. Two of these descriptions are fixed literals you can build logic around: * `[ILLEGIBLE_SIGNATURE]`: a signature that can't be read. * `[ILLEGIBLE_TEXT]`: any other unreadable text. **Example** An attestation block that is both stamped and signed, with a legible and an unreadable signature, could render like this: ``` [STAMPED][SIGNED] Secretary of State use only IDAHO SECRETARY OF STATE [HANDWRITTEN_SIGNATURE] [ILLEGIBLE_SIGNATURE] ``` ## Structure: Pages and Blocks The `structure` field is a `document` node whose `children` are pages, and each page's `children` are the blocks on that page. Every node below the root `document` carries its location inline in a [`grounding`](#grounding-where-things-are) object, so hierarchy and spatial data live in one tree. ### Common Block Fields Every block in the structure tree shares the same base shape: | Field | Description | | ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `type` | The block type. See [block types](#block-types) below. | | `id` | A semantic block identifier, unique within the document, in the format `-`. The index is a per-type counter that starts at 0 and follows reading order: `text-0` is the document's first text block, `figure-0` is its first figure, and `table_cell-3` is the fourth cell of its first table. Block ids are stable within a response but not across re-parses of the same document. | | `grounding` | The block's location: the page it appears on, its `range` in the `markdown` string, and its bounding `box`. See [Grounding](#grounding-where-things-are). | | `atomic_grounding` | Finer-grained grounding segments within the block. Present only on leaf blocks (every type except `table`). See [Atomic Grounding](#atomic-grounding). | | `children` | Child blocks. Present on `document`, `page`, and `table`. | | `markdown` | The block's slice of the top-level `markdown` string. Present only when the request sets [`options.inline_markdown`](./parse-input#request-options) to `true`; an empty string for blocks with zero-length ranges. | ### Page Fields `page` nodes carry their own `grounding` plus parse status fields: | Field | Description | | ----------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `grounding` | The page's location data. The `page` value is the page's 1-indexed number in the source document, `range` covers the page's content in the `markdown` string (zero-length for failed pages), and `box` is always the full page: `{"xmin": 0, "ymin": 0, "xmax": 1, "ymax": 1}`. | | `status` | `"ok"` if the page was parsed successfully, or `"failed"`. | | `reason` | Failure reason. Present only when `status` is `"failed"`. | | `children` | The blocks detected on the page, in reading order. Empty for failed pages. | ### Block Types Parse recognizes the following block types: | Type | Description | | ------------- | ----------------------------------------------------------------------------------------------------------------------- | | `text` | Any textual content: titles, headings, paragraphs, lists, captions, key-value pairs, form fields, headers, and footers. | | `table` | A table. Its `children` are the cells. | | `table_cell` | A table cell, present as a child of a `table`. A single type covers every cell; there is no separate header-cell type. | | `figure` | An image, chart, diagram, or other non-text visual content. | | `marginalia` | Text appearing in the margins, outside the main content flow. | | `attestation` | A certification, stamp, or signature region. | | `logo` | A company or brand logo. | | `card` | A business card or card-like block. | | `scan_code` | A QR code, barcode, or other machine-readable code. | ### Tables and Cells A `table` block has its own `id` and `grounding`, and a `children` array of `table_cell` blocks in row-major order. Every cell uses the `table_cell` type, including cells in header rows. Each cell carries its grid position: | Field | Description | | --------- | ------------------------------------------------ | | `row` | 0-indexed row position. | | `col` | 0-indexed column position. | | `colspan` | Number of columns the cell spans. Defaults to 1. | | `rowspan` | Number of rows the cell spans. Defaults to 1. | Cell positions are 0-indexed even though page numbers are 1-indexed. A table is the one block type that has children but no `atomic_grounding` of its own. Its cells are leaf blocks that carry it instead: empty with DPT-3 Pro, one entry per word with DPT-3 Verity. See [Entries by Block Type](#entries-by-block-type). A cell's `range` points to its own content in the Markdown, so an empty cell has a zero-length range. In this DPT-3 Pro example, both cells have empty `atomic_grounding` arrays: ```json theme={null} { "type": "table", "id": "table-0", "grounding": { "page": 1, "range": { "start": 114, "end": 212 }, "box": { "xmin": 0.08007, "ymin": 0.2197, "xmax": 0.91993, "ymax": 0.42045 } }, "children": [ { "type": "table_cell", "id": "table_cell-0", "grounding": { "page": 1, "range": { "start": 114, "end": 114 }, "box": { "xmin": 0.08007, "ymin": 0.2197, "xmax": 0.27941, "ymax": 0.2702 } }, "atomic_grounding": [], "row": 0, "col": 0, "colspan": 1, "rowspan": 1 }, { "type": "table_cell", "id": "table_cell-1", "grounding": { "page": 1, "range": { "start": 118, "end": 125 }, "box": { "xmin": 0.27941, "ymin": 0.2197, "xmax": 0.59967, "ymax": 0.2702 } }, "atomic_grounding": [], "row": 0, "col": 1, "colspan": 1, "rowspan": 1 } // ... ] } ``` ## Grounding: Where Things Are Every node below the root `document` carries a `grounding` object. The same shape appears on pages, blocks, and each `atomic_grounding` entry, so any grounding object is self-contained: you can lift it out of the tree and it still locates its content. To map fields extracted by [Extract](./extract) onto these blocks, use the [Ground API](./ground). ```json theme={null} "grounding": { "page": 1, "range": { "start": 29, "end": 112 }, "box": { "xmin": 0.08007, "ymin": 0.11995, "xmax": 0.91993, "ymax": 0.18056 } } ``` | Field | Description | | ------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `page` | The 1-indexed page number this content appears on. On a `page` node, the page's own number. | | `range` | The block's extent in the top-level `markdown` string, as `{"start": n, "end": n}`. The `start` offset is inclusive and `end` is exclusive, in Unicode code points (see [`metadata.range_units`](#metadata)). | | `box` | The bounding box, as `{"xmin": n, "ymin": n, "xmax": n, "ymax": n}` in normalized page coordinates: each value is a fraction of the page's width (`xmin`, `xmax`) or height (`ymin`, `ymax`), from 0 to 1, with at most 5 decimal places. | | `confidence` | [DPT-3 Verity](./parse-models) only: how certain the model is that it transcribed this word correctly, from 0 to 1, with at most 2 decimal places. Present only on the word entries of `atomic_grounding`, never on a block, table, or page `grounding`, and never on DPT-3 Pro. See [Word Confidence Scores](#word-confidence-scores-dpt-3-verity). | ### Working with Boxes Boxes are resolution-independent. To convert a box to pixels, multiply its `x` values by the width and its `y` values by the height of whatever rendering of the page you draw on. The same box lines up at any resolution because it scales with the dimensions you supply. For images with EXIF orientation metadata (such as phone photos), the API applies the orientation before parsing, so boxes align with the upright image as a viewer sees it. Use the upright dimensions when converting. ```python Python theme={null} box = block["grounding"]["box"] left = box["xmin"] * image_width top = box["ymin"] * image_height right = box["xmax"] * image_width bottom = box["ymax"] * image_height ``` ### Atomic Grounding Grounding locates a whole block. **Atomic grounding** locates the content inside it: the `atomic_grounding` field breaks a block into its individual lines or words, with one grounding entry for each. Every entry has the same `{page, range, box}` shape as the block's own `grounding`, so you can highlight single lines or words on the page, or slice them out of the Markdown. Every leaf block carries `atomic_grounding`. The `document` root, `page` nodes, and `table` nodes never carry it. A table's cells carry it instead. #### Line-Level vs. Word-Level Grounding The granularity of atomic grounding depends on the [parsing model family](./parse-models): * **DPT-3 Pro** grounds at the line level: one entry per visual line. * **DPT-3 Verity** grounds at the word level: one entry per word, each with a [`confidence`](#word-confidence-scores-dpt-3-verity) score. #### Entries by Block Type Atomic grounding entries follow the block type and the model family. Any block the model cannot segment finer carries a single entry covering the block's full range and box. | Block type | DPT-3 Pro | DPT-3 Verity | | ---------------------------------------------------- | --------------------------------- | ------------------------------------------------------- | | `text`, `marginalia` | One entry per visual line | One entry per word, with `confidence` | | `table_cell` | No entries | One entry per word, with `confidence` | | `figure`, `logo`, `card`, `scan_code`, `attestation` | One entry per transcribed segment | One entry per transcribed segment, without `confidence` | #### Range Boundaries Atomic grounding entries are ordered, non-overlapping sub-ranges of the block's own `range`. The first entry starts where the block starts, and the last one ends where it ends. With DPT-3 Pro, the line entries are contiguous: every character in the block, newlines included, falls inside exactly one entry, so joining the entries reproduces the block's Markdown. With DPT-3 Verity, a word entry in a `text` block includes the whitespace or newline that follows the word, so those entries are contiguous too. Inside a `table_cell`, the single space between two words falls outside both entries, so joining a cell's entries drops the spaces between words. #### When the Array Is Empty An empty `atomic_grounding` array is expected in four cases: * An empty `table_cell`, which has no content to ground. Its own `range` is zero-length. * A `table_cell` parsed with DPT-3 Pro: cells have no line-level detail. * A block whose Markdown is suppressed with [`blocks..markdown=false`](./parse-input#request-options). * A `table_cell` parsed with DPT-3 Verity whose words cannot be located in the rendered cell text (for example, a character that is escaped in an HTML table). Those entries are dropped rather than risk ranges that point at the wrong characters. #### Turn Off Atomic Grounding To omit the field from every node in the response, set [`options.atomic_grounding`](./parse-input#request-options) to `false`. On DPT-3 Verity, this also removes every [`confidence`](#word-confidence-scores-dpt-3-verity) score, because the scores live on the word entries. ### Word Confidence Scores (DPT-3 Verity) [DPT-3 Verity](./parse-models) scores every word it transcribes in text, tables, and marginalia. The `confidence` field on a word's [atomic grounding](#atomic-grounding) entry is a value between 0 and 1 for how certain the model is that it transcribed the word correctly. DPT-3 Pro does not include confidence scores. #### Where Confidence Score Appears The confidence score appears only on the word entries of a DPT-3 Verity response. | Location | Confidence score | | -------------------------------------------------------------------------- | --------------------- | | Word entries of `text`, `marginalia`, and `table_cell` blocks | The word's own score. | | Entries of `figure`, `logo`, `card`, `scan_code`, and `attestation` blocks | Never. | | The `grounding` of a block, `table`, or `page`, and the `document` root | Never. | In this trimmed `text` block, each word entry carries its own score, and the block's `grounding` carries none: ```json highlight={14,20} theme={null} { "type": "text", "id": "text-0", "grounding": { "page": 1, "range": { "start": 52, "end": 212 }, "box": { "xmin": 0.65845, "ymin": 0.04808, "xmax": 0.9191, "ymax": 0.10764 } }, "atomic_grounding": [ { "page": 1, "range": { "start": 52, "end": 65 }, "box": { "xmin": 0.74463, "ymin": 0.05285, "xmax": 0.82379, "ymax": 0.06079 }, "confidence": 1.0 }, { "page": 1, "range": { "start": 134, "end": 136 }, "box": { "xmin": 0.77741, "ymin": 0.08043, "xmax": 0.78066, "ymax": 0.08702 }, "confidence": 0.85 } ] } ``` #### How the Confidence Score Is Calculated The confidence value is the lowest per-character score in the word: a single uncertain character lowers the score for the whole word. #### Handle Low-Confidence Words Use the confidence score to route uncertain transcriptions to review instead of trusting every one equally, or to re-parse low-confidence documents with DPT-3 Pro. ### Look Up Blocks by ID To look up blocks by `id` instead of walking the tree, flatten it into a map once: ```python Python theme={null} def iter_blocks(node): for child in node.get("children") or []: if child.get("id"): yield child yield from iter_blocks(child) blocks_by_id = {b["id"]: b for b in iter_blocks(response["structure"])} ``` ### Slice the Markdown Any grounding `range` turns into text with one slice: index the top-level `markdown` string with the range's `start` and `end` offsets. The same slice works for a block's `grounding.range` and for a single line or word from its [`atomic_grounding`](#atomic-grounding), so you can pull one table out of a long document or quote the exact words behind a value. Offsets count Unicode code points, as declared by [`metadata.range_units`](#metadata). To skip slicing entirely, set [`options.inline_markdown`](./parse-input#request-options) to `true` and each node carries its own `markdown` field instead. Slice a block's range like this: ```python Python theme={null} r = block["grounding"]["range"] block_markdown = response["markdown"][r["start"]:r["end"]] ``` ```javascript JavaScript theme={null} // Slice code points, not the string: JavaScript indexes strings by // UTF-16 code units, which drift from the code-point offsets when the // Markdown contains emoji or some CJK characters. const codePoints = Array.from(response.markdown); const { start, end } = block.grounding.range; const blockMarkdown = codePoints.slice(start, end).join(""); ``` ## Metadata The `metadata` field describes the job. | Field | Description | | ----------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `job_id` | A unique, server-generated identifier for this parse job. Useful for tracking a document across a workflow (for example, parse to extract) and for support requests. | | `model_version` | The exact model snapshot used (for example, `dpt-3-pro-20260710`). | | `page_count` | Total number of pages in the source document. Includes pages filtered out by `options.pages`; the pages actually returned are in `structure.children`. | | `output_markdown_chars` | Number of Unicode code points in the returned `markdown` string. | | `range_units` | The units of every `range` offset in the response. Always `"unicode_codepoints"`. Declared explicitly because some languages index strings differently; see [Slice the Markdown](#slice-the-markdown). | | `openapi_spec` | The URL of the OpenAPI spec that describes this API. Use it for inspection or client generation. | | `failed_pages` | An array of 1-indexed page numbers that failed to parse. Empty on success. Also reflected inline in `structure.children` with `status: "failed"` and a `reason`. See [Troubleshoot Parsing](./parse-troubleshoot#status-206-partial-content). | | `duration_ms` | Total processing time in milliseconds. | | `billing` | Billing details: `service_tier` is the service tier the request ran on (`standard` or `priority`; synchronous requests always report `priority`), and `total_credits` is the credits consumed (`0` if none). See [Credit Consumption](./credit-consumption). | A complete `metadata` block could look like this: ```json theme={null} { "job_id": "parse-01k04g2b8xv9q3m5n7r2sd4tfe", "model_version": "dpt-3-pro-20260710", "page_count": 1, "output_markdown_chars": 3765, "range_units": "unicode_codepoints", "openapi_spec": "https://api.ade.landing.ai/openapi.json", "failed_pages": [], "duration_ms": 17266, "billing": { "service_tier": "priority", "total_credits": 2.9 } } ``` # Parse Asynchronously (Parse Jobs) Source: https://docs.landing.ai/dpt3/parse-async Parse documents asynchronously with Parse Jobs: submit a job, poll for status, and retrieve results. Use Parse Jobs to parse documents asynchronously with the [Parse API](./parse). Submit a document, receive a `job_id` immediately, then poll for the result instead of holding open a single synchronous request. Parse Jobs runs the same parsing as the synchronous Parse API and returns the same parse response shape. Use it for workflows where you don't want to wait on a live connection, such as batch pipelines, long-running parses, and documents beyond the synchronous size limits, or when you want to submit work at a lower-cost service tier. ## Endpoints Parse Jobs uses one endpoint to submit a job and two to monitor it. All calls use the same host as the synchronous [Parse API](./parse#call-the-parse-api), `https://api.ade.landing.ai`. | Action | Method and Path | | ------------------ | ----------------------------- | | Create a parse job | `POST /v2/parse/jobs` | | Get a parse job | `GET /v2/parse/jobs/{job_id}` | | List parse jobs | `GET /v2/parse/jobs` | ## Workflow Overview 1. Submit a document to `POST /v2/parse/jobs`. 2. Copy the `job_id` from the response. 3. Poll `GET /v2/parse/jobs/{job_id}` until `status` reaches a terminal state (`completed` or `failed`). 4. When the job completes, read the parsed output from `result`, or from `output_url` if you saved the output to a URL. ## Create a Parse Job Submit a document the same way as the synchronous [Parse API](./parse#call-the-parse-api): a `document` file upload or a `document_url`, with an optional `model` and `options`. Setting `service_tier` to `standard` runs the job in the lane that consumes half the credits of `priority`. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key). ```bash cURL theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'service_tier=standard' ``` ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("document.pdf"), model="dpt-3-pro-latest", service_tier="standard", ) print(job.job_id) ``` ```typescript TypeScript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", service_tier: "standard", }); console.log(job.job_id); ``` The request returns a `202` response with the `job_id`, the job's status, and its creation time: ```json theme={null} { "job_id": "parse-01k04g2b8xv9q3m5n7r2sd4tfe", "status": "pending", "created_at": "2026-07-16T18:03:12Z" } ``` The status at creation is normally `pending`; a job that finishes very quickly can already report `completed` or `failed`. Treat the `job_id` as an opaque string; the same id is returned on every poll. Parse Jobs accepts the same `options` as the synchronous endpoint, including page selection, table format, and grounding detail. See [Request Options](./parse-input#request-options). ### Choose a Service Tier Set the optional `service_tier` form field to control the job's turnaround time and credit consumption. Jobs run on the `standard` tier when you omit it. Each tier draws from its own [rate limit](./rate-limits): `standard` jobs are measured against your plan's hourly limit, and `priority` jobs share the synchronous Parse per-minute limit. For a comparison of Parse and the two Parse Jobs tiers, see [Sync vs Async Processing](./sync-async). For credit consumption by tier, see [Credit Consumption](./credit-consumption#parse). | Tier | Behavior | | ---------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `standard` | Consumes half the credits of the `priority` tier, with a slower turnaround. The default, and the right choice for automated pipelines, background agent steps, scheduled ingestion, and the largest documents. | | `priority` | Consumes credits at the full rate, the same as Parse, with a faster turnaround. Use it for time-sensitive jobs where someone is waiting on the result. | **Set the tier.** Include the `service_tier` field in your create-job request, sending `standard` or `priority`. Setting it explicitly keeps the tier visible in code you copy between projects: ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' \ -F 'service_tier=standard' ``` ```python Python highlight={9} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.parse_jobs.create( document=Path("document.pdf"), model="dpt-3-pro-latest", service_tier="standard", ) print(job.job_id) ``` ```typescript TypeScript highlight={9} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.parseJobs.create({ document: fs.createReadStream("document.pdf"), model: "dpt-3-pro-latest", service_tier: "standard", }); console.log(job.job_id); ``` ## Monitor a Parse Job Poll the get-job endpoint with the `job_id` to check status and retrieve the result when the job finishes. To be notified when the job finishes instead of polling, set up [webhooks](./webhooks). ```bash cURL theme={null} curl 'https://api.ade.landing.ai/v2/parse/jobs/JOB_ID' \ -H 'Authorization: Bearer YOUR_API_KEY' ``` ```python Python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() # Fetch the job once. Use client.v2.parse_jobs.wait("JOB_ID") to poll until it finishes. job = client.v2.parse_jobs.get("JOB_ID") print(job.status) if job.status == "completed": print(job.result.markdown) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); // Fetch the job once. Use client.v2.parseJobs.wait("JOB_ID") to poll until it finishes. const job = await client.v2.parseJobs.get("JOB_ID"); console.log(job.status); if (job.status === "completed") { console.log((job.result as LandingAIADE.V2ParseResponse).markdown); } ``` The response reports the job status and, once the job finishes, the result: | Field | Description | | -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `job_id` | The unique identifier for the job. The same id is returned on the create response and every poll. | | `status` | The current state of the job. See [Job Statuses](#job-statuses). | | `created_at` | When the job was created, as an ISO-8601 timestamp. | | `completed_at` | When the job reached a terminal state, as an ISO-8601 timestamp. Present once the job finishes. | | `progress` | An estimate of how close the job is to completion, between `0` and `1`, updated on each poll. Present only while the job is processing, and never reaches `1`. To detect completion, check for a `status` of `completed` instead. | | `result` | The parse result, present when `status` is `completed` and you did not save the output to a URL. Contains the full parse response (`markdown`, `metadata`, and `structure`). See [Parse API Response](./parse-response#the-response-shape). | | `output_url` | The location of the saved output, present only when you supplied `output_save_url`. When set, the full output is delivered to the URL instead of returned in `result`. See [Save Parsed Output to a URL](#save-parsed-output-to-a-url). | | `metadata` | The job's `metadata` block, including `billing`. Present on completed jobs that saved their output to a URL, so you can confirm the model version and charge without fetching the file. For inline results, this information is in `result.metadata` instead. See [Parse API Response](./parse-response#metadata). | | `error` | Present when `status` is `failed`. Contains a `code` and a `message`. | ### Job Statuses A job moves through these statuses until it reaches a terminal state. | Status | Meaning | | ------------ | ---------------------------------------------------------------- | | `pending` | The job is accepted and queued, but has not started. | | `processing` | The job is running. | | `completed` | The job finished. Read the result from `result` or `output_url`. | | `failed` | The job did not finish. See the `error` field for details. | ### Get Job Results When a job reaches `completed`, the parsed output is returned in one of two ways: * **Inline in `result`.** By default, `result` contains the full parse response. See [Parse API Response](./parse-response#the-response-shape) for the field-by-field reference. * **As a URL in `output_url`.** If you supplied `output_save_url` when you created the job, Agentic Document Extraction saves the output to that URL, `output_url` contains the location, and `result` is `null`. The poll response still reports the job's `metadata`. See [Save Parsed Output to a URL](#save-parsed-output-to-a-url). If some pages fail to parse, the completed job still returns every page and the poll request reports a `206` status. See [Troubleshoot Parsing](./parse-troubleshoot#parse-jobs). ## List Parse Jobs To retrieve the parse jobs for your organization, call the list endpoint. ```bash cURL theme={null} curl 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' ``` ```python Python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() jobs = client.v2.parse_jobs.list() for job in jobs: print(job.job_id, job.status) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const jobs = await client.v2.parseJobs.list(); for (const job of jobs.jobs) { console.log(job.job_id, job.status); } ``` The response returns your jobs newest first, as a summary row per job. Use the optional `page` (0-indexed), `pageSize`, and `status` query parameters to page through the list or filter by job status. ```json theme={null} { "jobs": [ { "job_id": "parse-01k04g2b8xv9q3m5n7r2sd4tfe", "status": "completed", "created_at": "2026-07-16T18:03:12Z", "completed_at": "2026-07-16T18:04:37Z", "model_version": "dpt-3-pro-20260710", "failure_reason": null } ], "page": 0, "page_size": 10, "has_more": false } ``` | Field | Description | | ----------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `jobs` | A summary for each job, containing `job_id`, `status`, `created_at`, `completed_at`, and `model_version` (the model snapshot used). A failed job also reports a `failure_reason`. | | `page` | The 0-indexed page number of this list response. | | `page_size` | The number of jobs per page. | | `has_more` | Whether more jobs are available beyond those returned. | ## Save Parsed Output to a URL If you need to manage large outputs or integrate with your existing storage provider, use the `output_save_url` parameter. When you use this parameter, the output is written to the URL you specify in that parameter, instead of returning it inline in `result`. The delivered file contains the complete parse response: `markdown`, `metadata` (including `billing`), and `structure`. The completed poll response also carries the job's `metadata` alongside `output_url`, so billing information is available without fetching the file. ### URL Requirements If you specify `output_save_url`, your URL must meet these requirements: * The URL must be a presigned URL that grants time-limited write access to a single object. * These storage provider methods are tested: * [Amazon S3 presigned URL](https://docs.aws.amazon.com/AmazonS3/latest/userguide/PresignedUrlUploadObject.html) * [Azure Blob Storage shared access signature (SAS)](https://learn.microsoft.com/en-us/azure/storage/common/storage-sas-overview) * [Google Cloud Storage signed URL](https://docs.cloud.google.com/storage/docs/access-control/signed-urls) * Other providers that support presigned URLs may also work, but are not tested. * The URL must stay valid until the job completes, not just until you submit it. A URL that is already expired or expires too soon is rejected at submission with a 422 error. See [Troubleshoot Parsing](./parse-troubleshoot#status-422-unprocessable-entity). * An Azure SAS URL must grant write (`w`) or create (`c`) permission. * To maintain security, do not use a publicly accessible URL or expose a storage bucket. * The API cannot access private URLs, such as folders in Google Drive. ## Zero Data Retention (ZDR) If Zero Data Retention (ZDR) is enabled for your organization, it applies to all Parse Jobs calls. No special parameters are required. Under ZDR, results are deleted as soon as you retrieve them. See [Result Retention](../ade/zdr#result-retention). For the strictest control over sensitive documents, keep them out of the API request and response: * Pass a document as a presigned URL in `document_url`. * Write the response to a presigned URL specified in `output_save_url`. See [Save Parsed Output to a URL](#save-parsed-output-to-a-url). ## Rate Limits Parse Jobs accepts larger files than the synchronous Parse API: a size cap of 1 GiB for PDFs and 50 MiB for images, with the same 6,000-page ceiling per PDF. Usage is metered by pages against the job's service tier: `priority` jobs draw from the same per-minute limit as synchronous Parse, and `standard` jobs are measured against your plan's hourly limit. A document with more pages than the `priority` per-minute limit cannot run on that tier; submit it on the `standard` tier. See [Rate Limits](./rate-limits#parse-api). # Troubleshoot Parsing Source: https://docs.landing.ai/dpt3/parse-troubleshoot Resolve errors when parsing with the Parse API using status codes, causes, and recommended fixes. Use this section to troubleshoot issues encountered when calling the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse). ## Error Response Format Every API error returns a JSON body with two fields: ```json theme={null} { "code": "unknown_model_version", "message": "Unknown model version 'dpt-2'. Available: dpt-3-pro-20260710, dpt-3-pro-latest, dpt-3-pro, dpt-3-verity-20260804-preview, dpt-3-verity-latest, dpt-3-verity." } ``` The `code` field is a stable identifier you can branch on, such as `validation_error`, `unknown_model_version`, `invalid_url`, `invalid_api_key`, or `rate_limit_exceeded`. The `message` field is a human-readable description; treat its exact wording as variable. The error messages quoted on this page are `message` values. ## Common Status Codes These status codes are handled at the account and gateway level and can apply to any request. | Status Code | Name | Description | What to Do | | ----------- | ------------------- | ------------------------------------------------------------------------------------------------------------------------ | --------------------------------------------------------------------------------------------------------------------------------- | | 401 | Unauthorized | Missing or invalid API key. | Check that your `Authorization` header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 429 | Too Many Requests | A rate limit rejected the request: either the limit is temporarily exhausted, or the document is too large for the tier. | The error message states which case you hit and the fix. See [Status 429](#status-429-too-many-requests). | | 502 | Bad Gateway | A transient infrastructure error interrupted the request. | Retry with exponential backoff. A synchronous request that fails to deliver a result is not billed. | | 503 | Service Unavailable | The service is temporarily unavailable. | Retry with exponential backoff. If the error persists, contact [support@landing.ai](mailto:support@landing.ai). | ## Parse Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Document parsed successfully and returned immediately. | Continue with normal operations. | | 206 | Partial Content | Document parsed, but at least one page (and not all pages) failed during processing. | Review the `failed_pages` field in the metadata. See [Status 206](#status-206-partial-content). | | 422 | Unprocessable Entity | Input validation failed, including an unknown model version, an invalid `document_url`, an out-of-range `pages` selection, or a document over the size limits. | Review your request parameters. See [Status 422](#status-422-unprocessable-entity). | | 500 | Internal Server Error | All pages failed to process. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500](#status-500-internal-server-error). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit (475 seconds). | Reduce the number of pages per request or use Parse Jobs. See [Status 504](#status-504-gateway-timeout). | ## Status 206: Partial Content This response occurs when the document was parsed successfully but at least one page (and not all pages) failed during processing. The response includes: * A 206 status code. * Parsed content for the successful pages. Each successful page has a `status` of `"ok"` in `structure.children`. * A `failed_pages` array in `metadata` listing which pages failed (1-indexed). * A `status` of `"failed"`, a `reason`, and a zero-length `range` on each failed page in `structure.children`. Because the API returns at least partial results, the call consumes credits. **What to do:** * Review `metadata.failed_pages` to identify which pages failed. * Review the `reason` on each failed page in `structure.children` for details. * Check whether the failed pages are corrupted or have unusual formatting. * If the issue persists with specific pages, contact [support@landing.ai](mailto:support@landing.ai). For more on the response shape, see [Parse API Response](./parse-response#metadata). ## Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error `message` and adjust your request parameters. ### Error: Unknown Model Version This error occurs when the `model` form field specifies a version that is not registered. The error `code` is `unknown_model_version`. **Error message:** ``` Unknown model version '{version}'. Available: {versions}. ``` **What to do:** * Omit the `model` field to use the latest DPT-3 Pro snapshot by default. * Supply a valid version: a family alias such as `dpt-3-pro-latest` or `dpt-3-verity`, or a dated snapshot from [Model Versions and Snapshots](./parse-models#model-versions-and-snapshots). ### Error: Invalid document\_url Scheme This error occurs when the `document_url` uses a scheme other than `http` or `https` (for example, `ftp://` or `file://`). **Error message:** ``` document_url scheme must be http or https, got '{scheme}' ``` **What to do:** Supply a `document_url` that begins with `http://` or `https://`. ### Error: document\_url Missing Hostname This error occurs when the `document_url` does not contain a hostname. **Error message:** ``` document_url missing hostname ``` **What to do:** Verify the URL is complete and properly formatted, including a hostname (for example, `https://example.com/file.pdf`). ### Error: document\_url Did Not Resolve This error occurs when the `document_url` hostname cannot be resolved through DNS. **Error message:** ``` document_url hostname did not resolve: {hostname} ``` **What to do:** * Verify the hostname is spelled correctly. * Confirm the host is publicly reachable. ### Error: document\_url Resolves to a Non-Public IP This error occurs when the `document_url` hostname resolves to a private, loopback, link-local, reserved, or multicast IP address. Only publicly reachable URLs are allowed. The error `code` is `invalid_url`. **Error message:** ``` document_url resolves to a non-public IP: {ip} ``` **What to do:** Host the document at a publicly accessible URL, or upload the file directly using the `document` parameter. ### Error: document\_url Returned a Redirect This error occurs when the `document_url` responds with a redirect (301, 302, 303, 307, or 308). The server does not follow redirects; the URL must serve the file bytes directly. **Error message:** ``` document_url returned a redirect; supply the final URL directly. ``` **What to do:** Resolve the redirect yourself and supply the final destination URL that serves the file directly. ### Error: document\_url Fetch Failed This error occurs when the URL passes validation but the file cannot be fetched: the server returns an error status, times out, or refuses the connection. **Error message:** ``` Failed to fetch document_url: HTTP {status} ``` or ``` Failed to fetch document_url: request timed out ``` or ``` Failed to fetch document_url: connection failed ``` **What to do:** * Verify the URL serves the file and is publicly reachable. * If the URL is presigned, confirm it has not expired. ### Error: output\_save\_url Expired or Expires Too Soon This error occurs when you create a job with an `output_save_url` whose presigned URL is already expired or does not stay valid long enough for the job to complete. The output is delivered when the job completes, so the URL must outlive the job: Parse Jobs requires at least 15 minutes of remaining validity plus 3 seconds per page. The error `code` is `invalid_url`. **Error message:** ``` output_save_url presigned URL expired {time} ago; sign a fresh URL valid for at least {required} ``` or ``` output_save_url presigned URL expires in {remaining}, but this request requires at least {required} of validity (the URL must outlive the job; it is used at completion, not at submit) ``` **What to do:** * Sign a fresh presigned URL with a longer validity and create the job again. The job is rejected before processing starts, so no credits are consumed. * For Azure SAS URLs, also confirm the token grants write (`w`) or create (`c`) permission. A URL without write access is rejected with a similar 422 error. * Sign delivery URLs with long-lived credentials. A URL signed with temporary session credentials can pass this check but still fail at delivery if the session expires before the job completes. ### Error: Document Exceeds the Size Cap This error occurs when the document exceeds the 50 MiB size limit. The limit applies whether you upload the file directly (`document`) or supply a URL (`document_url`). **Error message:** ``` document exceeds 50 MiB cap ``` or ``` document_url body exceeds 50 MiB cap ``` **What to do:** * Reduce the document size to 50 MiB or less. * Split larger documents into smaller files, or submit the document to [Parse Jobs](./parse-async), which accepts documents up to 1 GiB. See [Rate Limits](./rate-limits) for current size limits. ### Error: Image Exceeds the Maximum Resolution This error occurs when an image has more pixels than the [maximum image resolution](./rate-limits#size-limits) of 178,956,970 pixels (about 179 megapixels). The check runs on the image's declared dimensions, so an oversized image is rejected even when its file size is under the 50 MiB cap. No credits are consumed. On [Parse Jobs](./parse-async), the check runs after the job starts, so an oversized image fails the job instead of rejecting the creation request. The poll response reports a `failed` status, with the code `ParseImageTooLarge` and this message in the `error` field. See [Failed Jobs](#failed-jobs). **Error message:** ``` image exceeds the maximum supported size of 178956970 pixels ``` **What to do:** Downscale the image below the resolution limit before uploading. Parsing accuracy does not benefit from resolutions this high, because pages are downscaled during processing anyway. ### Error: Must Provide a Document This error occurs when your request includes neither the `document` nor the `document_url` parameter. **Error message:** ``` One of `document` or `document_url` is required. ``` **What to do:** Add one of these parameters to your request: * Use the `document` parameter to upload a file. * Use the `document_url` parameter to provide a URL to a file. ### Error: Cannot Provide Both document and document\_url This error occurs when both a file and a URL are provided in the same request. **Error message:** ``` Provide exactly one of `document` or `document_url`, not both. ``` **What to do:** Choose one input method and remove the other from your request. ### Error: Page Numbers Must Be 1-Indexed This error occurs when the `options.pages` selector includes `0` or a negative number. Page numbers are 1-indexed: `1` is the document's first page. **Error message:** ``` pages: page numbers are 1-indexed (must be >= 1), got: [0] ``` **What to do:** Update the `pages` values to 1-indexed page numbers. For example, to parse the first and third pages, send `{"pages": [1, 3]}`. ### Error: Pages Out of Range This error occurs when the `options.pages` selector includes a page number beyond the document's last page. A single out-of-range value rejects the whole request, even when the other values are valid. On [Parse Jobs](./parse-async), the page count is not known when you create the job, so an out-of-range selection fails the job instead of rejecting the creation request. The poll response reports a `failed` status, with this message in `error.message`. See [Failed Jobs](#failed-jobs). **Error message:** ``` pages out of range: {pages}; the document has {N} page(s) ``` **What to do:** Remove the out-of-range page numbers from the selection. To check a document's length, read `metadata.page_count` from a parse of the full document. ### Error: Empty File This error occurs when the uploaded file contains no data. **Error message:** ``` Empty file ({filename}). ``` **What to do:** Upload a valid file that contains content. ### Error: Unsupported or Unrecognized File Format This error occurs when the file is not a supported PDF, image, or Office document. Spreadsheets (XLSX, CSV) and legacy binary Office files (DOC, PPT) are not supported. The format is detected from the file's content, not its extension or Content-Type header. **Error message:** ``` Unsupported format: {format} ({filename}). Supported formats: PDF, PNG, JPEG, GIF, BMP, TIFF, WEBP, DOCX, PPTX, ODT, RTF. ``` or ``` Unrecognised file format ({filename}). Supported formats: PDF, PNG, JPEG, GIF, BMP, TIFF, WEBP, DOCX, PPTX, ODT, RTF. ``` **What to do:** * Convert your document to a supported format before uploading. See [Supported File Types](./file-types). * Verify the file is not corrupted by opening it in the appropriate application. ### Error: Too Many Pages This error occurs when a PDF exceeds the per-request page limit. The limit applies to both Parse and Parse Jobs. See [Rate Limits](./rate-limits#parse-api). **Error message:** ``` document has {N} pages; the per-request limit is {limit} ``` **What to do:** Split the PDF into shorter PDFs and parse them separately. A document under the page limit can still exceed your `priority` tier's per-minute rate limit; in that case the request returns a 429 error, and the fix is to submit the document as a `standard` tier job. See [Rate Limits](./rate-limits#run-large-documents-as-async-jobs-on-the-standard-tier). ### Error: Failed to Fetch document\_url This error occurs when the server cannot retrieve the file from the `document_url`. The URL returned an HTTP error status, or the request failed (for example, a connection or timeout error). **Error message:** ``` Failed to fetch document_url: HTTP {status} ``` or ``` document_url fetch failed: {error_type} ``` **What to do:** * Verify the URL is accessible and returns the file directly. * Check that the URL does not require authentication. * Confirm the host is reachable and responds within the timeout. ### Error: Invalid options Value This error occurs when the `options` form field is not valid JSON, when its contents fail validation, or when it contains a key the API does not recognize. Unknown keys are rejected at every nesting level, including the retired legacy options `dpi`, `grounding`, and `blocks..caption`. **Error message:** ``` options: invalid JSON: {details} ``` or ``` options.dpi: Extra inputs are not permitted ``` **What to do:** * Ensure `options` is a valid JSON object. * Remove any option key named in the message. If the key is a legacy option, use its replacement: `blocks..markdown` instead of `blocks..caption`, and `atomic_grounding` instead of `grounding.parts`. The `dpi` option has no replacement; coordinates are normalized. * Use 1-indexed page numbers in `pages`, and keep them within the document's length. See [Page Numbers Must Be 1-Indexed](#error-page-numbers-must-be-1-indexed) and [Pages Out of Range](#error-pages-out-of-range). * See [Request Options](./parse-input#request-options) for the full schema. ### Error: service\_tier Is Only Valid on Parse Jobs This error occurs when a request to the synchronous Parse endpoint (`POST /v2/parse`) includes the `service_tier` parameter. Service tiers only apply to asynchronous endpoints, like Parse Jobs. The parameter is rejected even when its value is empty. **Error message:** ``` service_tier (or its deprecated alias priority) is only valid on the async POST /v2/parse/jobs route; sync runs in the fast lane already ``` **What to do:** * Remove the `service_tier` parameter from Parse requests. Parse always runs on the `priority` tier. See [Sync vs Async Processing](./sync-async). * To choose a service tier, create a Parse Job instead. See [Choose a Service Tier](./parse-async#choose-a-service-tier). ## Status 429: Too Many Requests A 429 means a [rate limit](./rate-limits) rejected the request. The error message states which of two cases you hit and what to do. ### The Limit Is Temporarily Exhausted Recent traffic used up your tier's limit. Wait and retry with exponential backoff. **Error message:** ``` Rate limit exceeded: the limit of {limit} pages per {window} is temporarily exhausted. Please retry shortly. ``` ### The Document Is Too Large for the Tier The document has more pages than the tier admits per request, so retrying never succeeds. Follow the message: submit the document as a `standard` tier [Parse Job](./parse-async), or split it into smaller documents. See [Run Large Documents as Async Jobs on the Standard Tier](./rate-limits#run-large-documents-as-async-jobs-on-the-standard-tier). **Error message:** ``` {N} pages exceeds the priority tier ({limit}/request). Larger documents use the standard tier on /v2/parse/jobs, up to {max}/request. ``` or ``` {N} pages exceeds the maximum of {max}/request. Split it into smaller documents. ``` ## Status 500: Internal Server Error This status code indicates that every page in the document failed to process. The response body is still a full parse response: each page in `structure.children` carries a `status` of `"failed"` and a `reason`, and `metadata.failed_pages` lists every page. **What to do:** * Retry the request. * Review the `reason` on the failed pages for details. * Check whether the document has unusual formatting or corrupted content. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 504: Gateway Timeout This error occurs when a synchronous parse request exceeds the timeout limit (475 seconds). The work is cancelled, so retrying starts the parse from the beginning. You are not billed for a request that times out. **Error message:** ``` parse did not complete within 475s; use POST /v2/parse/jobs for long-running work ``` **What to do:** * Reduce the number of pages per request with the `pages` option, or split the document into smaller files. See [Request Options](./parse-input#request-options). * Use [Parse Jobs](./parse-async) instead. Jobs are not subject to the synchronous timeout and accept larger documents. See [Sync vs Async Processing](./sync-async). * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## When Are Credits Consumed? Credits are consumed only when the Parse API returns a 200 or 206 status code. All other responses, including errors, do not consume credits. ## Parse Jobs This section covers error and status behavior specific to [Parse Jobs](./parse-async), the asynchronous Parse API. Errors surface in two places: as HTTP status codes when you create or poll a job, and as a terminal `failed` job status when parsing itself fails. ### Job Creation Errors Creating a job with `POST /v2/parse/jobs` returns these status codes: | Status | Meaning | | --------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `202 Accepted` | The job was created. The response contains the `job_id`. | | `422 Unprocessable Entity` | The request is invalid: an unrecognized `model` version, an encrypted PDF, malformed `options`, an invalid `service_tier` value, a PDF over the page limit, or a document over the size limits. See [Rate Limits](./rate-limits#parse-api). | | `429 Too Many Requests` | You exceeded your rate limit. | | `500 Internal Server Error` | The job could not be queued. Retry the request. | ### Polling Errors Polling a job with `GET /v2/parse/jobs/{job_id}` returns these status codes: | Status | Meaning | | ------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `200 OK` | The job status was retrieved. Check the `status` field. | | `206 Partial Content` | The job completed, but some pages failed to parse. The result still contains every page; failed pages carry a `status` of `"failed"`. | | `404 Not Found` | No job with that `job_id` exists for your account. | | `410 Gone` | The job completed, but its result is no longer stored. The error code is `result_expired`. For when results are deleted, see [Result Retention](../ade/zdr#result-retention). Submit a new job to parse the document again. | | `503 Service Unavailable` | The stored result could not be retrieved. The error code is `result_store_unavailable`. This is a transient condition. The result has not expired, so retry with exponential backoff instead of re-running the job. | ### Failed Jobs When parsing fails after a job starts, the poll request still returns `200`. The failure is reported in the job itself: `status` is `failed` and the `error` field carries a `code` and a `message` describing the cause. Jobs have a maximum run time of 6 hours; a job that exceeds it fails. Review the error and resubmit the job to retry. # Parse in the Playground Source: https://docs.landing.ai/dpt3/playground Parse documents with DPT-3 in the Playground, no code required. Use the [Playground](https://ade.landing.ai/) to upload a document, see what the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse) returns, and copy a ready-to-use API snippet before you write any code. ## Parse a Document in the Playground To parse a document with DPT-3: 1. Go to the [Playground](https://ade.landing.ai/). 2. In the upload card, confirm the model in the drop-down menu: **DPT-3 Pro** (the default) or **DPT-3 Verity**. DPT-3 Verity is a preview model with lower latency and per-word confidence scores; for the full comparison, see [Parsing Models](./parse-models). 3. Drag and drop your file into the upload area, or click to choose a file. 4. Click **Start**. The Playground processes the file and opens the project view with the parse results. Playground upload card with the model drop-down open and DPT-3 Pro selected ## Review the Results The parse results open in the Parse tab of the project view: * **Markdown view (default):** The reading-order Markdown rendering of your document. Use this for quick visual review or to copy into a downstream tool. * **JSON view:** The full response payload. Use this view to inspect block ids, ranges, and grounding coordinates. To collapse or expand a nested section, hover over the narrow column along the left edge of the JSON and click the arrow that appears. * **Click a block** in either view to highlight its bounding box on the document preview on the left. * Use the **Search**, **Download**, and **Copy** buttons in the toolbar above the result to find text in the current view, save it, or paste it elsewhere. * Click **Display** in the toolbar to change how results render: **Always show atomic grounding** keeps the fine-grained grounding boxes visible on the document preview, and **Word wrap** wraps long lines in the JSON view. For a complete reference on what each response field contains, see [Parse API Response](./parse-response). View DPT-3 results in the Playground ## Review Word Confidence Scores (DPT-3 Verity) When you parse with [DPT-3 Verity](./parse-models), every word in text, tables, and marginalia carries a [confidence score](./parse-response#word-confidence-scores-dpt-3-verity). ### Spot Low-Confidence Words The parse result highlights every word whose score falls below the [confidence threshold](#confidence-settings-in-the-display-menu). Hover over a highlighted word to see its score. Each block also shows its lowest word score (for example, `min 0.683`). Playground results for a DPT-3 Verity parse, with low-confidence words highlighted in red, a hover tooltip reading min conf 0.683, and per-block minimum confidence labels ### Confidence Settings in the Display Menu Open the **Display** menu on the Parse tab to adjust the highlighting: * **Highlight low confidence:** Show or hide the highlights. On by default, and available only for parses that include confidence scores. * **Threshold:** Set the score that counts as low confidence (default 95%). The highlights update as you change it. * **Show low-confidence blocks only:** Filter the results panel to blocks that contain at least one word below the threshold. Display menu with the Confidence section: the Highlight low confidence toggle on, the Threshold set to 95%, and Show low-confidence blocks only off ## Customize the Parse Output with Config To change how DPT-3 parses your files, open the **Config** drop-down menu on the Parse tab and update the settings. These controls set the same values as the API's [`options` field](./parse-input#request-options). After you adjust the options, click **Apply to all files** to reparse with the new settings. * **Captioning options:** Choose which block types are included in the Markdown (Text, Table, Figure, Marginalia, Attestation, Logo, Scan code, and Card). All are on by default. Clearing one drops that block type's content from the Markdown, but the block still appears in the JSON structure and grounding. * **Table output format:** Choose **HTML** (default) or **Markdown** for how tables appear in the Markdown output. This control appears only while **Table** captioning is on. * **Atomic grounding:** Include the fine-grained grounding detail (the `atomic_grounding` array) with each block: per-line with DPT-3 Pro, per-word with DPT-3 Verity. On by default. * **Pages:** Enter the pages to parse (for example, `1-3`) to process only part of the document. The Playground and the API's `options.pages` field both use 1-based page numbers. DPT-3 Pro Config drop-down menu showing the parse options ## Get a Ready-to-Use Code Snippet When the parse results match what you need, the Playground generates a Python script that reproduces the call, so you can parse the same document, or any other, from code. The Playground provides two versions: one for the [ade-python library](./ade-python) and one for calling the API directly. **To get the script:** 1. Click **Get Code** in the project header. The **View Code** pop-up opens. 2. Click the **Library** or **API** tab to see the code for each method. 3. Click the **Download** or **Copy** buttons to get the code. View Code dialog with Library and API tabs, showing the Python library script for Parse # Extract Data Source: https://docs.landing.ai/dpt3/extract Pull specific fields from Markdown with a schema for high-volume, repeatable extraction. Use the redesigned Extract API to pull specific data fields from a document. You provide a Markdown representation of the document and a schema that defines the fields you want, and the API returns their values in a structured, predictable format along with the location of each value in the source Markdown. The Extract API suits high-volume, repeatable workflows: use it when you need the same set of fields from many documents, such as invoice totals, contract dates, or form field values. Results stay consistent across documents with varying layouts because extraction is schema-driven. ## How Extract Works The Extract API works on a Markdown string. That Markdown can come from any source: the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse), a third-party parser, a web scraper, or a hand-authored document. For the best results, use Markdown produced by the Parse API, which preserves the document's reading order and structure and links each extraction back to its parse job. You pass the Markdown and a schema to the endpoint. The API returns the extracted values, per-field range grounding that points back into the source Markdown, and request metadata. To turn those ranges into visual locations (the blocks, page numbers, and bounding boxes each value came from), pass the results to the [Ground API](./ground). ## Sample Request Send the Markdown and a schema to the extract endpoint with a POST request. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key) and `parse-output.md` with the path to your Markdown file. ```bash cURL theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' ``` ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.v2.extract( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, ) print(response.extraction) ``` ```typescript TypeScript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const response = await client.v2.extract({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, }); console.log(response.extraction); ``` For the full request and response contract, see the [API reference](https://docs.landing.ai/api-reference/extract/ade-extract). # Extract Input Parameters Source: https://docs.landing.ai/dpt3/extract-input Set the Markdown, schema, options, and model version when calling the Extract API. The Extract API accepts Markdown, a schema that names the fields to pull, an optional model, and an optional `options` object. The same core fields work whether you [call it synchronously](https://docs.landing.ai/api-reference/extract/ade-extract) or create an [Extract Job](./extract-async), which takes a few additional parameters of its own. ## Sample Request Create an [Extract Job](./extract-async) on the `standard` service tier, then collect the extraction from the finished job. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key) and `parse-output.md` with the path to your Markdown file. ```bash cURL theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' \ -F 'service_tier=standard' ``` ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.extract_jobs.create( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, service_tier="standard", ) done = client.v2.extract_jobs.wait(job.job_id) print(done.result.extraction) ``` ```typescript TypeScript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.extractJobs.create({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, service_tier: "standard", }); const done = await client.v2.extractJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ExtractResult).extraction); ``` ## Parameters | Parameter | Required | Description | | ----------------- | ----------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `markdown` | Conditional | The Markdown content to extract from, sent as a string or an uploaded file. Provide either `markdown` or `markdown_url`. | | `markdown_url` | Conditional | A public URL that the API fetches the Markdown from. Provide either `markdown` or `markdown_url`. | | `schema` | Yes | The JSON Schema that defines the fields to extract. See [Extraction Schema (JSON)](./ade-extract-schema-json). | | `model` | No | The extraction model version. Defaults to the latest snapshot. See [Model Version](#model-version). | | `options` | No | A JSON object of optional settings. See [Options](#options). | | `service_tier` | No | Extract Jobs only: the tier the job runs on, either `standard` or `priority`. Defaults to `standard`. See [Choose a Service Tier](./extract-async#choose-a-service-tier). | | `output_save_url` | No | Extract Jobs only: a presigned URL the job delivers its output to, instead of returning it in `result`. See [Save Extraction Output to a URL](./extract-async#save-extraction-output-to-a-url). | ## Provide the Markdown The Extract API works on a Markdown string. That Markdown can come from any source: the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse), a third-party parser, a web scraper, or a hand-authored document. For the best results, use Markdown produced by the Parse API. Parse output preserves the document's reading order and structure, which improves extraction accuracy, and it embeds a `` comment that Extract reads automatically and echoes back as `metadata.doc_id`. This links each extraction to the parse job it came from. Pass the Markdown in one of two ways: * `markdown`: the Markdown content, sent as a string or an uploaded file. * `markdown_url`: a public URL that the API fetches the Markdown from. Provide exactly one of these fields per request. ## Set the Extraction Schema Set the extraction schema in the `schema` field. The schema is a JSON object with a `properties` map that names each field and describes what to extract. The schema must meet specific format and property requirements. For detailed guidance, see [Extraction Schema (JSON)](./ade-extract-schema-json). ## Options Pass optional settings in the `options` field as a JSON object. The Extract API accepts one option: | Option | Type | Default | Description | | -------- | ------- | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `strict` | boolean | `false` | Controls how the API handles schema content it cannot honor. When `false` (default), fields the model cannot extract are skipped, unsupported schema keywords are ignored, and extraction continues. When `true`, the API returns a `422` error in either case. | To enable strict mode, add it to your request. In cURL, pass the `options` form field; the client libraries expose it as the top-level `strict` parameter: ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' \ -F 'options={"strict": true}' \ -F 'service_tier=standard' ``` ```python Python highlight={14} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.extract_jobs.create( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, strict=True, service_tier="standard", ) done = client.v2.extract_jobs.wait(job.job_id) print(done.result.extraction) ``` ```typescript TypeScript highlight={14} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.extractJobs.create({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, strict: true, service_tier: "standard", }); const done = await client.v2.extractJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ExtractResult).extraction); ``` ## Model Version By default, requests use the latest snapshot of the extraction model. To pin to a specific snapshot, supply it in the `model` form field. The resolved version is returned in `metadata.model_version`. Use the `-latest` alias for development or when you want continuous improvements; pin to a dated snapshot for production workloads where consistent results matter. | Value | Behavior | | ------------------ | ----------------------------------------------------------------- | | `extract-latest` | The latest snapshot of the extraction model. This is the default. | | `extract` | Alias for `extract-latest`; resolves to the latest snapshot. | | `extract-20260903` | The snapshot generated on September 3, 2026. | | `extract-20260819` | The snapshot generated on August 19, 2026. | | `extract-20260710` | The snapshot generated on July 10, 2026. | To set the model, add the `model` field to your request: ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' \ -F 'model=extract-latest' \ -F 'service_tier=standard' ``` ```python Python highlight={14} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.extract_jobs.create( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, model="extract-latest", service_tier="standard", ) done = client.v2.extract_jobs.wait(job.job_id) print(done.result.extraction) ``` ```typescript TypeScript highlight={14} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.extractJobs.create({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, model: "extract-latest", service_tier: "standard", }); const done = await client.v2.extractJobs.wait(job.job_id); console.log((done.result as LandingAIADE.V2ExtractResult).extraction); ``` Some snapshots have been superseded: a newer snapshot replaced them, and they no longer appear in the table above. If you pin a superseded snapshot, your requests still succeed. The API resolves the name to the current snapshot and reports the current version in `metadata.model_version`. Update pinned code to a value from the table. # Extraction Schema (JSON) Source: https://docs.landing.ai/dpt3/ade-extract-schema-json Structure the JSON schema that tells Extract which fields to pull and how to format output. ## Overview An extraction schema is a JSON object that defines which fields to extract from a document and how to structure the output. You pass the schema to the ADE Extract API along with Markdown content generated by the ADE Parse API. Use this article as a reference for understanding how schemas are structured and how the API handles unsupported keywords. ## Basic Structure The extraction schema must follow this structure: ```json theme={null} { "type": "object", "properties": { "your_field_name": { "type": "string", "description": "Describe what to extract." } } } ``` **Example** This schema extracts two fields from an invoice. It also includes the optional `x-alternativeNames` keyword to account for field name variations across documents: ```json theme={null} { "type": "object", "properties": { "total_invoice_amount": { "description": "The total monetary value of the invoice, including all charges and taxes.", "x-alternativeNames": [ "Total Invoice Amount", "Grand Total", "Amount Due" ], "type": "number" }, "bank_name": { "description": "The official name of the bank where the payment will be deposited.", "x-alternativeNames": [ "Bank Name", "Beneficiary Bank", "Financial Institution" ], "type": "string" } } } ``` ### Top-Level Type Requirement The top-level `type` keyword must be `"object"`. Schemas with a different top-level type will return an error. In the following example, the highlighted line shows the required top-level `type` keyword: ```json highlight={2} theme={null} { "type": "object", "properties": {} } ``` ## Define Each Field Each field you want to extract is defined as a property inside the `properties` keyword. Each property can include the following: | | Required | Description | | ------------------------------------------ | --------------------------- | ---------------------------------------------------------------------------- | | [Field name](#field-names) | Required | The key used to identify the extracted value in the output. | | [`type`](#supported-field-types) | Required | The data type of the extracted value. | | [`description`](#field-descriptions) | Optional | Natural-language description of what to extract. | | [`enum`](#restrict-values-with-enum) | Optional | Restricts the extracted value to a set of allowed values. | | [`format`](#format) | Optional | Instructions for how to format the extracted value. | | [`x-alternativeNames`](#alternative-names) | Optional | Alternative labels for the field that may appear across different documents. | | [`properties`](#properties-for-objects) | Required for `object` types | Defines the fields within a nested object. | | [`items`](#format-arrays-with-items) | Required for `array` types | Defines the structure of items in an array. | ### Field Names **Required.** The field name is the key that identifies each property in the `properties` object and determines how the extracted value is labeled in the output. Field names can contain letters, numbers, underscores, and hyphens. Use descriptive, specific names that clearly indicate what data to extract: * `invoice_number` instead of `number` * `patient_name` instead of `name` In the following example, the highlighted lines are field names: ```json highlight={4, 13} theme={null} { "type": "object", "properties": { "account_holder": { "description": "The name of the individual or entity who owns the bank account.", "x-alternativeNames": [ "Account Holder", "Account Owner", "Primary Account Holder" ], "type": "string" }, "ending_balance": { "description": "The total amount of money in the account at the end of a specific period.", "x-alternativeNames": [ "Ending Balance", "Final Balance", "Closing Balance" ], "type": "number" } } } ``` ### Supported Field Types **Required.** Use the `type` keyword to define the data type of the extracted value. Supported types are: | Type | Description | | --------- | -------------------------------------------------------------------------------------------------------------------------------------- | | `array` | A list of items. To see an example, go to [Arrays](#format-arrays-with-items). | | `boolean` | True or false values. | | `integer` | Whole numbers. | | `number` | Numeric values, including decimals. Use this type for monetary values or when you need to perform calculations on the extracted value. | | `object` | A nested structure. To see an example, go to [Nested Objects](#nested-objects). | | `string` | Text values. | In the following example, the highlighted line shows the `type` keyword: ```json highlight={12} theme={null} { "type": "object", "properties": { "statement_date": { "description": "The date on which the financial statement was issued.", "format": "Month DD, YYYY", "x-alternativeNames": [ "Statement Date", "Date of Statement", "Billing Date" ], "type": "string" } } } ``` To restrict a field to a specific set of allowed values, use the [`enum`](#restrict-values-with-enum) keyword. ### Restrict Values with Enum **Optional.** Use the `enum` keyword to restrict the extracted value to a specific set of allowed values. Only string values are supported. Include `"type": "string"` in the field definition. Any non-string values are converted to strings. For example, the following schema restricts the extracted account type to one of three allowed values. The highlighted lines show the `type` and `enum` keywords: ```json highlight={5, 12-16} theme={null} { "type": "object", "properties": { "account_type": { "type": "string", "description": "The classification of the bank account, such as checking or savings, with specific features.", "x-alternativeNames": [ "Account Type", "Type of Account", "Account Category" ], "enum": [ "Premium Checking", "Basic Checking", "Savings" ] } } } ``` In the Playground, "enum" appears as a field type option in the **Type** drop-down menu. When you export the schema, the Playground outputs this correctly using the `enum` keyword. ### Field Descriptions **Optional.** Use the `description` keyword to help the API identify and extract the correct data. The more specific your descriptions, the more accurate the extraction. Include the following in your descriptions: * Exactly what data to extract * What to include or exclude (for example, "excluding tax" or "including area code") In the following example, the highlighted line shows the `description` keyword: ```json highlight={6} theme={null} { "type": "object", "properties": { "total_amount": { "type": "number", "description": "Total amount in USD, excluding tax" } } } ``` ### Format **Optional.** Use the `format` keyword to specify how the extracted value should be formatted. This is most commonly applied to `string` fields. The `format` keyword accepts natural-language instructions and standard [JSON Schema format values](https://www.learnjsonschema.com/2020-12/format-annotation/format/). Natural-language instructions offer more flexibility, since you can describe formatting requirements that don't have a standard equivalent. We recommend experimenting with different values to find what works best for your use case. The following examples illustrate the range of options: | `format` value | Output example | | ------------------------------------------------------- | ------------------ | | `YYYY-MM-DD` | `2026-01-17` | | `Month DD, YYYY` | `January 17, 2026` | | `Currency amount with the $ symbol, for example $12.50` | `$170.23` | | `Two-letter US state code` | `CA` | In the following example, the highlighted line shows the `format` keyword: ```json highlight={6} theme={null} { "type": "object", "properties": { "statement_date": { "type": "string", "format": "YYYY-MM-DD", "description": "The date on which the financial statement was issued." } } } ``` ### Alternative Names **Optional.** Use the `x-alternativeNames` keyword to list alternative labels for a field. This helps the API locate the correct data when documents use different labels for the same field, such as "Invoice Number" versus "Reference Number." In the following example, the highlighted lines show the `x-alternativeNames` keyword: ```json highlight={6-10} theme={null} { "type": "object", "properties": { "total_amount": { "type": "number", "x-alternativeNames": [ "Total Amount", "Grand Total", "Amount Due" ], "description": "The total monetary value of the invoice." } } } ``` ### Properties (For Objects) **Required for `object` types.** Use the `properties` keyword to define the fields within a nested object. For a full example, see [Nested Objects](#nested-objects). ### Format Arrays with `items` **Required for `array` types.** Use the `items` keyword to define the structure of items in an array. For a full example, see [Arrays](#arrays). ## Nested Objects Use nested objects when the data you want to extract has a natural hierarchical structure. For example, an invoice might include a billing address with multiple sub-fields (street, city, state, and ZIP code), or a patient form might have separate sections for personal details and insurance information. In the following example, the highlighted lines show a nested `properties` keyword inside the `invoice` object: ```json highlight={6-19} theme={null} { "type": "object", "properties": { "invoice": { "type": "object", "properties": { "number": { "type": "string", "description": "Invoice number" }, "date": { "type": "string", "description": "Invoice date" }, "total": { "type": "number", "description": "Total amount" } } } } } ``` ## Arrays Use arrays to extract repeating structures from a document, such as all rows in a table. Each item in the array follows the same schema, making arrays well-suited for data like transaction lists, invoice line items, or lists of charges. To define an array field: 1. Set `"type": "array"` on the field. 2. Include the `items` keyword to define the structure of each item. 3. Inside `items`, define the fields each item should contain. The following example extracts financial transactions from a bank statement, where each transaction is an object with three fields: ```json highlight={11, 12-44} theme={null} { "type": "object", "properties": { "transactions": { "description": "A list of all financial transactions recorded for the account.", "x-alternativeNames": [ "Transaction History", "Activity Log", "Movements" ], "type": "array", "items": { "type": "object", "properties": { "date": { "description": "The date when the transaction occurred.", "format": "YYYY-MM-DD", "x-alternativeNames": [ "Transaction Date", "Date of Transaction", "Activity Date" ], "type": "string" }, "description": { "description": "A brief description of the transaction.", "x-alternativeNames": [ "Transaction Description", "Details", "Item" ], "type": "string" }, "type": { "description": "The type of transaction, for example debit, credit, deposit, or withdrawal.", "x-alternativeNames": [ "Transaction Type", "Category", "Kind" ], "type": "string" } } } } } } ``` ## Keyword Support The ADE Extract API only supports a specific set of JSON Schema keywords. Unsupported keywords are removed before extraction runs; they do not cause errors. ### Supported Keywords The ADE Extract API supports the following keywords. For details on each, see [Define Each Field](#define-each-field). * [`description`](#field-descriptions) * [`enum`](#restrict-values-with-enum) (string values only) * [`format`](#format) * [`items`](#format-arrays-with-items) * [`properties`](#properties-for-objects) * [`type`](#supported-field-types) * [`x-alternativeNames`](#alternative-names) * `additionalProperties` (boolean values only) ### Ignored Keywords The following keywords are not supported but will not cause errors. The API removes or resolves them before running extraction. | Keyword | How the API handles it | | ---------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | Reference keywords: `$anchor`, `$defs`, `$id`, `$ref`, `$schema`, `definitions` | Used to define and reference reusable schema components. All references are resolved during schema conversion. The keywords are then removed. | | Recursive and dynamic keywords: `$dynamicAnchor`, `$dynamicRef`, `$recursiveAnchor`, `$recursiveRef` | Used for self-referential schemas. All references are resolved during schema conversion. The keywords are then removed. | | `anyOf` | To ensure consistent output, each field is limited to a specific type.
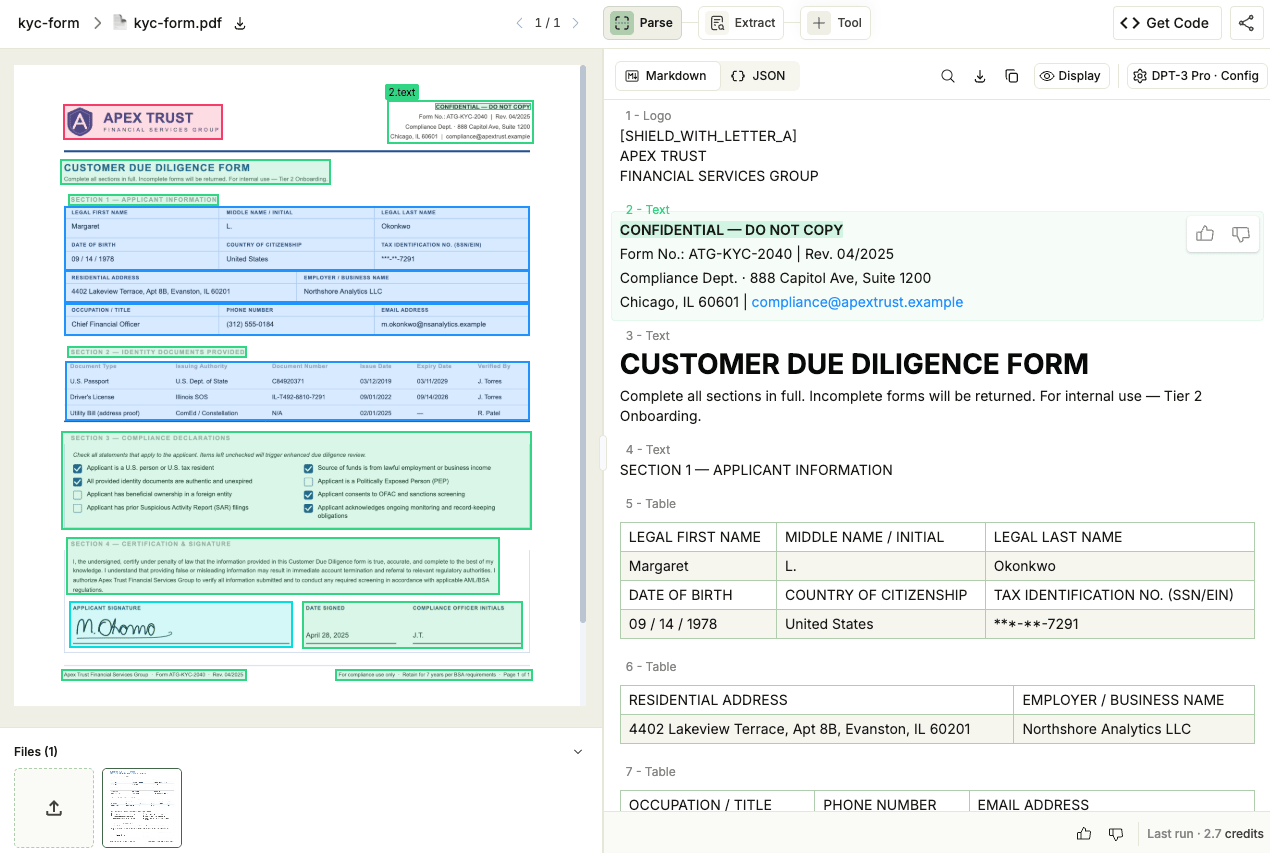
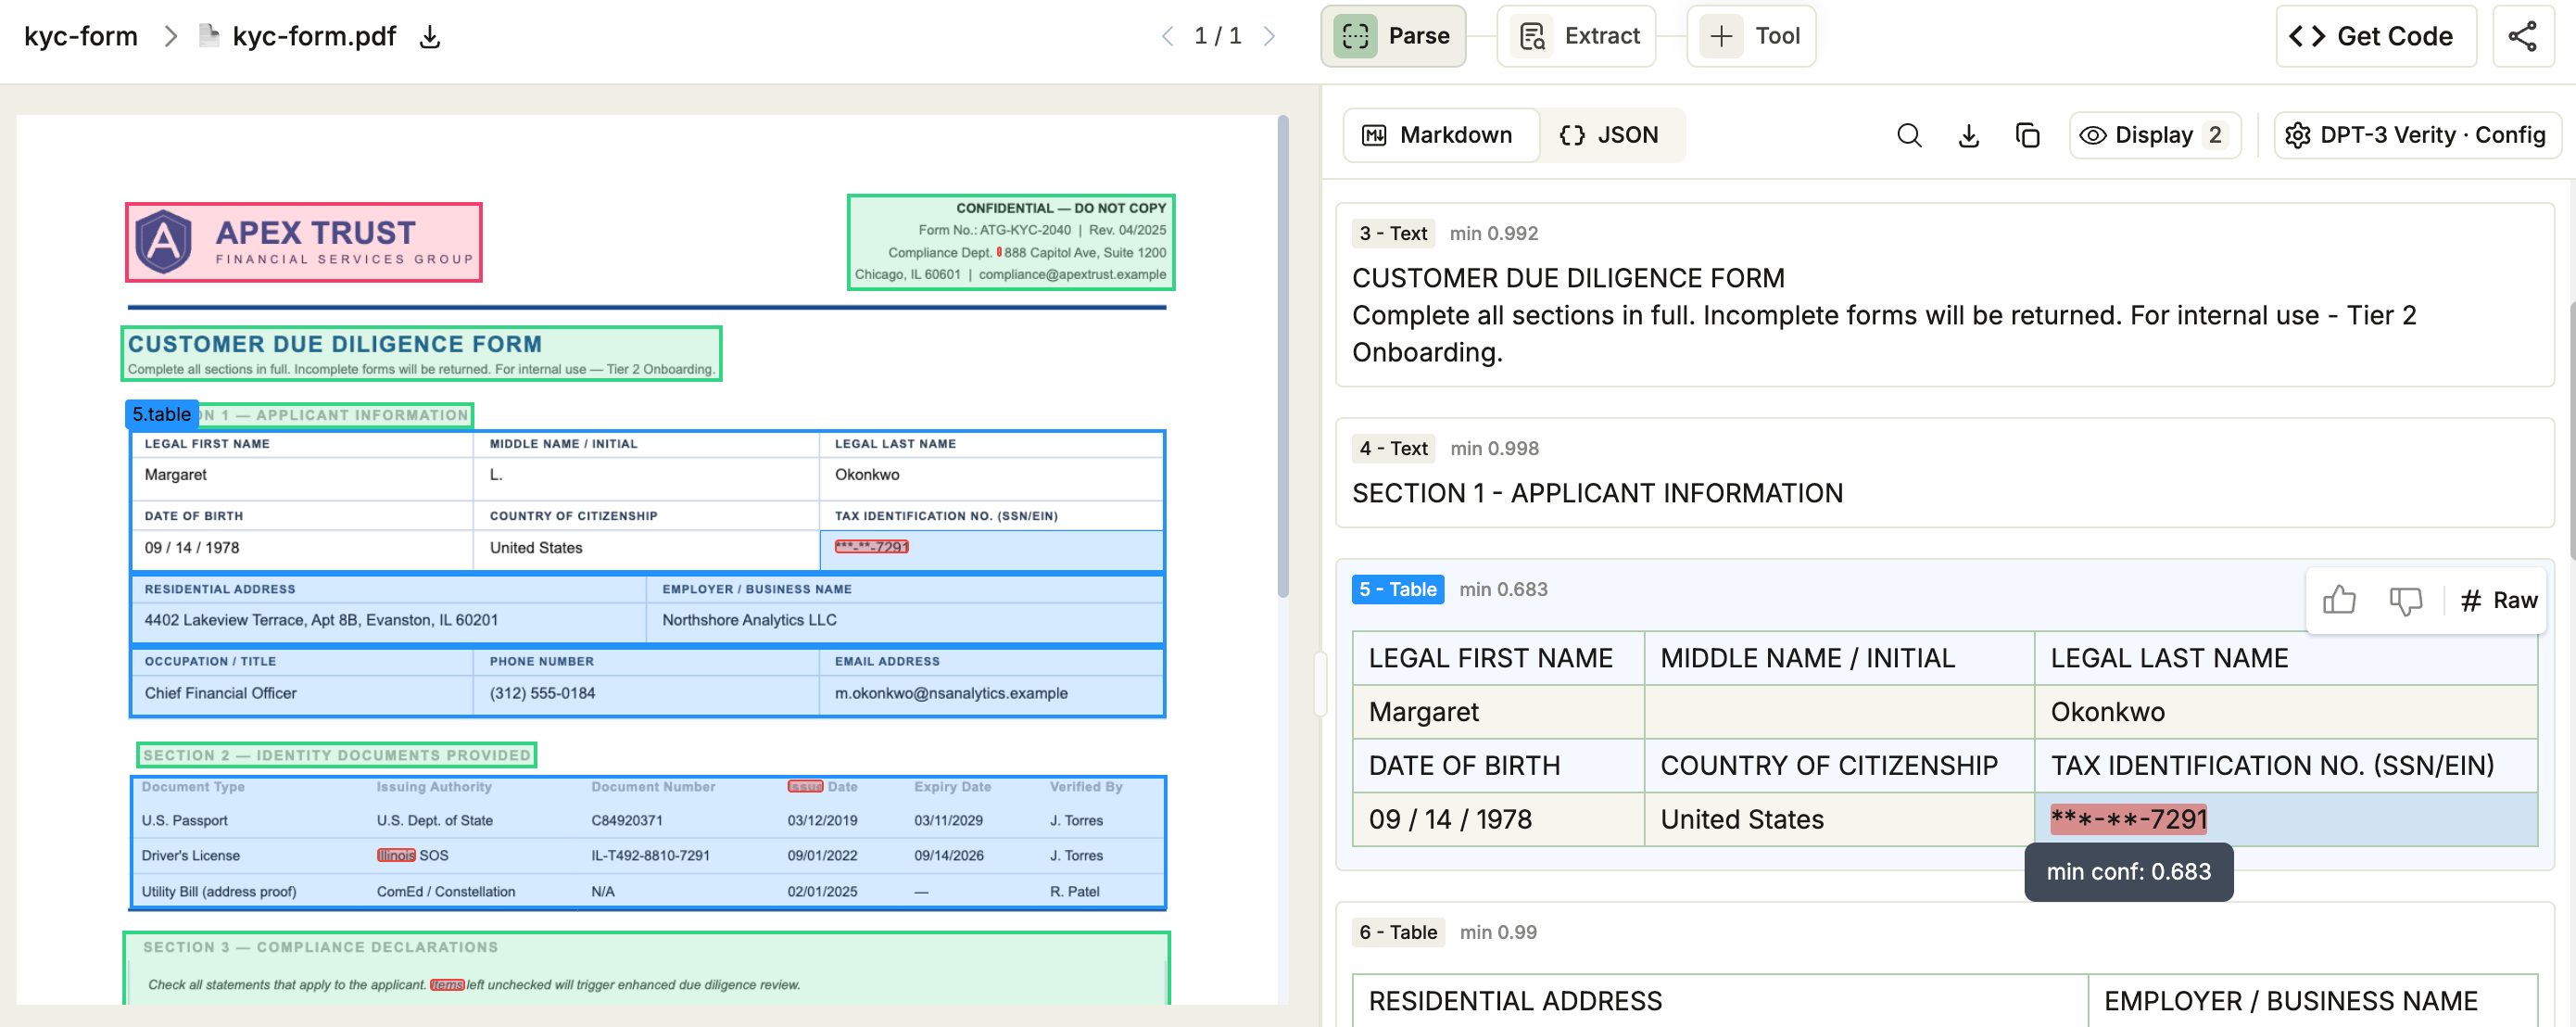
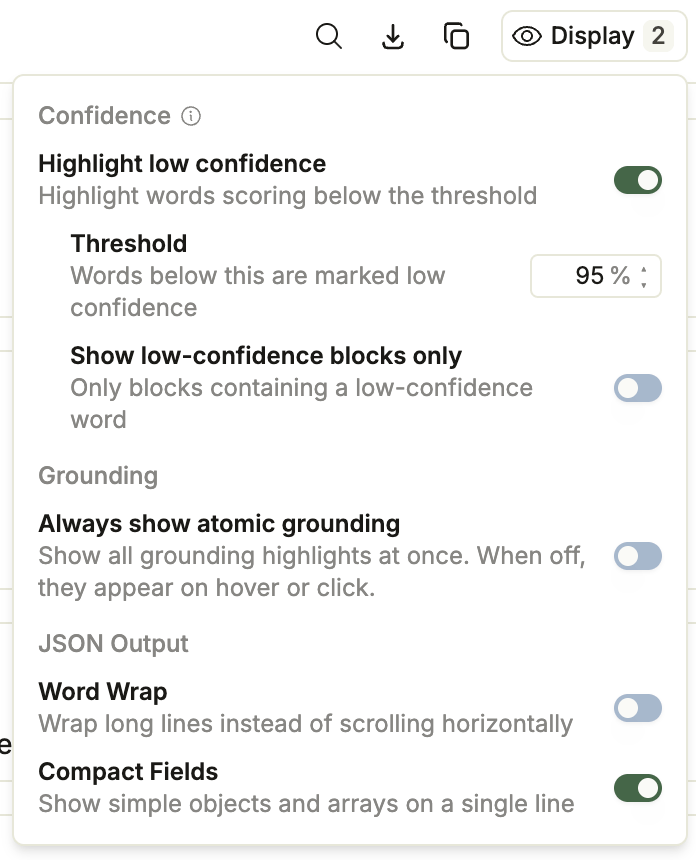
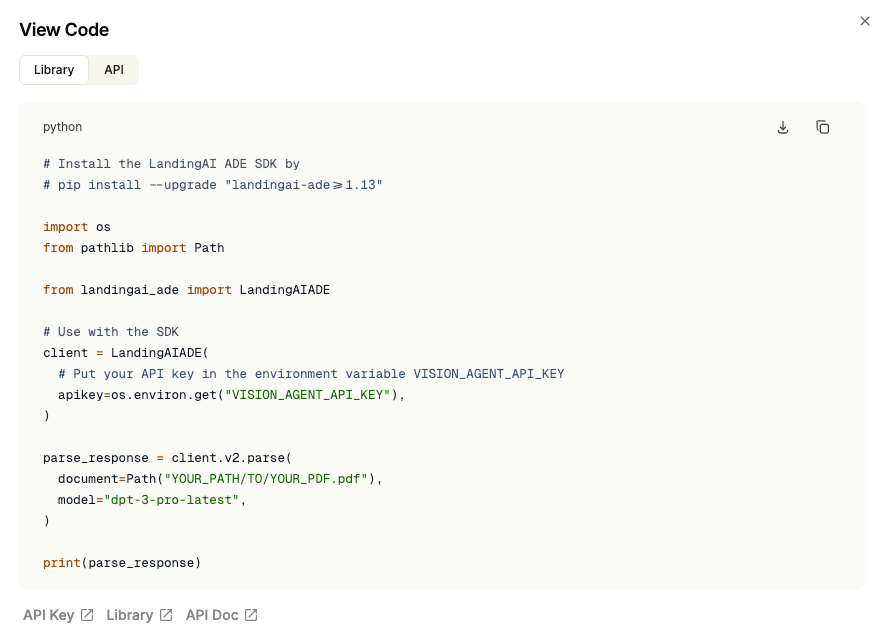
If one of the `anyOf` types is `null`, the API removes `null` and sets the `type` to the other specified type.

If none of the types are `null`, the API falls back to `string`, since that is least likely to cause issues. | | `default` | The API removes the keyword. | | `nullable` | The API removes the keyword. All fields are nullable by default. For more information, see [How the API Handles Missing Fields](#how-the-api-handles-missing-fields). | | `required` | The API removes the keyword. The API considers all fields to be required. | | `title` | The API removes the keyword. Typically, the title does not give additional information that is not already present in the field name or description. | ### Other Unsupported Keywords Any keyword not listed in [Supported Keywords](#supported-keywords) or [Ignored Keywords](#ignored-keywords) is removed during schema conversion, and extraction continues with the remaining schema. The following list provides common examples and is not exhaustive: * `allOf` * `const` * `maxItems` * `maxLength` * `maximum` * `minItems` * `minLength` * `minimum` * `oneOf` * `pattern` * `propertyOrdering` * `uniqueItems` ## How the API Handles Required Fields The ADE Extract API treats all fields as required and always attempts to extract every property defined in your schema. The `required` keyword is not supported and is ignored if included. For more information, see [Ignored Keywords](#ignored-keywords). If the API cannot find a field in the document, it returns `null` rather than an error. For more information, see [How the API Handles Missing Fields](#how-the-api-handles-missing-fields). ## How the API Handles Missing Fields All fields are nullable, meaning the API returns `null` when it cannot find a field in the document rather than returning an error. Because of this, the API ignores `null` and `nullable` if included in your schema. For more information, see [Ignored Keywords](#ignored-keywords). For example, if your schema includes a `first_name` field but the document does not contain a first name, the API returns `null` for that field. The exact behavior depends on the field type: | Field type | Behavior when not found | | ----------------------------------------------------------- | ----------------------------------------------------------------------- | | Primitive fields (`boolean`, `integer`, `number`, `string`) | Returns `null`. | | `array` | Returns an empty array: `[]`. | | `object` | Never returns `null`, but all primitive fields within it return `null`. | ## Schema Validation The API processes your schema in two stages: * [Before Extraction: Validate Schema Structure](#validate-schema-structure-before-extraction) * [During Processing: Convert Schema](#convert-schema-during-processing) ### Validate Schema Structure (Before Extraction) The API checks that your schema is valid JSON and follows the required structure. If validation fails, the API returns a `422` error before processing begins. Common causes are a schema that is not valid JSON, a root that is not `"type": "object"`, or recursive `$ref` cycles. ### Convert Schema (During Processing) The API converts your schema before running extraction. Keywords that are not supported are removed during this step (see [Ignored Keywords](#ignored-keywords) and [Other Unsupported Keywords](#other-unsupported-keywords)), and extraction continues with the remaining schema. ## FAQs for Extraction Schemas ### Does the order of properties in the schema need to match the order of the fields in the document? No. The order of properties in the schema has no impact on extraction. For example, a property defined last in the schema can still extract data from a field that appears at the top of the document. ### Is there a maximum number of fields that can be extracted? No. There is no maximum number of properties in an extraction schema. ### Can I put formatting and alternative names in the description field? You can include formatting instructions and alternative field names in `description`, but using the dedicated `format` and `x-alternativeNames` keywords is more effective. When you use dedicated keywords, the API knows exactly what each piece of information is: `format` contains only formatting instructions, and `x-alternativeNames` contains only alternative field labels. This allows the API to apply each more precisely than if the same information were embedded in a general description. For more information, see [Format](#format) and [Alternative Names](#alternative-names). ### What is the best practice for writing field descriptions? Be as specific as needed so there is no ambiguity about what to extract. Think of it as natural-language instructions (like prompting an LLM). The clearer and more specific it is, the better the results. You may want to iterate on your descriptions to find what works best for your use case. For more information, see [Field Descriptions](#field-descriptions). # Extract API Response Source: https://docs.landing.ai/dpt3/extract-response Read the Extract response: extracted values, per-field range grounding, and metadata. A successful extraction returns a JSON object with the extracted values, per-field metadata, and request metadata. ## Response Structure The response contains these top-level fields: * [`extraction`](#extracted-values-extraction): the extracted values, structured to match your schema. * [`extraction_metadata`](#per-field-metadata-extraction_metadata): per-field metadata with the range grounding for each value. * `markdown`: the input Markdown, echoed back unchanged. All `ranges` offsets index into this string. * [`metadata`](#request-metadata-metadata): request information such as the job ID, model version, and duration. * `warnings`: non-fatal warnings emitted during extraction. Empty when the extraction is clean. * `schema_violation_error`: set when `options.strict` is `false` and the schema contained fields the model could not extract; the extraction is partial. See [Status 206](./extract-troubleshoot#status-206-partial-success). When `warnings` or `schema_violation_error` is set, a synchronous request returns HTTP 206 instead of 200. An Extract Jobs poll always returns HTTP 200, with these fields inside `result`. ## Extracted Values (`extraction`) The `extraction` field contains the values extracted from the document, structured to match your schema exactly. When a value cannot be found in the source, it is returned as `null`. For a schema that requests a `revenue` field and a `summary` field, `extraction` returns: ```json theme={null} { "revenue": "$4.2M", "summary": "Strong Q1 driven by 12% YoY revenue growth and enterprise adoption" } ``` ## Per-Field Metadata (`extraction_metadata`) The `extraction_metadata` field mirrors the structure of `extraction`, with each leaf value replaced by a `{value, ranges}` object: * `value`: the extracted value, matching the corresponding leaf in `extraction`. * `ranges`: an array of `{"start": n, "end": n}` objects that locate the value in the input Markdown. See [Grounding with Ranges](#grounding-with-ranges). ```json theme={null} { "revenue": { "value": "$4.2M", "ranges": [{ "start": 164, "end": 169 }] }, "summary": { "value": null, "ranges": null } } ``` ### Grounding with Ranges Every extracted value is grounded: its `ranges` tell you where the value came from in the input Markdown. For each leaf value in `extraction_metadata`, `ranges` is an array of `{"start": n, "end": n}` objects. Each marks a `[start, end)` slice of the Markdown string you submitted, in Unicode code point offsets, so you can map any value back to its exact location in the text. For bounding boxes on the page (visual grounding), pass the response's `extraction_metadata` and the parse's `structure` to the [Ground API](./ground), which maps each field to the blocks it came from, with page numbers and coordinates. Each entry in the `ranges` array follows these rules: * Each object marks a range of characters, where `start` is inclusive and `end` is exclusive. * The `ranges` array can contain more than one object, because a single value can appear in more than one place in the document. * When a value is synthesized rather than copied from the source, both `value` and `ranges` are `null`. ### Slice the Markdown A value's `ranges` index into the returned `markdown` string, which echoes your input back unchanged, so you can quote the exact source text behind an extracted value. Offsets count Unicode code points, as declared by [`metadata.range_units`](#request-metadata-metadata). A value can have more than one range. Join the slices to reassemble its text: ```python Python theme={null} text = "".join(response["markdown"][r["start"]:r["end"]] for r in ranges) ``` ```javascript JavaScript theme={null} // Slice code points, not the string: JavaScript indexes strings by // UTF-16 code units, which drift from the code-point offsets when the // Markdown contains emoji or some CJK characters. const codePoints = Array.from(response.markdown); const text = ranges.map(({ start, end }) => codePoints.slice(start, end).join("")).join(""); ``` ## Request Metadata (`metadata`) The `metadata` field provides information about the request: | Field | Type | Description | | ------------------------- | -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `job_id` | string | The unique identifier for this request. | | `model_version` | string | The resolved model version, such as `extract-20260819`. | | `duration_ms` | number | The end-to-end request duration in milliseconds. | | `doc_id` | string \| null | The ID of the originating parse job. Present only when the input Markdown contains a `` comment (embedded by the Parse API). | | `range_units` | string | The units of every `ranges` offset in the response. Always `"unicode_codepoints"`. Declared explicitly because some languages index strings differently; see [Slice the Markdown](#slice-the-markdown). | | `openapi_spec` | string | The URL of the OpenAPI spec that describes this API. Use it for inspection or client generation. | | `input_markdown_chars` | number | The number of Unicode code points in the Markdown you submitted. This is the input basis of the credit charge. | | `output_extraction_chars` | number | The number of characters in the serialized extraction output. This is the output basis of the credit charge. Together with `input_markdown_chars`, it lets you verify the credit consumption from the response. See [Credit Consumption](./credit-consumption#extract). | | `billing` | object | Billing details: `service_tier` is the service tier the request ran on (`standard` or `priority`; synchronous requests always report `priority`), and `total_credits` is the credits consumed (`0` if none). See [Credit Consumption](./credit-consumption). | ## Example Response This response extracts a `revenue` value and a `summary` from a one-page financial report. The `revenue` value is grounded: its range covers the characters `$4.2M` in the input Markdown. The `summary` value is synthesized from the document as a whole rather than copied from one location, so its `value` and `ranges` are `null`. ```json theme={null} { "extraction": { "revenue": "$4.2M", "summary": "Strong Q1 driven by 12% YoY revenue growth and enterprise adoption" }, "extraction_metadata": { "revenue": { "value": "$4.2M", "ranges": [{ "start": 164, "end": 169 }] }, "summary": { "value": null, "ranges": null } }, "metadata": { "job_id": "extract-01k04h6t8rw2xq9v3m5npbsd4f", "doc_id": "parse-01k04g2b8xv9q3m5n7r2sd4tfe", "model_version": "extract-20260819", "range_units": "unicode_codepoints", "openapi_spec": "https://api.ade.landing.ai/openapi.json", "duration_ms": 843, "input_markdown_chars": 396, "output_extraction_chars": 100, "billing": { "service_tier": "priority", "total_credits": 0.4 } } } ``` # Asynchronous Extraction (Extract Jobs) Source: https://docs.landing.ai/dpt3/extract-async Extract from large Markdown documents asynchronously with Extract Jobs, then poll for results. Use Extract Jobs to extract structured data asynchronously. Instead of waiting for a single request to finish, you create a job, receive a `job_id` immediately, and retrieve the result when the job completes. Use Extract Jobs for long-running extractions, such as extracting from long documents or with large, complex schemas. ## Endpoints The request fields are the same as the synchronous Extract API. See [Extract Input Parameters](./extract-input). Extract Jobs uses these endpoints: | Method | Endpoint | Purpose | | ------ | --------------------------- | ----------------------------------- | | POST | `/v2/extract/jobs` | Create an extract job. | | GET | `/v2/extract/jobs/{job_id}` | Get the status and result of a job. | ## Workflow 1. Build your extraction schema. See [Extraction Schema (JSON)](./ade-extract-schema-json). 2. Submit the Markdown and schema to `POST /v2/extract/jobs`. 3. Get the `job_id` from the response. 4. Poll `GET /v2/extract/jobs/{job_id}` until `status` is `completed`. 5. Read the extracted fields from the job's `result`, or from `output_url` if you saved the output to a URL. See [Extract API Response](./extract-response). ## Create a Job Send the same fields you would send to the synchronous endpoint. Setting `service_tier` to `standard` runs the job in the lane that consumes half the credits of `priority`. Replace `YOUR_API_KEY` with your [API key](./agentic-api-key) and `parse-output.md` with the path to your Markdown file. ```bash cURL theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' \ -F 'service_tier=standard' ``` ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.extract_jobs.create( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, service_tier="standard", ) print(job.job_id) ``` ```typescript TypeScript theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.extractJobs.create({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, service_tier: "standard", }); console.log(job.job_id); ``` The request returns a `202` response with the `job_id` and the initial status: ```json theme={null} { "job_id": "extract-01k04h6t8rw2xq9v3m5npbsd4f", "status": "pending", "created_at": "2026-07-16T18:03:12Z" } ``` ### Choose a Service Tier Set the optional `service_tier` form field to control the job's turnaround time and credit consumption. Jobs run on the `standard` tier when you omit it. For how the tiers compare, see [Sync vs Async Processing](./sync-async). For credit consumption by tier, see [Credit Consumption](./credit-consumption#extract). | Tier | Behavior | | ---------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `standard` | Consumes half the credits of the `priority` tier, with a slower turnaround. The default, and the right choice for automated pipelines, background agent steps, and scheduled ingestion. | | `priority` | Consumes credits at the full rate, the same as Extract, with a faster turnaround. Use it for time-sensitive jobs where someone is waiting on the result. | **Set the tier.** Include the `service_tier` field in your create-job request, sending `standard` or `priority`. Setting it explicitly keeps the tier visible in code you copy between projects: ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' \ -F 'service_tier=standard' ``` ```python Python highlight={14} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.extract_jobs.create( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, service_tier="standard", ) print(job.job_id) ``` ```typescript TypeScript highlight={14} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.extractJobs.create({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, service_tier: "standard", }); console.log(job.job_id); ``` ## Get a Job Poll the job with its `job_id`. To be notified when the job finishes instead of polling, set up [webhooks](./webhooks). ```bash cURL theme={null} curl 'https://api.ade.landing.ai/v2/extract/jobs/JOB_ID' \ -H 'Authorization: Bearer YOUR_API_KEY' ``` ```python Python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() # Fetch the job once. Use client.v2.extract_jobs.wait("JOB_ID") to poll until it finishes. job = client.v2.extract_jobs.get("JOB_ID") print(job.status) if job.status == "completed": print(job.result.extraction) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); // Fetch the job once. Use client.v2.extractJobs.wait("JOB_ID") to poll until it finishes. const job = await client.v2.extractJobs.get("JOB_ID"); console.log(job.status); if (job.status === "completed") { console.log((job.result as LandingAIADE.V2ExtractResult).extraction); } ``` The response includes the job status and, once the job finishes, the result: | Field | Description | | -------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `job_id` | The unique identifier for the job. | | `status` | The current state of the job. See [Job Statuses](#job-statuses). | | `created_at` | When the job was created. | | `completed_at` | When the job finished. Present once the job reaches a final state. | | `progress` | An estimate of how close the job is to completion, between `0` and `1`, updated on each poll. Present only while the job is processing, and never reaches `1`. To detect completion, check for a `status` of `completed` instead. | | `result` | The extraction result, present when `status` is `completed` and you did not save the output to a URL. This object has the same shape as a synchronous response. See [Extract API Response](./extract-response). | | `output_url` | The location of the saved output, present only when you supplied `output_save_url`. When set, the output is delivered to the URL instead of returned in `result`. See [Save Extraction Output to a URL](#save-extraction-output-to-a-url). | | `metadata` | The job's `metadata` block, including `billing`. Present on completed jobs that saved their output to a URL, so you can confirm the model version and charge without fetching the file. For inline results, this information is in `result.metadata` instead. See [Extract API Response](./extract-response#request-metadata-metadata). | | `error` | Present when `status` is `failed`. Contains a `code` and a `message`. | ## Job Statuses | Status | Description | | ------------ | -------------------------------------------------------------------- | | `pending` | The job is accepted and queued, but has not started. | | `processing` | The job is running. | | `completed` | The job finished. Read the extraction from `result` or `output_url`. | | `failed` | The job did not finish. See the `error` field for details. | ## Save Extraction Output to a URL To write the extraction result to your own storage instead of retrieving it inline, pass the optional `output_save_url` parameter when you create the job. The result (the same shape as a synchronous response, including `metadata` with `billing`) is delivered to that URL, and the poll response reports `output_url` instead of `result`. The completed poll response also carries the job's `metadata`, so billing information is available without fetching the file. The `output_save_url` parameter is accepted only on job creation; the synchronous `/v2/extract` endpoint rejects it with a 422 error. The URL must be a presigned URL that grants time-limited write access to a single object, with the same requirements as Parse Jobs; see [URL Requirements](./parse-async#url-requirements). ```bash cURL highlight={5} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' \ -F 'output_save_url=YOUR_PRESIGNED_URL' ``` ```python Python highlight={14} theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() job = client.v2.extract_jobs.create( markdown=Path("parse-output.md").read_text(), schema={ "type": "object", "properties": { "revenue": {"type": "string", "description": "Q1 2024 revenue"} }, }, output_save_url="YOUR_PRESIGNED_URL", ) print(job.job_id) ``` ```typescript TypeScript highlight={14} theme={null} import fs from "fs"; import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const job = await client.v2.extractJobs.create({ markdown: fs.readFileSync("parse-output.md", "utf8"), schema: { type: "object", properties: { revenue: { type: "string", description: "Q1 2024 revenue" }, }, }, output_save_url: "YOUR_PRESIGNED_URL", }); console.log(job.job_id); ``` ## Zero Data Retention (ZDR) If Zero Data Retention (ZDR) is enabled for your organization, it applies to all Extract Jobs calls. No special parameters are required. Under ZDR, results are deleted as soon as you retrieve them. See [Result Retention](../ade/zdr#result-retention). ## Rate Limits Extract Jobs submissions are always accepted (HTTP 202) and never return a rate-limit error; jobs are paced internally instead. There is no input size cap. See [Rate Limits](./rate-limits#extract-api). # Troubleshoot Extraction Source: https://docs.landing.ai/dpt3/extract-troubleshoot Resolve Extract errors using status codes, causes, and fixes. Use this section to troubleshoot issues encountered when calling the Extract API (`/v2/extract`) and Extract Jobs (`/v2/extract/jobs`). ## Error Response Format Every API error returns a JSON body with two fields: ```json theme={null} { "code": "validation_error", "message": "schema: Field required" } ``` The `code` field is a stable identifier you can branch on, such as `validation_error`, `unknown_model_version`, `invalid_url`, `invalid_api_key`, or `rate_limit_exceeded`. The `message` field is a human-readable description; treat its exact wording as variable. The error messages quoted on this page are `message` values. ## Common Status Codes These status codes are handled at the account and gateway level and can apply to any request. | Status Code | Name | Description | What to Do | | ----------- | ------------------- | ----------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- | | 401 | Unauthorized | Missing or invalid API key. | Check that your `Authorization` header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. See [Rate Limits](./rate-limits). | | 502 | Bad Gateway | A transient infrastructure error interrupted the request. | Retry with exponential backoff. A synchronous request that fails to deliver a result is not billed. | | 503 | Service Unavailable | The service is temporarily unavailable. | Retry with exponential backoff. If the error persists, contact [support@landing.ai](mailto:support@landing.ai). | ## Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | -------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | 200 | Success | Extraction completed successfully. | Continue with normal operations. | | 206 | Partial Content | The extraction completed, but not cleanly. | Review the `warnings` and `schema_violation_error` fields. See [Status 206: Partial Success](#status-206-partial-success). | | 413 | Payload Too Large | The request payload exceeds the maximum allowed size. | Reduce the size of the Markdown you send. | | 422 | Unprocessable Entity | Input validation failed, including an unknown model version, an unusable `markdown_url`, or an invalid schema. | Review your request parameters. See [Status 422: Unprocessable Entity](#status-422-unprocessable-entity). | | 500 | Internal Server Error | Server error during processing. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500: Internal Server Error](#status-500-internal-server-error). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit (475 seconds). | Reduce document size or simplify the extraction schema. See [Status 504: Gateway Timeout](#status-504-gateway-timeout). | ## Status 206: Partial Success This status code indicates the extraction completed but not cleanly. The response body has the normal success shape, plus one or both of these signals: * The `schema_violation_error` field is set when `options.strict` is `false` and the schema contained fields the model could not extract. The extraction is partial: unsupported fields were skipped. * The `warnings` array lists non-fatal warnings emitted during extraction. **What to do:** * Review the flagged fields and adjust your schema, or set `options.strict` to `true` to fail the request with a 422 error instead. See [Schema Fields Not Supported (Strict Mode)](#error-schema-fields-not-supported-strict-mode). * For Extract Jobs, the poll response stays HTTP 200; check `warnings` and `schema_violation_error` inside `result` instead of relying on the status code. ## Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error `message` and adjust your request parameters. ### Error: markdown\_url Fetch Failed This error occurs when the Markdown cannot be fetched from the provided `markdown_url`. The URL is validated and fetched when you submit the request, so an unusable URL fails immediately, before any processing starts. **Error message:** ``` Failed to fetch markdown_url: HTTP 404 ``` or ``` Failed to fetch markdown_url: request timed out ``` or ``` Failed to fetch markdown_url: connection failed ``` **What to do:** * Verify the URL is publicly accessible and serves the Markdown directly. A URL that responds with a redirect is rejected; supply the final URL. * If the URL is presigned, confirm it has not expired. ### Error: Field extraction invalid This error occurs when the extraction process fails due to issues with the extraction schema or the extracted data. **Error message:** ``` Field extraction invalid: {error_details} ``` **What to do:** * Review the error details in the response. * Verify the JSON schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. * Ensure all required fields are properly defined in the schema. * Check if the document contains data that matches the schema structure. ### Error: Unknown Extract Version This error occurs when an unsupported model version is specified. The error `code` is `unknown_model_version`. **Error message:** ``` Unknown extract version '{version}'. Valid versions: {versions} (or extract-latest). ``` **What to do:** * Use one of the supported versions listed in the error message. * Use `extract-latest` to automatically use the latest version. * If you don't specify a version, the API uses the latest version by default. * For more information, go to [Model Version](./extract-input#model-version). ### Error: The provided schema is not valid JSON This error occurs when the `schema` parameter cannot be parsed as JSON. **Error message:** ``` The provided string is not valid JSON, let alone a schema. ``` **What to do:** * Verify your extraction schema is valid JSON. * Check for syntax errors such as missing commas, quotes, or brackets. * See [Extraction Schema (JSON)](./ade-extract-schema-json) for the required structure. ### Error: The provided schema must have "type": "object" for the root This error occurs when the `schema` is a valid JSON object, but its `type` keyword is not set to `"object"`. The extraction engine requires the root schema to explicitly declare `"type": "object"`. **Error message:** ``` Field extraction validation error: The provided schema must have "type": "object" for the root. ``` **What to do:** Set `"type": "object"` at the root of your schema. **Correct:** ```json {2} theme={null} { "type": "object", "properties": { "invoice_number": { "type": "string", "description": "Invoice number" } } } ``` **Incorrect:** ```json {2} theme={null} { "type": "array", "items": { "type": "object", "properties": { "invoice_number": { "type": "string", "description": "Invoice number" } } } } ``` ### Error: The provided JSON must parse to an object at the root This error occurs when the `schema` parameter is valid JSON, but the root value is not a JSON object. For example, the root is a JSON array (`[...]`), a string, or a number rather than `{...}`. **Error message:** ``` Field extraction validation error: The provided JSON must parse to an object at the root. ``` **What to do:** Wrap your schema in a JSON object (`{...}`). **Correct:** ```json {1,8} theme={null} { "type": "object", "properties": { "invoice_number": {"type": "string"}, "vendor_name": {"type": "string"}, "total": {"type": "number"} } } ``` **Incorrect:** ```json theme={null} ["invoice_number", "vendor_name", "total"] ``` ### Error: The provided JSON object was not a valid JSON schema This error occurs when the `schema` parameter contains a JSON object that does not conform to the JSON Schema specification. **Error message:** ``` Field extraction validation error: The provided JSON object was not a valid JSON schema. Error: {error_details} ``` **What to do:** * Review the error details to identify the specific schema issue. * Check that every `type` value is a JSON Schema type (`string`, `number`, `integer`, `boolean`, `object`, `array`, or `null`). A custom type such as `"money"` fails validation, and the error details report that the value `is not valid under any of the given schemas`. * Verify your schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). ### Error: The provided schema contains recursive local \$ref cycles This error occurs when the extraction schema contains circular `$ref` references (for example, a schema that references itself). **Error message:** ``` Field extraction validation error: The provided schema contains recursive local `$ref` cycles, which are not supported. ``` **What to do:** Remove circular `$ref` references from your schema. Restructure nested types to avoid self-referencing definitions. ### Error: Fields the model cannot extract (strict mode) This error occurs when [`strict`](./extract-input#options) is `true` and the schema contains one or more fields the model cannot extract. When `strict` is `false` (default), those fields are skipped and extraction continues. **What to do:** * Confirm the document actually contains the data for the fields that could not be extracted. * Refine each field's `description` and `x-alternativeNames` to help the model locate the data. See [Field Descriptions](./ade-extract-schema-json#field-descriptions) and [Alternative Names](./ade-extract-schema-json#alternative-names). * To skip fields that cannot be extracted instead of returning an error, set `strict` to `false`. ### Error: Schema fields not supported (strict mode) This error occurs when [`strict`](./extract-input#options) is `true` and the schema contains keywords the extraction engine does not support. When `strict` is `false` (default), unsupported keywords are ignored and extraction continues. **Error message:** ``` The following schema fields were not supported: {keywords} ``` **What to do:** * Remove the listed keywords from your schema. See [Extraction Schema (JSON)](./ade-extract-schema-json) for the supported schema features. * To ignore unsupported keywords instead of returning an error, set `strict` to `false`. ### Error: Cannot provide both 'markdown' and 'markdown\_url' This error occurs when both a Markdown file and a URL to a Markdown file are provided in the same request. **Error message:** ``` Cannot provide both 'markdown' and 'markdown_url'. Please provide only one. ``` **What to do:** Choose one input method: * Provide a Markdown file using the `markdown` parameter, OR * Provide a URL to a Markdown file using the `markdown_url` parameter. ### Error: Provide exactly one Markdown source This error occurs when your request does not include a Markdown source. **Error message:** ``` provide exactly one of markdown or markdown_url ``` **What to do:** Add one of these parameters to your request: * Use the `markdown` parameter to upload a Markdown file, OR * Use the `markdown_url` parameter to provide a URL to a Markdown file. ### Error: No markdown file or URL provided This error occurs when you include a `markdown` or `markdown_url` parameter in your request, but the value is empty or blank. **Error message:** ``` No markdown file or URL provided. ``` **What to do:** * If using `markdown`: Ensure you are uploading a valid Markdown file (not an empty file or blank value). * If using `markdown_url`: Ensure the parameter contains a valid URL (not an empty string or blank value). * Verify that your request properly includes the file or URL value. ### Error: Invalid URL format This error occurs when the `markdown_url` parameter contains a value that is not a valid URL. **Error message:** ``` Invalid URL format: {url} ``` **What to do:** * Verify the URL is properly formatted with a valid protocol (http\:// or https\://). * Check for typos or missing characters in the URL. * Ensure the URL is properly encoded if it contains special characters. ### Error: Multiple Markdown files detected This error occurs when multiple Markdown files are included in the request. **Error message:** ``` Multiple markdown files detected (X). Please provide only one document file. ``` **What to do:** Send only one Markdown file per request. ### Error: Unsupported format This error occurs when you provide a file other than Markdown (.md) to the extract endpoint, such as PDF, DOCX, XLSX, or image files. **Error message:** ``` Unsupported format: {mime_type} ({filename}). Supported formats: MD ``` **What to do:** * The extract endpoint only accepts Markdown files with a .md extension. * If you have a PDF, DOCX, or other document format, use the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse) to convert your document to Markdown first. * Ensure your file has a .md extension and contains valid UTF-8 encoded Markdown content. ### Error: service\_tier Is Only Valid on Extract Jobs This error occurs when a request to the synchronous Extract endpoint (`POST /v2/extract`) includes the `service_tier` parameter. Service tiers only apply to asynchronous endpoints, like Extract Jobs. The parameter is rejected even when its value is empty. **Error message:** ``` service_tier (or its deprecated alias priority) is only valid on the async POST /v2/extract/jobs route; sync runs in the fast lane already ``` **What to do:** * Remove the `service_tier` parameter from Extract requests. Extract always runs on the `priority` tier. See [Sync vs Async Processing](./sync-async). * To choose a service tier, create an Extract Job instead. See [Choose a Service Tier](./extract-async#choose-a-service-tier). ### Error: output\_save\_url Expired or Expires Too Soon This error occurs when you create an Extract Job with an `output_save_url` whose presigned URL is already expired or does not stay valid long enough for the job to complete. The output is delivered when the job completes, so the URL must have at least 15 minutes of remaining validity at submission. The error `code` is `invalid_url`. **Error message:** ``` output_save_url presigned URL expired {time} ago; sign a fresh URL valid for at least {required} ``` or ``` output_save_url presigned URL expires in {remaining}, but this request requires at least {required} of validity (the URL must outlive the job; it is used at completion, not at submit) ``` **What to do:** * Sign a fresh presigned URL with a longer validity and create the job again. The job is rejected before processing starts, so no credits are consumed. * For Azure SAS URLs, also confirm the token grants write (`w`) or create (`c`) permission. A URL without write access is rejected with a similar 422 error. * Sign delivery URLs with long-lived credentials. A URL signed with temporary session credentials can pass this check but still fail at delivery if the session expires before the job completes. ## Status 500: Internal Server Error This error indicates an unexpected server error occurred during processing. **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 504: Gateway Timeout This error occurs when the extraction process exceeds the timeout limit (475 seconds). You are not billed for a request that times out. **Error message:** ``` v2-extract did not complete within 475s; use POST /v2/extract/jobs for long-running work ``` **What to do:** * Reduce the size of your Markdown document. * Simplify your extraction schema and verify it follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. * Use [Extract Jobs](./extract-async) instead. Jobs are not subject to the synchronous timeout. See [Sync vs Async Processing](./sync-async). * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Extract Jobs These status codes apply to the asynchronous [Extract Jobs](./extract-async) endpoints. ### Create a Job These status codes apply to `POST /v2/extract/jobs`. | Status Code | Name | Description | What to Do | | ----------- | --------------------- | -------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------- | | 202 | Accepted | The job was queued successfully. The response contains the `job_id`. | Poll `GET /v2/extract/jobs/{job_id}` to track status and retrieve the result. | | 409 | Conflict | A job with the same identifier already exists. | Retry the request. | | 422 | Unprocessable Entity | Input validation failed. | The causes and fixes match the synchronous Extract API. See [Status 422](#status-422-unprocessable-entity). | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. See [Rate Limits](./rate-limits#extract-api). | | 500 | Internal Server Error | Server error while creating the job. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | ### Get a Job These status codes apply to `GET /v2/extract/jobs/{job_id}`. | Status Code | Name | Description | What to Do | | ----------- | --------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | The job was retrieved. When `status` is `completed`, the response includes the `result`. When `status` is `failed`, the `error` field describes what went wrong. Jobs have a maximum run time of 6 hours; a job that exceeds it fails. | Read the `status` field. | | 404 | Not Found | No job with the given ID exists for your API key. | Verify the `job_id` matches the value returned when you created the job, and that you are using the same API key. | | 410 | Gone | The job completed, but its result is no longer stored. The error code is `result_expired`. For when results are deleted, see [Result Retention](../ade/zdr#result-retention). | Submit a new job to run the extraction again. | | 500 | Internal Server Error | Server error while retrieving the job. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | | 503 | Service Unavailable | The stored result could not be retrieved. The error code is `result_store_unavailable`. This is a transient condition. The result has not expired. | Retry with exponential backoff instead of re-running the job. If the error persists, contact [support@landing.ai](mailto:support@landing.ai). | ## When Are Credits Consumed? Credits are consumed only when the API returns a 200 or 206 status code. Error responses do not consume credits. For Extract Jobs, credits are consumed only when a job reaches the `completed` status; failed jobs do not consume credits. For more information, see [Credit Consumption](./credit-consumption). # Ground Extracted Fields Source: https://docs.landing.ai/dpt3/ground Map extracted fields to the blocks they were quoted from, and get page numbers and bounding boxes for each value. The [Ground API](https://docs.landing.ai/api-reference/ground/ade-ground) maps each field extracted by [Extract](./extract) back to the blocks it was quoted from in the [Parse](./parse) response, and returns each one with its id, page number, and bounding box. A **block** is one piece of content Parse detected on a page, such as a paragraph, a table, a single table cell, or a figure. Extract already locates every value in the Markdown text through [range grounding](./extract-response#grounding-with-ranges). Ground turns those text locations into visual ones, so you can highlight values on a rendering of the page, build review interfaces where a person clicks a field and sees where it came from, attach citations to extracted data, or crop the region a value appears in. Ground runs synchronously and [consumes no credits](./credit-consumption#ground). ## How Ground Works Both objects you send describe positions in the same Markdown string. A field's `ranges` say which characters the value was quoted from. A block's `grounding.range` says which characters the block covers. Ground overlaps the two and returns every block a field's ranges fall inside. The join is stateless. Nothing is stored server-side, and the block ids in the response resolve only against the `structure` you send in the same request. You send two objects you already have from earlier responses: * `extraction_metadata`: the per-field metadata returned by [Extract](./extract-response#per-field-metadata-extraction_metadata), whose leaves are `{value, ranges}` objects. * `structure`: the block tree returned by [Parse](./parse-response#structure-pages-and-blocks), whose blocks each carry a `grounding` object. ## Pair the Extraction with Its Own Parse The `extraction_metadata` must come from an Extract call that ran on the `markdown` of the same Parse response the `structure` came from. Re-parsing invalidates an older extraction, because block ranges shift between parses even of the same file. If the locations come back wrong, see [Troubleshoot Grounding](./ground-troubleshoot#the-locations-point-at-the-wrong-content). Ground cannot detect a mismatched pair, so check it in code. The Extract response's `metadata.doc_id` carries the `job_id` of the parse whose `markdown` it read: ```python theme={null} assert extract_response.metadata.doc_id == parse_response.metadata.job_id ``` ## Call the Ground API Send both objects to the ground endpoint with a POST request. The endpoint accepts a JSON body (used by the libraries below) or multipart form data with each field JSON-serialized (used in the cURL example). The cURL example assumes you saved the Parse response to `parse.json` and the Extract response to `extract.json`. ```bash cURL theme={null} jq '.structure' parse.json > structure.json jq '.extraction_metadata' extract.json > extraction-metadata.json curl -X POST 'https://api.ade.landing.ai/v2/ground' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'extraction_metadata= For the full request and response contract, see the [API reference](https://docs.landing.ai/api-reference/ground/ade-ground). ## The Grounding Tree The response's `grounding` field mirrors your `extraction_metadata` tree: nested objects and arrays keep their shape, so a nested field like `issuer.name` resolves to `grounding.issuer.name`. Each `{value, ranges}` leaf is replaced by one of three values: | Leaf value | What it means | | ---------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | A list of blocks | The blocks the field's ranges overlap, in reading order. | | `null` | The field's `ranges` was `null`, so nothing in the document was quoted for it. Either the model synthesized the value or it did not find one. There is no source passage to look up. | | `[]` | The ranges were valid but overlapped no block. This usually means the `extraction_metadata` and `structure` are from different parses. See [Pair the Extraction with Its Own Parse](#pair-the-extraction-with-its-own-parse). | ### Matching Blocks Only content blocks are returned. The `page` nodes in the `structure` never appear, because pages are containers rather than content. Each returned block reports its own page number in `grounding.page` instead. A field with multiple ranges pools the blocks from all of them, without duplicates. A single range can still match more than one block: a value inside a table matches both the `table` and the `table_cell` that contains it, so you can highlight the whole table or just the cell. Each entry in the list identifies one block from the `structure` you sent: | Field | Description | | ------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `block_id` | The block's `id` in the `structure` tree, such as `text-1` or `table_cell-3`. Use it to look the block up. Block ids resolve only against the `structure` sent in the same request. | | `type` | The block's type. See [Block Types](./parse-response#block-types). | | `parent_id` | The id of the enclosing block. Present only on nested blocks: a `table_cell` names its `table`. | | `grounding` | The block's own `{page, range, box}` object, copied unchanged from the `structure`. The `box` is in normalized page coordinates. See [Working with Boxes](./parse-response#working-with-boxes) for converting it to pixels. | | `atomic_grounding` | The matching subset of the block's own [`atomic_grounding`](./parse-response#atomic-grounding) entries. See [Matches Inside a Block](#matches-inside-a-block). | ### Matches Inside a Block The `grounding` on a returned block covers the whole block. When the block also carries [`atomic_grounding`](./parse-response#atomic-grounding), the response narrows the location to the individual entries the field's ranges overlap, each with its own, tighter box. Each entry is an `{index, page, range, box}` object, and carries a [`confidence`](./parse-response#word-confidence-scores-dpt-3-verity) score as well on a DPT-3 Verity parse. The `index` is the entry's position in the block's own `atomic_grounding` array, so you can match it back to the block's full list. A returned block can also carry no entries at all: | Value | What it means | | ------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `[]` | The block's range matched, but no individual entry did. Highlight the block's own `box` instead. A `table_cell` reports this on a DPT-3 Pro parse, which gives cells no finer detail than the cell itself. | | No `atomic_grounding` key | The block has no `atomic_grounding` of its own. A `table` never does. | ## Example Response This response grounds three fields extracted from a one-page PDF parsed with DPT-3 Pro. The `report_number` was quoted from a text block, so the returned block carries the matching line entry. The `serial_number` sits in a table, so its range matches both the `table` and the `table_cell` that contains it. The report has no purchase order, so `purchase_order` has no source passage and its grounding is `null`. ```json expandable theme={null} { "grounding": { "report_number": [ { "block_id": "text-0", "type": "text", "grounding": { "page": 1, "range": { "start": 43, "end": 143 }, "box": { "xmin": 0.7558, "ymin": 0.06102, "xmax": 0.91343, "ymax": 0.11799 } }, "atomic_grounding": [ { "index": 0, "page": 1, "range": { "start": 43, "end": 67 }, "box": { "xmin": 0.77067, "ymin": 0.06525, "xmax": 0.90643, "ymax": 0.07522 } } ] } ], "serial_number": [ { "block_id": "table-0", "type": "table", "grounding": { "page": 1, "range": { "start": 298, "end": 719 }, "box": { "xmin": 0.09481, "ymin": 0.23333, "xmax": 0.90513, "ymax": 0.34713 } } }, { "block_id": "table_cell-7", "type": "table_cell", "parent_id": "table-0", "grounding": { "page": 1, "range": { "start": 482, "end": 493 }, "box": { "xmin": 0.7532, "ymin": 0.26184, "xmax": 0.90513, "ymax": 0.29022 } }, "atomic_grounding": [] } ], "purchase_order": null }, "metadata": { "job_id": "ground-01m1n7d2apjktw530s7bnfmnst", "duration_ms": 118, "openapi_spec": "https://api.ade.landing.ai/openapi.json", "billing": { "service_tier": "priority", "total_credits": 0.0 } } } ``` ## Metadata The `metadata` field provides information about the request: | Field | Type | Description | | -------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------ | | `job_id` | string | The unique identifier for this request, prefixed `ground-`. | | `duration_ms` | number | The end-to-end request duration in milliseconds. | | `openapi_spec` | string | The URL of the OpenAPI spec that describes this API. Use it for inspection or client generation. | | `billing` | object | Billing details: `service_tier` reports `priority`, and `total_credits` is always `0.0`. Grounding [consumes no credits](./credit-consumption#ground). | ## Limits * The Ground API is synchronous only. There is no Ground Jobs API, because the join completes quickly and the response arrives inline. * There is no `model` parameter. The join is a deterministic overlap computation, so there is no model version to pin. * The Ground API is not available for organizations with [Zero Data Retention](../ade/zdr) enabled. Requests from ZDR-enabled organizations return a 501 error. See [Troubleshoot Grounding](./ground-troubleshoot#status-501-not-implemented). # Troubleshoot Grounding Source: https://docs.landing.ai/dpt3/ground-troubleshoot Resolve Ground errors using status codes, causes, and fixes. Use this section to troubleshoot issues encountered when calling the [Ground API](./ground) (`/v2/ground`). ## Error Response Format Every API error returns a JSON body with two fields: ```json theme={null} { "code": "validation_error", "message": "structure: Field required" } ``` The `code` field is a stable identifier you can branch on, such as `validation_error` or `not_implemented`. The `message` field is a human-readable description; treat its exact wording as variable. The error messages quoted on this page are `message` values. ## Common Status Codes These status codes are handled at the account and gateway level and can apply to any request. | Status Code | Name | Description | What to Do | | ----------- | ------------------- | --------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------- | | 401 | Unauthorized | Missing or invalid API key. | Check that your `Authorization` header is present and contains a valid [API key](./agentic-api-key). | | 502 | Bad Gateway | A transient infrastructure error interrupted the request. | Retry with exponential backoff. | | 503 | Service Unavailable | The service is temporarily unavailable. | Retry with exponential backoff. If the error persists, contact [support@landing.ai](mailto:support@landing.ai). | ## Ground Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Grounding completed successfully. | A `200` response can still carry wrong locations, because a mismatched pair is not an error. See [The Locations Point at the Wrong Content](#the-locations-point-at-the-wrong-content). | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See [Status 422: Unprocessable Entity](#status-422-unprocessable-entity). | | 500 | Internal Server Error | Server error during processing. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | | 501 | Not Implemented | Your organization has Zero Data Retention enabled. | See [Status 501: Not Implemented](#status-501-not-implemented). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit (475 seconds). Grounding normally completes well within that limit, so this is rare even for very large inputs. | Retry. If the error persists, contact [support@landing.ai](mailto:support@landing.ai). | ## Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error `message` and adjust your request. ### Error: Field Required This error occurs when the request is missing `extraction_metadata` or `structure`. Both fields are required. **Error message:** ``` structure: Field required ``` or ``` extraction_metadata: Field required ``` **What to do:** * Include both fields in the request body: the `extraction_metadata` object from an [Extract response](./extract-response#per-field-metadata-extraction_metadata) and the `structure` object from the matching [Parse response](./parse-response#structure-pages-and-blocks). * If you send multipart form data, confirm each field's value is a JSON-serialized object. An empty or unparseable value also fails validation. ## Status 501: Not Implemented This error occurs when your organization has [Zero Data Retention](../ade/zdr) (ZDR) enabled. The Ground API is not available for ZDR-enabled organizations, because the request carries extracted document content in `extraction_metadata`. **What to do:** * Compute grounding client-side instead: every block in the Parse response's `structure` carries its own `grounding.range`, so you can overlap each field's `ranges` against the blocks yourself. See [Grounding with Ranges](./extract-response#grounding-with-ranges) and [Grounding: Where Things Are](./parse-response#grounding-where-things-are). * If your organization does not need ZDR, you can ask to turn it off by contacting [support@landing.ai](mailto:support@landing.ai). ## The Locations Point at the Wrong Content Grounding returned `200` and every field has blocks, but the boxes land on the wrong part of the page, or one value in a batch is highlighted somewhere unrelated. This is what a mismatched `extraction_metadata` and `structure` normally look like. The ranges are still valid numbers, so they overlap whatever blocks sit at those offsets in the `structure` you sent. Two parses of the same document produce similar offsets, so most locations come back correct and only some are wrong. Nothing in the response marks the difference. **What to do:** * Verify the pairing rather than judging it by eye, by comparing the Extract response's `metadata.doc_id` with the Parse response's `metadata.job_id`. See [Pair the Extraction with Its Own Parse](./ground#pair-the-extraction-with-its-own-parse). * If you re-parse a document, re-run the extraction too. Block ranges shift between parses, even of the same file, so an old extraction cannot be grounded against a new `structure`. * If the pair checks out, confirm you did not edit the `markdown` between the Parse call and the Extract call. Inserting or removing characters shifts every offset after the edit. ## Every Field Returns an Empty Array Grounding returned `200`, but every field's grounding is `[]`. Valid ranges that overlap no block almost always mean the two inputs are from different parses, and far enough apart that no offsets overlap at all: the `extraction_metadata` offsets index a different Markdown string than the one the `structure` describes. **What to do:** * Work through [The Locations Point at the Wrong Content](#the-locations-point-at-the-wrong-content). An empty result has the same cause as a wrong one, and the same fix. * Check that the `structure` is the whole tree from the Parse response, not a single page or a trimmed subtree. A structure covering only part of the document has no blocks at most offsets. ## A Field Returns Null Instead of Blocks A field whose grounding is `null` is not an error. The field's `ranges` was `null` in the `extraction_metadata`, so nothing in the document was quoted for it. Check the field's value in the Extract response to tell the two causes apart: * The value is present. The model synthesized it (for example, a summary or an inferred flag) rather than quoting it, so there is no source passage to point to. * The value is `null`. The model did not find the field in the document at all. **What to do:** * If a synthesized field should have been quoted, refine its schema `description` so the model extracts a literal value. See [Extraction Schema (JSON)](./ade-extract-schema-json). * Handle `null` in your rendering code: show the value without a source highlight, or show the field as not found. ## When Are Credits Consumed? The Ground API never consumes credits. Every call is still recorded in your usage history. For more information, see [Credit Consumption](./credit-consumption#ground). # Sync vs Async Processing Source: https://docs.landing.ai/dpt3/sync-async Decide when to run work synchronously or as a job by comparing turnaround, timeouts, limits, and credits per service tier. ## Sync vs Async The Parse and Extract APIs give you two ways to run work: * **Synchronous**: Call [Parse](./parse) or [Extract](./extract) and get the result in the response. * **Asynchronous**: Create a [Parse Job](./parse-async) or [Extract Job](./extract-async) and collect the result when the job finishes. [Webhooks](./webhooks) can notify you when a job finishes, so you don't have to poll. The [Ground API](./ground) always runs synchronously, so neither choice applies to it. You cannot select a tier for it either. Like every synchronous request it runs on `priority`, and it consumes no credits. ## Service Tiers Every request runs on a service tier: `priority` or `standard`. * The tier controls the turnaround time, the credit consumption rate, and which rate limit the request draws from. * The tier does not change the supported file size or the number of pages allowed per file. * Synchronous requests always run on the `priority` tier. * Jobs run on the `standard` tier by default. Set the `service_tier` parameter to run a job on the `priority` tier. * All `priority` work (synchronous requests and `priority` jobs) counts against one shared per-minute rate limit. A document with more pages than that per-minute limit cannot run on the `priority` tier. Run it as a `standard` job instead. See [Rate Limits](./rate-limits#run-large-documents-as-async-jobs-on-the-standard-tier). ## Choose a Processing Mode and Service Tier Use the table to choose the right call for your workload. Turnaround times are estimates, not guaranteed speeds. Rate limit values depend on your pricing plan; for the values and how each API meters usage, see [Rate Limits](./rate-limits). For per-page credit rates, see [Credit Consumption](./credit-consumption).
Parse and Extract (synchronous) Parse Jobs and Extract Jobs (asynchronous)
Service tier Priority Standard (default)
Best for Interactive workflows: a person or agent is waiting on the result Time-sensitive work that a synchronous request can't handle: files over the synchronous size cap, or when you don't want to hold a connection open Work with no one waiting: automated pipelines, background agent steps, scheduled ingestion, and the largest documents
How you get the result Inline in the response Poll the job, or save the output to a URL Poll the job, or save the output to a URL
Estimated turnaround time Seconds to minutes Seconds to minutes Minutes to hours
Timeout limit 475 seconds 6 hours 6 hours
Credit consumption Full rate Full rate Half the priority rate
Parse limits per request 6,000 pages; 50 MiB 6,000 pages; 1 GiB for PDFs, 50 MiB for images 6,000 pages; 1 GiB for PDFs, 50 MiB for images
Largest single document (Parse) Your plan's per-minute page limit: 100 pages (Explore), 200 (Team). Enterprise limits are custom. 6,000 pages
Parse rate limit Per-minute limit shared across all priority work, refilling continuously Hourly limit, resetting each hour
Extract limits per request No input size limit No input size limit No input size limit
Extract rate limit Based on your plan and the input Markdown size None: jobs are accepted immediately and paced internally None: jobs are accepted immediately and paced internally
## Set the Service Tier [Parse](./parse) and [Extract](./extract) do not accept the `service_tier` parameter. To run a [Parse Job](./parse-async) or an [Extract Job](./extract-async) on the `priority` tier, set the `service_tier` parameter when you create the job. ```bash highlight={4} theme={null} curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'service_tier=priority' ``` ## Confirm the Service Tier To confirm which tier a request ran on, check `metadata.billing.service_tier` in the response. See [Parse API Response](./parse-response#metadata) and [Extract API Response](./extract-response#request-metadata-metadata). # Webhooks Source: https://docs.landing.ai/dpt3/webhooks Receive signed events when Parse and Extract jobs finish, instead of polling for job status. Verify signatures and handle retries. Webhooks notify your systems the moment a [Parse Job](./parse-async) or [Extract Job](./extract-async) finishes, so you don't have to poll for job status. Register an HTTPS endpoint in **[Playground](https://ade.landing.ai/)** > **Settings** > **Webhooks**, and it receives a signed POST request when a job succeeds or fails. Events carry the job's identifiers and status, never the content of the document. ## When to Use Webhooks Any job can be polled, so webhooks matter where polling works poorly: poll frequently and most requests return `processing`, poll slowly and finished results sit unclaimed. One push per job replaces that loop. This is most valuable when many jobs run at once, when a finished parse should immediately trigger the next pipeline stage, and when failures should raise an alert rather than wait to be noticed. ## Webhook Events The `parse` and `extract` events fire when a run reaches its final state. When the result is fetchable from the API, the event includes a `result_url`. See [Event Payload](#event-payload) for the variants. Synchronous [Parse](./parse) and [Extract](./extract) requests also fire events, but never include a `result_url`, because the result was already returned in the API response. | Event | When it fires | | ------------------- | ---------------------------------------------------------------------------------------------------------------------------------------- | | `parse.succeeded` | A parse run finished successfully. | | `parse.failed` | A parse run failed. | | `extract.succeeded` | An extract run finished successfully. | | `extract.failed` | An extract run failed. | | `webhook.test` | Sent to one endpoint when you click **Send test event** in the Playground. Ignores event subscriptions. See [Test Events](#test-events). | ## How Long Results Are Available Job results are available for 24 hours after the job completes. If your organization uses [Zero Data Retention](../ade/zdr#result-retention) (ZDR), a result is also deleted as soon as you fetch it, so the `result_url` works once. If your pipeline may act on events late (for example, working through a backlog after downtime), fetch results promptly on receipt, or create jobs with `output_save_url` so the output is delivered to your own storage as soon as the job finishes. See [Events for Saved Output](#events-for-saved-output). ## Set Up a Webhook Endpoint Create an endpoint on your side first: an HTTPS URL that accepts POST requests and returns a `2xx` status code. The URL must be publicly reachable. For local development, use a tunnel such as ngrok. Then register the endpoint. Registration happens in the [Playground](https://ade.landing.ai/) only, because there is no API for managing endpoints: 1. Go to **[Playground](https://ade.landing.ai/)** > **Settings** > **Webhooks**. Endpoints belong to the workspace you create them in: your organization or your personal account. 2. Click **Add Endpoint**. 3. Enter the **Endpoint URL**. 4. (Optional) Enter a **Description** so your team knows what the endpoint is for. 5. Select the events to subscribe to. If you select none, the endpoint receives all events. 6. Click **Create endpoint**. 7. Copy the signing secret and store it securely, such as in a secret manager. The secret is shown only once. You use it to [verify event signatures](#verify-event-signatures). 8. Click **Send test event** to confirm your endpoint receives and verifies a signed event. See [Test Events](#test-events). ## Event Payload The event body is compact JSON that identifies the job and, when the result is fetchable from the API, carries a URL for it. It never contains document content, which keeps sensitive data out of the systems around your webhooks, such as request logs and log aggregators. ```json parse.succeeded theme={null} { "type": "parse.succeeded", "timestamp": "2026-08-14T18:02:11.482209+00:00", "data": { "job_id": "parse-01k04g2b8xv9q3m5n7r2sd4tfe", "status": "completed", "result_url": "https://api.ade.landing.ai/v2/parse/jobs/parse-01k04g2b8xv9q3m5n7r2sd4tfe", "result_expires_at": "2026-08-15T18:02:11.482209+00:00" } } ``` | Field | Description | | ------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `type` | The [event type](#webhook-events). | | `timestamp` | When the run finished (ISO 8601). Stable across delivery retries. | | `data.job_id` | The job identifier. For jobs, poll or fetch the job with it. Use it to correlate the event with your own records. | | `data.status` | The final status: `completed` or `failed`. | | `data.result_url` | The authenticated API URL for fetching the result. The same URL you poll for [Parse Jobs](./parse-async#monitor-a-parse-job) and [Extract Jobs](./extract-async#get-a-job). Call it with your API key. Present only when the result is retrievable from the API. | | `data.result_expires_at` | The result is not available after this time (ISO 8601). See [How Long Results Are Available](#how-long-results-are-available). | | `data.result_retained` | Present and `false` only when the result can't be fetched from the API: the run was synchronous, or the output was delivered to your storage under ZDR. | | `data.delivery` | Present only when the job saved its output to your storage. See [Events for Saved Output](#events-for-saved-output). | ### Events for Failed Runs Failed job events carry only the job ID and status. Fetch the job to get the error details. For a failed synchronous request, the error was already returned in the API response. ```json parse.failed theme={null} { "type": "parse.failed", "timestamp": "2026-08-14T18:02:11.482209+00:00", "data": { "job_id": "parse-01k04g2b8xv9q3m5n7r2sd4tfe", "status": "failed" } } ``` ### Events for Saved Output If you created the job with `output_save_url`, the event adds a `delivery` receipt confirming that the result was written to your URL, with the status code your storage returned. See [Save Parsed Output to a URL](./parse-async#save-parsed-output-to-a-url) and [Save Extraction Output to a URL](./extract-async#save-extraction-output-to-a-url). ```json extract.succeeded with saved output theme={null} { "type": "extract.succeeded", "timestamp": "2026-08-14T18:02:11.482209+00:00", "data": { "job_id": "extract-01k04h6t8rw2xq9v3m5npbsd4f", "status": "completed", "result_url": "https://api.ade.landing.ai/v2/extract/jobs/extract-01k04h6t8rw2xq9v3m5npbsd4f", "result_expires_at": "2026-08-15T18:02:11.482209+00:00", "delivery": { "status": "delivered", "destination": "output_save_url", "status_code": 200 } } } ``` If your organization uses [ZDR](../ade/zdr), the result is deleted as soon as it is delivered to your `output_save_url`. The event then has no `result_url`, and `result_retained` is `false`. The `delivery` receipt is your confirmation that the job finished and where the output went. See [Result Retention](../ade/zdr#result-retention). ```json extract.succeeded with ZDR theme={null} { "type": "extract.succeeded", "timestamp": "2026-08-14T18:02:11.482209+00:00", "data": { "job_id": "extract-01k04h6t8rw2xq9v3m5npbsd4f", "status": "completed", "result_retained": false, "delivery": { "status": "delivered", "destination": "output_save_url", "status_code": 200 } } } ``` ### Test Events Clicking **Send test event** on an endpoint sends a `webhook.test` event to that endpoint only. The event is signed like any real event, so it exercises your signature verification end to end. The `job_id` is synthetic (prefixed `test-`), there is never a `result_url`, and the send gets one attempt with no retries. ```json webhook.test theme={null} { "type": "webhook.test", "timestamp": "2026-08-27T18:02:11.482209+00:00", "data": { "job_id": "test-01k04j8x2mv6q9r3t5w7yzbcde", "status": "completed", "result_retained": false } } ``` ## Verify Event Signatures Every event is signed following the [Standard Webhooks](https://www.standardwebhooks.com/) specification, so you can confirm that an event is authentic and wasn't altered in transit. Verify the signature before acting on any event. Each delivery includes three headers: | Header | Description | | ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `webhook-id` | The unique message ID: the job ID and event type joined with a period. Stable across delivery retries, so use it as your idempotency key to skip events you already processed. | | `webhook-timestamp` | When this delivery attempt was sent (Unix seconds). A fresh value per attempt. | | `webhook-signature` | The signature: `v1,` followed by a base64-encoded hash-based message authentication code (HMAC-SHA256) of the ID, timestamp, and raw body. Can contain multiple space-delimited signatures. Match any one of them. | Use a Standard Webhooks library instead of comparing hashes yourself: the libraries compare in constant time and reject stale timestamps, which blocks replay attacks. Verify with the endpoint's own signing secret, and pass the raw request body exactly as received. Re-serialized JSON changes the bytes and fails verification. ```python Python theme={null} # pip install standardwebhooks from standardwebhooks import Webhook wh = Webhook("whsec_YOUR_SIGNING_SECRET") def handle_webhook(raw_body: bytes, headers: dict) -> None: # Raises WebhookVerificationError if the signature is invalid. event = wh.verify(raw_body, headers) print(event["type"], event["data"]["job_id"]) ``` ```typescript TypeScript theme={null} // npm install standardwebhooks import { Webhook } from "standardwebhooks"; const wh = new Webhook("whsec_YOUR_SIGNING_SECRET"); function handleWebhook(rawBody: string, headers: Record) { // Throws if the signature is invalid. const event = wh.verify(rawBody, headers) as { type: string; data: { job_id: string } }; console.log(event.type, event.data.job_id); } ``` ## Delivery and Retries Your endpoint has 15 seconds to respond. Return a `2xx` status code as soon as you have recorded the event, and do any heavy processing afterward. Any `2xx` counts as delivered. Any other response, or a timeout, counts as a failed attempt. Failed deliveries are retried with increasing delays, from 30 seconds up to 2 hours between attempts: up to 14 attempts over roughly 12 hours. Retries reuse the same `webhook-id`, so deduplicating by that header makes a redelivered event harmless. Every delivery attempt is recorded in the endpoint's delivery log in **Playground** > **Settings** > **Webhooks**, including the response status and body (truncated to 4 KB). Responding **410 Gone** permanently cancels the remaining retries for that event. It does not unsubscribe the endpoint, and future events are still delivered. To stop all deliveries, disable or delete the endpoint in **Playground** > **Settings** > **Webhooks**. ## Troubleshoot Webhooks Use this section to troubleshoot issues with webhook endpoints and event deliveries. ### Signature Verification Fails Verification fails when the secret, the body, or the timestamp doesn't match what was signed. Check the three requirements in [Verify Event Signatures](#verify-event-signatures): the endpoint's own secret, the raw body bytes (web frameworks often parse and re-serialize JSON automatically), and an accurate server clock. To reproduce a delivery locally, use **Copy as curl** on the delivery in the delivery log. If you lost the endpoint's secret, delete the endpoint and create it again to get a new one. ### Endpoint Stopped Receiving Events Check the endpoint in **Playground** > **Settings** > **Webhooks**: deliveries stop when the endpoint is disabled or deleted, or when its event subscriptions change. Review the delivery log to see what was sent and what your endpoint returned. After fixing the receiver, click **Send test event** to confirm deliveries reach it. ### Missed or Duplicate Events If your receiver was down for longer than the retry window (roughly 12 hours), the missed deliveries are not resent. To recover, call [List Parse Jobs](./parse-async#list-parse-jobs) to find parse jobs you haven't processed, and fetch each one. Extract Jobs has no list endpoint, so keep the `job_id` from each create response on your side. Duplicates are expected with webhooks in general. Deduplicate by `webhook-id`. ### Fetching the Result Returns an Error A `result_url` fetch returns status 410 with the error code `result_expired` when the result is no longer available. See [How Long Results Are Available](#how-long-results-are-available). # Rate Limits Source: https://docs.landing.ai/dpt3/rate-limits See how rate and size limits work for the Parse and Extract APIs, and the largest document each service tier accepts. Rate limits cap how much work your organization can submit in a given time window, so one user or an accidental traffic spike cannot slow processing for everyone else. Limits apply per organization, so all API keys in an organization share them. When you exceed a rate limit, the API returns an HTTP 429 response. Wait before retrying and use exponential backoff. ## Parse API The [Parse API](./parse) has two kinds of limits: * [size limits](#size-limits) on each request * [rate limits](#rate-limits) on the pages you process over time ### Size Limits Size limits apply per request and differ between synchronous requests and async jobs: | Limit | Synchronous | Async jobs | | ------------------------ | ------------------------------------------- | ----------------------------------------- | | Maximum document size | 50 MiB | 1 GiB for PDFs, 50 MiB for images | | Maximum pages | 6,000 per PDF (an image counts as one page) | 6,000 per PDF | | Maximum image resolution | 178,956,970 pixels (about 179 megapixels) | 178,956,970 pixels (about 179 megapixels) | ### Rate Limits Every request counts against one of two rate limits, one per [service tier](./sync-async), and the two limits are independent of each other. Each [parsing model family](./parse-models) also has its own independent set of these limits, with the same values: pages parsed with DPT-3 Verity do not count against DPT-3 Pro's limits, and vice versa. Synchronous requests and `priority` jobs count against the same `priority` limit, so splitting traffic across the two routes does not increase capacity. Jobs run on the `standard` tier by default. To set a job's tier, see [Choose a Service Tier](./parse-async#choose-a-service-tier). | Plan | Priority limit (refills continuously) | Standard limit (resets each hour) | | ---------- | ------------------------------------- | --------------------------------- | | Explore | 100 pages per minute | 6,000 pages per hour | | Team | 200 pages per minute | 12,000 pages per hour | | Enterprise | Custom | Custom | The Explore values apply once you purchase credits. During the free trial, a lower `standard` limit applies. ### Run Large Documents as Async Jobs on the Standard Tier A parse request is admitted against its tier's rate limit all at once. This means a document with more pages than your `priority` per-minute limit can never run on the `priority` tier: the request returns a 429 error no matter how long you wait between retries. The error message states the limit and the fix. This is by design. The `priority` tier is sized for interactive work, so your plan's [per-minute limit](#rate-limits) is also the largest single document the tier accepts. Submit larger documents as a [Parse Job](./parse-async) on the `standard` tier, which accepts up to 6,000 pages per PDF. ## Extract API The [Extract API](./extract) has no input size limit, and rate limiting differs between synchronous requests and async jobs. The synchronous limit depends on your pricing plan. For jobs, the service tier affects turnaround time and credit consumption only. To set a job's tier, see [Choose a Service Tier](./extract-async#choose-a-service-tier). | Limit | Synchronous | Async jobs | | ------------------ | ---------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------- | | Maximum input size | No limit | No limit | | Rate limit | Based on the size of the input Markdown (a `markdown_url` counts as a single unit) | None: [Extract Jobs](./extract-async) are accepted immediately (HTTP 202) and paced internally, so a burst of jobs waits in the queue instead of failing | # Supported Languages Source: https://docs.landing.ai/ade/ade-languages Learn which languages ADE supports for parsing. Agentic Document Extraction supports a wide range of languages, with extraction accuracy influenced by script type, image clarity, and formatting. The language support on this page applies to DPT-2 and DPT-3 Pro. DPT-3 Verity reads Latin-script documents only. See [Parsing Models](/dpt3/parse-models). ## Strong Support The following languages typically yield consistent and accurate results: * English * Chinese (Simplified and Traditional) * Dutch * French * German * Italian * Japanese (All scripts) * Korean * Portuguese * Russian * Spanish ## Moderate Support Support for the following languages varies based on font and clarity: * Arabic * Czech * Danish * Finnish * Greek * Hebrew * Hindi * Indonesian * Norwegian * Polish * Swedish * Thai * Turkish * Vietnamese ## Basic Support Agentic Document Extraction may struggle with the complex scripts of the following languages: * Amharic * Bengali * Gujarati * Malayalam * Tamil * Telugu * Urdu * Other non-Latin or stylized scripts # Supported File Types Source: https://docs.landing.ai/dpt3/file-types See which file types Parse accepts: PDFs, images, and Office text documents and presentations. The Parse API can parse the file types listed in the table below. Support depends on the method you use: the [Playground](https://ade.landing.ai/my/playground/ade) or the [API](https://docs.landing.ai/api-reference/parse/ade-parse). ## Supported Formats
File Type Playground API
PDF
PDF ✓ ✓
Images
JPEG ✓ ✓
JPG ✓ ✓
PNG ✓ ✓
GIF × ✓
BMP × ✓
TIFF × ✓
TIF × ✓
WEBP ✓ ✓
Text Documents
(see notes [here](#file-conversion-for-text-documents-and-presentations))
DOCX (Word) ✓ ✓
ODT (OpenDocument Text) ✓ ✓
RTF (Rich Text Format) × ✓
Presentations
(see notes [here](#file-conversion-for-text-documents-and-presentations))
PPTX (PowerPoint) ✓ ✓
## How Files Are Handled * **PDFs** are processed one page at a time, so each page is parsed independently. * **Images** are treated as a single page. * **Text documents and presentations** are converted to PDF before parsing, then processed one page at a time. ## File Conversion for Text Documents and Presentations Parse converts text documents and presentations to PDFs before parsing them. This conversion may change the document layout and increase or decrease the number of pages. For example, unsupported fonts may be replaced with larger alternatives, causing text to wrap differently or overflow onto additional pages. While the conversion process may impact the layout, Parse still parses content correctly. Page-based limits and credits apply to the converted PDF's page count. ## File Size and Page Limits For size and page limits, see [Rate Limits](./rate-limits). # European Union (EU) Source: https://docs.landing.ai/dpt3/eu Use the EU-hosted ADE for data residency, GDPR compliance, and lower latency for European users. Agentic Document Extraction is available in the European Union (EU) here: [https://ade.eu-west-1.landing.ai/](https://ade.eu-west-1.landing.ai/). Agentic Document Extraction in the EU provides: * **Data residency**: All data is stored and processed within the EU * **GDPR compliance**: The EU-hosted version of Agentic Document Extraction is compliant with the General Data Protection Regulation (GDPR) * **Regional performance**: Reduced latency for European users ## GDPR and Compliance Refer to the resources below to learn more about GDPR and compliance. Enterprise plans support SSO via SAML 2.0 and OpenID Connect (OIDC), allowing your organization to manage access through your existing identity provider (IdP). The Trust Center is your central resource for accessing our security documentation, compliance reports, and real-time system status. This page outlines our security posture, compliance with industry standards, and the measures we take to safeguard your data across our products and infrastructure. ## EU Pricing For EU subscription plans and pricing, go to [Plans & Billing](/ade/ade-pricing). Pricing is the same in the US and EU regions. ## Differences When Using the EU Using Agentic Document Extraction in the EU works the same as the default US deployment, with only a few key differences outlined in this article: * [Create an account](#create-an-account-in-the-eu): Use the EU URL * [Get your API key](#get-your-api-key-for-the-eu): Use the EU URL * [Call the API directly](#call-the-api-directly-in-the-eu): Use the EU endpoint ### Create an Account in the EU Create an account and access the Playground in the EU here: [https://ade.eu-west-1.landing.ai/home](https://ade.eu-west-1.landing.ai/home). ### Get Your API Key for the EU To get your API key for the EU, go to [https://ade.eu-west-1.landing.ai/settings/api-key](https://ade.eu-west-1.landing.ai/settings/api-key). Use this API key when calling the API directly in the EU. API keys are deployment-specific. An API key created in the US will not work for the EU, and vice versa. ### Call the API Directly in the EU To ensure your API calls are processed in the EU, replace the default base URL with the EU base URL: **US:** `https://api.ade.landing.ai`\ **EU:** `https://api.ade.eu-west-1.landing.ai` For example: * US: `https://api.ade.landing.ai/v2/parse` * EU: `https://api.ade.eu-west-1.landing.ai/v2/parse` # Support Source: https://docs.landing.ai/ade/ade-support Find support channels and resources for getting help with ADE. ## Support Resources In addition to the documentation in this site, use the following resources to learn more about Agentic Document Extraction. Share your scripts, ask questions, and get feedback from other programmers in our developer-focused Discord server. Explore end-to-end examples for common document processing workflows. Watch demos and video tutorials from our Machine Learning Experts. Plus, get the latest feature announcements from Dr. Andrew Ng! Join the LandingAI community to connect with other users and get the latest updates. ## Submit a Support Ticket If you experience an issue with Agentic Document Extraction, send an email to [support@landing.ai](mailto:support@landing.ai). To help us troubleshoot your issue, include this information in your email: * The email address for your Agentic Document Extraction account, found in your [profile page](https://ade.landing.ai/settings/personal/profile) * The document you were processing when the issue occurred * The processing method you were using when the issue occurred: * **API call**: Include your script or command. * **Library**: Include your script and the library version. * **Playground**: Include the link to the results. To get this, click the **Share Results** icon in the top right corner of the page and enable sharing. Share Results ## Delete Account To delete your Agentic Document Extraction account, send an email with your request to [support@landing.ai](mailto:support@landing.ai). Use the email address you used to sign up for Agentic Document Extraction. # Security and Privacy Source: https://docs.landing.ai/dpt3/ade-security Review ADE security practices, zero data retention, and compliance certifications (GDPR, SOC 2, HIPAA). LandingAI is committed to protecting your data and maintaining the highest security standards for Agentic Document Extraction. Refer to the resources below to learn about our security practices, zero data retention (ZDR) option, compliance certifications (GDPR, SOC 2 Type II, HIPAA), and more. Enterprise plans support SSO via SAML 2.0 and OpenID Connect (OIDC), allowing your organization to manage access through your existing identity provider (IdP). Enterprise plans can restrict an organization's API access to approved IP addresses and CIDR ranges. The Trust Center is your central resource for accessing our security documentation, compliance reports, and real-time system status. This page outlines our security posture, compliance with industry standards, and the measures we take to safeguard your data across our products and infrastructure. # Zero Data Retention (ZDR) Option Overview Source: https://docs.landing.ai/ade/zdr Enable the Zero Data Retention (ZDR) option so your data is used only to process your requests and deliver results. For customers with strict data privacy and compliance requirements, LandingAI offers the **Zero Data Retention (ZDR) option for our Agentic Document Extraction (ADE) product.** This document provides an overview of what the ZDR option means, its availability, and how to enable it for your organization. ## What Is the Zero Data Retention (ZDR) Option? When the ZDR option is enabled for your account, LandingAI retains your data only long enough to process your request and deliver the result. This means: * Your data is used exclusively to perform the operation you request, such as parsing or extracting a document. * Your documents and all intermediate processing data are deleted when the operation finishes. * Results are deleted when you receive them. See [Result Retention](#result-retention). * LandingAI does not use your data for training or improving our models when ZDR is active. ## What Versions of Agentic Document Extraction Support ZDR? ZDR is available for the following versions of Agentic Document Extraction: * [LandingAI-Hosted ADE](#how-zdr-works-in-the-landingai-hosted-version-of-ade) * [ADE Containerized App in Your VPC](#how-zdr-works-in-an-ade-containerized-app-in-your-vpc) ## How ZDR Works in the LandingAI-Hosted Version of ADE The LandingAI-hosted version of ADE is available in both the [US](https://ade.landing.ai/) and [EU](https://ade.eu-west-1.landing.ai/). Users on the Team and Enterprise plans can enable ZDR directly in the user interface. | Location | Region | | -------- | ------------------------------ | | US | AWS Ohio
(us-east-2) | | EU | AWS Ireland
(eu-west-1) | ### Scope When ZDR is enabled, our fully managed SaaS offering ensures zero data retention across the entire platform, including all subprocessors. When ZDR is enabled, ZDR is applicable when parsing documents with our Python libraries and when calling the ADE APIs directly. The [Ground API](/dpt3/ground) is the exception: it is not available while ZDR is enabled, and requests to it return a 501 error. A separate setting controls whether ZDR is applied to the [Playground](https://ade.landing.ai/). ### Result Retention Results are kept only until you receive them. Specific retention functionality depends on what generation of the API you're using: * [Gen2 APIs](#gen2-apis) * [Gen1 APIs](#gen1-apis) #### Gen2 APIs Every result from the [Gen2 APIs](/dpt3/overview) is deleted as soon as you receive it, no matter how you call the API. A result can be retrieved once. If you need it again, rerun the request. | How you call the API | What happens to the result | | ------------------------------------------------------------------------------------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Synchronous [Parse](/dpt3/parse) and [Extract](/dpt3/extract) requests | Returned in the response. Nothing is retained after the response is sent. | | [Parse Jobs](/dpt3/parse-async) and [Extract Jobs](/dpt3/extract-async) | Deleted as soon as you fetch it. For a job, the first poll that returns the completed result is the fetch. A result you never fetch is deleted automatically, no less than 24 hours and no longer than 48 hours after the job completes. | | [Parse Jobs](/dpt3/parse-async) and [Extract Jobs](/dpt3/extract-async) created with `output_save_url` | Delivered to your storage, then deleted immediately. | #### Gen1 APIs The [Gen1 APIs](./ade-overview) never hold a result for later pickup: | How you call the API | What happens to the result | | ----------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Synchronous [Parse](./parse) and [Extract](./ade-extract) requests | Returned in the response. Nothing is retained after the response is sent. | | [Parse Jobs](./ade-parse-async) and [Extract Jobs](./ade-extract-async) | Delivered to your storage and never retained. ZDR requires the URL input parameter and the `output_save_url` parameter on every job. See the ZDR Requirements for [Parse Jobs](./ade-parse-async#zdr-requirements) and [Extract Jobs](./ade-extract-async#zdr-requirements). | ### Enable ZDR Users on the Team and Enterprise plans can enable ZDR in the user interface by following the instructions below: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Organization Settings**). 3. In the Zero Data Retention box, click **Turn It On**. 4. A pop-up opens. Carefully read the information so that you understand how ZDR works. 5. If you want ZDR to also be applied when uploading documents to the [Playground](https://ade.landing.ai/), select the **Also apply to Playground UI** checkbox. 6. Click **Enable Zero Data Retention**. 7. The Zero Data Retention box confirms that ZDR is enabled. 8. If you need to ensure HIPAA compliance, you must have a Business Associate Agreement (BAA) in place with LandingAI. To initiate the BAA process, submit your request through the form on the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (available after ZDR is enabled). US users can also enable ZDR when upgrading to a Team plan. ### Turn Off ZDR If you have enabled ZDR and later want to turn it off, contact [support@landing.ai](mailto:support@landing.ai). ## How ZDR Works in an ADE Containerized App in Your VPC ADE can be deployed within your own Virtual Private Cloud (e.g., AWS, Azure, GCP). In this deployment, ADE maintains zero data retention because it is on your VPC. In a VPC deployment, LandingAI is not responsible for zero data retention related to your infrastructure or any subprocessors you integrate (e.g., your own LLM API keys). Your organization is responsible for managing these. ## Using ZDR for Protected Health Information (PHI), Personally Identifiable Information (PII) & HIPAA Compliance The ZDR option provides the necessary technical safeguards to support customers processing Protected Health Information (PHI) and Personally Identifiable Information (PII) in compliance with HIPAA. If you are a covered entity and intend to process PHI or PII with our ADE service, you must: 1. Enable the Zero Data Retention (ZDR) option. 2. Have a signed Business Associate Agreement (BAA) in place with LandingAI. To initiate the BAA process, submit your request through the form on the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (available after ZDR is enabled). To learn more about HIPAA compliance, see these resources: * [Security and Data Privacy](https://landing.ai/security-at-landingai) * [Trust Center](https://trust.landing.ai/) # IP Address Allowlist Source: https://docs.landing.ai/ade/ip-allowlist Restrict your organization's API access to approved IP addresses and CIDR ranges. Available on the Enterprise plan. An IP address allowlist restricts your organization's access to the Agentic Document Extraction (ADE) APIs to a set of approved IP addresses. When an allowlist is active, API requests from any other address are rejected. Use an allowlist to ensure your organization's API keys work only from networks you control, such as your corporate network or your production servers. The IP address allowlist is available on the Enterprise plan. ## Set Up an Allowlist To enable an IP allowlist for your organization, email your request with the approved IP addresses to [support@landing.ai](mailto:support@landing.ai). To later change the IP addresses on the allowlist or disable allowlisting, email [support@landing.ai](mailto:support@landing.ai). ## Which IP Addresses Should Be on the Allowlist? Include the public addresses your API traffic leaves your network from. If your requests go through a NAT gateway, VPN, or proxy, that device's public address is the one ADE sees, not the local address of the machine sending the request. An allowlist can contain: * Single IPv4 or IPv6 addresses (for example, `203.0.113.7`) * CIDR ranges (for example, `203.0.113.0/24` or `2001:db8::/32`) ## What the Allowlist Covers The allowlist applies to every request to the ADE APIs, both v1 and v2, no matter which of your organization's API keys the request uses. The allowlist does not restrict the [Playground](https://ade.landing.ai/). When you use the Playground, its API requests are sent by LandingAI's servers on your behalf, so those requests never come from your organization's network. Members of your organization can sign in and use the Playground from any network. ## Blocked Requests An API request from an address that is not on your organization's allowlist is rejected with an HTTP 403 response. The response body carries the error code `forbidden` and this message: ```text theme={null} Your organization restricts API access to approved IP addresses. This request originated from an address that is not approved. ``` # Organizations & Members Source: https://docs.landing.ai/ade/ade-members Manage your organization, invite members, and assign roles in ADE. Enterprise plans support single sign-on (SSO) via SAML 2.0 and OpenID Connect (OIDC). For more information, see [Single Sign-On (SSO)](./ade-sso). ## Organizations An **organization** is the container for your Agentic Document Extraction account. It holds your credits, members, API keys, files, and settings. When you create an account, an organization is automatically created on the Explore plan. If you later upgrade to a Team plan, you keep the same organization. You can be invited to join multiple organizations. **If you upgraded to a subscription plan before April 2, 2026:** Before this date, a separate organization was created when you upgraded. You still have a Personal account in addition to your subscription organization. This ensures that files and data in your Personal organization are not shared with members of your subscription organization. ### Switch to a Different Organization To switch to a different organization: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Click your profile icon at the bottom left corner of the page. 3. Click the name of the organization you're currently in. 4. Select the organization you want to open. ### Change the Organization Name Members with the Admin role can change the organization name. To change the organization name: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Organization Settings**). 3. Enter the new name in the **Organization name** field. 4. Click **Save**. ### Organization ID Each organization has an Organization ID, which is a unique identifier. You do not need to include the Organization ID when sending API calls. When contacting support, you might be asked to share your Organization ID. To locate the Organization ID: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Organization Settings**). 3. The **Organization ID** displays. 4. Click the **Copy** icon to copy the ID. ## Members and Roles The Explore plan supports one user. To add members to your organization, upgrade to a Team or Enterprise plan. Users in an organization are called **members**. Team and Enterprise plans support unlimited members. For more information about plan features, go to [Plans & Billing](./ade-pricing). Members are managed on the [Members](https://ade.landing.ai/settings/organization/members) page. ### Member Roles An organization includes the following member roles: **Developer** and **Admin**. The following table defines what actions each role can perform:
Action Developer Admin
Process documents ✓ ✓
Create API keys ✓ ✓
Revoke your own API keys ✓ ✓
Revoke API keys other members created ✖ ✓
Invite members ✖ ✓
Remove members ✖ ✓
Change member roles ✖ ✓
Manage billing ✖ ✓
Update organization name ✖ ✓
### Invite Members Members with the Admin role can invite other members to the organization. Invitations to members expire in 2 days. If an invitation has expired, you can invite the user again. If your organization has SSO enabled, inviting users may not be required. For more information, go to [Single Sign-On (SSO)](./ade-sso#user-access-and-jit-provisioning). To invite a member: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Members](https://ade.landing.ai/settings/organization/members) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Members**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click **Invite**. 5. Enter the email addresses of the users you want to invite. Separate email addresses with a comma. 6. Select the [role](#member-roles) you want to assign to the users. 7. Click **Invite**. An invitation to join the organization is emailed to the users. Invited users can then join your organization by following the [Complete Your Registration](#complete-your-registration) process. ### Complete Your Registration After you’ve been invited to an organization, you will receive an automated email prompting you to complete your registration. Your account will be linked to the email address the email was sent to. If you want your account to be linked to a different email address, ask the user who invited you to send a new invitation to that address. To complete your registration: 1. Open the automated email. 2. Click the button that prompts you to accept the invitation. A new window or tab opens. 3. Follow the on-screen prompts to either create a new account or log in with an existing account. 4. After logging in, your registration is complete and you can start using Agentic Document Extraction. ### Remove Members Members with the Admin role can remove other members from the organization. If you remove a member, any API keys that user created will remain active and can be managed by Admins. To remove members: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Members](https://ade.landing.ai/settings/organization/members) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Members**). 3. Locate the row for the member. (You may need to search for the member to narrow down the list of members.) 4. Click the **Settings** button (ellipses) and select **Remove from \[organization]**. Follow the on-screen prompts to complete the process. ### Revoke Invitations Members with the Admin role can revoke invitations that are Pending. To revoke an invitation: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Members](https://ade.landing.ai/settings/organization/members) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Members**). 3. Locate the row for the member. (You may need to search for the member to narrow down the list of members.) 4. Click the **Settings** button (ellipses) and select **Revoke invitation**. The user will no longer be able to create an account for your organization. If you revoked the invitation by mistake, you can invite the user again. ### Change Member Roles Members with the Admin role can change the role of other members. To change a member's role: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Members](https://ade.landing.ai/settings/organization/members) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Members**). 3. Locate the row for the member. (You may need to search for the member to narrow down the list of members.) 4. Select the role you want to assign to the member. Follow the on-screen prompts to complete the process. # Single Sign-On (SSO) Source: https://docs.landing.ai/ade/ade-sso Set up SSO via SAML 2.0 or OpenID Connect to manage ADE access through your identity provider. ## About SSO Agentic Document Extraction supports SSO via **SAML 2.0** and **OpenID Connect (OIDC)**, letting your organization manage Agentic Document Extraction access through your existing identity provider (IdP). Common IdPs include Okta, Microsoft Entra ID (formerly Azure AD), OneLogin, Ping Identity, and Google Workspace. Users can also sign in with Google or GitHub without any additional setup. This page covers SSO setup via SAML 2.0 and OIDC only. ## Availability SSO via SAML 2.0 and OIDC is available on the **Enterprise** plan. ## What to Know Before Enabling SSO ### SSO Replaces Existing Login Methods Once SSO is enabled for your organization, it becomes the only way users can log in to Agentic Document Extraction. Users will no longer be able to sign in with a password, Google, or GitHub. This is by design; it ensures that all user access is managed through your IdP, so your organization's security policies are consistently enforced. To avoid disruption, communicate this change to all Agentic Document Extraction users in your organization before enabling SSO. ### User Access and JIT Provisioning Your IT department controls who can access Agentic Document Extraction through your IdP by managing user groups. Having a company email address does not automatically grant access. Users must be included in the group configured for Agentic Document Extraction in your IdP. When setting up SSO, let the LandingAI team know which option you prefer for adding users to your Agentic Document Extraction organization: * **By invitation**: Only users who have been invited to your Agentic Document Extraction organization can log in, even after SSO is enabled. For information about manually inviting users, see [Organizations & Members](./ade-members). * **Just-in-Time (JIT) provisioning**: Any user in your IdP's user group who successfully authenticates via SSO is automatically added to your Agentic Document Extraction organization the first time they log in, with no invitation required. ## Enable SSO SSO setup involves multiple steps and ongoing coordination between your team and the LandingAI team. Here is an overview of the process: 1. [Request SSO](#request-sso) through your Organization Settings. 2. The LandingAI team reaches out to begin the process. 3. Share the required information with the LandingAI team: [SAML 2.0](#required-information-for-saml-20) or [OIDC](#required-information-for-oidc). 4. The LandingAI team enters your information in the Agentic Document Extraction backend. 5. The LandingAI team shares configuration details with you. [Add these to your IdP](#complete-setup-in-your-idp). 6. [Test that SSO is working correctly](#test-that-sso-is-working-correctly). ### Request SSO To request SSO: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Organization Settings**). 3. In the **Single Sign-On (SSO)** box, click **Contact Support**. This sends an automated message to the LandingAI team. The team will contact you about next steps for setting up SSO. ### Required Information for SAML 2.0 Share the following information with the LandingAI team. Most of it can be found in your IdP's SAML configuration page. The examples below are for Microsoft Entra ID. Formats and field names vary by IdP. | Item | Description | | --------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | IdP (Identity Provider) | The service provider your organization uses to manage email and SSO.

**Example**: Okta, Microsoft Entra ID, etc. | | JIT provisioning preference | Whether you want to enable Just-in-Time (JIT) provisioning for your organization. See [User Access and JIT Provisioning](#user-access-and-jit-provisioning). | | Metadata URL | The URL that provides your IdP's SAML metadata, including the Entity ID, SSO login URL, and signing certificate. This URL allows LandingAI to automatically configure the SAML connection without requiring each value separately.

In Microsoft Entra ID, this is called **App Federation Metadata URL**. In Okta, this is called **Identity Provider Metadata**.

**Example**: `https://login.microsoftonline.com/123/federationmetadata/2007-06/federationmetadata.xml?appid=456` | | Enterprise email domains | Each email domain that will need access to Agentic Document Extraction.

**Example**: acme.com, acme.ai | | Email claim | The Uniform Resource Identifier (URI) for the email claim type. This communicates the email address of the user.

**Example**: `http://schemas.xmlsoap.org/ws/2005/05/identity/claims/emailaddress` | | Name claim | Optional. The Uniform Resource Identifier (URI) for the name claim type. This communicates the name of the user.

**Example**: `http://schemas.xmlsoap.org/ws/2005/05/identity/claims/name` | ### Required Information for OIDC Share the following information with the LandingAI team. Most of it can be found in your IdP's OIDC configuration page. The examples below are for Microsoft Entra ID. Formats and field names vary by IdP. | Item | Description | | --------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | IdP (Identity Provider) | The service provider your organization uses to manage email and SSO.

**Example**: Okta, Microsoft Entra ID, etc. | | JIT provisioning preference | Whether you want to enable Just-in-Time (JIT) provisioning for your organization. See [User Access and JIT Provisioning](#user-access-and-jit-provisioning). | | Client ID | A unique identifier for the Agentic Document Extraction application registered in your IdP. Your IdP generates this when you create the application. | | Client Secret | A secret key used to authenticate the Agentic Document Extraction application with your IdP. Share this with the LandingAI team through a secure channel. | | Issuer URL | The base URL of your IdP's OIDC configuration, used to locate the OIDC metadata endpoint.

**Example**: `https://login.microsoftonline.com/{tenant-id}/v2.0` | | Scope | The permissions requested from your IdP. At minimum: `openid`, `profile`, `email`. | | Enterprise email domains | Each email domain that will need access to Agentic Document Extraction.

**Example**: acme.com, acme.ai | ### Complete Setup in Your IdP After the LandingAI team enters your information in the Agentic Document Extraction backend, they will continue coordinating with you to complete the setup. The LandingAI team will give you the following information to enter in your IdP configuration page: | Protocol | Item | Description | | -------- | ------------------------------ | ---------------------------------------------------------------------------------------------------------------------- | | SAML 2.0 | Assertion Consumer Service URL | In Microsoft Entra ID, this is called a "Reply URL".

**Example**: `https://login.landing.ai/api/authn/...` | | SAML 2.0 | Audience URI | Also called an "SP Entity ID".

**Example**: `https://login.landing.ai/api/enterprise-sso/...` | | OIDC | Redirect URI (Callback URL) | **Example**: `https://login.landing.ai/callback/1234` | ### Test That SSO Is Working Correctly After adding the information from the LandingAI team, test that SSO is working correctly: 1. Go to [https://login.landing.ai/sign-in](https://login.landing.ai/sign-in). 2. If you are currently logged in, log out. 3. Click **Continue with Enterprise SSO** and follow the on-screen prompts to log in. If you're unable to log in, send an email to [support@landing.ai](mailto:support@landing.ai). ## View Your SSO Settings After SSO has successfully been configured, you can view your SSO settings in read-only mode in Agentic Document Extraction: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [Organization Settings](https://ade.landing.ai/settings/organization/general) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Organization Settings**). 3. In the **Single Sign-On (SSO)** box, click **View Details**. The SSO settings display. # Plans & Billing Source: https://docs.landing.ai/ade/ade-pricing Understand ADE plan pricing, how costs are calculated, and how to manage overages and plan changes. This page covers what the Agentic Document Extraction plans cost and how billing works. To see how many credits each API call consumes, go to [Credit Consumption for ADE Gen2](/dpt3/credit-consumption) or [Credit Consumption for ADE Gen1](/ade/ade-credit-consumption). To see what your organization has already consumed, go to [Monitor Credit Usage](./monitor-usage). ## Pricing Agentic Document Extraction uses credit-based pricing. On the Explore and Team plans, a credit costs \$0.01 (\$1 buys 100 credits). Enterprise plans have custom pricing; for details, [contact us](mailto:support@landing.ai). All users start on our pay-as-you-go **Explore** plan with free credits. After that, you can stay on the Explore plan and buy credits as needed, or upgrade to a **Team** or **Enterprise** plan. See the full plan details and upgrade in the [app](https://ade.landing.ai/plan). For EU users: The pricing is the same for both US and EU regions. EU users can see plan details and upgrade in the [EU app](https://ade.eu-west-1.landing.ai/plan). We price in US dollars across all regions. Your payment will be processed in USD using current exchange rates. ## How Costs Are Calculated Every API call and Playground run consumes credits. The cost of a call is the credits it consumes multiplied by the credit price: * Credits consumed depend on the API and the amount of content processed. For per-API rates, see [Credit Consumption for ADE Gen2](/dpt3/credit-consumption) or [Credit Consumption for ADE Gen1](/ade/ade-credit-consumption). * Total cost = credits consumed × \$0.01. ## Plans
Explore Team Enterprise
Cost Pay-as-you-go
Start with 1000 free credits
Credit packs start at \$250/mo Contact us
Core Capabilities
Parsing
[view supported file formats](./ade-file-types)
✓ ✓ ✓
Intelligent Layout ✓ ✓ ✓
Structured Field Extraction ✓ ✓ ✓
List Extraction ✓ ✓ ✓
Table Extraction ✓ ✓ ✓
Figure Summaries ✓ ✓ ✓
Visual Grounding ✓ ✓ ✓
Document Splitting ✓ ✓ ✓
Multilingual Documents ✓ ✓ ✓
Custom Processing Pipeline ✓
Organization Management & Support
Users 1 Unlimited users Unlimited users
Support Level Community Enhanced Dedicated
Security & Deployment
Rate Limits
[see more details](./ade-rate-limits)
Base Enhanced Custom
Zero Data Retention (ZDR) ✓ ✓
HIPAA (BAA) (inc. ZDR) ✓ ✓
VPC and On-Prem Deployments ✓
SLA & Uptime Guarantees ✓
Single Sign-On (SSO)
[see more details](./ade-sso)
✓
## Overages **Explore Plan** If you're on the **Explore** plan, you can only use the credits you have purchased. If you run out of credits, you can purchase additional credits to continue using Agentic Document Extraction. **Team Plan (Subscription)** If you're on a **Team** plan (a subscription plan), you have a pool of extra credits to draw from if you exceed your allocation for a billing cycle. This pool can include: * **Transferred credits**: Credits from a previous plan that carried over when you upgraded (for example, unused Explore credits). * **Prepaid credits**: "Pay-As-You-Go" credits purchased in advance. Prepaid credits cost \$0.01 per credit and expire 1 year from the purchase date. Credits that expire soonest are consumed first. For example, if you have 500 transferred Explore credits expiring in 2 months and 1,000 prepaid credits expiring in 10 months, the transferred credits are consumed first. To top up your balance automatically instead of buying credits manually, use [Auto Recharge](./auto-recharge). ## Upgrade Team Plans You can upgrade your Team plan from one tier to another. For example, you can upgrade from the tier that includes 55K credits per month to the tier that includes 110K credits per month. If you upgrade your Team plan, the changes take effect immediately. ### What to Expect When You Upgrade **Your current billing cycle ends:** * Your current billing cycle ends on the upgrade date. **Your new billing cycle starts:** * A new billing cycle starts on the upgrade date. * You are charged for the new plan. * Your unused credits from the previous plan are transferred to the allocation for the new billing cycle and expire at the end of that cycle. These transferred credits can be transferred again if you upgrade before they expire. ### How to Upgrade Your Plan 1. Log in to [https://ade.landing.ai/home](https://ade.landing.ai/home). 2. Go to the **Plan & Billing** page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Plan & Billing**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click the **Plan** tab. 5. Click **Manage** > **Change Plan**. 6. Select the plan you want and follow the on-screen prompts. ## Downgrade Team Plans You can downgrade your Team plan from one tier to another. If you downgrade your Team, the changes take effect at the end of the current billing cycle. If you have unused credits when you downgrade, those credits do not transfer to your new plan. You have until the end of your current billing cycle to use the remaining credits. ### How to Downgrade Your Plan 1. Log in to [https://ade.landing.ai/home](https://ade.landing.ai/home). 2. Go to the **Plan & Billing** page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Plan & Billing**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click the **Plan** tab. 5. Click **Manage** > **Change Plan**. 6. Select the plan you want and follow the on-screen prompts. ## Credit Expiration
Credit Type Expiration
Free credits included in the Explore plan Expire 90 days after you create your account
"Pay-As-You-Go" Credits Purchased (includes credits purchased via Auto Recharge) Expire 1 year from the purchase date
Credits allocated as part of a subscription or Enterprise plan Credits are allocated at the start of each billing cycle (for subscription plans) or subscription term (for Enterprise plans). Unused credits expire at the end of that period.
## FAQs Credits are usage units that get consumed each time you process a document. Every document processing task—like parsing or field extraction—uses credits. A credit costs 1¢: \$1 buys 100 credits on the Explore and Team plans, in both the US and EU regions. Enterprise plans have custom pricing; contact us. Yes. When you sign up, you’re automatically on the **Explore** plan, which includes 1000 free credits. These credits are perfect for exploring the ADE document processing capabilities, building prototypes, and testing how ADE integrates with your workflow. Each ADE plan is designed to meet the volume and feature needs of a different use case. If you’re a solo developer, the **Explore** plan might be best fit for you. But if you’re processing a high number of documents each month and need zero data retention, then the **Team** plan might be better suited for you. If you start on the **Explore** plan and upgrade to another plan, unused **Explore** credits are transferred to your account and are consumed if you go over the allocated credits for your billing cycle. No, you do not need to put down a credit card to get started with ADE! When you sign up, you’re automatically on the **Explore** plan, which includes free credits and doesn’t require upfront payment. You are billed based on the number of credits consumed by your API requests, regardless of how you interact with ADE. Whether you call the API directly, use one of our libraries, or test in the Playground, all requests count toward your credit usage. Yes. Whenever an API operation results in partial credits, the cost is rounded up to the nearest tenth decimal place. For example, if a calculation results in 1.67 credits, the cost is rounded up to 1.7 credits. If you were on the original “pay-as-you-go plan” and added funds before the credit-based system was implemented, your funds have been converted to credits. The conversion is \$0.01 to 1 credit, which ensures that you retain your original pricing of parsing costing \$0.03 per page. If you were on an enterprise plan before the credit-based system was implemented, there are no changes to your plan. Credits are consumed based on the number of pages processed. When processing PDFs, a page (regardless of dimensions) is simply a page in the PDF. When processing images, each image counts as a page. All billing is securely processed through Stripe. For **Team** plans, you'll be charged at the beginning of each billing cycle and immediately receive your credits for that period. This can happen when you pay with [Stripe Link](https://docs.stripe.com/payments/link), Stripe's digital wallet. Link charges your primary card, which may differ from a card you typed at checkout, and it may charge a backup card if your primary card is declined. To guarantee a specific card is used, enter that card directly at checkout instead of using Link. Yes, you can resubscribe to a Team plan when your organization is in "read-only" mode. To resubscribe, click the **Re-subscribe** button that displays at the top of the page. Or, resubscribe on the **Plan & Billing** page: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the **Plan & Billing** page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Plan & Billing**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click the **Re-subscribe** button and follow the on-screen prompts. Yes, you can cancel your subscription to a Team plan. If you cancel your subscription, the cancellation takes effect at the end of the current billing cycle. Once the cancellation is in effect, the organization is in "read-only" mode. To cancel a subscription: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the **Plan & Billing** page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Plan & Billing**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Go to **Manage** > **Cancel Subscription** and follow the on-screen prompts. If you are on a Team plan, you can update your billing information, including your credit card and billing address, directly in the user interface. To do this: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the **Plan & Billing** page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Plan & Billing**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click the **Billing** tab. 5. To update your credit card information, click **Update Card**. Update your information in the pop-up window and click **Save card**. Update Card 6. To update your billing address, click **Manage**. This opens your billing information in Stripe. Manage Billing 7. Click **Update Information**. Update your billing information and click **Save**. Update Billing Information If you are on an Enterprise plan and need to update your payment information or billing address, contact [support@landing.ai](mailto:support@landing.ai). No. LandingAI does not collect or remit sales tax, VAT, or GST on invoices for Agentic Document Extraction. Our invoices are issued by a U.S. entity. If your local laws require tax on digital services, you are responsible for assessing, reporting, and paying any such taxes to your local authority (including reverse-charge where applicable). If you have questions about your obligations, please consult your tax advisor or local tax authority. Not at this time. We do not display customer tax IDs on invoices. LandingAI is not currently registered to collect VAT/GST. Prices are quoted exclusive of taxes, and customers remain responsible for any taxes due locally (e.g., under reverse-charge rules). No. For compliance and audit integrity, issued invoices cannot be modified or reissued. Please make sure your billing profile is correct before your next invoice is created. Pricing plans change over time. This page documents only currently available plans. If you are on a plan that is no longer offered, you remain on your current plan. For questions, contact [support@landing.ai](mailto:support@landing.ai). # Credit Consumption Source: https://docs.landing.ai/dpt3/credit-consumption See credit rates per model family and service tier for the Parse and Extract APIs, and how to verify charges from the response. The [Parse](./parse) and [Extract](./extract) APIs use complexity-aware pricing: credit consumption scales with how much content a request processes, so simpler documents consume fewer credits and denser documents consume more. Rates depend on the [service tier](./sync-async): the `standard` tier consumes half the credits of the `priority` tier. All credit totals are rounded up to the nearest 0.1 credit. For plan and billing details and pricing for other ADE tools, see [Plans & Billing](../ade/ade-pricing). ## Parse Synchronous [Parse](./parse) requests run on the `priority` tier. Asynchronous [Parse Jobs](./parse-async) requests run on either the `priority` or `standard` tier. Rates depend on the [parsing model family](./parse-models) and [service tier](./sync-async). Each page's credit consumption is the sum of two components: a per-page rate and an output-character rate. ### DPT-3 Pro [DPT-3 Pro](./parse-models) is the default, highest-quality parsing model. A typical business document parsed with DPT-3 Pro uses a median of 1.5 credits on the `standard` tier. | Component | Priority (sync and jobs) | Standard (jobs only) | | :---------------- | :-------------------------------------- | :--------------------------------------- | | Page | 1 credit per page | 0.5 credits per page | | Output characters | 0.5 credits per 1,000 output characters | 0.25 credits per 1,000 output characters | ### DPT-3 Verity [DPT-3 Verity](./parse-models) is the lower-latency preview model for digitally created text documents. | Component | Priority (sync and jobs) | Standard (jobs only) | | :---------------- | :-------------------------------------- | :-------------------------------------- | | Page | 0.3 credits per page | 0.15 credits per page | | Output characters | 0.2 credits per 1,000 output characters | 0.1 credits per 1,000 output characters | ### How Output Characters Are Counted for Parse Output characters are all characters (Unicode code points) in the returned `markdown` field, including the page-break and document-ID markers. ### Verify Parse Credit Consumption The response's `metadata` shows the credits consumed and every number used to calculate the total. For example, a 12-page synchronous DPT-3 Pro parse could report: ```json theme={null} "metadata": { "page_count": 12, // 12 pages × 1 credit = 12 credits "output_markdown_chars": 48120, // 48,120 / 1,000 × 0.5 = 24.06 credits "billing": { "service_tier": "priority", // the rate column that applied "total_credits": 36.1 // 12 + 24.06 = 36.06, rounded up to 36.1 } } ``` For the full field reference, see [Parse API Response](./parse-response#metadata). ## Extract Synchronous [Extract](./extract) requests run on the `priority` tier. Asynchronous [Extract Jobs](./extract-async) requests run on either the `priority` or `standard` tier. A typical business document uses a median of 1.5 credits on the `standard` tier. A request's credit consumption is the sum of the two components below. | Component | Priority (sync and jobs) | Standard (jobs only) | | :---------------- | :---------------------------- | :---------------------------- | | Input characters | 1 credit per 2,500 characters | 1 credit per 5,000 characters | | Output characters | 1 credit per 500 characters | 1 credit per 1,000 characters | ### How Input and Output Characters Are Counted for Extract Input characters are the characters (Unicode code points) in the Markdown you send. Output characters are the characters (Unicode code points) in the returned `extraction` field, serialized as compact JSON. Whitespace between values is not counted, and each non-ASCII character counts as one character, not as an escape sequence. ### Verify Extract Credit Consumption The response's `metadata` shows the credits consumed and every number used to calculate the total. For example, an extract job on the `standard` tier could report: ```json theme={null} "metadata": { "input_markdown_chars": 40000, // 40,000 / 5,000 = 8 credits at the standard rate "output_extraction_chars": 1842, // 1,842 / 1,000 = 1.842 credits at the standard rate "billing": { "service_tier": "standard", // the rate column that applied "total_credits": 9.9 // 8 + 1.842 = 9.842, rounded up to 9.9 } } ``` For the full field reference, see [Extract API Response](./extract-response#request-metadata-metadata). ## Ground [Ground](./ground) requests consume no credits. Each call is still recorded in your usage history, and the response's `metadata.billing` reports `"total_credits": 0.0`. ## Zero Data Retention Using [Zero Data Retention](../ade/zdr) (ZDR) with the Parse and Extract APIs does not consume any additional credits. # Monitor Credit Usage Source: https://docs.landing.ai/ade/monitor-usage See how many credits your organization has consumed, filter usage by type or API key, and trace individual jobs. Use the [Usage page](https://ade.landing.ai/settings/usage) to see how many credits your organization has consumed and why. To get an email when consumption crosses a threshold, set a [credit usage alert](./credit-alerts). The Usage page has two parts: * **Credit usage chart:** A bar chart of credit usage over time. Toggle between **Daily** and **Monthly** views. Filter by function type (Parse, Extract, etc.) and API key. Group by type, API key, or model. * **Detailed logs:** A searchable table of every job, showing how many credits each one used. Search by job ID and download the logs as a CSV. ## Detailed Log Columns Each row in the detailed logs includes these columns: | Column | Description | | :------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | Timestamp | When the job ran. | | Job ID | The unique identifier for the job. Use it to trace a specific request. | | API Key | The API key used, or **Playground** for requests made in the Playground. | | Endpoint | The API endpoint called (for example, `v2/parse` or `v1/ade/parse/jobs`). | | Model | The model used, such as DPT-2 or DPT-3 Pro. | | Mode | **Async** for the [Parse Jobs](./ade-parse-async) and [Extract Jobs](./ade-extract-async) APIs, which process requests asynchronously. **Sync** for all other APIs. | | Processed Unit | The units the charge is based on. Depending on the API, this is a number of pages, characters, or both. | | Credit Used | The credits the job consumed. Failed jobs show a **Failed** tag instead. | # Credit Usage Alerts Source: https://docs.landing.ai/ade/credit-alerts Set alerts that email your team when your organization's credit usage crosses a threshold. Use credit usage alerts to get an email when your organization's credit consumption crosses a threshold. Alerts help you catch unusual usage before it becomes an unexpected bill or an interrupted workload. Alert section of the Usage page, showing the three default credit alerts with their thresholds, recipients, and statuses ## Credit Alert Availability Credit usage alerts are available on the **Team** and **Enterprise** plans. Members with the **Developer** or **Admin** [role](./ade-members#member-roles) can view alerts on the [Usage page](https://ade.landing.ai/settings/usage). Only **Admins** can create, edit, and delete alerts. ## Credit Alert Workflow Alerts work like this: * Each alert has a threshold, a list of recipients, and an optional label. * Your organization's consumption for the current billing period is checked against each alert's threshold every hour. * When consumption crosses the threshold, the recipients receive an email. Each alert emails at most once per billing period, then starts watching again when the next period begins. ## Default Alerts By default, organizations on the **Team** and **Enterprise** plans have three alerts that are sent to members with the **Admin** role. Default alerts can be deleted. | Threshold | Label | | ------------- | -------------- | | 80% of quota | Usage warning | | 90% of quota | Critical usage | | 100% of quota | Quota reached | ## Create an Alert Members with the **Admin** role can create alerts. To create an alert: 1. Go to the [Usage page](https://ade.landing.ai/settings/usage) and scroll down to the **Alert** section. 2. Click **Create Alert**. 3. Enter the **Alert threshold**: a number and its [unit](#alert-threshold-units) (**Credits**, **USD**, or **% of quota**). 4. Add up to 20 **Recipients**. Recipients must be members of your organization. A recipient who later leaves the organization stops receiving emails. 5. To describe the alert, add an optional **Label** (for example, "Finance overage warning"). 6. Click **Create alert**. ## Edit or Delete an Alert Members with the **Admin** role can edit and delete alerts. To change or remove an alert, open it from the alert table on the Usage page, then update its values or click **Delete Alert**. ## Alert Threshold Units All three threshold units measure the same quantity: the credits your organization consumes in a billing period. The create dialog shows your subscription quota and the next reset date, and previews the equivalent credit value as you type. | Unit | Description | | ---------- | --------------------------------------------------------------- | | Credits | The threshold as a number of credits. | | USD | Converted to credits at the standard rate (\$1 = 100 credits). | | % of quota | A percentage of your subscription quota for the billing period. | ## Alert Status The alert table on the Usage page shows one of two statuses for each alert. Statuses reset automatically when a new billing period starts. | Status | Meaning | | --------- | ------------------------------------------------------------------------------------------------------------------------------------------ | | Watching | The alert has not fired during the current billing period. | | Triggered | The alert fired during the current billing period. Recipients received the email, and the alert does not fire again until the next period. | # Auto Recharge Source: https://docs.landing.ai/ade/auto-recharge Automatically buy credits when your balance falls below a threshold, so API calls don't fail when credits run out. Use Auto Recharge to automatically purchase credits when your balance falls below a set threshold. If your organization runs out of credits, API calls fail with a `402` (Payment Required) status until you add more; Auto Recharge keeps a working balance so that doesn't happen. Auto Recharge is available on the **Explore** and **Team** plans. It is enabled by default on **Team** plans and disabled by default on the **Explore** plan. To get an email about consumption instead of purchasing automatically, set a [credit usage alert](./credit-alerts). ## Set the Right Threshold Set your threshold high enough to cover your largest expected API call. If your threshold is too low, Auto Recharge may not trigger before your balance is exhausted, and the API call will return a `402` status (Payment Required). For example, if a typical job consumes 1,500 credits, set your threshold above 1,500 credits. ## Manage Auto Recharge 1. Log in to [https://ade.landing.ai](https://ade.landing.ai). 2. Go to the **Plan & Billing** page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **Plan & Billing**). 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click the **Plan** tab. 5. Click **Add Credits**. (If you're on the **Explore** plan, click **Buy Credits**.) 6. If Auto Recharge is not already enabled, turn on **Enable Auto Recharge**. 7. In the **When credit balance goes below** field, enter the threshold that will trigger Auto Recharge. For example, entering 5,000 means credits are purchased automatically when your balance reaches 5,000 or fewer. By default, this is 10% of the credits allocated for your billing cycle. 8. In the **Add to** field, enter the number of credits you want to purchase. By default, this is 100% of the credits allocated for your billing cycle. 9. Click **Next** and follow the on-screen prompts. # ADE Parse Source: https://docs.landing.ai/api-reference/parse/ade-parse Parse a document and return the parse response inline. ## OpenAPI ````yaml /dpt3/openapi-adev2.json post /v2/parse openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/parse: post: tags: - Parse summary: ADE Parse description: Parse a document and return the parse response inline. operationId: parse_run_sync requestBody: required: true content: multipart/form-data: schema: type: object properties: document: type: string format: binary description: >- The file to parse. The file must be a PDF or image; see the list of [supported file types](https://docs.landing.ai/dpt3/file-types). Provide either `document` or `document_url`, not both. document_url: type: string description: >- A publicly accessible URL to the file to parse. The file must be a PDF or image; see the list of [supported file types](https://docs.landing.ai/dpt3/file-types). Provide either `document` or `document_url`, not both. model: type: string description: >- The DPT-3 model snapshot to use for this request. Accepts a dated snapshot (for example, `dpt-3-pro-20260710`), a `-latest` alias, or a bare family name (equivalent to that family's `-latest`). Two families are available: `dpt-3-pro` for highest quality, and `dpt-3-verity` for lower-latency parsing without vision-model captioning. Defaults to the latest DPT-3 Pro snapshot. options: additionalProperties: false properties: pages: anyOf: - items: type: integer type: array - type: 'null' default: null title: Pages blocks: $ref: '#/components/schemas/BlocksOptions' atomic_grounding: default: true description: >- Include the fine-grained `atomic_grounding` array on leaf elements. Set `false` to omit the field entirely from every node. title: Atomic Grounding type: boolean inline_markdown: default: false description: >- Include each node's slice of the document `markdown` inline as a `markdown` field on every structure node: the document root, each page, and each element (including table cells). `atomic_grounding` entries do not carry it. title: Inline Markdown type: boolean password: anyOf: - type: string - type: 'null' default: null description: >- Password for encrypted PDFs. Not currently supported — providing a value returns a 422 error; decrypt the file before uploading. title: Password title: ParseOptions type: object description: >- Optional object that customizes the parse. Use it to select which pages to process, adjust how content appears in the Markdown, or control how much detail the response includes. Sent as a JSON-serialized string in form data. responses: '200': description: The parse response content: application/json: schema: $ref: '#/components/schemas/ParseResponse' '206': description: Partial success (some pages failed to parse) content: application/json: schema: $ref: '#/components/schemas/ParseResponse' '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.ade.landing.ai/v2/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' - lang: Python label: Python source: >- import requests url = 'https://api.ade.landing.ai/v2/parse' headers = {'Authorization': 'Bearer YOUR_API_KEY'} files = {'document': open('document.pdf', 'rb')} data = {'model': 'dpt-3-pro-latest'} response = requests.post(url, headers=headers, files=files, data=data) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('document', fs.createReadStream('document.pdf')); form.append('model', 'dpt-3-pro-latest'); axios.post('https://api.ade.landing.ai/v2/parse', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: BlocksOptions: additionalProperties: false properties: text: $ref: '#/components/schemas/BaseElementOptions' table: $ref: '#/components/schemas/TableOptions' figure: $ref: '#/components/schemas/FigureOptions' marginalia: $ref: '#/components/schemas/BaseElementOptions' attestation: $ref: '#/components/schemas/BaseElementOptions' logo: $ref: '#/components/schemas/BaseElementOptions' scan_code: $ref: '#/components/schemas/BaseElementOptions' card: $ref: '#/components/schemas/BaseElementOptions' title: BlocksOptions type: object ParseResponse: description: |- The parse result: the full document as `markdown`, its hierarchical `structure` (with per-node spatial `grounding` inline), and request `metadata`. properties: markdown: description: The full document as a single Markdown string, in reading order. title: Markdown type: string metadata: $ref: '#/components/schemas/ParseMetadata' description: >- Information about the request: model version, page count, duration, billing, and more. structure: $ref: '#/components/schemas/Document' description: >- The document's hierarchical structure: pages and the elements detected on each page. Every node below the root carries its spatial data inline in a `grounding` object (`{page, range, box}`, normalized page coordinates); leaf elements additionally carry `atomic_grounding`. required: - markdown - metadata - structure title: ParseResponse type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. BaseElementOptions: additionalProperties: false properties: markdown: default: true title: Markdown type: boolean title: BaseElementOptions type: object TableOptions: additionalProperties: false properties: markdown: default: true title: Markdown type: boolean format: default: html enum: - markdown - html title: Format type: string title: TableOptions type: object FigureOptions: additionalProperties: false properties: markdown: default: true title: Markdown type: boolean title: FigureOptions type: object ParseMetadata: description: Information about a parse request. properties: job_id: anyOf: - type: string - type: 'null' description: >- The parse job identifier — always server-minted and unique per submit. On the async `/jobs` route this is the id the caller polls. Correlates with the job's entry in your billing dashboard. Format: ``-<26-character Crockford base32 ULID>`` matching ``^(parse|extract)-[0-9a-hjkmnp-tv-z]{26}$``. Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. title: Job Id model_version: anyOf: - type: string - type: 'null' description: >- The exact model snapshot that parsed the document, e.g. `dpt-3-pro-20260710`. title: Model Version page_count: anyOf: - type: integer - type: 'null' description: >- Total number of pages in the source document. Includes pages filtered out by `options.pages`; the actual returned pages are in `structure.children`. title: Page Count output_markdown_chars: anyOf: - type: integer - type: 'null' description: Number of Unicode code points in the returned `markdown` string. title: Output Markdown Chars range_units: const: unicode_codepoints description: >- Units of every `range` offset in the response. Always `"unicode_codepoints"` (Unicode code points into `markdown`). Declared explicitly so consumers know how to slice the string — e.g. JavaScript strings are UTF-16, so a naive `.slice()` drifts when the markdown contains astral characters; such consumers must convert code-point offsets to UTF-16 indices first. title: Range Units type: string openapi_spec: description: >- URL of the OpenAPI spec covering this API, for inspection and client generation. title: Openapi Spec type: string failed_pages: description: >- 1-indexed page numbers that failed to parse. Empty when all pages succeed; failed pages also appear in `structure.children` with `status: failed`. items: type: integer title: Failed Pages type: array duration_ms: anyOf: - type: integer - type: 'null' description: Total processing time in milliseconds. title: Duration Ms billing: $ref: '#/components/schemas/ParseBilling' description: 'Billing summary: the service tier and the credits charged.' required: - job_id - model_version - page_count - output_markdown_chars - range_units - openapi_spec - failed_pages - duration_ms - billing title: ParseMetadata type: object Document: properties: type: const: document default: document description: >- The node type. Identifies this node as the root of the structure tree. title: Type type: string children: description: The pages of the document, in source order. items: $ref: '#/components/schemas/Page' title: Children type: array markdown: anyOf: - type: string - type: 'null' default: null description: >- The full document markdown — identical to the top-level `markdown` field, included so the structure tree is self-contained. Present only when `options.inline_markdown` is `true`. title: Markdown title: Document type: object ParseBilling: description: Billing summary for one parse request. properties: service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' description: >- The service tier the request ran in: `standard` or `priority`. A sync request reports `priority` (same lane, same price). title: Service Tier total_credits: anyOf: - type: number - type: 'null' description: Credits charged for this request. title: Total Credits required: - service_tier - total_credits title: ParseBilling type: object Page: properties: type: const: page default: page description: The node type. Identifies this node as a page in the structure tree. title: Type type: string grounding: $ref: '#/components/schemas/Grounding' description: >- The page's spatial data: `page` is the 1-indexed page number in the source document (not contiguous when `options.pages` filters out some pages); `range` covers this page's content in the top-level `markdown` string (zero-length `start == end` for failed pages); `box` is always the full page `{0, 0, 1, 1}`. status: default: ok description: >- Whether this page was parsed successfully (`ok`) or failed (`failed`). enum: - ok - failed title: Status type: string reason: anyOf: - type: string - type: 'null' default: null description: Failure reason. Present only when `status` is `failed`. title: Reason children: description: >- The elements detected on this page, in reading order. Empty for failed pages. items: $ref: '#/components/schemas/Element' title: Children type: array markdown: anyOf: - type: string - type: 'null' default: null description: >- This page's slice of the top-level `markdown` string (`markdown[grounding.range.start:grounding.range.end]`). `""` for failed pages. Present only when `options.inline_markdown` is `true`. title: Markdown required: - grounding title: Page type: object Grounding: description: |- Where a node lives: its page, its slice of `markdown`, and its box. The same shape is used for page nodes, element nodes, and each `atomic_grounding` entry, so any grounding object is self-contained — it can be lifted out of the tree and still locates its content. properties: page: description: >- 1-indexed page number this grounding is on. On a page node, the page's own number. title: Page type: integer range: $ref: '#/components/schemas/Range' description: >- `[start, end)` offsets into the top-level `markdown` string covered by this node or segment. box: $ref: '#/components/schemas/Box' description: >- Bounding box in normalized page coordinates (`0`–`1` fractions of page width/height, at most 5 decimal places). A page node's box is always the full page `{0, 0, 1, 1}`. confidence: anyOf: - type: number - type: 'null' default: null description: >- How sure the model is of the text in this segment, in `[0, 1]`. Present only on word-granularity `atomic_grounding` entries (`dpt-3-verity`), where it is the lowest per-character OCR confidence in the word — so a word is only as trustworthy as its weakest character. Omitted on node-level grounding and on models that ground at line granularity. title: Confidence required: - page - range - box title: Grounding type: object Element: description: |- Hierarchical document element. All non-page elements share this shape. Keys off `type`; optional fields are excluded from the serialized JSON via ``exclude_none=True`` when not set. properties: type: description: >- The element type. Determines which optional fields appear on this element. enum: - text - table - table_cell - figure - marginalia - attestation - logo - card - scan_code title: Type type: string id: description: >- Semantic element id, unique within the document. Format `-`, where `` is a per-type 0-based counter assigned in reading order — `text-0` is the first text element in the document, `figure-0` the first figure, `table_cell-0` the first cell of the first table. Stable within a response but not across re-parses of the same document. title: Id type: string grounding: $ref: '#/components/schemas/Grounding' description: >- The element's spatial data: the page it appears on, its `[start, end)` range in the top-level `markdown` string, and its bounding box in normalized page coordinates. atomic_grounding: anyOf: - items: $ref: '#/components/schemas/Grounding' type: array - type: 'null' default: null description: >- Fine-grained grounding segments, at whichever granularity the model reads at: one entry per visual line for `dpt-3-pro`, one per **word** — each with its `confidence` — for `dpt-3-verity`, including the words inside table cells. Present only on leaf elements — every type except `table`. `[]` in three cases: an element whose markdown is suppressed via `blocks..markdown=false`; a `table_cell` on a line-granularity model (a cell has no finer granularity than itself there); and a `table_cell` on a word-granularity model whose words cannot be located in the rendered cell text — a `|` escaped on the way into a pipe table, or a character escaped on the way into an HTML table — where the segments are dropped rather than risk reporting offsets that point at the wrong characters. Any other leaf the model could not segment finer carries a single entry covering the element's full range and box. Omitted entirely when `options.atomic_grounding` is `false`. title: Atomic Grounding children: anyOf: - items: $ref: '#/components/schemas/Element' type: array - type: 'null' default: null description: >- The cells (`table_cell` elements) of a `table` element. Present only when `type` is `table`. title: Children markdown: anyOf: - type: string - type: 'null' default: null description: >- The element's slice of the top-level `markdown` string (`markdown[grounding.range.start:grounding.range.end]`). `""` for zero-length ranges (e.g. blocks suppressed via `blocks..markdown=false`). Present only when `options.inline_markdown` is `true`. title: Markdown row: anyOf: - type: integer - type: 'null' default: null description: >- 0-indexed row position of this cell within its parent `table`. Present only on `table_cell` elements. title: Row col: anyOf: - type: integer - type: 'null' default: null description: >- 0-indexed column position of this cell within its parent `table`. Present only on `table_cell` elements. title: Col colspan: anyOf: - type: integer - type: 'null' default: null description: >- Number of columns this cell spans. `1` for unmerged cells. Present only on `table_cell` elements. title: Colspan rowspan: anyOf: - type: integer - type: 'null' default: null description: >- Number of rows this cell spans. `1` for unmerged cells. Present only on `table_cell` elements. title: Rowspan required: - type - id - grounding title: Element type: object Range: description: A `[start, end)` slice of the top-level `markdown` string. properties: start: description: >- Inclusive start offset into the top-level `markdown` string, in the units declared by `metadata.range_units` (Unicode code points). title: Start type: integer end: description: >- Exclusive end offset into the top-level `markdown` string, in the units declared by `metadata.range_units` (Unicode code points). title: End type: integer required: - start - end title: Range type: object Box: description: >- Axis-aligned bounding box in normalized page coordinates. Every value is a fraction of the page's width (`xmin`/`xmax`) or height (`ymin`/`ymax`) in `[0, 1]`, with at most 5 decimal places. To convert to pixels, multiply by the dimensions of whatever raster of the page you are drawing on. Coordinates are clamped and rounded at construction so the in-process value always equals the serialized one. properties: xmin: description: Left edge as a fraction of the page width, in `[0, 1]`. title: Xmin type: number ymin: description: Top edge as a fraction of the page height, in `[0, 1]`. title: Ymin type: number xmax: description: Right edge as a fraction of the page width, in `[0, 1]`. title: Xmax type: number ymax: description: Bottom edge as a fraction of the page height, in `[0, 1]`. title: Ymax type: number required: - xmin - ymin - xmax - ymax title: Box type: object ```` # ADE Parse Jobs Source: https://docs.landing.ai/api-reference/parse/ade-parse-jobs Parse a document asynchronously. Returns a job ID; use it to poll for the job's status and retrieve the parse result once processing completes. ## OpenAPI ````yaml /dpt3/openapi-adev2.json post /v2/parse/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/parse/jobs: post: tags: - Parse summary: ADE Parse Jobs description: >- Parse a document asynchronously. Returns a job ID; use it to poll for the job's status and retrieve the parse result once processing completes. operationId: parse_create_job requestBody: required: true content: multipart/form-data: schema: type: object properties: document: type: string format: binary description: >- The file to parse. The file must be a PDF or image; see the list of [supported file types](https://docs.landing.ai/dpt3/file-types). Provide either `document` or `document_url`, not both. document_url: type: string description: >- A publicly accessible URL to the file to parse. The file must be a PDF or image; see the list of [supported file types](https://docs.landing.ai/dpt3/file-types). Provide either `document` or `document_url`, not both. model: type: string description: >- The DPT-3 model snapshot to use for this request. Accepts a dated snapshot (for example, `dpt-3-pro-20260710`), a `-latest` alias, or a bare family name (equivalent to that family's `-latest`). Two families are available: `dpt-3-pro` for highest quality, and `dpt-3-verity` for lower-latency parsing without vision-model captioning. Defaults to the latest DPT-3 Pro snapshot. options: additionalProperties: false properties: pages: anyOf: - items: type: integer type: array - type: 'null' default: null title: Pages blocks: $ref: '#/components/schemas/BlocksOptions' atomic_grounding: default: true description: >- Include the fine-grained `atomic_grounding` array on leaf elements. Set `false` to omit the field entirely from every node. title: Atomic Grounding type: boolean inline_markdown: default: false description: >- Include each node's slice of the document `markdown` inline as a `markdown` field on every structure node: the document root, each page, and each element (including table cells). `atomic_grounding` entries do not carry it. title: Inline Markdown type: boolean password: anyOf: - type: string - type: 'null' default: null description: >- Password for encrypted PDFs. Not currently supported — providing a value returns a 422 error; decrypt the file before uploading. title: Password title: ParseOptions type: object description: >- Optional object that customizes the parse. Use it to select which pages to process, adjust how content appears in the Markdown, or control how much detail the response includes. Sent as a JSON-serialized string in form data. output_save_url: type: string description: >- Public URL the full response is delivered to; the API response then carries ``output_url`` instead of inline data. A presigned URL must stay valid until the job COMPLETES, not just past submit: an already-expired URL, or one whose remaining validity is too short for the document's page count, is rejected at submit (422). By default the URL must retain at least 15 minutes of validity at submit, plus 3 seconds per document page; the 422 message names the exact window required. Sign with credentials that outlive the expected job duration — a URL signed with temporary (assumed-role/session) credentials dies when that session expires, regardless of the URL's stated expiry. service_tier: type: string enum: - standard - priority description: >- Async service tier (``POST /jobs`` only). ``priority`` runs in the fast lane at the sync billing rate; absent → ``standard``. responses: '202': description: Job created content: application/json: schema: type: object required: - job_id - status - created_at properties: job_id: type: string description: >- The unique identifier for the created parse job. Poll ``GET /v2/parse/jobs/{job_id}`` for its status and result. Format: ``-<26-character Crockford base32 ULID>`` matching ``^(parse|extract)-[0-9a-hjkmnp-tv-z]{26}$``. Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. status: type: string enum: - pending - processing - completed - failed description: >- The job's status at creation — normally ``pending`` (a just-created job that is still running is reported as ``pending``), but may already be a terminal ``completed`` / ``failed`` if the job finished before the create response was rendered. created_at: type: - string - 'null' description: ISO-8601 timestamp for when the job was created. '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-3-pro-latest' - lang: Python label: Python source: >- import requests url = 'https://api.ade.landing.ai/v2/parse/jobs' headers = {'Authorization': 'Bearer YOUR_API_KEY'} files = {'document': open('document.pdf', 'rb')} data = {'model': 'dpt-3-pro-latest'} response = requests.post(url, headers=headers, files=files, data=data) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('document', fs.createReadStream('document.pdf')); form.append('model', 'dpt-3-pro-latest'); axios.post('https://api.ade.landing.ai/v2/parse/jobs', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: BlocksOptions: additionalProperties: false properties: text: $ref: '#/components/schemas/BaseElementOptions' table: $ref: '#/components/schemas/TableOptions' figure: $ref: '#/components/schemas/FigureOptions' marginalia: $ref: '#/components/schemas/BaseElementOptions' attestation: $ref: '#/components/schemas/BaseElementOptions' logo: $ref: '#/components/schemas/BaseElementOptions' scan_code: $ref: '#/components/schemas/BaseElementOptions' card: $ref: '#/components/schemas/BaseElementOptions' title: BlocksOptions type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. BaseElementOptions: additionalProperties: false properties: markdown: default: true title: Markdown type: boolean title: BaseElementOptions type: object TableOptions: additionalProperties: false properties: markdown: default: true title: Markdown type: boolean format: default: html enum: - markdown - html title: Format type: string title: TableOptions type: object FigureOptions: additionalProperties: false properties: markdown: default: true title: Markdown type: boolean title: FigureOptions type: object ```` # ADE List Parse Jobs Source: https://docs.landing.ai/api-reference/parse/ade-list-parse-jobs ## OpenAPI ````yaml /dpt3/openapi-adev2.json get /v2/parse/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/parse/jobs: get: tags: - Parse summary: ADE List Parse Jobs operationId: parse_list_jobs parameters: - name: page in: query required: false schema: type: integer minimum: 0 description: Page number (0-indexed). default: 0 title: Page description: Page number (0-indexed). - name: pageSize in: query required: false schema: type: integer maximum: 100 minimum: 1 description: Number of items per page. default: 10 title: Page Size description: Number of items per page. - name: status in: query required: false schema: anyOf: - type: string - type: 'null' description: Filter by job status. title: Status description: Filter by job status. responses: '200': description: The caller's jobs, newest first content: application/json: schema: type: object properties: jobs: type: array description: The caller's parse jobs for this page, newest first. items: type: object properties: job_id: type: string description: >- The unique identifier for the parse job. Format: ``-<26-character Crockford base32 ULID>`` matching ``^(parse|extract)-[0-9a-hjkmnp-tv-z]{26}$``. Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. status: type: string enum: - pending - processing - completed - failed description: >- The job's current status: ``pending``, ``processing``, ``completed``, or ``failed``. created_at: type: - string - 'null' description: ISO-8601 timestamp for when the job was created. completed_at: type: - string - 'null' description: >- ISO-8601 timestamp for when the job finished, if terminal. model_version: type: - string - 'null' description: The model snapshot used to parse the document. failure_reason: type: - string - 'null' description: >- The reason the job failed. Present only when ``status`` is ``failed``. page: type: integer description: The 0-indexed page number. page_size: type: integer description: Items per page. has_more: type: boolean description: >- Whether more jobs exist beyond this page; request the next ``page`` to fetch them. '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl 'https://api.ade.landing.ai/v2/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests url = 'https://api.ade.landing.ai/v2/parse/jobs' headers = {'Authorization': 'Bearer YOUR_API_KEY'} response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); axios.get('https://api.ade.landing.ai/v2/parse/jobs', { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. ```` # ADE Get Parse Jobs Source: https://docs.landing.ai/api-reference/parse/ade-get-parse-jobs Get the status of an async parse job. Once the job has ``completed``, ``result`` carries the parse response (or ``output_url`` when ``output_save_url`` was set). Partial success (some pages failed) is reported in ``result.metadata.failed_pages``. ## OpenAPI ````yaml /dpt3/openapi-adev2.json get /v2/parse/jobs/{job_id} openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/parse/jobs/{job_id}: get: tags: - Parse summary: ADE Get Parse Jobs description: >- Get the status of an async parse job. Once the job has ``completed``, ``result`` carries the parse response (or ``output_url`` when ``output_save_url`` was set). Partial success (some pages failed) is reported in ``result.metadata.failed_pages``. operationId: parse_get_job parameters: - name: job_id in: path required: true schema: type: string description: >- The identifier of the job to retrieve, as returned by the create-job request. title: Job Id description: >- The identifier of the job to retrieve, as returned by the create-job request. responses: '200': description: Job status / result content: application/json: schema: type: object properties: job_id: type: string description: >- The unique identifier for this parse job. Format: ``-<26-character Crockford base32 ULID>`` matching ``^(parse|extract)-[0-9a-hjkmnp-tv-z]{26}$``. Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. status: type: string enum: - pending - processing - completed - failed description: >- The job's current status: ``pending``, ``processing``, ``completed``, or ``failed``. created_at: type: - string - 'null' description: ISO-8601 timestamp for when the job was created. completed_at: type: string description: ISO-8601 timestamp; present once the job is terminal. progress: type: number description: >- Job completion as a decimal from 0 (not started) to 1 (complete). Present while ``processing``. result: anyOf: - $ref: '#/components/schemas/ParseResponse' - type: 'null' description: >- The parse response, present once the job has ``completed`` and ``output_save_url`` was not set. When ``output_save_url`` was set, the result is delivered there and ``output_url`` is returned instead. output_url: type: - string - 'null' description: >- The URL the result was delivered to. Present once the job has ``completed`` and ``output_save_url`` was set, instead of inline ``result``. metadata: anyOf: - $ref: '#/components/schemas/ParseMetadata' - type: 'null' description: >- The parse metadata (billing included), present alongside ``output_url`` once a job with ``output_save_url`` has ``completed`` — the delivery moves the content, not the receipt. Inline jobs carry it inside ``result`` instead. error: type: object description: >- Present once the job has ``failed`` — the failure code + message. properties: code: type: string description: Stable error code. message: type: string '404': description: Job not found content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl 'https://api.ade.landing.ai/v2/parse/jobs/JOB_ID' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests url = 'https://api.ade.landing.ai/v2/parse/jobs/JOB_ID' headers = {'Authorization': 'Bearer YOUR_API_KEY'} response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); axios.get('https://api.ade.landing.ai/v2/parse/jobs/JOB_ID', { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ParseResponse: description: |- The parse result: the full document as `markdown`, its hierarchical `structure` (with per-node spatial `grounding` inline), and request `metadata`. properties: markdown: description: The full document as a single Markdown string, in reading order. title: Markdown type: string metadata: $ref: '#/components/schemas/ParseMetadata' description: >- Information about the request: model version, page count, duration, billing, and more. structure: $ref: '#/components/schemas/Document' description: >- The document's hierarchical structure: pages and the elements detected on each page. Every node below the root carries its spatial data inline in a `grounding` object (`{page, range, box}`, normalized page coordinates); leaf elements additionally carry `atomic_grounding`. required: - markdown - metadata - structure title: ParseResponse type: object ParseMetadata: description: Information about a parse request. properties: job_id: anyOf: - type: string - type: 'null' description: >- The parse job identifier — always server-minted and unique per submit. On the async `/jobs` route this is the id the caller polls. Correlates with the job's entry in your billing dashboard. Format: ``-<26-character Crockford base32 ULID>`` matching ``^(parse|extract)-[0-9a-hjkmnp-tv-z]{26}$``. Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. title: Job Id model_version: anyOf: - type: string - type: 'null' description: >- The exact model snapshot that parsed the document, e.g. `dpt-3-pro-20260710`. title: Model Version page_count: anyOf: - type: integer - type: 'null' description: >- Total number of pages in the source document. Includes pages filtered out by `options.pages`; the actual returned pages are in `structure.children`. title: Page Count output_markdown_chars: anyOf: - type: integer - type: 'null' description: Number of Unicode code points in the returned `markdown` string. title: Output Markdown Chars range_units: const: unicode_codepoints description: >- Units of every `range` offset in the response. Always `"unicode_codepoints"` (Unicode code points into `markdown`). Declared explicitly so consumers know how to slice the string — e.g. JavaScript strings are UTF-16, so a naive `.slice()` drifts when the markdown contains astral characters; such consumers must convert code-point offsets to UTF-16 indices first. title: Range Units type: string openapi_spec: description: >- URL of the OpenAPI spec covering this API, for inspection and client generation. title: Openapi Spec type: string failed_pages: description: >- 1-indexed page numbers that failed to parse. Empty when all pages succeed; failed pages also appear in `structure.children` with `status: failed`. items: type: integer title: Failed Pages type: array duration_ms: anyOf: - type: integer - type: 'null' description: Total processing time in milliseconds. title: Duration Ms billing: $ref: '#/components/schemas/ParseBilling' description: 'Billing summary: the service tier and the credits charged.' required: - job_id - model_version - page_count - output_markdown_chars - range_units - openapi_spec - failed_pages - duration_ms - billing title: ParseMetadata type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. Document: properties: type: const: document default: document description: >- The node type. Identifies this node as the root of the structure tree. title: Type type: string children: description: The pages of the document, in source order. items: $ref: '#/components/schemas/Page' title: Children type: array markdown: anyOf: - type: string - type: 'null' default: null description: >- The full document markdown — identical to the top-level `markdown` field, included so the structure tree is self-contained. Present only when `options.inline_markdown` is `true`. title: Markdown title: Document type: object ParseBilling: description: Billing summary for one parse request. properties: service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' description: >- The service tier the request ran in: `standard` or `priority`. A sync request reports `priority` (same lane, same price). title: Service Tier total_credits: anyOf: - type: number - type: 'null' description: Credits charged for this request. title: Total Credits required: - service_tier - total_credits title: ParseBilling type: object Page: properties: type: const: page default: page description: The node type. Identifies this node as a page in the structure tree. title: Type type: string grounding: $ref: '#/components/schemas/Grounding' description: >- The page's spatial data: `page` is the 1-indexed page number in the source document (not contiguous when `options.pages` filters out some pages); `range` covers this page's content in the top-level `markdown` string (zero-length `start == end` for failed pages); `box` is always the full page `{0, 0, 1, 1}`. status: default: ok description: >- Whether this page was parsed successfully (`ok`) or failed (`failed`). enum: - ok - failed title: Status type: string reason: anyOf: - type: string - type: 'null' default: null description: Failure reason. Present only when `status` is `failed`. title: Reason children: description: >- The elements detected on this page, in reading order. Empty for failed pages. items: $ref: '#/components/schemas/Element' title: Children type: array markdown: anyOf: - type: string - type: 'null' default: null description: >- This page's slice of the top-level `markdown` string (`markdown[grounding.range.start:grounding.range.end]`). `""` for failed pages. Present only when `options.inline_markdown` is `true`. title: Markdown required: - grounding title: Page type: object Grounding: description: |- Where a node lives: its page, its slice of `markdown`, and its box. The same shape is used for page nodes, element nodes, and each `atomic_grounding` entry, so any grounding object is self-contained — it can be lifted out of the tree and still locates its content. properties: page: description: >- 1-indexed page number this grounding is on. On a page node, the page's own number. title: Page type: integer range: $ref: '#/components/schemas/Range' description: >- `[start, end)` offsets into the top-level `markdown` string covered by this node or segment. box: $ref: '#/components/schemas/Box' description: >- Bounding box in normalized page coordinates (`0`–`1` fractions of page width/height, at most 5 decimal places). A page node's box is always the full page `{0, 0, 1, 1}`. confidence: anyOf: - type: number - type: 'null' default: null description: >- How sure the model is of the text in this segment, in `[0, 1]`. Present only on word-granularity `atomic_grounding` entries (`dpt-3-verity`), where it is the lowest per-character OCR confidence in the word — so a word is only as trustworthy as its weakest character. Omitted on node-level grounding and on models that ground at line granularity. title: Confidence required: - page - range - box title: Grounding type: object Element: description: |- Hierarchical document element. All non-page elements share this shape. Keys off `type`; optional fields are excluded from the serialized JSON via ``exclude_none=True`` when not set. properties: type: description: >- The element type. Determines which optional fields appear on this element. enum: - text - table - table_cell - figure - marginalia - attestation - logo - card - scan_code title: Type type: string id: description: >- Semantic element id, unique within the document. Format `-`, where `` is a per-type 0-based counter assigned in reading order — `text-0` is the first text element in the document, `figure-0` the first figure, `table_cell-0` the first cell of the first table. Stable within a response but not across re-parses of the same document. title: Id type: string grounding: $ref: '#/components/schemas/Grounding' description: >- The element's spatial data: the page it appears on, its `[start, end)` range in the top-level `markdown` string, and its bounding box in normalized page coordinates. atomic_grounding: anyOf: - items: $ref: '#/components/schemas/Grounding' type: array - type: 'null' default: null description: >- Fine-grained grounding segments, at whichever granularity the model reads at: one entry per visual line for `dpt-3-pro`, one per **word** — each with its `confidence` — for `dpt-3-verity`, including the words inside table cells. Present only on leaf elements — every type except `table`. `[]` in three cases: an element whose markdown is suppressed via `blocks..markdown=false`; a `table_cell` on a line-granularity model (a cell has no finer granularity than itself there); and a `table_cell` on a word-granularity model whose words cannot be located in the rendered cell text — a `|` escaped on the way into a pipe table, or a character escaped on the way into an HTML table — where the segments are dropped rather than risk reporting offsets that point at the wrong characters. Any other leaf the model could not segment finer carries a single entry covering the element's full range and box. Omitted entirely when `options.atomic_grounding` is `false`. title: Atomic Grounding children: anyOf: - items: $ref: '#/components/schemas/Element' type: array - type: 'null' default: null description: >- The cells (`table_cell` elements) of a `table` element. Present only when `type` is `table`. title: Children markdown: anyOf: - type: string - type: 'null' default: null description: >- The element's slice of the top-level `markdown` string (`markdown[grounding.range.start:grounding.range.end]`). `""` for zero-length ranges (e.g. blocks suppressed via `blocks..markdown=false`). Present only when `options.inline_markdown` is `true`. title: Markdown row: anyOf: - type: integer - type: 'null' default: null description: >- 0-indexed row position of this cell within its parent `table`. Present only on `table_cell` elements. title: Row col: anyOf: - type: integer - type: 'null' default: null description: >- 0-indexed column position of this cell within its parent `table`. Present only on `table_cell` elements. title: Col colspan: anyOf: - type: integer - type: 'null' default: null description: >- Number of columns this cell spans. `1` for unmerged cells. Present only on `table_cell` elements. title: Colspan rowspan: anyOf: - type: integer - type: 'null' default: null description: >- Number of rows this cell spans. `1` for unmerged cells. Present only on `table_cell` elements. title: Rowspan required: - type - id - grounding title: Element type: object Range: description: A `[start, end)` slice of the top-level `markdown` string. properties: start: description: >- Inclusive start offset into the top-level `markdown` string, in the units declared by `metadata.range_units` (Unicode code points). title: Start type: integer end: description: >- Exclusive end offset into the top-level `markdown` string, in the units declared by `metadata.range_units` (Unicode code points). title: End type: integer required: - start - end title: Range type: object Box: description: >- Axis-aligned bounding box in normalized page coordinates. Every value is a fraction of the page's width (`xmin`/`xmax`) or height (`ymin`/`ymax`) in `[0, 1]`, with at most 5 decimal places. To convert to pixels, multiply by the dimensions of whatever raster of the page you are drawing on. Coordinates are clamped and rounded at construction so the in-process value always equals the serialized one. properties: xmin: description: Left edge as a fraction of the page width, in `[0, 1]`. title: Xmin type: number ymin: description: Top edge as a fraction of the page height, in `[0, 1]`. title: Ymin type: number xmax: description: Right edge as a fraction of the page width, in `[0, 1]`. title: Xmax type: number ymax: description: Bottom edge as a fraction of the page height, in `[0, 1]`. title: Ymax type: number required: - xmin - ymin - xmax - ymax title: Box type: object ```` # ADE Extract Source: https://docs.landing.ai/api-reference/extract/ade-extract Extract structured data from a Markdown document according to a JSON schema, with character-span grounding into the source Markdown. Runs synchronously and returns the result inline. ## OpenAPI ````yaml /dpt3/openapi-adev2.json post /v2/extract openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/extract: post: tags: - Extract summary: ADE Extract description: >- Extract structured data from a Markdown document according to a JSON schema, with character-span grounding into the source Markdown. Runs synchronously and returns the result inline. operationId: v2-extract_run_sync requestBody: required: true content: application/json: schema: description: >- The Extract API request body. Provide the markdown as an inline ``markdown`` string, as a multipart file part named ``markdown`` (recommended for large inputs), or via a public ``markdown_url``. Exactly one source must be supplied. properties: schema: additionalProperties: true description: >- JSON Schema describing the fields to extract. The schema must be an object type with a ``properties`` map of field names to their types and descriptions. example: properties: revenue: description: Q1 revenue figure type: string summary: description: Executive summary type: string type: object title: Schema type: object markdown: anyOf: - type: string - type: 'null' default: null description: >- Markdown string to extract from, or a multipart FILE part carrying the markdown (recommended for large inputs). Can come from any source — LandingAI parse output, a third-party parser, or hand-authored text. When the markdown was produced by ``POST /v2/parse``, it ends with a ```` comment that the service reads automatically and echoes as ``metadata.doc_id``. title: Markdown markdown_url: anyOf: - type: string - type: 'null' default: null description: >- URL to fetch the markdown from. Must be a public http(s) URL; private/loopback IPs are rejected at submit time. title: Markdown Url model: anyOf: - type: string - type: 'null' default: null description: >- The version of the model to use for extraction. Use ``extract-latest`` to use the latest version. title: Model options: anyOf: - $ref: '#/components/schemas/V2ExtractOptions' - type: 'null' default: null description: Extraction options (``strict``). Omit for defaults. required: - schema title: V2ExtractRequest type: object multipart/form-data: schema: type: object properties: schema: additionalProperties: true description: >- JSON Schema describing the fields to extract. The schema must be an object type with a ``properties`` map of field names to their types and descriptions. JSON-serialized string in form data. example: properties: revenue: description: Q1 revenue figure type: string summary: description: Executive summary type: string type: object title: Schema type: object markdown: anyOf: - type: string description: >- Markdown string to extract from, or a multipart FILE part carrying the markdown (recommended for large inputs). Can come from any source — LandingAI parse output, a third-party parser, or hand-authored text. When the markdown was produced by ``POST /v2/parse``, it ends with a ```` comment that the service reads automatically and echoes as ``metadata.doc_id``. - type: string format: binary description: File upload. markdown_url: anyOf: - type: string - type: 'null' default: null description: >- URL to fetch the markdown from. Must be a public http(s) URL; private/loopback IPs are rejected at submit time. JSON-serialized string in form data. title: Markdown Url model: anyOf: - type: string - type: 'null' default: null description: >- The version of the model to use for extraction. Use ``extract-latest`` to use the latest version. JSON-serialized string in form data. title: Model options: anyOf: - $ref: '#/components/schemas/V2ExtractOptions' - type: 'null' default: null description: >- Extraction options (``strict``). Omit for defaults. JSON-serialized string in form data. required: - schema responses: '200': description: v2-extract result content: application/json: schema: description: >- The Extract API response body. ``extraction`` and ``extraction_metadata`` mirror each other structurally: leaf values in ``extraction`` are replaced by ``ExtractionFieldMetadata`` objects in ``extraction_metadata``. properties: extraction: additionalProperties: true description: Extracted values conforming to the request ``schema``. title: Extraction type: object extraction_metadata: additionalProperties: true description: >- Per-field metadata, mirroring ``extraction`` with leaf values replaced by ``{value, ranges}`` objects. title: Extraction Metadata type: object markdown: description: Echoed input markdown. title: Markdown type: string metadata: $ref: '#/components/schemas/V2ExtractMetadata' description: >- Request metadata (job_id, model_version, duration_ms, doc_id, billing). schema_violation_error: anyOf: - type: string - type: 'null' default: null description: >- Set when ``options.strict`` is false and the schema contained fields the model could not extract — the extraction is partial. title: Schema Violation Error warnings: description: Non-fatal warnings emitted during extraction. items: additionalProperties: true type: object title: Warnings type: array required: - extraction - extraction_metadata - markdown - metadata title: V2ExtractResult type: object '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.ade.landing.ai/v2/extract' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' - lang: Python label: Python source: >- import json import requests url = 'https://api.ade.landing.ai/v2/extract' headers = {'Authorization': 'Bearer YOUR_API_KEY'} files = {'markdown': open('parse-output.md', 'rb')} data = { 'schema': json.dumps({ 'type': 'object', 'properties': { 'revenue': {'type': 'string', 'description': 'Q1 2024 revenue'} } }) } response = requests.post(url, headers=headers, files=files, data=data) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdown', fs.createReadStream('parse-output.md')); form.append('schema', JSON.stringify({ type: 'object', properties: { revenue: { type: 'string', description: 'Q1 2024 revenue' } } })); axios.post('https://api.ade.landing.ai/v2/extract', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: V2ExtractOptions: additionalProperties: false description: Extraction options. properties: strict: default: false description: >- When ``true``, a schema containing fields the model cannot extract fails with a validation error — HTTP 422 on the sync route, or a failed job (``status: "failed"``) on the async ``/jobs`` route. When ``false`` (default), unsupported fields are skipped and extraction continues. title: Strict type: boolean title: V2ExtractOptions type: object V2ExtractMetadata: description: Response metadata for a v2 extract call. properties: job_id: description: >- The job ID for this request. Correlates with the request's entry in your billing dashboard. title: Job Id type: string model_version: description: Resolved model version. title: Model Version type: string duration_ms: description: End-to-end request duration in milliseconds. title: Duration Ms type: integer doc_id: anyOf: - type: string - type: 'null' default: null description: >- Present when the input markdown contained a ```` comment (embedded by ``POST /v2/parse``). Links this extract call to the originating parse job. title: Doc Id range_units: const: unicode_codepoints default: unicode_codepoints description: >- Units of every `range` offset in the response. Always `"unicode_codepoints"` (Unicode code points into `markdown`). Declared explicitly so consumers know how to slice the string — e.g. JavaScript strings are UTF-16, so a naive `.slice()` drifts when the markdown contains astral characters. title: Range Units type: string input_markdown_chars: anyOf: - type: integer - type: 'null' default: null description: >- Characters (Unicode code points) in the input markdown as submitted — the input basis of the credit charge. title: Input Markdown Chars output_extraction_chars: anyOf: - type: integer - type: 'null' default: null description: >- Characters in the serialized extraction output — the output basis of the credit charge. title: Output Extraction Chars openapi_spec: type: string description: >- URL of the OpenAPI spec covering this API, for inspection and client generation. billing: anyOf: - $ref: '#/components/schemas/V2Billing' - type: 'null' description: >- Billing summary: the service tier the request ran in and the credits charged. required: - job_id - model_version - duration_ms - openapi_spec - range_units title: V2ExtractMetadata type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. V2Billing: description: |- Billing summary: the service tier the request ran in and the credits charged. properties: service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' default: null description: >- The service tier the request ran in: `standard` or `priority`. A sync request reports `priority` (same lane, same price). title: Service Tier total_credits: anyOf: - type: number - type: 'null' default: null description: Credits charged for this request. title: Total Credits title: V2Billing type: object ```` # ADE Extract Jobs Source: https://docs.landing.ai/api-reference/extract/ade-extract-jobs Extract structured data from a Markdown document according to a JSON schema, with character-span grounding into the source Markdown. Runs asynchronously and returns a job ID; use it to poll for status and retrieve the result once processing completes. ## OpenAPI ````yaml /dpt3/openapi-adev2.json post /v2/extract/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/extract/jobs: post: tags: - Extract summary: ADE Extract Jobs description: >- Extract structured data from a Markdown document according to a JSON schema, with character-span grounding into the source Markdown. Runs asynchronously and returns a job ID; use it to poll for status and retrieve the result once processing completes. operationId: v2-extract_create_job requestBody: required: true content: application/json: schema: description: >- The Extract API request body. Provide the markdown as an inline ``markdown`` string, as a multipart file part named ``markdown`` (recommended for large inputs), or via a public ``markdown_url``. Exactly one source must be supplied. properties: schema: additionalProperties: true description: >- JSON Schema describing the fields to extract. The schema must be an object type with a ``properties`` map of field names to their types and descriptions. example: properties: revenue: description: Q1 revenue figure type: string summary: description: Executive summary type: string type: object title: Schema type: object markdown: anyOf: - type: string - type: 'null' default: null description: >- Markdown string to extract from, or a multipart FILE part carrying the markdown (recommended for large inputs). Can come from any source — LandingAI parse output, a third-party parser, or hand-authored text. When the markdown was produced by ``POST /v2/parse``, it ends with a ```` comment that the service reads automatically and echoes as ``metadata.doc_id``. title: Markdown markdown_url: anyOf: - type: string - type: 'null' default: null description: >- URL to fetch the markdown from. Must be a public http(s) URL; private/loopback IPs are rejected at submit time. title: Markdown Url model: anyOf: - type: string - type: 'null' default: null description: >- The version of the model to use for extraction. Use ``extract-latest`` to use the latest version. title: Model options: anyOf: - $ref: '#/components/schemas/V2ExtractOptions' - type: 'null' default: null description: Extraction options (``strict``). Omit for defaults. output_save_url: anyOf: - type: string - type: 'null' default: null description: >- URL to save the result to — e.g. a presigned S3 PUT URL. Async jobs only. When set, the finished result is delivered (HTTP PUT) to this URL and the completed job reports ``output_url`` instead of an inline ``result``. Must be a public http(s) URL; private/loopback IPs are rejected at submit time. A presigned URL must stay valid until the job COMPLETES, not just past submit — an already-expired presign, or one with less than 15 minutes of validity remaining (the default floor; the 422 names the exact window required), is rejected at submit. Sign with credentials that outlive the expected job duration: a URL signed with temporary (assumed-role/session) credentials dies when that session expires, regardless of the URL's stated expiry. title: Output Save Url service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' description: >- Async service tier. ``priority`` runs in the fast lane at the sync billing rate; absent → ``standard``. required: - schema title: V2ExtractRequest type: object multipart/form-data: schema: type: object properties: schema: additionalProperties: true description: >- JSON Schema describing the fields to extract. The schema must be an object type with a ``properties`` map of field names to their types and descriptions. JSON-serialized string in form data. example: properties: revenue: description: Q1 revenue figure type: string summary: description: Executive summary type: string type: object title: Schema type: object markdown: anyOf: - type: string description: >- Markdown string to extract from, or a multipart FILE part carrying the markdown (recommended for large inputs). Can come from any source — LandingAI parse output, a third-party parser, or hand-authored text. When the markdown was produced by ``POST /v2/parse``, it ends with a ```` comment that the service reads automatically and echoes as ``metadata.doc_id``. - type: string format: binary description: File upload. markdown_url: anyOf: - type: string - type: 'null' default: null description: >- URL to fetch the markdown from. Must be a public http(s) URL; private/loopback IPs are rejected at submit time. JSON-serialized string in form data. title: Markdown Url model: anyOf: - type: string - type: 'null' default: null description: >- The version of the model to use for extraction. Use ``extract-latest`` to use the latest version. JSON-serialized string in form data. title: Model options: anyOf: - $ref: '#/components/schemas/V2ExtractOptions' - type: 'null' default: null description: >- Extraction options (``strict``). Omit for defaults. JSON-serialized string in form data. output_save_url: anyOf: - type: string - type: 'null' default: null description: >- URL to save the result to — e.g. a presigned S3 PUT URL. Async jobs only. When set, the finished result is delivered (HTTP PUT) to this URL and the completed job reports ``output_url`` instead of an inline ``result``. Must be a public http(s) URL; private/loopback IPs are rejected at submit time. A presigned URL must stay valid until the job COMPLETES, not just past submit — an already-expired presign, or one with less than 15 minutes of validity remaining (the default floor; the 422 names the exact window required), is rejected at submit. Sign with credentials that outlive the expected job duration: a URL signed with temporary (assumed-role/session) credentials dies when that session expires, regardless of the URL's stated expiry. JSON-serialized string in form data. title: Output Save Url service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' description: >- Async service tier. ``priority`` runs in the fast lane at the sync billing rate; absent → ``standard``. required: - schema responses: '202': description: Job created content: application/json: schema: type: object properties: job_id: type: string description: >- The unique identifier for this v2-extract job. Format: ``extract-<26-character Crockford base32 ULID>`` (``[0-9a-hjkmnp-tv-z]{26}`` tail). Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. status: type: string enum: - pending - processing - completed - failed created_at: type: - string - 'null' '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parse-output.md' \ -F 'schema={"type":"object","properties":{"revenue":{"type":"string","description":"Q1 2024 revenue"}}}' - lang: Python label: Python source: >- import json import requests url = 'https://api.ade.landing.ai/v2/extract/jobs' headers = {'Authorization': 'Bearer YOUR_API_KEY'} files = {'markdown': open('parse-output.md', 'rb')} data = { 'schema': json.dumps({ 'type': 'object', 'properties': { 'revenue': {'type': 'string', 'description': 'Q1 2024 revenue'} } }) } response = requests.post(url, headers=headers, files=files, data=data) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdown', fs.createReadStream('parse-output.md')); form.append('schema', JSON.stringify({ type: 'object', properties: { revenue: { type: 'string', description: 'Q1 2024 revenue' } } })); axios.post('https://api.ade.landing.ai/v2/extract/jobs', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: V2ExtractOptions: additionalProperties: false description: Extraction options. properties: strict: default: false description: >- When ``true``, a schema containing fields the model cannot extract fails with a validation error — HTTP 422 on the sync route, or a failed job (``status: "failed"``) on the async ``/jobs`` route. When ``false`` (default), unsupported fields are skipped and extraction continues. title: Strict type: boolean title: V2ExtractOptions type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. ```` # ADE List Extract Jobs Source: https://docs.landing.ai/api-reference/extract/ade-list-extract-jobs List your Extract jobs, newest first. ## OpenAPI ````yaml /dpt3/openapi-adev2.json get /v2/extract/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/extract/jobs: get: tags: - Extract summary: ADE List Extract Jobs description: List your Extract jobs, newest first. operationId: v2-extract_list_jobs parameters: - name: page in: query required: false schema: type: integer minimum: 0 description: Page number (0-indexed). default: 0 title: Page description: Page number (0-indexed). - name: pageSize in: query required: false schema: type: integer maximum: 100 minimum: 1 description: Number of items per page. default: 10 title: Page Size description: Number of items per page. - name: status in: query required: false schema: anyOf: - type: string - type: 'null' description: Filter by job status. title: Status description: Filter by job status. responses: '200': description: The caller's jobs, newest first content: application/json: schema: type: object properties: jobs: type: array items: type: object properties: job_id: type: string description: >- The unique identifier for this v2-extract job. Format: ``extract-<26-character Crockford base32 ULID>`` (``[0-9a-hjkmnp-tv-z]{26}`` tail). Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. status: type: string enum: - pending - processing - completed - failed created_at: type: - string - 'null' completed_at: type: - string - 'null' model_version: type: - string - 'null' failure_reason: type: - string - 'null' page: type: integer page_size: type: integer has_more: type: boolean '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl 'https://api.ade.landing.ai/v2/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests url = 'https://api.ade.landing.ai/v2/extract/jobs' headers = {'Authorization': 'Bearer YOUR_API_KEY'} response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); axios.get('https://api.ade.landing.ai/v2/extract/jobs', { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. ```` # ADE Get Extract Jobs Source: https://docs.landing.ai/api-reference/extract/ade-get-extract-jobs Get the status of an async Extract job, including its result once the job has completed. ## OpenAPI ````yaml /dpt3/openapi-adev2.json get /v2/extract/jobs/{job_id} openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/extract/jobs/{job_id}: get: tags: - Extract summary: ADE Get Extract Jobs description: >- Get the status of an async Extract job, including its result once the job has completed. operationId: v2-extract_get_job parameters: - name: job_id in: path required: true schema: type: string description: >- The identifier of the job to retrieve, as returned by the create-job request. title: Job Id description: >- The identifier of the job to retrieve, as returned by the create-job request. responses: '200': description: Job status / result content: application/json: schema: type: object properties: job_id: type: string description: >- The unique identifier for this v2-extract job. Format: ``extract-<26-character Crockford base32 ULID>`` (``[0-9a-hjkmnp-tv-z]{26}`` tail). Opaque, server-minted, and stable for the life of the job — the same id is returned on the sync response, the async 202, and every poll. Treat it as opaque; older id formats remain accepted indefinitely and are never re-issued. status: type: string enum: - pending - processing - completed - failed created_at: type: - string - 'null' completed_at: type: string description: Present once the job is terminal. progress: type: number minimum: 0 maximum: 1 description: >- Estimated completion as a decimal from 0 to 1 — an estimate, not a measurement: it typically advances between polls while the job is ``processing``, may jump forward when the service reports a real milestone (e.g. parsed pages), and approaches but never reaches 1 (long-running jobs plateau near 0.98 — completion is signaled by ``status``, and a job may complete from any progress value). Present while ``processing``. result: anyOf: - description: >- The Extract API response body. ``extraction`` and ``extraction_metadata`` mirror each other structurally: leaf values in ``extraction`` are replaced by ``ExtractionFieldMetadata`` objects in ``extraction_metadata``. properties: extraction: additionalProperties: true description: >- Extracted values conforming to the request ``schema``. title: Extraction type: object extraction_metadata: additionalProperties: true description: >- Per-field metadata, mirroring ``extraction`` with leaf values replaced by ``{value, ranges}`` objects. title: Extraction Metadata type: object markdown: description: Echoed input markdown. title: Markdown type: string metadata: $ref: '#/components/schemas/V2ExtractMetadata' description: >- Request metadata (job_id, model_version, duration_ms, doc_id, billing). schema_violation_error: anyOf: - type: string - type: 'null' default: null description: >- Set when ``options.strict`` is false and the schema contained fields the model could not extract — the extraction is partial. title: Schema Violation Error warnings: description: Non-fatal warnings emitted during extraction. items: additionalProperties: true type: object title: Warnings type: array required: - extraction - extraction_metadata - markdown - metadata title: V2ExtractResult type: object - type: 'null' description: >- Present once status is ``completed`` and ``output_save_url`` was not set. When ``output_save_url`` was set, the result is delivered there and ``output_url`` is returned instead. error: type: object description: Present once status is ``failed``. properties: code: type: string description: Stable error code (``internal_error`` when unmapped). message: type: string output_url: type: - string - 'null' description: >- The URL the result was delivered to. Present once the job has ``completed`` and ``output_save_url`` was set, instead of inline ``result``. metadata: type: - object - 'null' description: >- The result's metadata block (billing included), present alongside ``output_url`` once a job with ``output_save_url`` has ``completed`` — the delivery moves the content, not the receipt. Same shape as the inline ``result``'s ``metadata``; inline jobs carry it there instead. '404': description: Not found (e.g. no such job). content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl 'https://api.ade.landing.ai/v2/extract/jobs/JOB_ID' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests url = 'https://api.ade.landing.ai/v2/extract/jobs/JOB_ID' headers = {'Authorization': 'Bearer YOUR_API_KEY'} response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); axios.get('https://api.ade.landing.ai/v2/extract/jobs/JOB_ID', { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: V2ExtractMetadata: description: Response metadata for a v2 extract call. properties: job_id: description: >- The job ID for this request. Correlates with the request's entry in your billing dashboard. title: Job Id type: string model_version: description: Resolved model version. title: Model Version type: string duration_ms: description: End-to-end request duration in milliseconds. title: Duration Ms type: integer doc_id: anyOf: - type: string - type: 'null' default: null description: >- Present when the input markdown contained a ```` comment (embedded by ``POST /v2/parse``). Links this extract call to the originating parse job. title: Doc Id range_units: const: unicode_codepoints default: unicode_codepoints description: >- Units of every `range` offset in the response. Always `"unicode_codepoints"` (Unicode code points into `markdown`). Declared explicitly so consumers know how to slice the string — e.g. JavaScript strings are UTF-16, so a naive `.slice()` drifts when the markdown contains astral characters. title: Range Units type: string input_markdown_chars: anyOf: - type: integer - type: 'null' default: null description: >- Characters (Unicode code points) in the input markdown as submitted — the input basis of the credit charge. title: Input Markdown Chars output_extraction_chars: anyOf: - type: integer - type: 'null' default: null description: >- Characters in the serialized extraction output — the output basis of the credit charge. title: Output Extraction Chars openapi_spec: type: string description: >- URL of the OpenAPI spec covering this API, for inspection and client generation. billing: anyOf: - $ref: '#/components/schemas/V2Billing' - type: 'null' description: >- Billing summary: the service tier the request ran in and the credits charged. required: - job_id - model_version - duration_ms - openapi_spec - range_units title: V2ExtractMetadata type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. V2Billing: description: |- Billing summary: the service tier the request ran in and the credits charged. properties: service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' default: null description: >- The service tier the request ran in: `standard` or `priority`. A sync request reports `priority` (same lane, same price). title: Service Tier total_credits: anyOf: - type: number - type: 'null' default: null description: Credits charged for this request. title: Total Credits title: V2Billing type: object ```` # ADE Ground Source: https://docs.landing.ai/api-reference/ground/ade-ground Map extracted fields to the document blocks they were quoted from. Takes the extraction_metadata from an extract call and the structure tree from the parse call the markdown came from, and returns, for every extracted field, the overlapping blocks with their ids, page numbers, and bounding boxes. Ru ## OpenAPI ````yaml /dpt3/openapi-adev2.json post /v2/ground openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen2 API: Parse, Extract, and Ground Documents with DPT-3 description: >- Parse and extract data from documents with DPT-3, a document parsing model from LandingAI, using the Agentic Document Extraction (ADE) v2 endpoints. Parse converts PDFs and images into structured Markdown and elements with per-element grounding (page numbers and coordinates) for RAG, search, and extraction pipelines. Extract pulls specific fields from parsed Markdown using a JSON schema. Ground maps extracted fields back to the source blocks, with page numbers and bounding boxes for each value. Documentation: https://docs.landing.ai version: 1.0.0 servers: - url: https://api.ade.landing.ai description: Production API security: [] paths: /v2/ground: post: tags: - Ground summary: ADE Ground description: >- Map extracted fields to the document blocks they were quoted from. Takes the extraction_metadata from an extract call and the structure tree from the parse call the markdown came from, and returns, for every extracted field, the overlapping blocks with their ids, page numbers, and bounding boxes. Runs synchronously and returns the result inline. operationId: v2-ground_run_sync requestBody: required: true content: application/json: schema: description: >- The Ground API request body. A pure, stateless join: each ``extraction_metadata`` leaf's ``ranges`` (char offsets into the markdown both artifacts were produced from) is overlapped against the ``grounding.range`` carried on every ``structure`` block, and the matching blocks are returned. Nothing is stored server-side, so block ids in the response resolve only against the ``structure`` tree supplied here — pairing an extraction with the parse result it actually came from is the caller's responsibility. properties: extraction_metadata: additionalProperties: true description: >- The ``extraction_metadata`` object returned by ``POST /v2/extract`` (or the pipeline's extract step): a tree mirroring your extraction schema whose leaves are ``{value, ranges}`` objects, where ``ranges`` are ``{start, end}`` Unicode code point offsets into the parse markdown. example: invoice_number: ranges: - end: 31 start: 13 value: INV-042 title: Extraction Metadata type: object structure: additionalProperties: true description: >- The ``structure`` tree from the parse response the extraction was produced from. Every block in the tree carries its ``grounding`` (``{page, range, box}``) inline; block ids in the response resolve against this exact tree. title: Structure type: object required: - extraction_metadata - structure title: V2GroundRequest type: object multipart/form-data: schema: type: object properties: extraction_metadata: additionalProperties: true description: >- The ``extraction_metadata`` object returned by ``POST /v2/extract`` (or the pipeline's extract step): a tree mirroring your extraction schema whose leaves are ``{value, ranges}`` objects, where ``ranges`` are ``{start, end}`` Unicode code point offsets into the parse markdown. JSON-serialized string in form data. example: invoice_number: ranges: - end: 31 start: 13 value: INV-042 title: Extraction Metadata type: object structure: additionalProperties: true description: >- The ``structure`` tree from the parse response the extraction was produced from. Every block in the tree carries its ``grounding`` (``{page, range, box}``) inline; block ids in the response resolve against this exact tree. JSON-serialized string in form data. title: Structure type: object required: - extraction_metadata - structure responses: '200': description: v2-ground result content: application/json: schema: description: >- The Ground API response body. ``grounding`` MIRRORS the ``extraction_metadata`` tree: nested objects and arrays keep their shape, and each ``{value, ranges}`` leaf is replaced by the list of structure blocks its ranges overlap (the block-hit shape documented on the field). It is NOT a flat map — a nested schema field like ``issuer.name`` resolves to ``grounding["issuer"]["name"]``. properties: grounding: additionalProperties: true description: >- A tree mirroring ``extraction_metadata``: nested objects and arrays keep their shape, and each ``{value, ranges}`` leaf is replaced by the list of blocks its ranges overlap, in reading order. Each entry carries ``block_id`` and ``type`` identifying the matched ``structure`` block, ``parent_id`` naming the enclosing block for nested blocks (table cells), and the block's own ``grounding`` object (``{page, range, box}``) verbatim. When the block itself carries ``atomic_grounding``, the entry also lists the overlapping subset as ``{index, page, range, box}`` objects, where ``index`` is the position in the block's own ``atomic_grounding`` array; ``[]`` means the block matched but no individual entry did, and the key is omitted for blocks that carry no ``atomic_grounding``. A leaf is ``null`` when its ``ranges`` was ``null`` (a synthesised value, with no supporting passage to look up) and ``[]`` when valid ranges overlapped no block (which usually indicates a mismatched extraction/structure pair). example: invoice_number: - atomic_grounding: [] block_id: text-1 grounding: box: xmax: 0.42 xmin: 0.1 ymax: 0.15 ymin: 0.12 page: 1 range: end: 31 start: 13 type: text title: Grounding type: object metadata: $ref: '#/components/schemas/V2GroundMetadata' description: Request metadata (job_id, duration_ms, credit_usage). required: - grounding - metadata title: V2GroundResult type: object '422': description: Request validation failed. content: application/json: schema: $ref: '#/components/schemas/ErrorResponse' x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.ade.landing.ai/v2/ground' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'extraction_metadata= console.log(response.data)) .catch(error => console.error(error)); components: schemas: V2GroundMetadata: description: Response metadata for a v2 ground call. properties: job_id: description: The job ID for this request. title: Job Id type: string duration_ms: description: End-to-end request duration in milliseconds. title: Duration Ms type: integer openapi_spec: type: string description: >- URL of the OpenAPI spec covering this API, for inspection and client generation. billing: anyOf: - $ref: '#/components/schemas/V2Billing' - type: 'null' description: >- Billing summary: the service tier the request ran in and the credits charged. required: - job_id - duration_ms - openapi_spec title: V2GroundMetadata type: object ErrorResponse: type: object title: ErrorResponse required: - code - message properties: code: type: string description: >- Stable snake_case error code (e.g. ``validation_error``, ``unknown_model_version``, ``invalid_url``, ``invalid_api_key``, ``rate_limit_exceeded``). message: type: string description: Human-readable detail. V2Billing: description: |- Billing summary: the service tier the request ran in and the credits charged. properties: service_tier: anyOf: - enum: - standard - priority type: string - type: 'null' default: null description: >- The service tier the request ran in: `standard` or `priority`. A sync request reports `priority` (same lane, same price). title: Service Tier total_credits: anyOf: - type: number - type: 'null' default: null description: Credits charged for this request. title: Total Credits title: V2Billing type: object ```` # CLI Quickstart Source: https://docs.landing.ai/cli/quickstart Install the ade CLI, log in, then parse a document and extract its fields from your terminal. The ade CLI parses documents into Markdown and extracts fields you define in a schema, recording where on the page each value came from. It accepts PDFs, images, and Office documents, saves every result on your machine, and consumes no credits when you re-run an identical command. ## Install the CLI The installer downloads a self-contained binary for your platform and puts it in `~/.ade/bin`. No Python or other runtime is needed. ```bash macOS / Linux theme={null} curl -fsSL https://raw.githubusercontent.com/landing-ai/ade-cli/main/scripts/install.sh | sh ``` ```powershell Windows (PowerShell) theme={null} irm https://raw.githubusercontent.com/landing-ai/ade-cli/main/scripts/install.ps1 | iex ``` ```bat Windows (CMD) theme={null} curl -fsSL https://raw.githubusercontent.com/landing-ai/ade-cli/main/scripts/install.cmd -o install.cmd && install.cmd && del install.cmd ``` ## Log In Log in with your [ADE account](https://ade.landing.ai/). Your browser opens to authenticate, and the CLI stores the credential. For more login options, see [Authentication](./authentication). ```bash theme={null} ade login ``` ## Parse a Document Download the sample patient billing statement, then point `ade parse` at it. The run creates a folder and saves the parsed Markdown output (`parse.md`) and related files in it. To run more commands on this document, like extract or view, use the `job item` ID. Passing `--tier standard` runs the parse in the lane that consumes half the credits, at a slower turnaround. The CLI uses the `priority` tier when you omit the flag, so add `--tier standard` whenever you are not waiting on the result. See [Choose a Service Tier](./parse#choose-a-service-tier). ```bash Command theme={null} ade parse -d patient-statement-brackenmill.pdf --tier standard ``` ```text Output theme={null} parse completed · 75s Parsed /Users/you/documents/patient-statement-brackenmill.pdf -> job item 6d5d84e646381e4a run: parse-01m1cmcy2bfdzeyyfsv9206jtw model: dpt-3-pro-20260710 pages: 2 (0 failed) credits: 2.3 (standard) saved: ~/.ade/jobs/6d5d84e646381e4a/ (parse.json, parse.md, elements.json) next: ade view 6d5d84e6 --open · ade extract 6d5d84e6 --schema ``` ## Extract the Fields You Need A schema tells the extraction which fields to pull and how to recognize them. Download the sample schema, or save the block below as `schema-patient-statement.json`. To create your own later, build it visually in the [Playground](https://ade.landing.ai/) and download the JSON, or write the schema with [Extraction Schema (JSON)](/dpt3/ade-extract-schema-json). ```json schema-patient-statement.json expandable theme={null} { "description": "Root object", "type": "object", "properties": { "patient_name": { "description": "The full name of the patient receiving medical services.", "x-alternativeNames": [ "Patient Name", "Name of Patient", "Recipient Name" ], "type": "string" }, "medical_record_number": { "description": "A unique identifier assigned to the patient's medical records.", "x-alternativeNames": [ "Medical Record Number", "Patient ID", "Chart Number" ], "type": "string" }, "balance_due": { "description": "The total outstanding amount that the patient or guarantor needs to pay.", "x-alternativeNames": [ "Balance Due", "Amount Due", "Pay This Amount" ], "type": "number" } }, "required": [ "patient_name", "medical_record_number", "balance_due" ] } ``` ### Run the Extraction Run the extraction against your parse, using the job item ID from the parse output. The run saves the extracted values (`extract.json`) and a record of where each value was found (`evidence.json`) in a folder of its own. ```bash Command theme={null} ade extract 6d5d84e646381e4a --schema schema-patient-statement.json --tier standard ``` ```text Output theme={null} extract completed · 15s Extracted /Users/you/documents/patient-statement-brackenmill.pdf -> job item 13dace824c25b005 run: extract-01m1cmfk1hca1yhwsbdh8pgf3s model: extract-20260819 fields: 3 (all grounded) evidence: grounded (field->box join from stored artifacts) credits: 1.1 (standard) saved: ~/.ade/jobs/13dace824c25b005/ (extract.json, evidence.json) next: ade history list --json · ade view 13dace82 --open ``` ## See Where Every Value Came From Open the extraction in your browser. The viewer shows the extracted values beside the original pages, and selecting a field highlights the exact spot on the document it came from: ```bash Command theme={null} ade view 13dace824c25b005 --open ``` ```text Output theme={null} Viewer for job item 13dace824c25b005 (extract) -> ~/.ade/jobs/13dace824c25b005/view.html (built) sidebar: building missing sibling viewers in the background opened in browser: file:///Users/you/.ade/jobs/13dace824c25b005/view.html ``` The ade viewer in a browser, showing the parsed patient statement with its elements outlined on the left, and the extraction results, per-field metadata, and schema fields on the right. ## Common Tasks Each command below takes a job item ID, or any unambiguous prefix of one. AI agents: `ade help --json` returns this whole surface as one JSON object. | To do this | Run | Learn more | | ---------------------------------------- | ------------------------------------------------ | -------------------------------------------------- | | Parse a local file at half the credits | `ade parse -d document.pdf --tier standard` | [Parse Documents](./parse) | | Parse in the fast lane, at the full rate | `ade parse -d document.pdf --tier priority` | [Parse Documents](./parse) | | Parse only some pages | `ade parse -d document.pdf --pages 1,3-5` | [Parse Documents](./parse) | | Extract fields from a parse | `ade extract JOB_ID --schema schema.json` | [Extract Fields](./extract) | | Get the result as JSON for a script | `ade extract JOB_ID --schema schema.json --json` | [Scripting and Automation](./scripting-automation) | | See your past runs | `ade history list` | [CLI Concepts](./concepts) | | Search a parsed document | `ade find JOB_ID "term"` | [Find, Crop, and View](./find-crop-view) | | Open a document in the viewer | `ade view JOB_ID --open` | [Find, Crop, and View](./find-crop-view) | | Save an element as an image | `ade crop JOB_ID --element-id ID` | [Find, Crop, and View](./find-crop-view) | | Capture an ID for a script | `ade parse -d document.pdf --id-only` | [Scripting and Automation](./scripting-automation) | | Check which account you are using | `ade auth status` | [Authentication](./authentication) | # Authentication Source: https://docs.landing.ai/cli/authentication Log in with your browser or an API key, choose which organization your runs use, and target the US or EU. Log in once per machine and the ade CLI remembers you. Pick the path that fits where you are: * At a terminal with a browser, run `ade login`. This is the simplest path. * Without a browser, log in with an API key. * Without a terminal, such as a continuous integration (CI) pipeline or an AI agent, set the `ADE_API_KEY` environment variable. ## Log In with Your Browser Run `ade login` to open your browser and authenticate with your [ADE account](https://ade.landing.ai/). The ade CLI stores the credential and refreshes it as needed. If it reports that the session is unusable, run `ade login` again. ```bash theme={null} ade login ``` If you belong to more than one organization, the CLI asks which one to use, and runs consume credits from the organization you choose. If you belong to only one, the CLI selects it for you. To choose without answering a prompt, name the organization with `--org`. ```bash theme={null} ade login --org "Acme Research" ``` ## Log In with an API Key Use an API key when you have no browser to log in with. A key always acts in the organization it was created in, so there is nothing to choose. Create a key in your [account settings](https://ade.landing.ai/settings/api-key). Then log in. The CLI prompts you for the key, and shows no characters as you type or paste it. ```bash theme={null} ade auth login --api-key - ``` ## Run Without a Terminal In CI, cron, or an AI agent harness, authenticate with an API key. Two ways work, and they differ in whether the key is stored on the machine: * Set the `ADE_API_KEY` environment variable. The key is never written to disk, and it overrides any stored credential. Use this unless you need the key to persist. * Pipe the key into login. The CLI stores it, exactly as the prompt would. ```bash theme={null} echo "$YOUR_KEY" | ade auth login # stored ``` ## View and Change Organizations These commands apply to browser logins. To see the organizations you belong to and which one is selected, list them. The list is read live, so a change to your access shows up immediately. ```bash theme={null} ade auth org list ``` To point later runs at a different organization, switch to it by ID or name. Switching needs no browser and no new login. Clearing the selection falls back to your account's default organization. ```bash theme={null} ade auth org switch "Acme Research" ade auth org clear ``` ## Work Across Environments There is no "current environment" to switch. Every command resolves its target fresh: the `--env` flag if given, else the `ADE_ENV` variable, else `production`. To make one shell sticky, export the variable there (`export ADE_ENV=eu`) while other shells keep working against production. API keys are region-specific, so a US key does not work in the EU. The CLI stores credentials per environment for the same reason, and job items are per-environment too: a parse run in the EU never serves a production request. For more about using ADE in the EU, see [European Union (EU)](/dpt3/eu). | Environment | Endpoint | | ---------------------- | -------------------------------------- | | `production` (default) | `https://api.ade.landing.ai` | | `eu` | `https://api.ade.eu-west-1.landing.ai` | ## Check Your Authentication Status To see which environment you are targeting, which organization a browser login acts in, and where else you hold credentials: ```bash theme={null} ade auth status ``` ## Log Out By default, logging out clears the credential for the environment you are targeting. Add `--env` to name a different one, or `--all` to clear every environment at once. ```bash theme={null} ade auth logout ``` # CLI Concepts Source: https://docs.landing.ai/cli/concepts Understand job items, free re-runs, resumable jobs, and the local store the ade CLI serves results from. The ade CLI saves every parse and extract run on your machine and serves later reads from that store. Because the results are already on disk: * Re-running an identical command consumes no credits, because the CLI serves it from disk. * An interrupted job resumes instead of restarting. * Every result stays available to search, cite, and reuse. If you haven't run a command yet, the [Quickstart](./quickstart) gets you there in minutes. ## Every Run Is a Job Item Every command that sends work to the ADE API, such as `ade parse` or `ade extract`, is recorded as a **job item**: the run itself plus everything it produced, in its own folder on your machine. Each job item has a 16-character ID, and every command that reads the store accepts the ID or any unambiguous prefix of it. A job item's identity is what defines the run: the command, its parameters, the environment, and the document's path and contents. Change any of those, by editing the document, moving it, or passing different parameters, and the next run creates a new job item rather than replacing the old one. To see your job items, newest first, list your history: ```bash Command theme={null} ade history list ``` ```text Output theme={null} d6b53a431d653464 parse parsed production 2026-08-31 15:12 dpt-3-pro-latest · standard ~/documents/kyc-form.pdf ``` ## Commands Are Guarantees A **guarantee command** ensures a state instead of firing a request: running `ade parse` means "make sure this exact run exists." If it already exists, the CLI serves the result from disk with an explicit notice, makes no API call, and consumes no credits. ```bash Command theme={null} ade parse -d kyc-form.pdf --tier standard ``` ```text Output theme={null} already parsed — job item d6b53a431d653464 (completed 2026-08-31 22:12 UTC); pass --force to re-parse source: /Users/you/documents/kyc-form.pdf run: parse-01m1cy2vs6bep5k9a7naz30jfc model: dpt-3-pro-20260710 pages: 1 (0 failed) credits: 1.4 (standard) saved: ~/.ade/jobs/d6b53a431d653464/ (parse.json, parse.md, elements.json) next: ade view d6b53a43 --open · ade extract d6b53a43 --schema ``` ## Re-Run and Consume Credits Only on Purpose The `--force` flag re-runs a completed job item in place and consumes credits again. It is the only flag that makes a repeated command consume credits. Editing or moving a document changes its identity, so the next parse of it creates a new job item that consumes credits. The old item stays intact and remains true of the run it came from. ## Wait for Long Jobs Parsing a large document can take longer than you want to watch. By default, a command waits up to 600 seconds for its job to finish. Set a different budget with `--wait`, or pass `--wait 0` to submit the job and return immediately. If the wait runs out, the command exits with code `3` and the job keeps running on the server. That is a normal outcome, not an error. To pick the job back up, run the same command again: it reconnects to the running job instead of starting a new one, so credits are not consumed twice. Stopping the command with Ctrl+C also leaves the job running on the server, and re-running the same command reconnects to it. You can't cancel a job after submitting it. It finishes on the server and consumes its credits whether you wait for it or not. ## Read the Output Every command prints human-readable text by default, and reports its outcome with an exit code. Add `--json` for the whole result as one object on stdout, or `--id-only` for just the ID. For what each mode guarantees and how to branch on the exit codes, see [Scripting and Automation](./scripting-automation). ## The Local Store Everything the CLI produces lives under `~/.ade`, with each job item in its own folder. To move the store, set the `ADE_HOME` environment variable. The [CLI Reference](./reference) lists the complete layout, including the viewer and crop files the CLI builds on demand. ### Files in Every Job Item | File | What it is | | ----------- | ------------------------------------------------------------------------------------------------------------------- | | `meta.json` | The CLI's record of the run: identity, parameters, server job ID, credits, and page count. | | `job.json` | The claim ticket, written before submitting. It is why re-running resumes a pending job instead of resubmitting it. | ### Files in a Parse Item | File | What it is | | --------------- | ---------------------------------------------------------------------------------------------------------------------------------- | | `parse.json` | The raw API response, verbatim, following the [Parse response schema](/dpt3/parse-response). Ground truth, never edited. | | `parse.md` | The parse markdown as its own file: the exact string every offset points into, and the file you pipe into downstream tools. | | `elements.json` | A flat projection of the structure tree, one record per element. This is what `ade find` searches. Recomputable from `parse.json`. | ### Files in an Extract Item | File | What it is | | ---------------- | --------------------------------------------------------------------------------------- | | `extract.json` | The raw API response, verbatim. Ground truth, never edited. | | `evidence.json` | Where each extracted value was found, joined to its page locally. | | `parse/ref.json` | A reference to the parse item the extraction ran against. Parse files are never copied. | | `markdown.md` | Only when you extracted from your own Markdown: the input, copied in. | ### Spans and Ranges Stored files describe every text location as a **span**: a pair of offsets into the parse markdown, written as `[start, end)` and counted in Unicode code points. The API response calls the same thing a `range`. ### Delete Job Items To delete a job item, run `ade history clear JOB_ID`. Clearing a parse item also clears the extractions that reference it. Never delete the whole store by hand: the CLI binary lives in a subfolder of it, and the rest is your local record of completed runs. ## Update the CLI Run `ade update` to check for a newer release. For installs made with uv or pipx, the [CLI Reference](./reference) covers how updates work. ## Next Steps Choose an input, a tier, and a model, and see what a run saves. Run a schema against a parse and read the grounded result. # Parse Documents Source: https://docs.landing.ai/cli/parse Parse your own documents from the terminal: choose a local file or a URL, pick a service tier, and parse only the pages you need. Run `ade parse` to turn a document into Markdown and a structured element tree, saved on your machine. Parse is the first step in most workflows: `ade find`, `ade crop`, and `ade view` all read a completed parse. Run [Extract](./extract) on a completed parse as well: that is what grounds each extracted value to a location on the page. Extract also accepts Markdown from other sources. The CLI covers Parse and Extract, so Classify, Split, and Section stay API-only. For a worked example, see the [Quickstart](./quickstart). For the files a run saves, see [CLI Concepts](./concepts). ## Choose Your Input Parse a local file with `-d`, or a URL the server fetches with `--document-url`. Pass exactly one of them. Parse accepts PDFs, images, and Office documents, and rejects encrypted PDFs, so decrypt those first. See [File Types](/dpt3/file-types). A URL parse never gives the CLI the document bytes, so `ade view` and `ade crop` fetch a copy the first time you use them. Add `--keep-copy` to fetch it during the parse instead, which matters when a pre-signed URL may expire before then. ```bash theme={null} ade parse -d invoice.pdf --tier standard ade parse --document-url https://example.com/invoice.pdf --tier standard ade parse --document-url https://example.com/invoice.pdf --tier standard --keep-copy ``` ## Choose a Service Tier Parse and Extract use async jobs, and each submitted job sends a service tier. The `standard` tier consumes half the credits and runs in a slower lane, which suits any run where you are not waiting on the result. The `priority` tier is the fast lane and consumes credits at the full rate. The CLI uses the `priority` tier when you omit `--tier`. That differs from the API, where a job that sends no `service_tier` runs on `standard`. Pass `--tier standard` whenever you are not waiting on the result. Pass it also when you move a workload from the API to the CLI, to keep credit consumption the same. For the rates, see [Credit Consumption](/dpt3/credit-consumption). For how the two lanes differ, see [Sync vs Async](/dpt3/sync-async). Set the tier per run. Pass `priority` only when you are waiting on the result: ```bash theme={null} ade parse -d invoice.pdf --tier priority ``` ## Parse Only Some Pages Pass 1-indexed page numbers and ranges to `--pages`. Parsing fewer pages consumes fewer credits. ```bash theme={null} ade parse -d contract.pdf --pages 1,3-5 --tier standard ``` ## Send Advanced Options The `--options` flag passes a JSON object straight through to the API, for settings the dedicated flags do not cover, such as table format or inline Markdown. The server rejects unknown keys. For the full set, see [Parse Input](/dpt3/parse-input) and the [CLI Reference](./reference). ```bash theme={null} ade parse -d report.pdf --tier standard --options '{"blocks": {"table": {"format": "markdown"}}}' ``` ## Parse a Long Document A document with more pages than your per-minute `priority` limit cannot run on the `priority` tier at all, because all `priority` work shares that limit. Run it as a `standard` job instead. See [Rate Limits](/dpt3/rate-limits#run-large-documents-as-async-jobs-on-the-standard-tier). A long parse can also outlast the 600-second default wait. The job keeps running on the server, and re-running the same command reconnects to it rather than starting over. [CLI Concepts](./concepts) covers the wait budget, and [Scripting and Automation](./scripting-automation) shows how to submit now and collect later. ## Next Steps Run a schema against a parse and read the grounded result. Search a parse locally and turn matches into visual evidence. # Extract Fields Source: https://docs.landing.ai/cli/extract Pull structured fields from a parsed document with a JSON Schema, then read the values and check which ones are grounded. Run `ade extract` to pull the fields you name from a document you have already parsed. A schema defines those fields, and the result comes back shaped like the schema, with a record of where each value was found. Each extraction is its own job item, and it references the parse it ran against rather than copying it. For a worked example, see the [Quickstart](./quickstart). For the files a run saves, see [CLI Concepts](./concepts). ## Choose Your Input Extract from a completed parse, from a document path, or from Markdown you hold yourself. | Input | What happens | | ------------------- | --------------------------------------------------------------------------------------------------------------------------- | | A parse job item ID | Extracts against the stored parse. This is the most common case. | | A document path | Reuses the latest parse of that file if there is one. Otherwise it parses first. | | Your own Markdown | Extracts from a Markdown file you supply rather than a parse. With no document behind it, the result has no page locations. | ```bash theme={null} ade extract d6b53a43 --schema schema.json --tier standard # a completed parse ade extract -d invoice.pdf --schema schema.json --tier standard # a document path ade extract --markdown notes.md --schema schema.json --tier standard # your own Markdown ``` ## Write a Schema A schema is a JSON Schema object naming each field, its type, and a description the model uses to recognize it. Build one visually in the [Playground](https://ade.landing.ai/) and download the JSON, or write it by hand following [Extraction Schema (JSON)](/dpt3/ade-extract-schema-json). Pass a file path or an inline JSON object. Changing a schema changes the run, so the next extraction is a new job item that consumes credits. ```bash theme={null} ade extract d6b53a43 --schema '{"type":"object","properties":{"total":{"type":"number"}}}' --tier standard ``` ### Require Every Field By default, a field the model cannot extract is skipped, and the run reports `schema_violation_error`. Add `--strict` to make the request fail instead. For everything strict mode covers, see [Extract Input Parameters](/dpt3/extract-input). ```bash theme={null} ade extract d6b53a43 --schema schema.json --strict --tier standard ``` ## Read the Result The extracted values come back under `extraction`, shaped exactly like your schema. For the three-field schema in the [Quickstart](./quickstart), that looks like this: ```json theme={null} { "balance_due": 89.52, "medical_record_number": "MRN-100-55-3821", "patient_name": "Ada M. Rensford" } ``` ### Check Which Values Are Grounded A grounded value is one the model read from a specific place on the page. To see where a value came from, open the extraction in the viewer, which highlights the spot on the page each field was read from. [Find, Crop, and View](./find-crop-view) covers the viewer, local search, and cropping evidence images. Three signals tell you where each field stands. | Signal | What it tells you | | -------------- | ----------------------------------------------------------------------------------------------------------------------------- | | `fields` | How many leaf fields the schema asked for. | | `ungroundable` | Fields with a value the model could not tie to a location on the page. The value may still be correct, but nothing quotes it. | | `empty_fields` | Fields with no value at all, so there was nothing to ground. | ### Use the Values in a Script Add `--json` to print the whole payload, then select the `extraction` key with a JSON tool such as `jq`. ```bash theme={null} ade extract d6b53a43 --schema schema.json --tier standard --json | jq .extraction ``` ## Choose a Service Tier Parse and Extract use async jobs, and each submitted job sends a service tier. The `standard` tier consumes half the credits and runs in a slower lane, which suits any run where you are not waiting on the result. The `priority` tier is the fast lane and consumes credits at the full rate. The CLI uses the `priority` tier when you omit `--tier`. That differs from the API, where a job that sends no `service_tier` runs on `standard`. Pass `--tier standard` whenever you are not waiting on the result. Pass it also when you move a workload from the API to the CLI, to keep credit consumption the same. For the rates, see [Credit Consumption](/dpt3/credit-consumption). For how the two lanes differ, see [Sync vs Async](/dpt3/sync-async). Set the tier per run. Pass `priority` only when you are waiting on the result: ```bash theme={null} ade extract d6b53a43 --schema schema.json --tier priority ``` ## Stale Extractions An extraction points at the parse it ran against. If you later re-run that parse with `--force`, the extraction keeps its old result, and `ade history list` marks it `stale`. Re-run the extraction to update it. ## Next Steps Verify a value by searching the parse and cropping the evidence. Pipe extractions into other tools and run them unattended. # Find, Crop, and View Source: https://docs.landing.ai/cli/find-crop-view Search parsed documents locally, crop elements as evidence images, and open a viewer that highlights exact spots. After a parse, you can answer "where does the document say that?" without another API call. Three commands run on your machine and consume no credits: * `ade find`: Search everything the parse found. * `ade crop`: Save any element's region of the page as an image. * `ade view`: Open the document in your browser with every element outlined. Each command takes a job item ID, which comes from parse output or `ade history list`. If you don't have a parse yet, start with the [Quickstart](./quickstart). ## Find Elements Use `ade find` to search a parse. Give it a job item ID and a search term: ```bash Command theme={null} ade find d6b5 "Margaret" --json ``` ```json Output theme={null} [ { "job_item_id": "d6b53a431d653464", "element_id": "table-0", "type": "table", "page": 1, "box": { "xmin": 0.08888, "ymin": 0.19241, "xmax": 0.91173, "ymax": 0.28081 }, "text": "\n\n\n\n\n
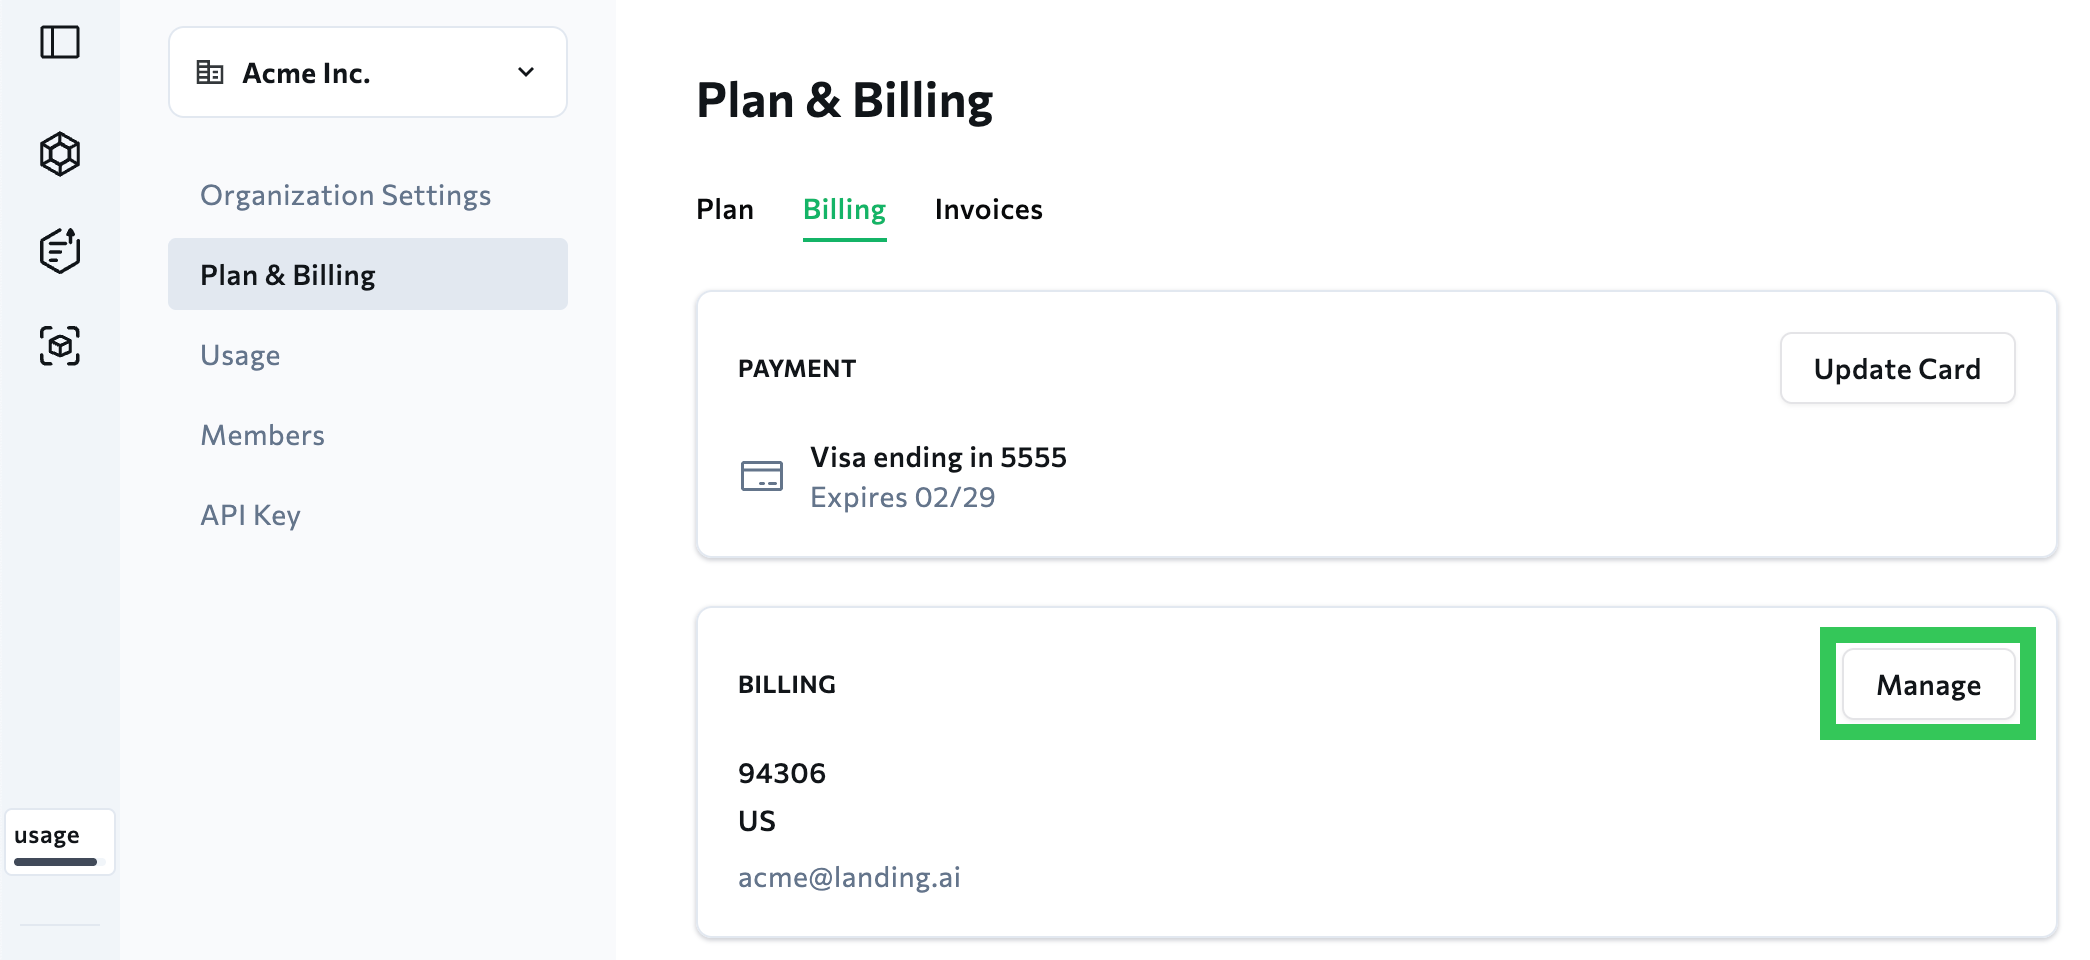
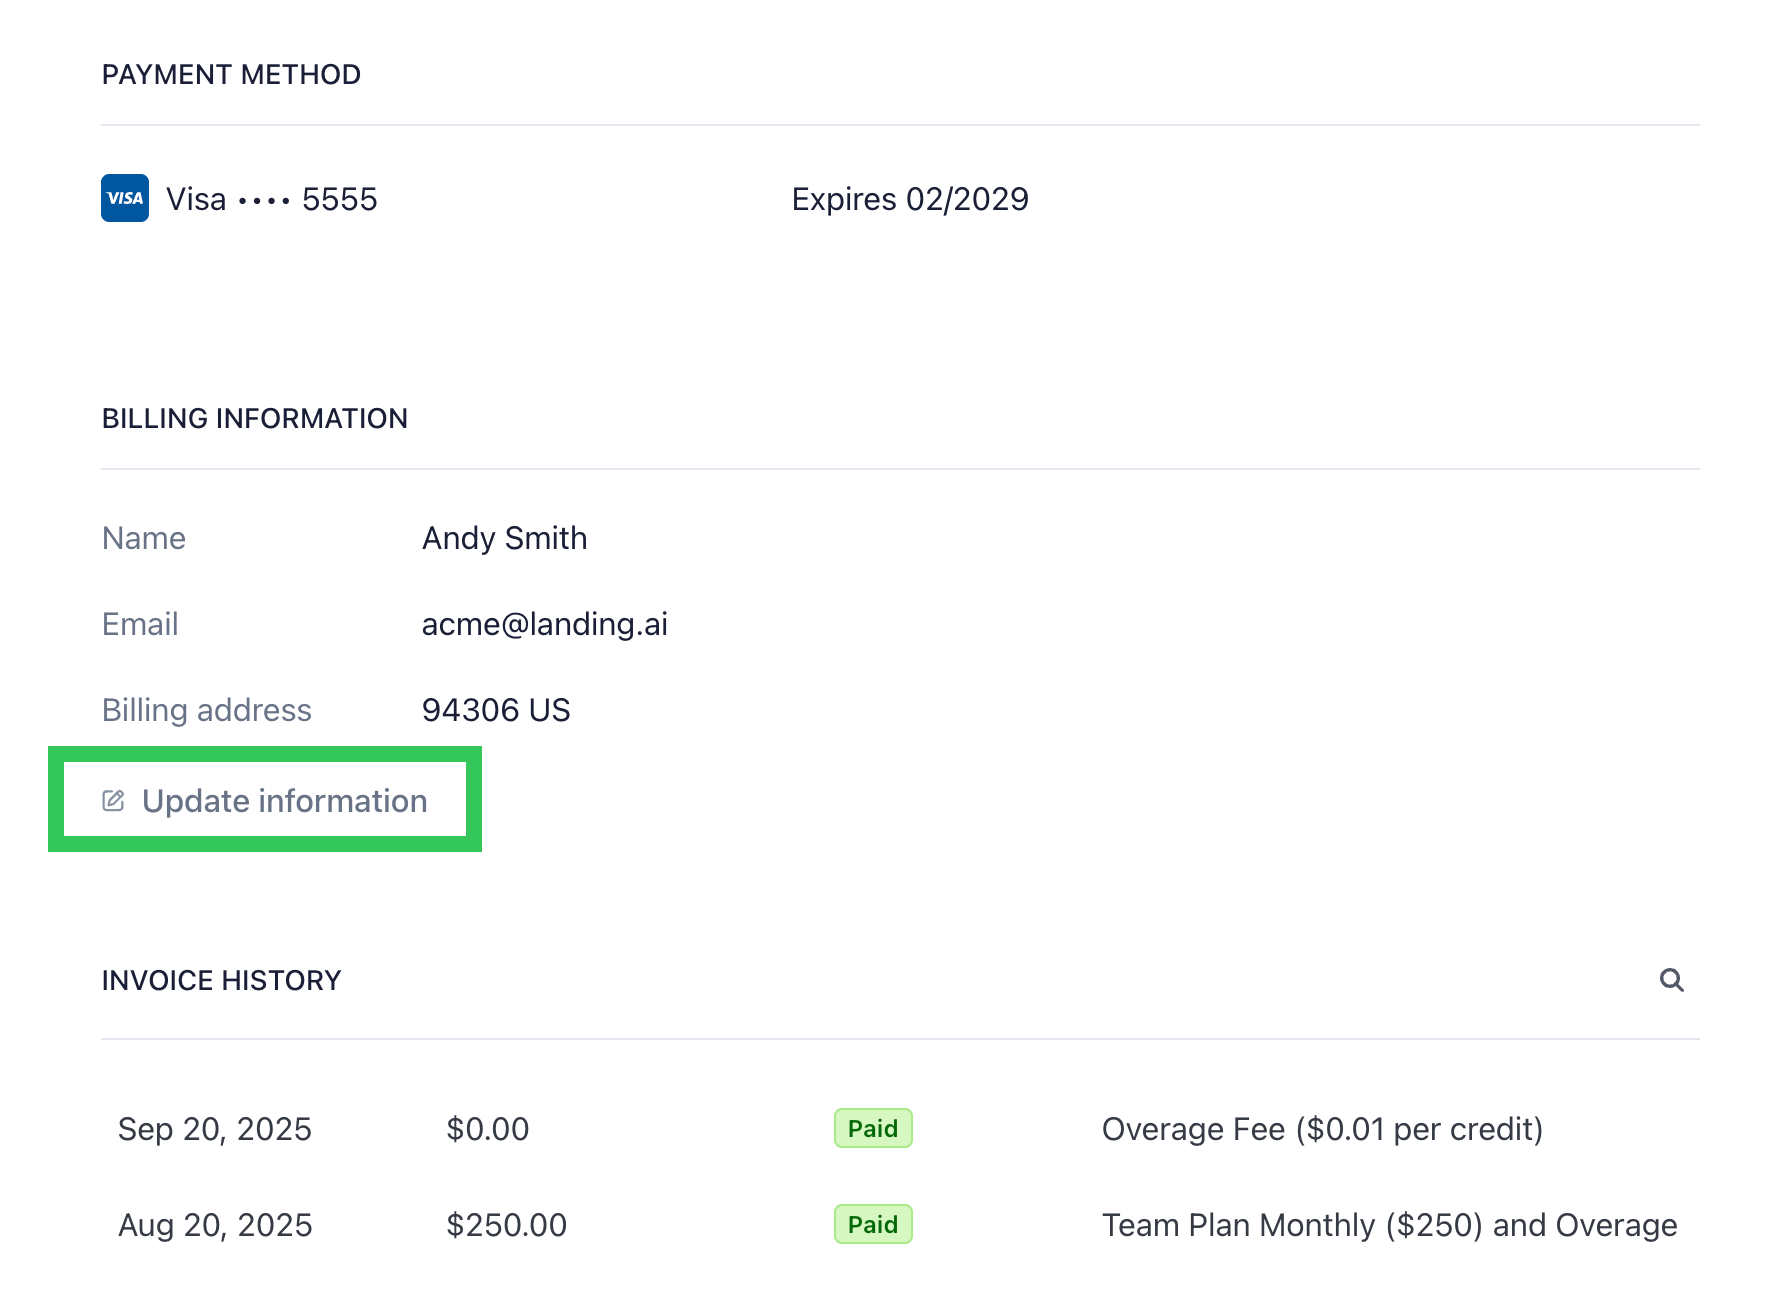
LEGAL FIRST NAMEMIDDLE NAME / INITIALLEGAL LAST NAME
MargaretL.Okonkwo
DATE OF BIRTHCOUNTRY OF CITIZENSHIPTAX IDENTIFICATION NO. (SSN/EIN)
09 / 14 / 1978United States***-**-7291
" }, { "job_item_id": "d6b53a431d653464", "element_id": "table_cell-3", "type": "table_cell", "page": 1, "box": { "xmin": 0.08898, "ymin": 0.20984, "xmax": 0.36211, "ymax": 0.2363 }, "text": "Margaret" } ] ``` ### Read a Match Each match is an **element**: one piece of the parsed document, such as a text block, a table, a single table cell, or a signature region. The API documentation calls elements blocks. A term can match at more than one level, so searching for "Margaret" matches both the table and the one cell inside it, and you can work with whichever fits your task. ### Narrow the Search The search term matches as a case-insensitive substring, and matches always come back in document order. To adjust what comes back: * Use `--regex` to treat the term as a regular expression. * Use `--type` to keep only certain element types, `--page` to keep one page, and `--limit` to cap the count. Filters combine freely. * Omit the search term to list every element. * Add `--id-only` to print just the element IDs for piping. ## Crop Elements as Images Use `ade crop` to save an element's region of the original page as a PNG image. The image is **evidence**: proof you can point at, showing exactly where in the document a value came from. Crop one element by ID, or a whole selection at once using the same filters `ade find` takes (`--type`, `--page`, `--all`). Images render at 300 dpi by default and land in the job item's `crops` folder. ```bash Command theme={null} ade crop d6b5 --element-id table_cell-3 --json ``` ```json Output theme={null} { "status": "cropped", "job_item_id": "d6b53a431d653464", "count": 1, "directory": "/Users/you/.ade/jobs/d6b53a431d653464/crops", "crops": [ { "element_id": "table_cell-3", "type": "table_cell", "page": 1, "box": { "xmin": 0.08898, "ymin": 0.20984, "xmax": 0.36211, "ymax": 0.2363 }, "dpi": 300, "path": "/Users/you/.ade/jobs/d6b53a431d653464/crops/table_cell-3@300dpi.png", "width": 697, "height": 88 } ] } ``` ## View the Document in Your Browser Use `ade view` to see the parse laid over the original document. The command builds one HTML file: the document's pages with every element outlined, next to the parsed markdown. Select an element on either side and the other side highlights to match. Pass `--open` to open the file in your browser, or click the link the command prints. To return to the exact spot a value came from, pass `--element-id`. The output includes a `deep_link` URL that opens the viewer on this machine with that element already highlighted. To show someone else, send them the `view.html` file itself: it is self-contained, and the same `#element=` ending works on their copy. The viewer builds once and rebuilds only when the parse changes, which is why this example reports `"built": false` for an unchanged job item. ```bash Command theme={null} ade view d6b5 --element-id table_cell-3 --json ``` ```json Output theme={null} { "status": "viewed", "job_item_id": "d6b53a431d653464", "kind": "parse", "path": "/Users/you/.ade/jobs/d6b53a431d653464/view.html", "built": false, "pages_embedded": null, "note": null, "url": null, "serve_error": null, "deep_link": "file:///Users/you/.ade/jobs/d6b53a431d653464/view.html#element=table_cell-3", "history_items": 10, "sidebar_sync": false } ``` ## Next Steps Pipe find results, batch crops, and run the CLI from agents and pipelines. Every flag these commands take, with their payload keys. # Scripting and Automation Source: https://docs.landing.ai/cli/scripting-automation Script the ade CLI with stable JSON output, pipeable IDs, and exit codes, and run it unattended in CI and cron. Every ade CLI command prints a result a script can parse, returns an exit code that says what to do next, and is safe to re-run. So you can: * Pipe IDs and results straight into other tools (`--id-only`, `--json`). * Submit long jobs now and collect them later (`--wait 0`). * Batch whole folders, and re-run after a crash: finished work is served from disk. ## Capture an ID for Piping The `--id-only` flag prints just the job item ID, one per line. Errors go to stderr, so a captured ID is never an error sentence: ```bash Command theme={null} ade parse -d patient-statement-brackenmill.pdf --tier standard --id-only ``` ```text Output theme={null} 6d5d84e646381e4a ``` Assign it directly in a script, then feed it to any command that takes an ID: ```bash theme={null} JOB=$(ade parse -d patient-statement-brackenmill.pdf --tier standard --id-only) ade extract "$JOB" --schema schema-patient-statement.json --tier standard --json ``` ## Pipe Results to Other Tools With `--json`, the whole result is on stdout as one object or array, so a script never reads files out of the store. Failures and unfinished jobs use the same shape, so one parser handles every outcome. The large artifacts stay on disk unless you carry them along with `--include`. Here the parse markdown flows straight into another tool: ```bash Command theme={null} ade parse -d patient-statement-brackenmill.pdf --tier standard --json --include markdown | jq -r .markdown | head -4 ``` ```text Output theme={null} [Pulse symbol inside rounded square] Brackenmill Family Health ``` ## Branch on Exit Codes Exit codes separate "wrong" from "not yet." Codes `3` (wait expired, job still running) and `4` (rate-limited, nothing consumed) both mean the same recovery: run the same command again. The [CLI Reference](./reference) lists every code. ```bash theme={null} ade parse -d "$FILE" --tier standard --json case $? in 0) echo "done" ;; 3|4) echo "not finished; re-run this script to resume" ;; *) echo "failed" >&2; exit 1 ;; esac ``` ## Submit Now, Collect Later Pass `--wait 0` to submit a job and return immediately with exit code `3`. Collect the result whenever you like by re-running the same command: it reconnects to the recorded job and never consumes credits twice. ```bash theme={null} ade parse -d big-document.pdf --tier standard --wait 0 --id-only ade parse -d big-document.pdf --tier standard --json ``` ## Process a Folder of Documents Free re-runs make batch jobs resumable. If this loop dies halfway, run it again, and only the unfinished documents do real work. ```bash theme={null} for f in *.pdf; do ade parse -d "$f" --tier standard --id-only done ``` ## Run Unattended In an unattended environment, such as a continuous integration (CI) pipeline, a cron job, or an AI agent harness, set the `ADE_API_KEY` environment variable for credentials. [Authentication](./authentication) covers the options. Non-interactive shells source no profile, so the `ade` command your login shell finds may not be on the job's PATH. Call the binary by its absolute path, or add it to PATH inside the job: ```bash theme={null} ade parse -d "$FILE" --tier standard --json ``` ## Next Steps Every command, flag, and payload key these patterns build on. Why re-runs are free: job items, guarantees, and the local store. # CLI Reference Source: https://docs.landing.ai/cli/reference See every ade CLI command with its flags, result shapes, and exit states. This reference documents every command in the [ade CLI](https://github.com/landing-ai/ade-cli). For the same reference in your terminal, run `ade help`. New to the CLI? Start with the [Quickstart](./quickstart). Commands are listed by group, each with its flags and its `--json` result keys. Behavior that applies across commands (output modes, exit codes, the local store) is covered in [CLI Concepts](./concepts). AI agents: run `ade help --json` to get this entire surface as a single JSON object. ## Credentials and CLI Lifecycle ### `ade auth login` ```text theme={null} ade auth login [options] [--json] ``` Ensure the target environment is logged in; `--api-key` authenticates with a key directly ('-' prompts with hidden input). Targets `--env`, else \$ADE\_ENV, else production - nothing is stored about the choice. | Flag | Value | Default | Description | | ----------- | ------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------- | | `--api-key` | `TEXT` | | Log in with this API key directly ('-' prompts with hidden input). | | `--org` | `TEXT` | | Act in this Logto organization (id or name). Browser (OAuth) logins only - API keys are already organization-bound. | | `--env` | `TEXT` | | Environment to target: dev, staging, production, eu (default: \$ADE\_ENV, then production). Credentials are stored per environment. | With `--json`, the command prints an object with these keys: | Key | Description | | ----------------------- | --------------------------------------------------------------------------------------------- | | `method` | api\_key \| oauth | | `credential` | masked credential - never the secret | | `stored` | true once written to credentials.json | | `already_authenticated` | present when the target needed nothing | | `environment` | the resolved target | | `endpoint` | its endpoint | | `endpoint_source` | default \| config \| env | | `identity` | OAuth logins: the token's identity claims | | `organization` | OAuth logins: the selected organization (\{id, name}; null when the platform default applies) | ### `ade auth status` ```text theme={null} ade auth status [options] [--json] ``` Show the resolved target's auth method, identity, and expiry, plus every other environment holding a credential. | Flag | Value | Default | Description | | ------- | ------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------- | | `--env` | `TEXT` | | Environment to target: dev, staging, production, eu (default: \$ADE\_ENV, then production). Credentials are stored per environment. | With `--json`, the command prints an object with these keys: | Key | Description | | ---------------------------------------------------------------- | ------------------------------------------------ | | `authenticated` | false (exit 1) when the target has no credential | | `method` | api\_key \| oauth | | `credential` | masked credential | | `source` | env (ADE\_API\_KEY) \| stored | | `environment / endpoint / endpoint_source` | the resolved target | | `other_environments` | every other environment holding a credential | | `expires_at / expires_in_seconds / refresh_token / organization` | OAuth only | ### `ade auth logout` ```text theme={null} ade auth logout [options] [--json] ``` Log out of one environment (the resolved target by default); `--all` clears every environment. Idempotent; OAuth refresh tokens are revoked best-effort first. | Flag | Value | Default | Description | | ------- | ------ | ------- | ------------------------------------------------------------------------------------------------- | | `--env` | `TEXT` | | Log out of this environment: dev, staging, production, eu (default: \$ADE\_ENV, then production). | | `--all` | | | Log out of every environment at once. | With `--json`, the command prints an object with these keys: | Key | Description | | ------------- | -------------------------------------------- | | `logged_out` | always true - logout is idempotent | | `cleared` | false when there was nothing stored to clear | | `revoked` | refresh tokens revoked best-effort | | `scope` | environment \| all | | `environment` | the environment cleared (null with `--all`) | ### `ade auth org list` ```text theme={null} ade auth org list [options] [--json] ``` List the organizations the target's OAuth session can act in, marking the selected one. Memberships come live from the login provider, so a fresh grant or removal shows immediately - including a selection that is no longer a membership. | Flag | Value | Default | Description | | ------- | ------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------- | | `--env` | `TEXT` | | Environment to target: dev, staging, production, eu (default: \$ADE\_ENV, then production). Credentials are stored per environment. | With `--json`, the command prints an object with these keys: | Key | Description | | ------------------- | ------------------------------------------------------------------------------------------------------------------------------------ | | `organizations` | your memberships, live from the login provider: \[\{id, name, selected}] | | `selected` | the selected organization id (null when the platform default applies) | | `selected_is_stale` | true when the selection is no longer one of your memberships - requests still send it and the platform rejects them; switch or clear | | `environment` | the resolved target | ### `ade auth org switch` ```text theme={null} ade auth org switch ORG [options] [--json] ``` Switch which organization the target's OAuth session acts in. Validated against your live memberships here, and membership-verified by the platform on every request regardless. | Argument | Description | | -------- | ---------------------------------- | | `ORG` | Required. Organization id or name. | | Flag | Value | Default | Description | | ------- | ------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------- | | `--env` | `TEXT` | | Environment to target: dev, staging, production, eu (default: \$ADE\_ENV, then production). Credentials are stored per environment. | With `--json`, the command prints an object with these keys: | Key | Description | | -------------- | ---------------------------------------- | | `organization` | the selection now stored (\{id, name}) | | `previous` | the selection it replaced (null if none) | | `stored` | always true on success | | `environment` | the resolved target | ### `ade auth org clear` ```text theme={null} ade auth org clear [options] [--json] ``` Drop the target's organization selection, falling back to the platform default. Idempotent, and deliberately offline: this is the way out when a selection has outlived its membership, which is exactly when listing memberships may not work. | Flag | Value | Default | Description | | ------- | ------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------- | | `--env` | `TEXT` | | Environment to target: dev, staging, production, eu (default: \$ADE\_ENV, then production). Credentials are stored per environment. | With `--json`, the command prints an object with these keys: | Key | Description | | -------------- | ---------------------------------------------- | | `organization` | always null - the platform default now applies | | `previous` | the selection that was dropped (null if none) | | `cleared` | false when there was nothing selected | | `environment` | the resolved target | ### `ade login` ```text theme={null} ade login [options] [--json] ``` Alias of `ade auth login`: ensure the target environment is logged in; `--api-key` authenticates with a key directly ('-' prompts with hidden input). | Flag | Value | Default | Description | | ----------- | ------ | ------- | ----------------------------------------------------------------------------------------------------------------------------------- | | `--api-key` | `TEXT` | | Log in with this API key directly ('-' prompts with hidden input). | | `--org` | `TEXT` | | Act in this Logto organization (id or name). Browser (OAuth) logins only - API keys are already organization-bound. | | `--env` | `TEXT` | | Environment to target: dev, staging, production, eu (default: \$ADE\_ENV, then production). Credentials are stored per environment. | With `--json`, the command prints an object with these keys: | Key | Description | | ----------------------- | --------------------------------------------------------------------------------------------- | | `method` | api\_key \| oauth | | `credential` | masked credential - never the secret | | `stored` | true once written to credentials.json | | `already_authenticated` | present when the target needed nothing | | `environment` | the resolved target | | `endpoint` | its endpoint | | `endpoint_source` | default \| config \| env | | `identity` | OAuth logins: the token's identity claims | | `organization` | OAuth logins: the selected organization (\{id, name}; null when the platform default applies) | ### `ade logout` ```text theme={null} ade logout [options] [--json] ``` Alias of `ade auth logout`: log out of one environment (the resolved target by default); `--all` clears every environment. | Flag | Value | Default | Description | | ------- | ------ | ------- | ------------------------------------------------------------------------------------------------- | | `--env` | `TEXT` | | Log out of this environment: dev, staging, production, eu (default: \$ADE\_ENV, then production). | | `--all` | | | Log out of every environment at once. | With `--json`, the command prints an object with these keys: | Key | Description | | ------------- | -------------------------------------------- | | `logged_out` | always true - logout is idempotent | | `cleared` | false when there was nothing stored to clear | | `revoked` | refresh tokens revoked best-effort | | `scope` | environment \| all | | `environment` | the environment cleared (null with `--all`) | ### `ade version` ```text theme={null} ade version [--json] ``` Print the ade version and install mode: 'binary' (the standalone app - `ade update` replaces it in place) or 'python' (uv/pipx - upgrade with `uv tool upgrade ade-cli`). With `--json`, the command prints an object with these keys: | Key | Description | | --------- | ---------------------------------------------------------------------------------------------------------------------------------------- | | `version` | the installed ade version | | `install` | how it is installed: binary (standalone app, self-updates via `ade update`) \| python (uv/pipx - upgrade with `uv tool upgrade ade-cli`) | ### `ade update` ```text theme={null} ade update [options] [--json] ``` Check the release channel for a newer CLI and self-update on confirmation. A standalone-binary install (see `ade version`) replaces itself in place after verifying the release checksum; a uv/pipx install is never mutated - the command reports the newer version and points at `uv tool upgrade ade-cli`. | Flag | Value | Default | Description | | ------- | ----- | ------- | ------------------------------------------------------------------------------------- | | `--yes` | | | Install without the interactive confirmation (required when stdin is not a terminal). | With `--json`, the command prints an object with these keys: | Key | Description | | --------- | ----------------------------------------------------------------------------------------------- | | `current` | the running version | | `latest` | the latest released version (null when the release channel is not visible) | | `updated` | true when this run installed the newer version | | `install` | binary \| python - python installs are never mutated, only pointed at `uv tool upgrade ade-cli` | ### `ade help` ```text theme={null} ade help [COMMAND|TOPIC]... [--json] ``` Print the whole-surface command reference in one call: every command and flag, the output convention, each verb's result shape, exit states, and the store layout. The agent bootstrap - run this (with `--json`) before anything else. `help TOPIC` prints one conceptual page instead (workflow, output, credentials, errors). | Argument | Description | | --------------------- | ----------------------------------------------------------------------------------------------------------------------------------------- | | `[COMMAND\|TOPIC]...` | Scope the reference to one command or group (`help extract`, `help auth login`), or print a topic: workflow, output, credentials, errors. | With `--json`, the command prints an object with these keys: | Key | Description | | ----------------------------- | ---------------------------------------------------- | | `cli / version / description` | what this binary is | | `conventions` | the rules every command follows | | `commands` | every command: usage, arguments, flags, result shape | | `topics` | the conceptual pages (`ade help workflow`) | | `exit_states` | every exit code and what it means | | `store` | the on-disk layout | ## Network Verbs: The ADE Job Contracts ### `ade parse` ```text theme={null} ade parse [options] [--json] ``` Ensure a document is parsed; persist all artifacts locally. The summary names the job item id every other verb takes: `find` it, `view` it, `extract` against it. The raw result stored in `parse.json` follows the [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse) response schema. | Flag | Value | Default | Description | | ---------------- | -------------------- | ------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `-d, --document` | `FILE` | | Local document file to parse; pass exactly one of -d/`--document` or `--document-url`. | | `--document-url` | `TEXT` | | Document URL the server fetches (identity is the URL x params; a re-run dedups even if the remote content changed - `--force` refreshes). | | `--model` | `TEXT` | `dpt-3-pro-latest` | Parse model registry version. | | `--tier` | `priority\|standard` | `priority` | Async lane: priority (full price, fast lane) or standard (half price, slower lane). The CLI defaults to priority. | | `--pages` | `TEXT` | | 1-indexed, e.g. '1,3-5'. | | `--options` | `TEXT` | | Full ParseOptions pass-through as a JSON object, sent verbatim (the server rejects unknown keys with a 422). Keys as of this release - pages: 1-indexed integer array (default: all pages); atomic\_grounding: bool (default true; false omits the per-line atomic\_grounding field from every node); inline\_markdown: bool (default false; true adds each node's own markdown slice inline); blocks.\.markdown: bool (default true; false suppresses that type's markdown; types: text, table, figure, marginalia, attestation, logo, scan\_code, card); blocks.table.format: 'html' (default) or 'markdown'; password: always rejected (422) - decrypt PDFs before upload. Example: '\{"inline\_markdown": true, "blocks": \{"table": \{"format": "markdown"}}}'. Merges with `--pages`; giving pages in both is an error. | | `--env` | `TEXT` | | Environment to run against: dev, staging, production, eu (default: \$ADE\_ENV, then production). Environments keep separate results - the job item id includes the environment. | | `--wait` | `FLOAT` | `600.0` | Poll budget in seconds. | | `--force` | | | Re-parse even if already parsed, or abandon an unreadable job for a fresh one (bills a new parse). | | `--keep-copy` | | | `--document-url` only: also download the document into the job item (plain HTTP, no API credits) so page previews and crops render locally - fetched now, while the URL (often pre-signed) still works. Without it, the first `view`/`crop` fetches the copy instead, by which time a pre-signed URL may have expired. | | `--include` | `markdown\|elements` | | Carry a bulk artifact in the payload instead of leaving it on disk: markdown (the parse markdown) or elements (the flat projection `find` searches). Repeatable. | | `--id-only` | | | Print only the id(s) this run produced, one per line - the piping mode (JOB=\$(ade parse -d f.pdf `--id-only`)). Takes precedence over `--json`; errors and hints go to stderr. | With `--json`, the command prints an object with these keys: | Key | Description | | ----------------- | --------------------------------------------------------------------------------------- | | `status` | 'parsed' | | `run_id` | server-side run id (the wire's job\_id) | | `job_item_id` | store key every other verb takes | | `environment` | resolved environment | | `version` | resolved parse model version | | `credits` | credits billed (0 on a cached hit) | | `tier` | service tier the run was billed at | | `page_count` | pages parsed | | `failed_pages` | 1-indexed pages the server could not parse | | `cached` | true when served free from the store | | `stored` | false when the result could not be persisted | | `store_dir` | absolute path of the job item folder | | `artifacts` | artifact filenames written there | | `markdown` | the parse markdown - only with `--include` markdown | | `elements` | the flat projection - only with `--include` elements | | `kept_copy` | with `--keep-copy`: whether the URL document's copy was stored in the job item | | `keep_copy_error` | with `--keep-copy`: why the copy could not be stored (the parse itself still succeeded) | ### `ade extract` ```text theme={null} ade extract [JOB_ITEM_ID] --schema TEXT [options] [--json] ``` Ensure an extraction exists for a parse job item (or bring-your-own markdown); persist the result as its own job item. The schema-shaped result rides in the payload (`extraction`) with its per-field evidence; `view JOB_ITEM_ID` renders the same join on the page, and `find`/`crop` on the referenced parse reach the cited elements. The raw result stored in `extract.json` follows the [Extract API](https://docs.landing.ai/api-reference/extract/ade-extract) response schema. | Argument | Description | | --------------- | ------------------------------------------------------ | | `[JOB_ITEM_ID]` | A completed parse job item id (or unambiguous prefix). | | Flag | Value | Default | Description | | ---------------- | -------------------- | ---------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `--schema` | `TEXT` | | Required. JSON Schema file or inline JSON object. | | `-d, --document` | `FILE` | | Extract by document path: reuse the latest completed parse of this path+content, else run a standalone parse job first - as if you had run `parse -d` - then extract (two billable jobs, both itemised). | | `--markdown` | `FILE` | | Escape hatch: extract from markdown that did not come from parse. | | `--markdown-url` | `TEXT` | | Escape hatch: extract from markdown fetched from a URL server-side (the response's echoed markdown is stored). | | `--model` | `TEXT` | `extract-latest` | Extract model registry version. | | `--tier` | `priority\|standard` | `priority` | Async lane: priority (full price, fast lane) or standard (half price, slower lane). The CLI defaults to priority. | | `--strict` | | | v2 ExtractOptions pass-through: the server rejects (422) schemas with fields the model cannot extract instead of skipping them. | | `--env` | `TEXT` | | Environment to run against: dev, staging, production, eu (default: \$ADE\_ENV, then production). The JOB\_ITEM\_ID form inherits the parse item's environment instead - its server-side parse job only exists there - and a conflicting `--env` is refused. | | `--wait` | `FLOAT` | `600.0` | Poll budget in seconds. | | `--force` | | | Re-extract even if already extracted, or abandon an unreadable job for a fresh one (bills a new extract). | | `--id-only` | | | Print only the id(s) this run produced, one per line - the piping mode (JOB=\$(ade parse -d f.pdf `--id-only`)). Takes precedence over `--json`; errors and hints go to stderr. | With `--json`, the command prints an object with these keys: | Key | Description | | ------------------------ | -------------------------------------------------------------------------------------------- | | `status` | 'extracted' | | `run_id` | server-side run id (the wire's job\_id) | | `job_item_id` | this extraction's own job item | | `parse_job_item_id` | the parse it references (absent for markdown) | | `environment` | resolved environment | | `version` | resolved extract model version | | `credits` | credits billed (0 on a cached hit) | | `tier` | service tier the run was billed at | | `extraction` | THE RESULT: the schema-shaped object, verbatim | | `fields` | number of leaf fields | | `ungroundable` | field paths whose non-empty value has no box | | `empty_fields` | field paths with no value (nothing to ground) | | `schema_violation_error` | set when the extraction is partial (strict=false skipped schema fields); null on a clean run | | `warnings` | server warnings, verbatim (\[] when none) | | `evidence` | \{kind, reason?, fields\[]} - the field→box join | | `cached` | true when served free from the store | | `stored` | false when the result could not be persisted | | `store_dir` | absolute path of the job item folder | | `artifacts` | artifact filenames written there | | `reused_parse` | the parse reused, when one was (no parse billed) | | `parsed_first` | the standalone parse run first, when one was | ## Local Read Models ### `ade history list` ```text theme={null} ade history list [options] [--json] ``` List stored job items: id, kind, state, env, params, source - the newest 100 submissions first (`--limit`/`--all` adjust, `--asc` for oldest first). Extract items referencing a parse item indent beneath it. Bare `ade history` defaults to this command. | Flag | Value | Default | Description | | --------- | --------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------- | | `--asc` | | | Oldest submission first (the pre-1.0.3 order). The listing defaults to newest first - the run you just did leads, matching the viewer sidebar. | | `--limit` | `INTEGER` | `100` | Keep only the newest N items (default 100), whatever the order; `--all` lifts the cap. | | `--all` | | | List every stored job item - no limit. | With `--json`, the command prints an array of objects with these keys: | Key | Description | | --------------------------- | ----------------------------------------------------------------------------------------------------------------- | | `job_item_id` | the item | | `kind` | parse \| extract | | `state` | derived from the ticket and artifacts on disk | | `run_id` | server-side run id of the recorded generation | | `source` | document path, URL, or markdown file | | `params` | the invocation params, verbatim | | `parse` | extract items: the referenced parse - \{job\_item\_id, run\_id (the parse generation extracted against), missing} | | `stale` | extract items: true when the referenced parse was `--force` re-run after this extraction | | `created_at / completed_at` | epoch seconds (null when unknown) | ### `ade history clear` ```text theme={null} ade history clear [JOB_ITEM_ID] [options] [--json] ``` Delete stored job items. Clearing a parse item cascades - with notice - to the extract items referencing it, so the store never holds dangling refs. | Argument | Description | | --------------- | ---------------------------------- | | `[JOB_ITEM_ID]` | Job item id or unambiguous prefix. | | Flag | Value | Default | Description | | ------- | ----- | ------- | ----------------------------- | | `--all` | | | Delete every stored job item. | With `--json`, the command prints an object with these keys: | Key | Description | | ---------- | ---------------------------------------------------- | | `cleared` | job item ids removed | | `cascaded` | extract items removed with the parse they referenced | ### `ade find` ```text theme={null} ade find [JOB_ITEM_ID] [QUERY] [options] [--json] ``` Search parsed elements locally: `find JOB_ITEM_ID [QUERY]`, or `--job` (repeatable) for several items; no query lists every element. Ids discovered here are what `view --element-id` deep-links and `crop --element-id` renders - though `crop` takes these same filters directly (`crop JOB_ITEM_ID --type figure`) when you want the images rather than the records. | Argument | Description | | ----------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------- | | `[JOB_ITEM_ID] [QUERY]` | Job item id (or unambiguous prefix) to search, then an optional case-insensitive substring QUERY. With `--job`, the one allowed positional is the QUERY. | | Flag | Value | Default | Description | | -------------- | --------- | ------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `--job` | `TEXT` | | Parse job item to search (id or unambiguous prefix); repeatable for multi-item search. Equivalent to the positional JOB\_ITEM\_ID for a single item. | | `--regex` | | | Treat QUERY as a regular expression (case-insensitive; scope with (?-i:...)). | | `--type` | `TEXT` | | Element type (text, table, table\_cell, figure, ...). | | `--page` | `INTEGER` | | 1-indexed page number. | | `--element-id` | `TEXT` | | Exact element id to match; repeatable. | | `--limit` | `INTEGER` | | Return at most this many matches. | | `--id-only` | | | Print only the id(s) this run produced, one per line - the piping mode (JOB=\$(ade parse -d f.pdf `--id-only`)). Takes precedence over `--json`; errors and hints go to stderr. | With `--json`, the command prints an array of objects with these keys: | Key | Description | | ------------- | ---------------------------------------------------- | | `job_item_id` | the parse item the match came from | | `element_id` | element id - what crop and view take | | `type` | element type (text, table, table\_cell, figure, ...) | | `page` | 1-indexed page | | `box` | \{xmin, ymin, xmax, ymax} fractions of page size | | `text` | the element's markdown slice | ### `ade view` ```text theme={null} ade view [JOB_ITEM_ID] [options] [--json] ``` Build a job item's self-contained grounded HTML viewer. | Argument | Description | | ------------- | -------------------------------------------------------------------------- | | `JOB_ITEM_ID` | Job item id or unambiguous prefix (default: the latest viewable job item). | | Flag | Value | Default | Description | | --------------------------- | --------- | ------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `--element-id` | `TEXT` | | Emit a deep link to this element. | | `--crop` | | | With `--element-id`: render that element's PNG crop instead of the HTML artifact. | | `--open, --no-open` | | | Open the result in the browser. Default: open when stdout is a terminal; `--json` runs and piped output never auto-open. | | `--dpi` | `INTEGER` | | Page render dpi (default 120); with `--crop`, the crop dpi (default 300). | | `--pages` | `TEXT` | | Pages to embed images for, 1-indexed, e.g. '1,3-5'. | | `--download, --no-download` | | | URL-parsed items: fetch the document from its recorded URL into the job item and render page previews from that copy - the parse itself never gives the CLI the bytes (#169). This happens automatically when no copy is attached yet (a notice and progress line land on stderr); `--no-download` skips the fetch and previews stay empty. Explicit `--download` makes a failed fetch an error instead of a warning. Plain HTTP, no API credits; the copy is unverified against the parsed run. Also works on an extract item id (fetches into its referenced parse item). | | `--no-sidebar-sync` | | | Skip the background build of missing sibling viewers. | | `--serve` | | | Open via a local server ([http://127.0.0.1](http://127.0.0.1)) instead of file:// - browser zoom then covers every viewer natively. Starts the server if needed; reuses a running one. It retires itself after 30 idle minutes, or immediately with `--stop-server`. | | `--stop-server` | | | Stop the local viewer server (started by `--serve`) and exit. | With `--json`, the command prints an object with these keys: | Key | Description | | ---------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `status` | 'viewed' ('cropped' with `--crop`, 'synced' with `--sync-viewers`) | | `job_item_id` | the item rendered | | `kind` | parse \| extract | | `path` | the self-contained view\.html (or the PNG, with `--crop`) | | `built` | true when this run rebuilt the artifact | | `pages_embedded` | pages inlined; the rest load from sidecars | | `note` | why the render weakened, when it did (else null) | | `downloaded` | URL items: true when this run fetched the document into the job item (automatic on first view). false when the automatic fetch failed (see download\_error) or explicit `--download` found the copy already attached; absent when nothing needed fetching | | `download_error` | why the automatic fetch failed, when it did (the viewer still builds, previews empty; else absent) | | `deep_link` | view\.html#element=... when `--element-id` was given | | `history_items` | items in the rebuilt sidebar read model | | `sidebar_sync` | true when sibling viewers build in the background | ### `ade crop` ```text theme={null} ade crop [JOB_ITEM_ID] [options] [--json] ``` Crop element regions from the source document into PNGs: one `--element-id`, or a filtered batch (`--type figure`, `--page`, `--all`) with the same filters `ade find` searches by. | Argument | Description | | --------------- | ---------------------------------- | | `[JOB_ITEM_ID]` | Job item id or unambiguous prefix. | | Flag | Value | Default | Description | | --------------------------- | --------- | ------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `--element-id` | `TEXT` | | Element to crop (ids from `ade find`); repeatable. | | `--type` | `TEXT` | | Crop every element of this type (text, table, figure, ...) - `find`'s filter, applied here. | | `--page` | `INTEGER` | | Restrict the selection to this 1-indexed page. | | `--all` | | | Crop every element the filters select (on its own: the whole item). | | `-o, --output` | `PATH` | | Where the crops land: a directory (a single crop lands inside it too), or - for a single crop only - the PNG path itself (default: the job item's crops/ dir). | | `--dpi` | `INTEGER` | `300` | Render dpi. | | `--open` | | | Open the crop (or the directory holding them). | | `--download, --no-download` | | | URL-parsed items: fetch the document from its recorded URL into the job item and crop from that copy - the parse itself never gives the CLI the bytes (#169). This happens automatically when no copy is attached yet (a notice and progress line land on stderr); `--no-download` skips the fetch, and the crop then fails honestly (a crop has no empty-imagery fallback). | With `--json`, the command prints an object with these keys: | Key | Description | | ------------- | ---------------------------------------------------------------------------------------------------------------------------- | | `status` | 'cropped' | | `job_item_id` | the addressed item (crops land under its crops/) | | `count` | how many PNGs were written | | `directory` | where they landed | | `crops` | one record per PNG (element\_id, type, page, box, dpi, path, width, height) | | `downloaded` | URL items: true when this run fetched the document into the parse item before cropping (absent when nothing needed fetching) | ## Exit States Every command exits with one of these codes. See [Scripting and Automation](./scripting-automation) for how to use them in scripts. | Code | State | Meaning | | ---- | -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `0` | `ok` | Success - the command's payload is on stdout. | | `1` | `failed` | The run failed or the target cannot serve the request (job failure, unknown id, missing parse, unreadable result). | | `2` | `usage` | The invocation itself was wrong; nothing was submitted. | | `3` | `pending` | The wait budget expired while the run continues server-side - a normal outcome, not an error. The payload carries a 'pending' status plus the run\_id and job\_item\_id; re-run the same command to resume polling (never resubmits, never re-bills). | | `4` | `rate_limited` | Submit was rate-limited and the wait budget ran out before a job existed; nothing was submitted, nothing bills. Re-run to retry. | ## Store Layout The local store lives at \~/.ade (ADE\_HOME overrides). | Path | Contents | | ----------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `~/.ade/config.json` | endpoint + named-environment config | | `~/.ade/credentials.json` | per-environment credentials (mode 0600; written by `auth login`) | | `~/.ade/history.js` | sidebar read model over jobs/, rewritten from a fresh store scan by every view/history run | | `~/.ade/jobs//` | one folder per run - parse and extract alike, all top-level siblings (flat, never nested) | | ` meta.json` | commit record: kind, source, identity, params, state, timestamps, artifact index. Its job\_id field is the server-side run id (= run\_id in `--json` payloads), never the job item id | | ` job.json` | claim ticket: the server-side run id (spelled job\_id on disk), tier, state - what a re-run resumes | | ` parse.json / parse.md / elements.json` | parse items: the raw ParseResponse verbatim, its markdown, and the flat elements projection (grounding inline) | | ` extract.json / evidence.json` | extract items: the raw result verbatim and the local field→box evidence join | | ` parse/ref.json` | parse-backed extract items: the reference to the parse job item (artifacts are never copied) | | ` markdown.md` | bring-your-own-markdown extract items: the input markdown, copied in (spans index exactly these bytes) | | ` document.` | URL parses: the attached document copy (`parse --keep-copy`, or fetched automatically on first `view`/`crop`) page previews and crops render from - unverified against the parsed run | | ` view.html / crops/` | derived artifacts: the self-contained viewer and PNG crops - recomputable, built on demand | ## Conventions * **`--json`**: Every command supports `--json`: one stable JSON object/array on stdout (errors and pending payloads follow the same rule). Agents should always pass it. Each command's published shape is its 'result' block below - the full result is always on stdout, never only in a file. * **`--id-only`**: parse, extract, and find also take `--id-only`: just the id(s), one per line, for piping (JOB=\$(ade parse -d f.pdf `--id-only`)). Errors and hints go to stderr so a captured id is never a sentence. * **`job item ids`**: Store commands take a job item id or an unambiguous prefix. Discover ids with `history list`; ambiguous or unknown ids error with candidates listed. Distinct from the server-side run id: `--json` payloads report that as run\_id, and on-disk records spell the same value job\_id (the wire's name) - neither is ever a job item id. * **`guarantees`**: parse and extract ensure a run exists rather than fire a request: an already-done run is served from disk free with an explicit notice (`--force` consents to a re-bill); a pending run is resumed, never resubmitted; Ctrl-C stops the waiting, not the work. * **`env overrides`**: ADE\_HOME relocates the store; ADE\_API\_KEY overrides stored credentials; ADE\_ENDPOINT overrides the stored endpoint. ## Help Topics The CLI ships conceptual help topics (`ade help `). Each one is covered in depth by a guide page: | Topic | Guide | | ---------------------- | -------------------------------------------------- | | `ade help workflow` | [CLI Concepts](./concepts) | | `ade help output` | [Scripting and Automation](./scripting-automation) | | `ade help credentials` | [Authentication](./authentication) | | `ade help errors` | [Scripting and Automation](./scripting-automation) | ## Next Steps Job items, output modes, exit codes, and the local store. Pipe results, handle exit codes, and run the CLI from agents and CI. # Changelog Source: https://docs.landing.ai/dpt3/changelog Learn about updates and new features across the ADE v2 APIs: Parse, Extract, Ground, Parse Jobs, and Extract Jobs. ## Ground Extracted Fields The new [Ground API](./ground) (`POST /v2/ground`) maps each field extracted by [Extract](./extract) back to the blocks it was quoted from in the [Parse](./parse) response. For every extracted value, it returns the matching blocks with their ids, page numbers, and bounding boxes, so you can highlight values on the page, build review interfaces, attach citations, or crop the regions values came from. Grounding is a stateless join over two objects you already have: the Extract response's `extraction_metadata` and the Parse response's `structure`. It runs synchronously, completes quickly, and consumes no credits. ### Get Started * [Ground Extracted Fields](./ground) * [API reference](https://docs.landing.ai/api-reference/ground/ade-ground) This release adds webhook notifications, changes the model values you send to [Parse](./parse) and what the Parse response reports, and moves [Extract](./extract) to a new default snapshot: * [Get Notified When Runs Finish](#get-notified-when-runs-finish) * [Model Values for DPT-3 Verity](#model-values-for-dpt-3-verity) * [Confidence Appears Only on Word Entries](#confidence-appears-only-on-word-entries) * [Response Values Are Shorter](#response-values-are-shorter) * [New Extraction Model Snapshot](#new-extraction-model-snapshot) * [Oversized Images Return an Error Right Away](#oversized-images-return-an-error-right-away) ## Get Notified When Runs Finish You can now register webhook endpoints that receive a signed event when a [Parse](./parse) or [Extract](./extract) run succeeds or fails, instead of polling for job status. Events carry job identifiers and status, never document content, and fire for synchronous requests and async jobs alike. Manage endpoints in **[Playground](https://ade.landing.ai/)** > **Settings** > **Webhooks**. See [Webhooks](./webhooks). ## Model Values for DPT-3 Verity [Parse](./parse) and [Parse Jobs](./parse-async) now accept `dpt-3-verity`, `dpt-3-verity-latest`, and `dpt-3-verity-20260804-preview`, matching the model's name. These values previously carried the model's earlier name, DPT-3 Fast. Requests that pin `dpt-3-fast`, `dpt-3-fast-latest`, or `dpt-3-fast-20260804-preview` still work, so no code change is required. The response reports the new name instead of the one you sent. For example, a request pinning `dpt-3-fast-20260804-preview` comes back with `metadata.model_version` set to `dpt-3-verity-20260804-preview`. Nothing about the model changed. The rename did not create a new snapshot. ## Confidence Appears Only on Word Entries On [DPT-3 Verity](./parse-models) parses, the `confidence` score now appears only on the word entries of `atomic_grounding`. The `grounding` of a block, `table_cell`, `table`, or page no longer carries one. To get a block's lowest score, take the minimum `confidence` across its word entries. Setting [`options.atomic_grounding`](./parse-input#request-options) to `false` now removes every score from the response, because the scores live on the word entries. See [Word Confidence Scores](./parse-response#word-confidence-scores-dpt-3-verity). ## Response Values Are Shorter Bounding box coordinates now carry at most 5 decimal places, and `confidence` at most 2. See [Grounding](./parse-response#grounding-where-things-are). ## New Extraction Model Snapshot [Extract](./extract) and [Extract Jobs](./extract-async) now accept the `extract-20260819` snapshot, and it is the default. Requests that omit `model`, or that send `extract-latest` or `extract`, run on it. Extraction results can change with a new snapshot. To keep the previous behavior, pin `extract-20260710`, which stays available. The response reports which snapshot ran in `metadata.model_version`. See [Model Version](./extract-input#model-version). ## Oversized Images Return an Error Right Away [Parse](./parse) now answers immediately with a 422 error when an image is larger than 178,956,970 pixels (about 179 megapixels). Previously the request kept processing until it timed out, so you waited for the full timeout to learn the image was too big. No credits are consumed either way. See [Troubleshoot Parsing](./parse-troubleshoot#error-image-exceeds-the-maximum-resolution). ## Restrict API Access by IP Address Organizations on the Enterprise plan can now restrict their access to the ADE APIs to a set of approved IP addresses. When an allowlist is active, API requests from any other address are rejected. The allowlist applies to every request to the v1 and v2 APIs, no matter which API key is used. It does not restrict the Playground. To enable an allowlist, email [support@landing.ai](mailto:support@landing.ai) with the IPv4 or IPv6 addresses and CIDR ranges to approve. See [IP Address Allowlist](/ade/ip-allowlist). ## Parse with DPT-3 Verity (Preview) [Parse](./parse) and [Parse Jobs](./parse-async) now offer a second model family: **DPT-3 Verity**, a preview model optimized for digitally created text documents. Set `model=dpt-3-verity` on a request, or select **DPT-3 Verity** in the [Playground](./playground) model drop-down. The default model remains DPT-3 Pro. Compared with DPT-3 Pro, DPT-3 Verity: * **Returns results faster and consumes fewer credits.** For credit rates, go to [Credit Consumption](./credit-consumption#dpt-3-verity). * **Grounds every word in text, tables, and marginalia.** The `atomic_grounding` array carries one entry per word, including the words inside table cells. See [Atomic Grounding](./parse-response#atomic-grounding). * **Scores every word it transcribes in text, tables, and marginalia.** Each word entry carries a `confidence` value, so you can route uncertain transcriptions to review. The [Playground](./playground#review-word-confidence-scores-dpt-3-verity) highlights low-confidence words. See [Word Confidence Scores](./parse-response#word-confidence-scores-dpt-3-verity). * **Optimized for digitally created documents and Latin scripts.** For scanned or handwritten documents, non-Latin scripts, math formulas, or detailed figure descriptions, choose DPT-3 Pro. For the full comparison and guidance on choosing a model, see [Parsing Models](./parse-models). This model was released as DPT-3 Fast and renamed to DPT-3 Verity on August 26, 2026. The `model` parameter values changed with it, and requests that pin the earlier `dpt-3-fast` values still work. ### Library Support Word confidence scores require the [Python Library](./ade-python) v1.17.0 or later, or the [TypeScript Library](./ade-typescript) v2.12.0 or later. ## Out-of-Range Page Selections Are Rejected [Parse](./parse) now rejects an `options.pages` selection that includes a page beyond the document's last page with a 422 error that names the invalid pages. Previously the same request could return a 500, a partial 206 result, or an empty result. A single out-of-range value rejects the whole request, and no credits are consumed. [Parse Jobs](./parse-async) runs the same check after the job starts, because the page count is not known at submission. An out-of-range selection fails the job, and the poll response reports the invalid pages in the `error` field. See [Troubleshoot Parsing](./parse-troubleshoot#error-pages-out-of-range). ## Parse Office Documents [Parse](./parse) and [Parse Jobs](./parse-async) now accept Word documents (DOCX), PowerPoint presentations (PPTX), OpenDocument text (ODT), and rich text files (RTF), in addition to PDFs and images. Office files are converted to PDF before parsing. You can also upload DOCX, PPTX, and ODT files in the [Playground](./playground). See [Supported File Types](./file-types). ## Expired Delivery URLs Are Rejected at Submission [Parse Jobs](./parse-async) and [Extract Jobs](./extract-async) now validate the `output_save_url` when you create the job. A presigned URL that is already expired, or that expires before the job can complete, is rejected with a 422 error at submission instead of failing at delivery after the document is processed. No credits are consumed for the rejected request. See [URL Requirements](./parse-async#url-requirements). ## Set Credit Usage Alerts You can now set alerts that email your team when your organization's credit consumption crosses a threshold. Organizations with a subscription start with three default alerts at 80%, 90%, and 100% of quota. See [Credit Usage Alerts](/ade/credit-alerts). Alert section of the Usage page, showing the three default credit alerts with their thresholds, recipients, and statuses ## Billing Metadata for Jobs That Save Output to a URL [Parse Jobs](./parse-async) and [Extract Jobs](./extract-async) created with `output_save_url` now report the job's `metadata` (including `billing`) in the completed poll response, and the file delivered to your URL contains the complete response, also including `metadata`. This also applies to jobs that completed before this change: poll the job again, and the response now includes its `metadata`. ## Smoother Job Progress Reporting The `progress` field on [Parse Jobs](./parse-async) and [Extract Jobs](./extract-async) polls now updates on every poll as an estimate of how close the job is to completion, instead of staying at `0` for most of a run. ## Playground Updates * Search the parse results with the toolbar's find-in-page search, fold JSON objects, and toggle word wrap. See [Review the Results](./playground#review-the-results). * The parse toolbar is redesigned, and the Config menu's grounding control is now named **Atomic grounding** (previously "Fine-grained output"). See [Customize the Parse Output with Config](./playground#customize-the-parse-output-with-config). * Hovering a block in the Parse tab reveals its per-line and per-cell boxes on the document, and hovering an extracted field in the Extract tab highlights and labels where its value appears in the document. ## The ADE v2 APIs Are Generally Available The Agentic Document Extraction v2 APIs, powered by DPT-3, are now generally available: [Parse](./parse), [Parse Jobs](./parse-async), [Extract](./extract), and [Extract Jobs](./extract-async). We have made many improvements since the May Preview, including faster processing and a cleaner, more consistent response format. Parse your first document with the v2 APIs. Move from the v1 (DPT-2) APIs. ## New Guide: Choose a Processing Mode and Service Tier The new [Sync vs Async Processing](./sync-async) guide compares the three ways to process documents, so you can choose the right call for each workload: * Synchronous requests * Jobs on the `priority` tier * Jobs on the `standard` tier (the default) ## New Response Format for the Parse and Extract v2 APIs We updated the response format of the [Parse v2](./parse) and [Extract v2](./extract) APIs based on developer feedback. The endpoints, authentication, and Markdown output format are unchanged. The changes are breaking if your code reads the `structure` or `grounding` output from Parse, the `extraction_metadata` output from Extract, sends the `options.pages` selector, or polls Parse Jobs. For the current response shapes, see [Parse API Response](./parse-response) and [Extract API Response](./extract-response). For the full list of changes and how to update your code, see the [July 17 Migration Notes](./migration-july-17). ## Simplified Pricing We have simplified pricing. For the Explore and Team plans, \$1 buys 100 credits. This is applicable to both the EU and US regions. See [Plans & Billing](../ade/ade-pricing). Credit *consumption* rates are unchanged. To see how many credits each API call consumes, go to [Credit Consumption for ADE v2](/dpt3/credit-consumption). ## Fixed: Bounding Boxes for EXIF Images with EXIF orientation metadata (such as phone photos) are now parsed upright, so bounding boxes align with the image as a viewer sees it. See [Working with Boxes](/dpt3/parse-response#working-with-boxes). This release updated the [Parse v2 API](./parse) and launched three new Agentic Document Extraction v2 APIs, all powered by DPT-3: * **[Parse Jobs v2](./parse-async)**: Parse documents asynchronously. Submit a document, receive a `job_id`, and poll for the result. Jobs accept up to 6,000 pages and 1 GiB per PDF, and can save output directly to a URL you control. * **[Extract v2](./extract)**: Pull specific fields from Markdown with a JSON schema, with span-level grounding that maps each value back to its source. * **[Extract Jobs v2](./extract-async)**: Run long-running extractions asynchronously, for long documents or large schemas. Parse Jobs and Extract Jobs choose a service tier when you create a job: `standard` (the default, half the credits) or `priority` (faster turnaround at the full rate). For current tier behavior, see [Sync vs Async Processing](./sync-async). Also in this release: * **New Playground URL.** The Agentic Document Extraction Playground moved to [ade.landing.ai](https://ade.landing.ai/) in the US and [ade.eu-west-1.landing.ai](https://ade.eu-west-1.landing.ai) in the EU. Links to the previous `va.landing.ai` URL redirect automatically. * **Redesigned Usage page.** The [Usage page](https://ade.landing.ai/settings/usage) shows daily and monthly consumption charts and detailed per-job logs. See [Monitor Credit Usage](/ade/monitor-usage). ## HTML Tables by Default Tables now return as HTML instead of pipe-syntax Markdown. HTML preserves merged cells and nested layouts that pipe syntax cannot represent. ## Parse Options in the Playground The Parse tab's **Config** menu now exposes DPT-3 parse options directly in the browser: choose which element types to caption, set the table output format, toggle fine-grained grounding, and select specific pages. These controls map to the API's [`options`](./parse-input#request-options) field. See [Parse in the Playground](./playground). DPT-3 Pro Config drop-down menu showing the parse options ## Preview of DPT-3 and the New Parse API DPT-3, our newest parsing model, and the redesigned [Parse API](https://docs.landing.ai/api-reference/parse/ade-parse) are now available in Preview. DPT-3 is a complete rethink of document parsing for the era of AI agents and agentic workflows: a new model architecture, a new response shape, and complexity-aware pricing. Upload a document directly in the browser. No code required. See parameters, response fields, and code samples. ### Highlights * **Designed for agent systems.** Semantic block ids, a predictable hierarchy, and Markdown span pointers so AI agents can map results back to source. * **Hierarchical layout model.** The structured output is a nested hierarchy: pages, blocks on each page, and cells within tables. * **Visual grounding.** A bounding box on every block, plus finer-grained grounding within blocks. * **Cleaner, more standardized Markdown.** Consistent, structured Markdown output designed for RAG and downstream processing. * **New endpoint and response shape.** Calls go to the [new API](https://docs.landing.ai/api-reference/parse/ade-parse), which returns the document as Markdown plus a hierarchical `structure` tree. See the [Migration Guide](./migration-guide). ### Get Started * [Overview](./overview) * [Quickstart](./quickstart) * [Migration Guide from DPT-2](./migration-guide) # Overview Source: https://docs.landing.ai/ade/ade-overview Learn how ADE converts documents into structured data and when to use Parse, Extract, Classify, Section, and Split. [Agentic Document Extraction](https://ade.landing.ai/) (ADE) is a document intelligence platform that converts documents into reliable, structured data. Use the structured data from ADE to build retrieval-augmented generation (RAG) applications, power intelligent search systems, extract key information, and automate document processing at scale. ## How ADE Works Agentic Document Extraction provides multiple APIs for document processing: [Parse](./parse), [Extract](./ade-extract), [Classify](./ade-classify), [Section](./ade-section), and [Split](./ade-split). Most workflows start with **Parse**, which converts your documents into structured data. After parsing, you can optionally use **Extract** to pull specific data fields, **Section** to generate a hierarchical table of contents, or **Split** to separate multi-document files. Use **Classify** independently to label pages by document type before or without parsing. | API | Description | When to Use | | -------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | [Parse](./parse) | Converts documents into structured Markdown with hierarchical JSON.
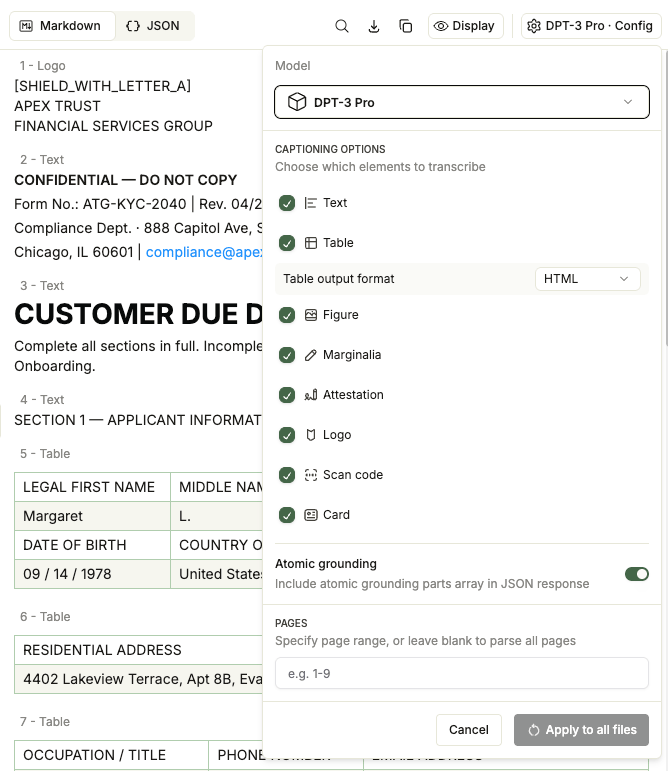
Identifies elements like text, tables, and form fields with exact page and coordinate references. | Use to convert documents into structured data for downstream applications, such as RAG, search, and training LLMs.

This is the required first step for all ADE workflows. | | [Extract](./ade-extract) | Pulls specific data fields from parsed documents using schema-based extraction. | Use when you need the values for specific fields.

Can be used after Parse or Split. | | [Classify](./ade-classify) | Assigns a category to each page of a document based on classes you define. | Use when you need to sort, route, or label pages by document type. Does not require Parse. | | [Section](./ade-section) | Analyzes a parsed document and generates a hierarchical table of contents with section titles, levels, and chunk references. | Use when you need to navigate, scope, or retrieve content by section (for example, for section-aware RAG chunking or document review tools). | | [Split](./ade-split) | Classifies and separates parsed documents into multiple sub-documents based on document types you define. | Use when one file contains multiple documents that need to be separated, such as batched Know Your Customer (KYC) documents. | ## Get Started Create an account and process files in our Playground. Comfortable with using the Playground? Now you can make your first API call in minutes. ## Key Features Delivers high accuracy, even on complex documents. Achieved **99.16% accuracy** on the DocVQA dataset. Identifies specific elements (called "chunks") including text, tables, images, form fields, and bar codes. Includes page numbers and coordinates for each chunk to support traceability, validation, and compliance workflows. Handles any document layout without templates or training—works out of the box. Understands relationships between elements to generate accurate descriptions and maintain proper reading order. Returns results in Markdown for human readability and JSON for programmatic access. Parses PDFs, images, text documents, presentations, and spreadsheets. Parses documents in multiple languages. # Quickstart Source: https://docs.landing.ai/ade/ade-quickstart Parse and extract fields from a sample document in minutes using cURL, Python, or TypeScript. Use the [Playground](https://ade.landing.ai/) to explore Agentic Document Extraction and understand basic concepts without writing code. When you're ready to scale intelligent document processing, follow the tutorial below to get started with code. ## Prerequisites * An Agentic Document Extraction [account](https://ade.landing.ai/) * An [API key](./agentic-api-key) ## Tutorial: Parse and Extract a Document This tutorial guides you through how to parse a sample bank statement and extract these fields: **Account Holder Name** and **Number of Deposits**. Install [jq](https://jqlang.org/), a free third-party command-line tool that will help you save files later in this procedure. Some common install instructions are below; to see all installation methods, go the the [jq site](https://jqlang.org/download/). ```bash Mac theme={null} brew install jq ``` ```bash Windows theme={null} winget install jqlang.jq ``` ```bash Linux theme={null} sudo apt-get install jq ``` Run the code below to parse a sample bank statement with the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse). The `>` at the end of the command saves the response to a file called `parse-output.json`. Replace `YOUR_API_KEY` with your API key. ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document_url=https://docs.landing.ai/examples/bank-statement.pdf' \ -F 'model=dpt-2-latest' > parse-output.json ``` To extract data from the document, you need to pass the `markdown` field from `parse-output.json` to the ADE Extract API. Run the following command to save the `markdown` field to a file called `markdown-bank-statement.md`. ```bash theme={null} jq -r .markdown parse-output.json > markdown-bank-statement.md ``` Now that the parsed output is in a Markdown file, run the code below to extract the **Account Holder Name** and **Number of Deposits** fields using the [ADE Extract API](https://docs.landing.ai/api-reference/tools/ade-extract). Replace `YOUR_API_KEY` with your API key. ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'schema={"type": "object", "properties": {"name": {"type": "string", "description": "Account holder name"}, "number_deposits": {"type": "integer", "description": "The number of deposits"}}}' \ -F 'markdown=@markdown-bank-statement.md' \ -F 'model=extract-latest' ``` The API response includes the extracted fields: * **Account Holder Name**: Sarah J. Mitchell * **Number of Deposits**: 5 ```json expandable highlight={3-4} theme={null} { "extraction":{ "name":"Sarah J. Mitchell", "number_deposits":5 }, "extraction_metadata":{ "name":{ "references":[ "8b70276e-a3ee-4ed4-9f11-15439c50d603" ], "value":"Sarah J. Mitchell" }, "number_deposits":{ "references":[ "d9d59d6d-cf43-4ed2-8632-5f48d08885c5" ], "value":5 } }, "metadata":{ "filename":"markdown-bank-statement.md", "org_id":"lgy5xucm9xnq", "duration_ms":6516, "credit_usage":1.5188, "job_id":"1bdcf9c99a614d698f3b4aca65f27935", "version":"extract-20260314", "schema_violation_error":null, "fallback_model_version":null, "warnings":[ ] } } ``` Get your [API key](https://ade.landing.ai/settings/api-key) and set it as an environment variable. For more details, go to [API Key](./agentic-api-key). ```bash theme={null} export VISION_AGENT_API_KEY="" ``` Install the [ade-python](https://github.com/landing-ai/ade-python) library. ```bash theme={null} pip install landingai-ade ``` This example shows the complete workflow of parsing a sample bank statement and extracting the **Account Holder Name** and **Number of Deposits** fields. If you only need to parse documents, use just the parsing section. Save the code block below as `quickstart.py`. ```python expandable theme={null} import json from landingai_ade import LandingAIADE # Initialize the client client = LandingAIADE() ##### Parse the document ##### # Parse the document parse_response = client.parse( document_url="https://docs.landing.ai/examples/bank-statement.pdf", model="dpt-2-latest", save_to="./output" # optional: saves the full response as JSON for later reference ) print("Full Parse response saved to ./output/") ##### Extract fields from the parsed document ##### # Define which fields to extract. Each property specifies a field name and its expected data type. schema_dict = { "type": "object", "properties": { "name": { "type": "string", "description": "Account holder name" }, "number_deposits": { "type": "integer", "description": "The number of deposits" } } } # Convert schema dictionary to JSON string schema_json = json.dumps(schema_dict) # Extract fields using the parsed markdown extract_response = client.extract( schema=schema_json, markdown=parse_response.markdown, # Parse converts the document to Markdown; Extract uses it to identify and pull specific fields model="extract-latest", save_to="./output" # optional: saves the full response as JSON for later reference ) print("Full Extract response saved to ./output/") # Print the extracted fields print("\nExtracted fields:") print(extract_response.extraction) ``` Run the Python file you created. ```bash theme={null} python quickstart.py ``` The script parses the document and saves both responses to `./output/`. The extracted fields returned are: * **Account Holder Name**: Sarah J. Mitchell * **Number of Deposits**: 5 ```text theme={null} Extracted fields: {'name': 'Sarah J. Mitchell', 'number_deposits': 5} ``` Get your [API key](https://ade.landing.ai/settings/api-key) and set it as an environment variable. For more details, go to [API Key](./agentic-api-key). ```bash theme={null} export VISION_AGENT_API_KEY="" ``` Install the [ade-typescript](https://github.com/landing-ai/ade-typescript) library. ```bash theme={null} npm install landingai-ade ``` This example shows the complete workflow of parsing a sample bank statement and extracting the **Account Holder Name** and **Number of Deposits** fields. If you only need to parse documents, use just the parsing section. Save the code block below as `quickstart.ts`. ```typescript expandable theme={null} import LandingAIADE from "landingai-ade"; // Initialize the client const client = new LandingAIADE(); ///// Parse the document ///// // Parse the document const parseResponse = await client.parse({ document: await fetch("https://docs.landing.ai/examples/bank-statement.pdf"), model: "dpt-2-latest", saveTo: "./output" // optional: saves the full response as JSON for later reference }); console.log("Full Parse response saved to ./output/"); ///// Extract fields from the parsed document ///// // Define which fields to extract. Each property specifies a field name and its expected data type. const schemaDict = { type: "object", properties: { name: { type: "string", description: "Account holder name" }, number_deposits: { type: "integer", description: "The number of deposits" } } }; // Convert schema object to JSON string const schemaJson = JSON.stringify(schemaDict); // Extract fields using the parsed markdown const extractResponse = await client.extract({ schema: schemaJson, markdown: parseResponse.markdown, // Parse converts the document to Markdown; Extract uses it to identify and pull specific fields model: "extract-latest", saveTo: "./output" // optional: saves the full response as JSON for later reference }); console.log("Full Extract response saved to ./output/"); // Print the extracted fields console.log("\nExtracted fields:"); console.log(extractResponse.extraction); ``` Run the TypeScript file you created. ```bash theme={null} npx tsx quickstart.ts ``` The script parses the document and saves both responses to `./output/`. The extracted fields returned are: * **Account Holder Name**: Sarah J. Mitchell * **Number of Deposits**: 5 ```text theme={null} Extracted fields: { name: 'Sarah J. Mitchell', number_deposits: 5 } ``` ## Next Steps: Develop and Scale Choose how you want to integrate Agentic Document Extraction into your workflow. Build with AI agents, call the API directly, or use our Python and TypeScript libraries. Use ADE skills, an MCP server, and llms.txt with your AI agents and coding tools. Call the API directly for language flexibility and advanced customization. Use our Python library to build custom scripts. TypeScript TypeScript } href="./ade-typescript" > Use our TypeScript library to build custom scripts. ## Sample Scripts & Projects Use these sample scripts and projects for real-world use cases as templates to develop your own custom document processing solutions. Explore end-to-end examples for common document processing workflows. Browse code samples with examples for the Python and TypeScript libraries. # API Key Source: https://docs.landing.ai/ade/agentic-api-key Create an API key and set it for the client libraries or direct API calls. Running the Agentic Document Extraction API, either by using a library or by calling an API directly, requires an API key. * [Get your API key](#get-your-api-key) * [Set your API key when using the library](#set-your-api-key-when-using-the-library) * [Set your API key when calling the API directly](#set-your-api-key-when-calling-the-api-directly) ## Get Your API Key If using Agentic Document Extraction in the EU, get your API key [here](https://ade.eu-west-1.landing.ai/settings/api-key). Get your API key on the [API Key](https://ade.landing.ai/settings/api-key) page: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [API Key](https://ade.landing.ai/settings/api-key) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **API Key**). Navigate to API Key 3. If you're on a subscription plan, you can [create an API key](#create-api-keys-subscription-plans-only) if needed. 4. Click the **Copy** icon to copy your API key. API Key ## Personal Plans (Explore Plans) Have One API Key The personal plan (the "Explore" plan) only has one API key. This API key cannot be deleted or revoked. The Explore plan type is designed for testing, prototyping, and hobby use. If you'd like to deploy to production and need more granular API key management, like the ability to create and revoke API keys, [upgrade](./ade-pricing) to a subscription plan. If your API key is exposed or leaked and you'd like to request a new API key, contact [support@landing.ai](mailto:support@landing.ai) ## Create API Keys If you are on a Team or Enterprise plan, you can create multiple API keys for your organization to use. To create an API key: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [API Key](https://ade.landing.ai/settings/api-key) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **API Key**). Navigate to API Key 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Click **Create Key**. 5. Enter a brief, descriptive name for the API key in the key name field. 6. Click **Create API Key**. 7. Click the **Copy** icon to copy the API key. 8. Click **Done** to close the pop-up. ## Revoke API Keys If you are on the Team or Enterprise plan, you can revoke API keys. A user with the Admin role can revoke any API key. A user with the Developer role can revoke only API keys they have created. To revoke an API key: 1. Log in to [https://ade.landing.ai/](https://ade.landing.ai/). 2. Go to the [API Key](https://ade.landing.ai/settings/api-key) page (to navigate there manually, click your profile icon at the bottom left corner of the page and click **API Key**). Navigate to API Key 3. If you're not currently in the correct organization, select your organization from the drop-down menu. 4. Locate the row for the API key. (You may need to search to narrow down the list of API keys.) 5. Click the **Settings** button (ellipses) and select **Revoke API Key**. Follow the on-screen prompts to complete the process. ## Set Your API Key When Using the Library The client libraries read your API key from the `VISION_AGENT_API_KEY` environment variable. [Get your API key](#get-your-api-key) first, then set it using any of the methods below. Do not hard-code your API key in source files. The examples below use the [ade-python library](./ade-python); the [TypeScript library](./ade-typescript) reads the same environment variable. ### Method 1: Set the API Key as an Environment Variable 1. Set the environment variable. To persist the key across sessions on macOS or Linux, add the `export` command to your shell profile (`.zshrc` or `.bashrc`), then run `source ~/.zshrc`. ```bash macOS/Linux theme={null} export VISION_AGENT_API_KEY="" ``` ```cmd Windows (Command Prompt) theme={null} set "VISION_AGENT_API_KEY=" ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY="" ``` 2. Initialize the client. It reads the `VISION_AGENT_API_KEY` environment variable automatically: ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() ``` ### Method 2: Store the API Key in a .env File Store your API key in a `.env` file. The library reads the key from the environment; it does not load `.env` files on its own, so use `python-dotenv` to load the file. 1. Install the `python-dotenv` package: ```bash theme={null} pip install python-dotenv ``` 2. Create a `.env` file in your project root and add your API key: ```bash theme={null} VISION_AGENT_API_KEY= ``` 3. Load the `.env` file before you initialize the client: ```python theme={null} from dotenv import load_dotenv from landingai_ade import LandingAIADE load_dotenv() # Populates the environment from .env. client = LandingAIADE() ``` ### Method 3: Set the API Key in a Notebook In IPython-based notebooks (Jupyter, JupyterLab, Google Colab, or Kaggle), set the key for the current session with the `%env` magic command. The key is cleared when the kernel restarts, and it is visible in the notebook file if you share or commit it. 1. In a notebook cell, set the environment variable: ```python theme={null} %env VISION_AGENT_API_KEY= ``` 2. Initialize the client in a later cell: ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() ``` ### API Key Precedence If the API key is set in more than one place, the library resolves it in this order (the first match wins): 1. The `apikey` passed to the client constructor. 2. The `VISION_AGENT_API_KEY` environment variable, whether you set it directly or loaded it from a `.env` file. A value already set in your environment is not overridden by a `.env` file. For help with missing-key errors, keys that fail to load, or keys that resolve to the wrong account, see [Troubleshoot API Key Issues](./agentic-api-key#troubleshoot-api-key-issues). ## Set Your API Key When Calling the API Directly Include the API key in request headers. To see code samples, go to [API](https://docs.landing.ai/api-reference/tools/ade-parse). ## Security Best Practices * If using a `.env` file: Add `.env` to `.gitignore` to prevent accidentally committing the API key to version control. * Do not hard-code the API key in your source code, because others could see and use your API key. Passing a variable that holds the key (for example, from a secrets manager) is fine. ## Troubleshoot API Key Issues Use the troubleshooting tips in this section to resolve issues related to API keys. ### Error: Missing API Key If no API key is set by any method, the library raises an error when you create the client. The Python library raises this error: ```text theme={null} landingai_ade.LandingAiadeError: The apikey client option must be set either by passing apikey to the client or by setting the VISION_AGENT_API_KEY environment variable ``` The TypeScript library throws this error: ```text theme={null} LandingAIADEError: The VISION_AGENT_API_KEY environment variable is missing or empty; either provide it, or instantiate the LandingAIADE client with an apikey option, like new LandingAIADE({ apikey: 'My Apikey' }). ``` To resolve this issue, set the key using one of the supported methods. If you set the key in a `.env` file or as an environment variable and still get this error, see the .env File Issues and Environment Variable Issues sections. ### .env File Issues If you set the API key in the `.env` file but the environment variable is not loading, try these possible solutions to resolve this issue: * Check file location: The `.env` file should be in the same directory where you run your script. * Verify file format: No spaces around the equals sign: ``` # Correct VISION_AGENT_API_KEY= # Incorrect VISION_AGENT_API_KEY = ``` ### Environment Variable Issues If you set the API key as an environment variable and are encountering issues, try these possible solutions to resolve this issue: * Restart your application after setting environment variables. * Check variable name: Must be exactly `VISION_AGENT_API_KEY`. * Check if the environment variable is correct: ```bash macOS/Linux theme={null} echo $VISION_AGENT_API_KEY ``` ```cmd Windows (Command Prompt) theme={null} echo %VISION_AGENT_API_KEY% ``` ```powershell Windows (PowerShell) theme={null} $env:VISION_AGENT_API_KEY ``` * Ensure that you apply the changes after setting, changing, or removing the environment variable: * **Linux/macOS**: Restart your terminal. If you added the variable to your `.zshrc` file, run `source ~/.zshrc`. * **Windows**: Close and reopen Command Prompt/PowerShell, or restart your IDE. ### Wrong API Key Used If you have multiple accounts and Agentic Document Extraction is using the wrong API key, the API key might be set using multiple methods and one is taking precedence over the other. To resolve this issue, check which API keys are set using each method. **Example Scenario:** 1. You create an account with your *personal* email address and set the API as an environment variable. 2. A few weeks later you create an account with your *work* email address and store the API key for that account in a .env file. 3. When you run Agentic Document Extraction, it uses the first API key, because the environment variable takes precedence over the .env file. **Solution**: Checking each way the API key can be set and then removing the unwanted API keys will ensure that the correct API key is used. ### Error: Missing Authorization Header This error occurs if the authorization header is not included when calling the API directly. To fix this, include the API header: ```python theme={null} headers = {"Authorization": f"Bearer {api_key}"} ``` ### Error: User Not Found, Please Check Your API Key This error occurs when the API key is entered incorrectly. To resolve this issue: * Verify the API key: Copy your key directly from the [dashboard](https://ade.landing.ai/settings/api-key). * Restart your environment: Close and reopen your terminal, IDE, or Jupyter notebook. # Playground Source: https://docs.landing.ai/ade/ade-playground Process documents with ADE in our Playground, no code required. ## Overview The Agentic Document Extraction [Playground](https://ade.landing.ai/) is a web-based application that lets you quickly try out our APIs without writing any code. You can run the [Parse](./parse), [Extract](./ade-extract), [Classify](./ade-classify), [Section](./ade-section), and [Split](./ade-split) tools on your documents and see the output directly in the interface. The Playground's model drop-down menu defaults to **DPT-3 Pro**, the ADE Gen2 model. To parse with DPT-2 and get the output described in these Gen1 docs, [select a DPT-2 model](./ade-parse-models#set-the-model-in-the-playground). ADE Playground ## From Playground to Production If you're new to Agentic Document Extraction, start with the [Playground](https://ade.landing.ai/) rather than jumping straight into the APIs. The Playground gives you an immediate, visual way to explore what [Parse](./parse), [Extract](./ade-extract), [Classify](./ade-classify), [Section](./ade-section), and [Split](./ade-split) can do with your specific documents. Use the Playground to: * **Test your use case before writing any code.** Upload your actual documents and see how Agentic Document Extraction handles them. Can it parse faxed medical records? Extract supplier IDs consistently across invoices from different vendors? Handle long financial tables in earnings reports? You'll get immediate answers. * **Build extraction and split schemas visually.** The schema wizard guides you through creating, editing, and validating schemas using a point-and-click interface. * **Export production-ready code.** Once you're satisfied with the results, the Playground generates the API or library code you need to replicate the same processing programmatically. When you're ready to scale, use the [API](https://docs.landing.ai/api-reference/tools/ade-parse) or the [Python](./ade-python) or [TypeScript](./ade-typescript) libraries. The Playground is not intended for production use and has limitations such as lower rate limits. ## Files Are Organized into Projects Files in the Playground are organized into **projects**. Projects let you group similar documents together. You can then [create and apply extraction schemas](./ade-extract-playground) across multiple documents at once. Recent Projects To view all files you've uploaded to the Playground, click **Projects** in the left navigation bar. View All Projects ## Chat with Document After the Playground parses a file, you can use the **Chat with Document** tool to interact with the document. The Chat with Document tool is an LLM layered on top of the output of the ADE Parse API. The chat tool showcases how the API accurately parses and understands document data, including element locations. Use the chat tool to get inspired for how you can build custom solutions on top of the API. The Chat with Document tool suggests a few prompts based on your document. You can also enter your own prompts. Like the Playground itself, the Chat with Document tool is an example of what you can build, and is not part of the Agentic Document Extraction API. ## Manage Your Account in the Playground The Playground is also used to create and manage your account. For more information, go to [Organizations & Members](./ade-members). # Python Library Source: https://docs.landing.ai/ade/ade-python Process documents using the ADE Python library. The [ade-python](https://github.com/landing-ai/ade-python) library is a lightweight Python library you can use for parsing documents, classifying pages, extracting data, generating tables of contents, and splitting documents into sub-documents. The library is automatically generated from our API specification, ensuring you have access to the latest endpoints and parameters. ## Install the Library ```bash theme={null} pip install landingai-ade ``` ## Set the API Key as an Environment Variable To use the library, first [generate an API key](https://ade.landing.ai/my/settings/api-key). Save the key to a `.zshrc` file or another secure location on your computer. Then export the key as an environment variable. ```bash theme={null} ``` For more information about API keys and alternate methods for setting the API key, go to [API Key](./agentic-api-key). ## Use with EU Endpoints By default, the library uses the US endpoints. If your API key is from the EU endpoint, set the `environment` parameter to `eu` when initializing the client. ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE( environment="eu", ) # ... rest of your code ``` For more information about using Agentic Document Extraction in the EU, go to [European Union (EU)](./ade-eu). ## Parse: Getting Started The `parse` function converts documents into structured markdown with chunk and grounding metadata. Use these examples as guides to get started with parsing with the library. ### Parse Local Files Use the `document` parameter to parse files from your filesystem. Pass the file path as a `Path` object. ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Replace with your file path response = client.parse( document=Path("/path/to/file/document"), model="dpt-2-latest", save_to="./output" ) print(response.chunks) ``` ### Parse Remote URLs Use the `document_url` parameter to parse files from remote URLs (http, https, ftp, ftps). ```python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE() # Parse a remote file response = client.parse( document_url="https://example.com/document.pdf", model="dpt-2-latest", save_to="./output" ) print(response.chunks) ``` ### Set Parameters The `parse` function accepts optional parameters to customize parsing behavior. To see all available parameters, go to [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse). Pass these parameters directly to the `parse()` function. ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest", split="page" ) ``` ### Parse Jobs The `parse_jobs` function enables you to asynchronously parse documents that are up to 1,000 pages or 1 GB. For more information about parse jobs, go to [Parse Large Files (Parse Jobs)](./ade-parse-async). Here is the basic workflow for working with parse jobs: 1. Start a parse job. 2. Copy the `job_id` in the response. 3. Get the results from the parsing job with the `job_id`. This script contains the full workflow: ```python [expandable] theme={null} import time from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() ## Step 1: Create a parse job job = client.parse_jobs.create( document=Path("/path/to/file/document"), model="dpt-2-latest" ) job_id = job.job_id print(f"Job {job_id} created.") # Step 2: Get the parsing results while True: response = client.parse_jobs.get(job_id) if response.status == "completed": print(f"Job {job_id} completed.") break print(f"Job {job_id}: {response.status} ({response.progress * 100:.0f}% complete)") time.sleep(5) # Step 3: Access the parsed data print("Global markdown:", response.data.markdown[:200] + "...") print(f"Number of chunks: {len(response.data.chunks)}") # Save Markdown output (useful if you plan to run extract on the Markdown) with open("output.md", "w", encoding="utf-8") as f: f.write(response.data.markdown) ``` #### List Parse Jobs To list all async parse jobs associated with your API key, run this code: ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # List all jobs response = client.parse_jobs.list() for job in response.jobs: print(f"Job {job.job_id}: {job.status}") ``` ### Parse Output The `parse` function returns a `ParseResponse` object with the following fields: * **`chunks`**: List of `Chunk` objects, one for each parsed region * **`markdown`**: Complete Markdown representation of the document * **`metadata`**: Processing information (credit usage, duration, filename, job ID, page count, version) * **`splits`**: List of `Split` objects organizing chunks by page or section * **`grounding`**: Dictionary mapping chunk IDs to detailed grounding information For detailed information about the response structure, chunks, grounding, and bounding box coordinates, go to [JSON Response](./ade-json-response). #### Common Use Cases for ParseResponse Fields **Access all text chunks:** ```python theme={null} for chunk in response.chunks: if chunk.type == 'text': print(f"Chunk {chunk.id}: {chunk.markdown}") ``` **Filter chunks by page:** ```python theme={null} page_0_chunks = [chunk for chunk in response.chunks if chunk.grounding.page == 0] ``` **Get chunk locations:** ```python theme={null} for chunk in response.chunks: box = chunk.grounding.box print(f"Chunk at page {chunk.grounding.page}: ({box.left}, {box.top}, {box.right}, {box.bottom})") ``` **Access detailed chunk types from grounding dictionary:** ```python theme={null} for chunk_id, grounding in response.grounding.items(): print(f"Chunk {chunk_id} has type: {grounding.type}") ``` ## Extract: Getting Started The `extract` function extracts structured data from Markdown content using extraction schemas. Use these examples as guides to get started with extracting with the library. **Pass Markdown Content** The library supports a few methods for passing the Markdown content for extraction: * Extract data directly from the [parse response](#extract-from-parse-response) * Extract data from a local [Markdown file](#extract-from-markdown-files) * Extract data from a Markdown file at a remote URL: `markdown_url="https://example.com/file.md"` **Pass the Extraction Schema** The library supports a few methods for passing the extraction schema: * [Pydantic models](#extraction-with-pydantic) * [JSON schema (inline)](#extraction-with-json-schema-inline) * [JSON schema file](#extraction-with-json-schema-file) ### Extract from Parse Response After parsing a document, you can pass the markdown string directly from the `ParseResponse` to the extract function without saving it to a file. ```python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE # Define your extraction schema schema_dict = { "type": "object", "properties": { "employee_name": { "type": "string", "description": "The employee's full name" } } } client = LandingAIADE() schema_json = json.dumps(schema_dict) # Parse the document parse_response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest" ) # Extract data using the markdown string from parse response extract_response = client.extract( schema=schema_json, markdown=parse_response.markdown, # Pass markdown string directly model="extract-latest" ) # Access the extracted data print(extract_response.extraction) ``` ### Extract from Markdown Files If you already have a Markdown file (from a previous parsing operation), you can extract data directly from it. Use the `markdown` parameter for local markdown files or `markdown_url` for remote markdown files. ```python [expandable] theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE # Define your extraction schema schema_dict = { "type": "object", "properties": { "employee_name": { "type": "string", "description": "The employee's full name" }, "employee_ssn": { "type": "string", "description": "The employee's Social Security Number" }, "gross_pay": { "type": "number", "description": "The gross pay amount" } } } client = LandingAIADE() schema_json = json.dumps(schema_dict) # Extract from a local markdown file extract_response = client.extract( schema=schema_json, markdown=Path("/path/to/output.md"), model="extract-latest" ) # Or extract from a remote markdown file extract_response = client.extract( schema=schema_json, markdown_url="https://example.com/document.md", model="extract-latest" ) # Access the extracted data print(extract_response.extraction) ``` ### Extraction with Pydantic Use Pydantic models to define your extraction schema in a type-safe way. The library provides a helper function to convert Pydantic models to JSON schemas. ```python [expandable] theme={null} from pathlib import Path from landingai_ade import LandingAIADE from landingai_ade.lib import pydantic_to_json_schema from pydantic import BaseModel, Field # Define your extraction schema as a Pydantic model class PayStubData(BaseModel): employee_name: str = Field(description="The employee's full name") employee_ssn: str = Field(description="The employee's Social Security Number") gross_pay: float = Field(description="The gross pay amount") # Initialize the client client = LandingAIADE() # First, parse the document to get markdown parse_response = client.parse( document=Path("/path/to/pay-stub.pdf"), model="dpt-2-latest" ) # Convert Pydantic model to JSON schema schema = pydantic_to_json_schema(PayStubData) # Extract structured data using the schema extract_response = client.extract( schema=schema, markdown=parse_response.markdown, model="extract-latest" ) # Access the extracted data print(extract_response.extraction) # Access extraction metadata to see which chunks were referenced print(extract_response.extraction_metadata) ``` ### Extraction with JSON Schema (Inline) Define your extraction schema directly as a JSON string in your script. ```python [expandable] theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE # Define your extraction schema as a dictionary schema_dict = { "type": "object", "properties": { "employee_name": { "type": "string", "description": "The employee's full name" }, "employee_ssn": { "type": "string", "description": "The employee's Social Security Number" }, "gross_pay": { "type": "number", "description": "The gross pay amount" } } } # Initialize the client client = LandingAIADE() # First, parse the document to get markdown parse_response = client.parse( document=Path("/path/to/pay-stub.pdf"), model="dpt-2-latest" ) # Convert schema dictionary to JSON string schema_json = json.dumps(schema_dict) # Extract structured data using the schema extract_response = client.extract( schema=schema_json, markdown=parse_response.markdown, model="extract-latest" ) # Access the extracted data print(extract_response.extraction) # Access extraction metadata to see which chunks were referenced print(extract_response.extraction_metadata) ``` ### Extraction with JSON Schema File Load your extraction schema from a separate JSON file for better organization and reusability. For example, here is the `pay_stub_schema.json` file: ```json theme={null} { "type": "object", "properties": { "employee_name": { "type": "string", "description": "The employee's full name" }, "employee_ssn": { "type": "string", "description": "The employee's Social Security Number" }, "gross_pay": { "type": "number", "description": "The gross pay amount" } } } ``` You can pass the JSON file defined above in the following script: ```python [expandable] theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE # Initialize the client client = LandingAIADE() # First, parse the document to get markdown parse_response = client.parse( document=Path("/path/to/pay-stub.pdf"), model="dpt-2-latest" ) # Load schema from JSON file with open("pay_stub_schema.json", "r") as f: schema_json = f.read() # Extract structured data using the schema extract_response = client.extract( schema=schema_json, markdown=parse_response.markdown, model="extract-latest" ) # Access the extracted data print(extract_response.extraction) # Access extraction metadata to see which chunks were referenced print(extract_response.extraction_metadata) ``` ### Extract Nested Subfields Define nested Pydantic models to extract hierarchical data from documents. This approach organizes related information under meaningful section names. Define nested models before the main extraction schema. Otherwise, the nested model classes will not be defined when referenced. For example, to extract data from the **Patient Details** and **Emergency Contact Information** sections in this Medical Form, define separate models for each section, then combine them in a main model. ```python [expandable] theme={null} from pathlib import Path from pydantic import BaseModel, Field from landingai_ade import LandingAIADE from landingai_ade.lib import pydantic_to_json_schema # Define a nested model for patient-specific information class PatientDetails(BaseModel): patient_name: str = Field( ..., description='Full name of the patient.', title='Patient Name' ) date: str = Field( ..., description='Date the patient information form was filled out.', title='Date', ) # Define a nested model for emergency contact details class EmergencyContactInformation(BaseModel): emergency_contact_name: str = Field( ..., description='Full name of the emergency contact person.', title='Emergency Contact Name', ) relationship_to_patient: str = Field( ..., description='Relationship of the emergency contact to the patient.', title='Relationship to Patient', ) primary_phone_number: str = Field( ..., description='Primary phone number of the emergency contact.', title='Primary Phone Number', ) secondary_phone_number: str = Field( ..., description='Secondary phone number of the emergency contact.', title='Secondary Phone Number', ) address: str = Field( ..., description='Full address of the emergency contact.', title='Address' ) # Define the main extraction schema that combines all the nested models class PatientAndEmergencyContactInformationExtractionSchema(BaseModel): # Nested field containing patient details patient_details: PatientDetails = Field( ..., description='Information about the patient as provided in the form.', title='Patient Details', ) # Nested field containing emergency contact information emergency_contact_information: EmergencyContactInformation = Field( ..., description='Details of the emergency contact person for the patient.', title='Emergency Contact Information', ) # Initialize the client client = LandingAIADE() # Parse the document to get markdown parse_response = client.parse( document=Path("/path/to/medical-form.pdf"), model="dpt-2-latest" ) # Convert Pydantic model to JSON schema schema = pydantic_to_json_schema(PatientAndEmergencyContactInformationExtractionSchema) # Extract structured data using the schema extract_response = client.extract( schema=schema, markdown=parse_response.markdown, model="extract-latest" ) # Display the extracted structured data print(extract_response.extraction) ``` ### Extract Variable-Length Data with List Objects Use python `List` type inside of a Pydantic BaseModel to extract repeatable data structures when you don't know how many items will appear. Common examples include line items in invoices, transaction records, or contact information for multiple people. For example, to extract variable-length wire instructions and line items from this Wire Transfer Form, use `List[DescriptionItem]` for line items and `List[WireInstruction]` for wire transfer details. ```python [expandable] theme={null} from typing import List from pathlib import Path from pydantic import BaseModel, Field from landingai_ade import LandingAIADE from landingai_ade.lib import pydantic_to_json_schema # Nested models for list fields class DescriptionItem(BaseModel): description: str = Field(description="Invoice or Bill Description") amount: float = Field(description="Invoice or Bill Amount") class WireInstruction(BaseModel): bank_name: str = Field(description="Bank name") bank_address: str = Field(description="Bank address") bank_account_no: str = Field(description="Bank account number") swift_code: str = Field(description="SWIFT code") aba_routing: str = Field(description="ABA routing number") ach_routing: str = Field(description="ACH routing number") # Invoice model containing list object fields class Invoice(BaseModel): description_or_particular: List[DescriptionItem] = Field( description="List of invoice line items (description and amount)" ) wire_instructions: List[WireInstruction] = Field( description="Wire transfer instructions" ) # Main extraction model class ExtractedInvoiceFields(BaseModel): invoice: Invoice = Field(description="Invoice list-type fields") # Initialize the client client = LandingAIADE() # Parse the document to get markdown parse_response = client.parse( document=Path("/path/to/wire-transfer.pdf"), model="dpt-2-latest" ) # Convert Pydantic model to JSON schema schema = pydantic_to_json_schema(ExtractedInvoiceFields) # Extract structured data using the schema extract_response = client.extract( schema=schema, markdown=parse_response.markdown, model="extract-latest" ) # Display the extracted data print(extract_response.extraction) ``` ### Extraction Output The `extract` function returns an `ExtractResponse` object with the following fields: * **`extraction`**: The extracted key-value pairs as defined by your schema * **`extraction_metadata`**: Metadata showing which chunks were referenced for each extracted field * **`metadata`**: Processing information including credit usage, duration, filename, job ID, version, and schema validation errors For detailed information about the response structure, extraction metadata, and chunk references, go to [Extract JSON Response](./ade-extract-response). ## Classify: Getting Started The `classify` function classifies each page in a document by type. Provide your document and a list of classes, and the API assigns a class to each page. Use these examples as guides to get started with classifying with the library. ### Classify Local Files Use the `document` parameter to classify files from your filesystem. Pass the file path as a `Path` object. ```python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() classes = [ {"class": "invoice", "description": "A commercial bill with line items, totals, and payment terms"}, {"class": "bank_statement", "description": "A monthly summary of account transactions"}, {"class": "pay_stub"} ] response = client.classify( classes=json.dumps(classes), document=Path("/path/to/document.pdf"), model="classify-latest" ) for result in response.classification: print(f"Page {result.page}: {result.class_}") ``` ### Classify Remote URLs Use the `document_url` parameter to classify files from remote URLs (http, https, ftp, ftps). ```python theme={null} import json from landingai_ade import LandingAIADE client = LandingAIADE() classes = [ {"class": "invoice", "description": "A commercial bill with line items, totals, and payment terms"}, {"class": "bank_statement", "description": "A monthly summary of account transactions"} ] response = client.classify( classes=json.dumps(classes), document_url="https://example.com/document.pdf", model="classify-latest" ) for result in response.classification: print(f"Page {result.page}: {result.class_}") ``` ### Set Parameters The `classify` function accepts optional parameters to customize classification behavior. To see all available parameters, go to [ADE Classify API](https://docs.landing.ai/api-reference/tools/ade-classify). ```python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() classes = [ {"class": "invoice"}, {"class": "bank_statement"} ] response = client.classify( classes=json.dumps(classes), document=Path("/path/to/document.pdf"), model="classify-latest" ) ``` ### Classify Output The `classify` function returns a `ClassifyResponse` object with the following fields: * **`classification`**: List of `Classification` objects, one per page, each containing: * **`class_`**: The predicted class label, or `'unknown'` if the page could not be classified. Note: `class_` is used instead of `class` because `class` is a reserved keyword in Python. * **`page`**: The zero-indexed page number * **`reason`**: A brief explanation of the classification (for debugging) * **`suggested_class`**: A proposed class when the prediction is `'unknown'` * **`metadata`**: Processing information (credit usage, duration, filename, job ID, page count, version) For detailed information about the response structure, see [JSON Response for Classification](./ade-classify-response). #### Common Use Cases for ClassifyResponse Fields **Get classification for each page:** ```python theme={null} for result in response.classification: print(f"Page {result.page}: {result.class_}") ``` **Filter pages by class:** ```python theme={null} invoices = [r for r in response.classification if r.class_ == "invoice"] print(f"Found {len(invoices)} invoice pages") ``` **Handle pages that could not be classified:** ```python theme={null} unknown = [r for r in response.classification if r.class_ == "unknown"] for r in unknown: print(f"Page {r.page}: suggested class is {r.suggested_class}") ``` ## Section: Getting Started The `section` function analyzes a parsed document and generates a hierarchical table of contents. Use these examples as guides to get started with sectioning with the library. **Pass Markdown Content** The library supports a few methods for passing the Markdown content for sectioning: * Section data directly from the [parse response](#section-from-parse-response) * Section data from a local [Markdown file](#section-from-markdown-files) * Section data from a Markdown file at a remote URL: `markdown_url="https://example.com/file.md"` ### Section from Parse Response After parsing a document, you can pass the Markdown string directly from the `ParseResponse` to the section function without saving it to a file. ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Parse the document parse_response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest" ) # Section using the Markdown string from parse response section_response = client.section( markdown=parse_response.markdown, # Pass Markdown string directly model="section-latest" ) # Access the table of contents for entry in section_response.table_of_contents: indent = " " * (entry.level - 1) print(f"{indent}{entry.section_number}. {entry.title}") ``` ### Section from Markdown Files If you already have a Markdown file (from a previous parsing operation), you can section it directly. Use the `markdown` parameter for local Markdown files or `markdown_url` for remote Markdown files. ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Section from a local Markdown file section_response = client.section( markdown=Path("/path/to/parsed_output.md"), model="section-latest" ) # Or section from a remote Markdown file section_response = client.section( markdown_url="https://example.com/document.md", model="section-latest" ) # Access the table of contents for entry in section_response.table_of_contents: indent = " " * (entry.level - 1) print(f"{indent}{entry.section_number}. {entry.title}") ``` ### Set Parameters The `section` function accepts optional parameters to customize sectioning behavior. To see all available parameters, go to [ADE Section API](https://docs.landing.ai/api-reference/tools/ade-section). ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() section_response = client.section( markdown=Path("/path/to/parsed_output.md"), guidelines="Treat each numbered article as a top-level section", model="section-latest" ) ``` ### Section Output The `section` function returns a `SectionResponse` object with the following fields: * **`table_of_contents`**: List of `SectionTOCEntry` objects, each containing: * **`title`**: The generated section heading text * **`level`**: The hierarchy depth (1 = top-level, 2 = subsection, 3 = sub-subsection, and so on) * **`section_number`**: The hierarchical number (for example, `"1"`, `"1.2"`, `"1.2.3"`) * **`start_reference`**: The chunk ID where this section begins, corresponding to a `chunks[].id` value from the parse response * **`table_of_contents_md`**: Markdown-formatted TOC string with anchor links * **`metadata`**: Processing information (credit usage, duration, filename, job ID, version) For detailed information about the response structure, see [JSON Response for Sectioning](./ade-section-response). ## Split: Getting Started The `split` function classifies and separates a parsed document into multiple sub-documents based on Split Rules you define. Use these examples as guides to get started with splitting with the library. **Pass Markdown Content** The library supports a few methods for passing the Markdown content for splitting: * Split data directly from the [parse response](#split-from-parse-response) * Split data from a local [Markdown file](#split-from-markdown-files) * Split data from a Markdown file at a remote URL: `markdown_url="https://example.com/file.md"` **Define Split Rules** Split Rules define how the API classifies and separates your document. Each Split Rule consists of: * `name`: The Split Type name (required) * `description`: Additional context about what this Split Type represents (optional) * `identifier`: A field that makes each instance unique, used to create separate splits (optional) For more information about Split Rules, see [Split Rules](./ade-split#split-rules). ### Split from Parse Response After parsing a document, you can pass the Markdown string directly from the `ParseResponse` to the split function without saving it to a file. ```python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Parse the document parse_response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest" ) # Define Split Rules split_class = [ { "name": "Bank Statement", "description": "Document from a bank that summarizes all account activity over a period of time." }, { "name": "Pay Stub", "description": "Document that details an employee's earnings, deductions, and net pay for a specific pay period.", "identifier": "Pay Stub Date" } ] # Split using the Markdown string from parse response split_response = client.split( split_class=json.dumps(split_class), markdown=parse_response.markdown, # Pass Markdown string directly model="split-latest" ) # Access the splits for split in split_response.splits: print(f"Classification: {split.classification}") print(f"Identifier: {split.identifier}") print(f"Pages: {split.pages}") ``` ### Split from Markdown Files If you already have a Markdown file (from a previous parsing operation), you can split it directly. Use the `markdown` parameter for local Markdown files or `markdown_url` for remote Markdown files. ```python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Define Split Rules split_class = [ { "name": "Invoice", "description": "A document requesting payment for goods or services.", "identifier": "Invoice Number" }, { "name": "Receipt", "description": "A document acknowledging that payment has been received." } ] # Split from a local Markdown file split_response = client.split( split_class=json.dumps(split_class), markdown=Path("/path/to/parsed_output.md"), model="split-latest" ) # Or split from a remote Markdown file split_response = client.split( split_class=json.dumps(split_class), markdown_url="https://example.com/document.md", model="split-latest" ) # Access the splits for split in split_response.splits: print(f"Classification: {split.classification}") if split.identifier: print(f"Identifier: {split.identifier}") print(f"Number of pages: {len(split.pages)}") print(f"Markdown content: {split.markdowns[0][:100]}...") ``` ### Set Parameters The `split` function accepts optional parameters to customize split behavior. To see all available parameters, go to [ADE Split API](https://docs.landing.ai/api-reference/tools/ade-split). ```python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() split_response = client.split( split_class=json.dumps([ {"name": "Section A", "description": "Introduction section"}, {"name": "Section B", "description": "Main content section"} ]), markdown=Path("/path/to/parsed_output.md"), model="split-latest" ) ``` ### Split Output The `split` function returns a `SplitResponse` object with the following fields: * **`splits`**: List of `Split` objects, each containing: * **`classification`**: The Split Type name assigned to this sub-document * **`identifier`**: The unique identifier value (or `None` if no identifier was specified) * **`pages`**: List of zero-indexed page numbers that belong to this split * **`markdowns`**: List of Markdown content strings, one for each page * **`metadata`**: Processing information (credit usage, duration, filename, job ID, page count, version) For detailed information about the response structure, see [JSON Response for Splitting](./ade-split-response). #### Common Use Cases for SplitResponse Fields **Access all splits by classification:** ```python theme={null} for split in split_response.splits: print(f"Split Type: {split.classification}") print(f"Pages included: {split.pages}") ``` **Filter splits by classification:** ```python theme={null} invoices = [split for split in split_response.splits if split.classification == "Invoice"] print(f"Found {len(invoices)} invoices") ``` **Access Markdown content for each split:** ```python theme={null} for split in split_response.splits: print(f"Classification: {split.classification}") for i, markdown in enumerate(split.markdowns): print(f" Page {split.pages[i]} Markdown: {markdown[:100]}...") ``` **Group splits by identifier:** ```python theme={null} from collections import defaultdict splits_by_id = defaultdict(list) for split in split_response.splits: if split.identifier: splits_by_id[split.identifier].append(split) for identifier, splits in splits_by_id.items(): print(f"Identifier '{identifier}': {len(splits)} split(s)") ``` ## Save Output Use the optional `save_to` parameter to save the full API response as a JSON file. The parameter is available on `parse`, `extract`, and `split`. ### Use the Default File Name Pass a directory path. The library names the file using the input document's filename and the function called (for example, `document_parse_output.json`). ```python Parse theme={null} # Saves as: ./output/document_parse_output.json response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest", save_to="./output" ) ``` ```python Extract theme={null} # Saves as: ./output/document_extract_output.json extract_response = client.extract( schema=schema_json, markdown=Path("/path/to/document.md"), model="extract-latest", save_to="./output" ) ``` ```python Split theme={null} # Saves as: ./output/document_split_output.json split_response = client.split( split_class=json.dumps(split_class), markdown=Path("/path/to/document.md"), model="split-latest", save_to="./output" ) ``` When passing Markdown content as a string (`markdown=parse_response.markdown`), the library cannot derive a filename from the content. In this situation, use [Set the File Name](#set-the-file-name) instead. ### Set the File Name Pass a path ending in `.json` to choose the exact location and filename. ```python Parse theme={null} response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest", save_to="./output/my_parse_results.json" ) ``` ```python Extract theme={null} extract_response = client.extract( schema=schema_json, markdown=parse_response.markdown, model="extract-latest", save_to="./output/document_extract_output.json" ) ``` ```python Split theme={null} split_response = client.split( split_class=json.dumps(split_class), markdown=parse_response.markdown, model="split-latest", save_to="./output/document_split_output.json" ) ``` ### Save the Markdown Field The `parse` response includes a `markdown` field that you can pass directly to other functions in the same script. To save the Markdown for downstream tasks, write it to a file: ```python theme={null} with open("output.md", "w", encoding="utf-8") as f: f.write(response.markdown) ``` # TypeScript Library Source: https://docs.landing.ai/ade/ade-typescript Process documents using the ADE TypeScript library. The [ade-typescript](https://github.com/landing-ai/ade-typescript) library is a lightweight TypeScript library you can use for parsing documents, classifying pages, extracting data, generating tables of contents, and splitting documents into sub-documents. The library is automatically generated from our API specification, ensuring you have access to the latest endpoints and parameters. ## Install the Library ```bash theme={null} npm install landingai-ade ``` ## Set the API Key as an Environment Variable To use the library, first [generate an API key](https://ade.landing.ai/my/settings/api-key). Save the key to a `.zshrc` file or another secure location on your computer. Then export the key as an environment variable. ```bash theme={null} ``` When initializing the client, the library automatically reads from the `VISION_AGENT_API_KEY` environment variable: ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); ``` Alternatively, you can explicitly pass the API key when initializing the client: ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE({ apikey: process.env.VISION_AGENT_API_KEY }); ``` For more information about API keys and alternate methods for setting the API key, go to [API Key](./agentic-api-key). ## Use with EU Endpoints By default, the library uses the US endpoints. If your API key is from the EU endpoint, set the `environment` parameter to `eu` when initializing the client. ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE({ environment: "eu", }); // ... rest of your code ``` For more information about using Agentic Document Extraction in the EU, go to [European Union (EU)](./ade-eu). ## Parse: Getting Started The `parse` method converts documents into structured Markdown with chunk and grounding metadata. Use these examples as guides to get started with parsing with the library. ### Parse Local Files Use the `document` parameter to parse files from your filesystem. Pass the file as a read stream using `fs.createReadStream()`. ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Replace with your file path const response = await client.parse({ document: fs.createReadStream("/path/to/file/document"), model: "dpt-2-latest", saveTo: "./output" }); console.log(response.chunks); ``` ### Parse Remote URLs Use the `document` parameter with `fetch()` to parse files from remote URLs (http, https). ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Parse a remote file const response = await client.parse({ document: await fetch("https://example.com/document.pdf"), model: "dpt-2-latest", saveTo: "./output" }); console.log(response.chunks); ``` ### Set Parameters The `parse` method accepts optional parameters to customize parsing behavior. To see all available parameters, go to [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse). Pass these parameters directly to the `parse()` method. ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const response = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest", split: "page" }); ``` ### Parse Jobs The `parseJobs` resource enables you to asynchronously parse documents that are up to 1,000 pages or 1 GB. For more information about parse jobs, go to [Parse Large Files (Parse Jobs)](./ade-parse-async). Here is the basic workflow for working with parse jobs: 1. Start a parse job. 2. Copy the `job_id` in the response. 3. Get the results from the parsing job with the `job_id`. This script contains the full workflow: ```typescript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Step 1: Create a parse job const job = await client.parseJobs.create({ document: fs.createReadStream("/path/to/file/document"), model: "dpt-2-latest" }); const jobId = job.job_id; console.log(`Job ${jobId} created.`); // Step 2: Get the parsing results while (true) { const response = await client.parseJobs.get(jobId); if (response.status === "completed") { console.log(`Job ${jobId} completed.`); break; } console.log(`Job ${jobId}: ${response.status} (${(response.progress * 100).toFixed(0)}% complete)`); await new Promise(resolve => setTimeout(resolve, 5000)); } // Step 3: Access the parsed data const response = await client.parseJobs.get(jobId); console.log("Global Markdown:", response.data.markdown.substring(0, 200) + "..."); console.log(`Number of chunks: ${response.data.chunks.length}`); // Save Markdown output (useful if you plan to run extract on the Markdown) fs.writeFileSync("output.md", response.data.markdown, "utf-8"); ``` #### List Parse Jobs To list all async parse jobs associated with your API key, run this code: ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); // List all jobs const response = await client.parseJobs.list(); for (const job of response.jobs) { console.log(`Job ${job.job_id}: ${job.status}`); } ``` ### Work with Parse Response Data **Access all text chunks:** ```typescript theme={null} for (const chunk of response.chunks) { if (chunk.type === 'text') { console.log(`Chunk ${chunk.id}: ${chunk.markdown}`); } } ``` **Filter chunks by page:** ```typescript theme={null} const page0Chunks = response.chunks.filter(chunk => chunk.grounding.page === 0); console.log(page0Chunks); ``` **Get chunk locations:** ```typescript theme={null} for (const chunk of response.chunks) { const box = chunk.grounding.box; console.log(`Chunk at page ${chunk.grounding.page}: (${box.left}, ${box.top}, ${box.right}, ${box.bottom})`); } ``` **Identify the chunk type for each chunk:** ```typescript theme={null} for (const [chunkId, grounding] of Object.entries(response.grounding)) { console.log(`Chunk ${chunkId} has type: ${grounding.type}`); } ``` ## Extract: Getting Started The `extract` method extracts structured data from Markdown content using extraction schemas. Use these examples as guides to get started with extracting with the library. **Pass Markdown Content** The library supports a few methods for passing the Markdown content for extraction: * Extract data directly from the [parse response](#extract-from-parse-response) * Extract data from a local [Markdown file](#extract-from-markdown-files) * Extract data from a Markdown file at a remote URL: `markdown: await fetch("https://example.com/file.md")` **Pass the Extraction Schema** The library supports a few methods for passing the extraction schema: * [Zod schemas](#extraction-with-zod) * [JSON schema (inline)](#extraction-with-json-schema-inline) * [JSON schema file](#extraction-with-json-schema-file) ### Extract from Parse Response After parsing a document, you can pass the markdown string directly from the `ParseResponse` to the extract method without saving it to a file. ```typescript theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; // Define your extraction schema const schemaDict = { type: "object", properties: { employee_name: { type: "string", description: "The employee's full name" } } }; const client = new LandingAIADE(); const schemaJson = JSON.stringify(schemaDict); // Parse the document const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest" }); // Extract data using the markdown string from parse response const extractResponse = await client.extract({ schema: schemaJson, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Access the extracted data console.log(extractResponse.extraction); ``` ### Extract from Markdown Files If you already have a Markdown file (from a previous parsing operation), you can extract data directly from it. Use the `markdown` parameter with `fs.createReadStream()` for local Markdown files or with `fetch()` for remote Markdown files. ```typescript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; // Define your extraction schema const schemaDict = { type: "object", properties: { employee_name: { type: "string", description: "The employee's full name" }, employee_ssn: { type: "string", description: "The employee's Social Security Number" }, gross_pay: { type: "number", description: "The gross pay amount" } } }; const client = new LandingAIADE(); const schemaJson = JSON.stringify(schemaDict); // Extract from a local markdown file const extractResponse = await client.extract({ schema: schemaJson, markdown: fs.createReadStream("/path/to/output.md"), model: "extract-latest" }); // Or extract from a remote markdown file const extractResponse = await client.extract({ schema: schemaJson, markdown: await fetch("https://example.com/document.md"), model: "extract-latest" }); // Access the extracted data console.log(extractResponse.extraction); ``` ### Extraction with Zod Use Zod schemas to define your extraction schema in a type-safe way. Zod provides TypeScript type inference and runtime validation for your extracted data. To use Zod with the library, install `zod`: ```bash theme={null} npm install zod ``` After installing `zod`, run extraction with the library: ```typescript [expandable] theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; import { z } from "zod"; // Define your extraction schema as a Zod schema const PayStubSchema = z.object({ employee_name: z.string().describe("The employee's full name"), employee_ssn: z.string().describe("The employee's Social Security Number"), gross_pay: z.number().describe("The gross pay amount") }); // Extract TypeScript type from schema type PayStubData = z.infer; // Initialize the client const client = new LandingAIADE(); // First, parse the document to get markdown const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/pay-stub.pdf"), model: "dpt-2-latest" }); // Convert Zod schema to JSON schema const schema = JSON.stringify(z.toJSONSchema(PayStubSchema)); // Extract structured data using the schema const extractResponse = await client.extract({ schema: schema, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Access the extracted data with type safety const data = extractResponse.extraction as PayStubData; console.log(data); // Access extraction metadata to see which chunks were referenced console.log(extractResponse.extraction_metadata); ``` ### Extraction with JSON Schema (Inline) Define your extraction schema directly as a JSON string in your script. ```typescript [expandable] theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; // Define your extraction schema as an object const schemaDict = { type: "object", properties: { employee_name: { type: "string", description: "The employee's full name" }, employee_ssn: { type: "string", description: "The employee's Social Security Number" }, gross_pay: { type: "number", description: "The gross pay amount" } } }; // Initialize the client const client = new LandingAIADE(); // First, parse the document to get markdown const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/pay-stub.pdf"), model: "dpt-2-latest" }); // Convert schema object to JSON string const schemaJson = JSON.stringify(schemaDict); // Extract structured data using the schema const extractResponse = await client.extract({ schema: schemaJson, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Access the extracted data console.log(extractResponse.extraction); // Access extraction metadata to see which chunks were referenced console.log(extractResponse.extraction_metadata); ``` ### Extraction with JSON Schema File Load your extraction schema from a separate JSON file for better organization and reusability. For example, here is the `pay_stub_schema.json` file: ```json theme={null} { "type": "object", "properties": { "employee_name": { "type": "string", "description": "The employee's full name" }, "employee_ssn": { "type": "string", "description": "The employee's Social Security Number" }, "gross_pay": { "type": "number", "description": "The gross pay amount" } } } ``` You can pass the JSON file defined above in the following script: ```typescript [expandable] theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; // Initialize the client const client = new LandingAIADE(); // First, parse the document to get markdown const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/pay-stub.pdf"), model: "dpt-2-latest" }); // Load schema from JSON file const schemaJson = fs.readFileSync("pay_stub_schema.json", "utf-8"); // Extract structured data using the schema const extractResponse = await client.extract({ schema: schemaJson, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Access the extracted data console.log(extractResponse.extraction); // Access extraction metadata to see which chunks were referenced console.log(extractResponse.extraction_metadata); ``` ### Extract Nested Subfields Define nested Zod schemas to extract hierarchical data from documents. This approach organizes related information under meaningful section names. Define nested schemas before the main extraction schema. Otherwise, the nested schemas will not be defined when referenced. For example, to extract data from the **Patient Details** and **Emergency Contact Information** sections in this Medical Form, define separate schemas for each section, then combine them in a main schema. ```typescript [expandable] theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; import { z } from "zod"; // Define a nested schema for patient-specific information const PatientDetailsSchema = z.object({ patient_name: z.string().describe("Full name of the patient."), date: z.string().describe("Date the patient information form was filled out.") }); // Define a nested schema for emergency contact details const EmergencyContactInformationSchema = z.object({ emergency_contact_name: z.string().describe("Full name of the emergency contact person."), relationship_to_patient: z.string().describe("Relationship of the emergency contact to the patient."), primary_phone_number: z.string().describe("Primary phone number of the emergency contact."), secondary_phone_number: z.string().describe("Secondary phone number of the emergency contact."), address: z.string().describe("Full address of the emergency contact.") }); // Define the main extraction schema that combines all the nested schemas const PatientAndEmergencyContactInformationSchema = z.object({ patient_details: PatientDetailsSchema.describe("Information about the patient as provided in the form."), emergency_contact_information: EmergencyContactInformationSchema.describe("Details of the emergency contact person for the patient.") }); // Extract TypeScript type from schema type PatientAndEmergencyContactInformation = z.infer; // Initialize the client const client = new LandingAIADE(); // Parse the document to get markdown const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/medical-form.pdf"), model: "dpt-2-latest" }); // Convert Zod schema to JSON schema const schema = JSON.stringify(z.toJSONSchema(PatientAndEmergencyContactInformationSchema)); // Extract structured data using the schema const extractResponse = await client.extract({ schema: schema, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Display the extracted structured data console.log(extractResponse.extraction); ``` ### Extract Variable-Length Data with List Objects Use Zod's `z.array()` to extract repeatable data structures when you don't know how many items will appear. Common examples include line items in invoices, transaction records, or contact information for multiple people. For example, to extract variable-length wire instructions and line items from this Wire Transfer Form, use `z.array(DescriptionItemSchema)` for line items and `z.array(WireInstructionSchema)` for wire transfer details. ```typescript [expandable] theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; import { z } from "zod"; // Nested schemas for array fields const DescriptionItemSchema = z.object({ description: z.string().describe("Invoice or Bill Description"), amount: z.number().describe("Invoice or Bill Amount") }); const WireInstructionSchema = z.object({ bank_name: z.string().describe("Bank name"), bank_address: z.string().describe("Bank address"), bank_account_no: z.string().describe("Bank account number"), swift_code: z.string().describe("SWIFT code"), aba_routing: z.string().describe("ABA routing number"), ach_routing: z.string().describe("ACH routing number") }); // Invoice schema containing array fields const InvoiceSchema = z.object({ description_or_particular: z.array(DescriptionItemSchema).describe("List of invoice line items (description and amount)"), wire_instructions: z.array(WireInstructionSchema).describe("Wire transfer instructions") }); // Main extraction schema const ExtractedInvoiceFieldsSchema = z.object({ invoice: InvoiceSchema.describe("Invoice list-type fields") }); // Extract TypeScript type from schema type ExtractedInvoiceFields = z.infer; // Initialize the client const client = new LandingAIADE(); // Parse the document to get markdown const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/wire-transfer.pdf"), model: "dpt-2-latest" }); // Convert Zod schema to JSON schema const schema = JSON.stringify(z.toJSONSchema(ExtractedInvoiceFieldsSchema)); // Extract structured data using the schema const extractResponse = await client.extract({ schema: schema, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Display the extracted data console.log(extractResponse.extraction); ``` ## Classify: Getting Started The `classify` method classifies each page in a document by type. Provide your document and a list of classes, and the API assigns a class to each page. Use these examples as guides to get started with classifying with the library. ### Classify Local Files Use the `document` parameter to classify files from your filesystem. Pass the file as a read stream using `fs.createReadStream()`. ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const classes = [ { class: "invoice", description: "A commercial bill with line items, totals, and payment terms" }, { class: "bank_statement", description: "A monthly summary of account transactions" }, { class: "pay_stub" } ]; const classesJson = JSON.stringify(classes); const response = await client.classify({ classes: classesJson as any, document: fs.createReadStream("/path/to/document.pdf"), model: "classify-latest" }); for (const result of response.classification) { console.log(`Page ${result.page}: ${result.class}`); } ``` ### Classify Remote URLs Use the `document_url` parameter to classify files from remote URLs (http, https). ```typescript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); const classes = [ { class: "invoice", description: "A commercial bill with line items, totals, and payment terms" }, { class: "bank_statement", description: "A monthly summary of account transactions" } ]; const classesJson = JSON.stringify(classes); const response = await client.classify({ classes: classesJson as any, document_url: "https://example.com/document.pdf", model: "classify-latest" }); for (const result of response.classification) { console.log(`Page ${result.page}: ${result.class}`); } ``` ### Set Parameters The `classify` method accepts optional parameters to customize classification behavior. To see all available parameters, go to [ADE Classify API](https://docs.landing.ai/api-reference/tools/ade-classify). ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const classes = [ { class: "invoice" }, { class: "bank_statement" } ]; const classesJson = JSON.stringify(classes); const response = await client.classify({ classes: classesJson as any, document: fs.createReadStream("/path/to/document.pdf"), model: "classify-latest" }); ``` ### Classify Output The `classify` method returns a `ClassifyResponse` object with the following fields: * **`classification`**: Array of `Classification` objects, one per page, each containing: * **`class`**: The predicted class label, or `'unknown'` if the page could not be classified * **`page`**: The zero-indexed page number * **`reason`**: A brief explanation of the classification (for debugging) * **`suggested_class`**: A proposed class when the prediction is `'unknown'` * **`metadata`**: Processing information (credit usage, duration, filename, job ID, page count, version) For detailed information about the response structure, see [JSON Response for Classification](./ade-classify-response). #### Work with Classify Response Data **Get classification for each page:** ```typescript theme={null} for (const result of response.classification) { console.log(`Page ${result.page}: ${result.class}`); } ``` **Filter pages by class:** ```typescript theme={null} const invoices = response.classification.filter(r => r.class === "invoice"); console.log(`Found ${invoices.length} invoice pages`); ``` **Handle pages that could not be classified:** ```typescript theme={null} const unknown = response.classification.filter(r => r.class === "unknown"); for (const r of unknown) { console.log(`Page ${r.page}: suggested class is ${r.suggested_class}`); } ``` ## Section: Getting Started The `section` method analyzes a parsed document and generates a hierarchical table of contents. Use these examples as guides to get started with sectioning with the library. **Pass Markdown Content** The library supports a few methods for passing the Markdown content for sectioning: * Section data directly from the [parse response](#section-from-parse-response) * Section data from a local [Markdown file](#section-from-markdown-files) * Section data from a Markdown file at a remote URL: `markdown: await fetch("https://example.com/file.md")` ### Section from Parse Response After parsing a document, you can pass the Markdown string directly from the `ParseResponse` to the section method without saving it to a file. ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Parse the document const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest" }); // Section using the Markdown string from parse response const sectionResponse = await client.section({ markdown: parseResponse.markdown, // Pass Markdown string directly model: "section-latest" }); // Access the table of contents for (const entry of sectionResponse.table_of_contents) { const indent = " ".repeat(entry.level - 1); console.log(`${indent}${entry.section_number}. ${entry.title}`); } ``` ### Section from Markdown Files If you already have a Markdown file (from a previous parsing operation), you can section it directly. Use the `markdown` parameter for local Markdown files or the `markdown` parameter with `fetch()` for remote Markdown files. ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Section from a local Markdown file const sectionResponse = await client.section({ markdown: fs.createReadStream("/path/to/parsed_output.md"), model: "section-latest" }); // Or section from a remote Markdown file const sectionResponse = await client.section({ markdown: await fetch("https://example.com/document.md"), model: "section-latest" }); // Access the table of contents for (const entry of sectionResponse.table_of_contents) { const indent = " ".repeat(entry.level - 1); console.log(`${indent}${entry.section_number}. ${entry.title}`); } ``` ### Set Parameters The `section` method accepts optional parameters to customize sectioning behavior. To see all available parameters, go to [ADE Section API](https://docs.landing.ai/api-reference/tools/ade-section). ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const sectionResponse = await client.section({ markdown: fs.createReadStream("/path/to/parsed_output.md"), guidelines: "Treat each numbered article as a top-level section", model: "section-latest" }); ``` ### Section Output The `section` method returns a `SectionResponse` object with the following fields: * **`table_of_contents`**: Array of `SectionTOCEntry` objects, each containing: * **`title`**: The generated section heading text * **`level`**: The hierarchy depth (1 = top-level, 2 = subsection, 3 = sub-subsection, and so on) * **`section_number`**: The hierarchical number (for example, `"1"`, `"1.2"`, `"1.2.3"`) * **`start_reference`**: The chunk ID where this section begins, corresponding to a `chunks[].id` value from the parse response * **`table_of_contents_md`**: Markdown-formatted TOC string with anchor links * **`metadata`**: Processing information (credit usage, duration, filename, job ID, version) For detailed information about the response structure, see [JSON Response for Sectioning](./ade-section-response). ## Split: Getting Started The `split` method classifies and separates a parsed document into multiple sub-documents based on Split Rules you define. Use these examples as guides to get started with splitting with the library. **Pass Markdown Content** The library supports a few methods for passing the Markdown content for splitting: * Split data directly from the [parse response](#split-from-parse-response) * Split data from a local [Markdown file](#split-from-markdown-files) * Split data from a Markdown file at a remote URL: `markdown: await fetch("https://example.com/file.md")` **Define Split Rules** Split Rules define how the API classifies and separates your document. Each Split Rule consists of: * `name`: The Split Type name (required) * `description`: Additional context about what this Split Type represents (optional) * `identifier`: A field that makes each instance unique, used to create separate splits (optional) For more information about Split Rules, see [Split Rules](./ade-split#split-rules). ### Split from Parse Response After parsing a document, you can pass the Markdown string directly from the `ParseResponse` to the split method without saving it to a file. ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Parse the document const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest" }); // Define Split Rules const splitClass = [ { name: "Bank Statement", description: "Document from a bank that summarizes all account activity over a period of time." }, { name: "Pay Stub", description: "Document that details an employee's earnings, deductions, and net pay for a specific pay period.", identifier: "Pay Stub Date" } ]; const splitClassJson = JSON.stringify(splitClass); // Split using the Markdown string from parse response const splitResponse = await client.split({ split_class: splitClassJson, markdown: parseResponse.markdown, // Pass Markdown string directly model: "split-latest" }); // Access the splits for (const split of splitResponse.splits) { console.log(`Classification: ${split.classification}`); console.log(`Identifier: ${split.identifier}`); console.log(`Pages: ${split.pages}`); } ``` ### Split from Markdown Files If you already have a Markdown file (from a previous parsing operation), you can split it directly. Use the `markdown` parameter for local Markdown files or the `markdown` parameter with `fetch()` for remote Markdown files. ```typescript theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Define Split Rules const splitClass = [ { name: "Invoice", description: "A document requesting payment for goods or services.", identifier: "Invoice Number" }, { name: "Receipt", description: "A document acknowledging that payment has been received." } ]; const splitClassJson = JSON.stringify(splitClass); // Split from a local Markdown file const splitResponse = await client.split({ split_class: splitClassJson, markdown: fs.createReadStream("/path/to/parsed_output.md"), model: "split-latest" }); // Or split from a remote Markdown file const splitResponse = await client.split({ split_class: splitClassJson, markdown: await fetch("https://example.com/document.md"), model: "split-latest" }); // Access the splits for (const split of splitResponse.splits) { console.log(`Classification: ${split.classification}`); if (split.identifier) { console.log(`Identifier: ${split.identifier}`); } console.log(`Number of pages: ${split.pages.length}`); console.log(`Markdown content: ${split.markdowns[0].substring(0, 100)}...`); } ``` ### Set Parameters The `split` method accepts optional parameters to customize split behavior. To see all available parameters, go to [ADE Split API](https://docs.landing.ai/api-reference/tools/ade-split). ```typescript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const splitClass = [ { name: "Section A", description: "Introduction section" }, { name: "Section B", description: "Main content section" } ]; const splitClassJson = JSON.stringify(splitClass); const splitResponse = await client.split({ split_class: splitClassJson, markdown: fs.createReadStream("/path/to/parsed_output.md"), model: "split-latest" }); ``` ### Split Output The `split` method returns a `SplitResponse` object with the following fields: * **`splits`**: Array of `Split` objects, each containing: * **`classification`**: The Split Type name assigned to this sub-document * **`identifier`**: The unique identifier value (or `null` if no identifier was specified) * **`pages`**: Array of zero-indexed page numbers that belong to this split * **`markdowns`**: Array of Markdown content strings, one for each page * **`metadata`**: Processing information (credit usage, duration, filename, job ID, page count, version) For detailed information about the response structure, see [JSON Response for Splitting](./ade-split-response). ### Work with Split Response Data **Access all splits by classification:** ```typescript theme={null} for (const split of splitResponse.splits) { console.log(`Split Type: ${split.classification}`); console.log(`Pages included: ${split.pages}`); } ``` **Filter splits by classification:** ```typescript theme={null} const invoices = splitResponse.splits.filter(split => split.classification === "Invoice"); console.log(`Found ${invoices.length} invoices`); ``` **Access Markdown content for each split:** ```typescript theme={null} for (const split of splitResponse.splits) { console.log(`Classification: ${split.classification}`); for (let i = 0; i < split.markdowns.length; i++) { console.log(` Page ${split.pages[i]} Markdown: ${split.markdowns[i].substring(0, 100)}...`); } } ``` **Group splits by identifier:** ```typescript theme={null} const splitsByIdentifier = new Map>(); for (const split of splitResponse.splits) { if (split.identifier) { const existing = splitsByIdentifier.get(split.identifier) || []; existing.push(split); splitsByIdentifier.set(split.identifier, existing); } } for (const [identifier, splits] of splitsByIdentifier.entries()) { console.log(`Identifier '${identifier}': ${splits.length} split(s)`); } ``` ## Save Output Use the optional `saveTo` parameter to save the full API response as a JSON file. The parameter is available on `parse`, `extract`, and `split`. The directory is created automatically if it doesn't exist. ### Use the Default File Name Pass a directory path. The library names the file using the input document's filename and the function called (for example, `document_parse_output.json`). ```typescript Parse theme={null} // Saves as: ./output/document_parse_output.json const response = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest", saveTo: "./output" }); ``` ```typescript Extract theme={null} // Saves as: ./output/document_extract_output.json const extractResponse = await client.extract({ schema: schemaJson, markdown: fs.createReadStream("/path/to/document.md"), model: "extract-latest", saveTo: "./output" }); ``` ```typescript Split theme={null} // Saves as: ./output/document_split_output.json const splitResponse = await client.split({ split_class: splitClassJson, markdown: fs.createReadStream("/path/to/document.md"), model: "split-latest", saveTo: "./output" }); ``` When passing Markdown content as a string (`markdown: parseResponse.markdown`), the library cannot derive a filename from the content. In this situation, use [Set the File Name](#set-the-file-name) instead. ### Set the File Name Pass a path ending in `.json` to choose the exact location and filename. ```typescript Parse theme={null} const response = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest", saveTo: "./output/my_parse_results.json" }); ``` ```typescript Extract theme={null} const extractResponse = await client.extract({ schema: schemaJson, markdown: parseResponse.markdown, model: "extract-latest", saveTo: "./output/document_extract_output.json" }); ``` ```typescript Split theme={null} const splitResponse = await client.split({ split_class: splitClassJson, markdown: parseResponse.markdown, model: "split-latest", saveTo: "./output/document_split_output.json" }); ``` ### Save the Markdown Field The `parse` response includes a `markdown` field that you can pass directly to other functions in the same script. To save the Markdown for downstream tasks, write it to a file: ```typescript theme={null} fs.writeFileSync("output.md", response.markdown, "utf-8"); ``` # Parse Documents Source: https://docs.landing.ai/ade/parse Convert documents into structured Markdown, chunks, and metadata with exact page and coordinate references. Use the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) to convert documents into structured Markdown, chunks, and metadata. The API identifies elements like text, tables, and form fields with exact page and coordinate references. After parsing, you can: * Use the Markdown output directly in your applications * Run [field extraction](./ade-extract) on the parsed content * [Generate a hierarchical table of contents](./ade-section) for navigation and retrieval * [Classify and split](./ade-split) multi-document files into separate documents ## Use ADE Parse to Parse Documents Use the ADE Parse API to parse data from documents. See the full ADE Parse API reference [here](https://docs.landing.ai/api-reference/tools/ade-parse). To get detailed information about the API response, go to [JSON Response for Parsing](./ade-json-response). ### Specify Documents to Parse The ADE Parse API offers two parameters for specifying the document you want to parse: * `document`: Specify the actual file you want to parse. * `document_url`: Include the URL to the file that you want to parse. ### Set Up Splits for Parsing The `split` parameter is different from the [ADE Split API](./ade-split). If your goal is to separate a document into sub-documents after parsing, use the ADE Split API, not the `split` parameter. The ADE Parse API includes an optional `split` parameter that controls how the parsed content is organized in the response. This is how to include the `split` parameter when calling the ADE Parse API. ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest'\ - F 'split=page' # Optional split parameter ``` #### Omit the Split Parameter When you omit the `split` parameter, the API returns the entire document as a single split. All chunks from all pages are grouped together in one split object with `class: "full"` and `identifier: "full"`. Omit the `split` parameter when you need to: * Process the entire document as a single unit * Maintain document context across pages * Extract data that spans multiple pages #### Use Page-Level Splits When you use page-level splits (When you set `split=page`), the API organizes chunks by page. For multi-page documents, this creates one split per page. Each split has `class: "page"` and an identifier like `page_0`, `page_1`, etc. Use page-level splits (set the `split` parameter to `page`) when you need to: * Process pages independently * Extract data from specific pages * Build page-by-page workflows * Reduce content size for downstream processing ## Add Custom Prompts for Figure Descriptions Use the optional `custom_prompts` parameter to customize how Agentic Document Extraction describes figures during parsing. For more information, see [Custom Prompts for Figure Descriptions](./ade-parse-custom-prompts). ## Example: Parse a Document with the API This example shows how to parse a document with the ADE Parse API and save the Markdown output to a file. Materials: * Sample PDF: Wire Transfer Form ```python [expandable] theme={null} import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/parse' # Upload a document document = open('wire-transfer.pdf', 'rb') files = {'document': document} data = {'model': 'dpt-2-latest'} response = requests.post(url, files=files, data=data, headers=headers) response_data = response.json() # Print the full response print(response_data) # Extract and save the markdown content if 'markdown' in response_data: markdown_content = response_data['markdown'] # Save markdown content to file with open('markdown-wire-transfer.md', 'w', encoding='utf-8') as f: f.write(markdown_content) print("\nMarkdown content saved to a Markdown file.") else: print("No 'markdown' field found in the response") # Close the file document.close() ``` The full response will be similar to the JSON below. Notice that each chunk has an `id`. For example, the first chunk is the text "# WIRE TRANSFER FORM". The `id` for that chunk is `33335548-e7c3-40bd-898e-4f23d6c99d34`. ```json [expandable] theme={null} { 'markdown':"\n\n# WIRE TRANSFER FORM\n\n\n\nInvoice Information\n\nInvoice Description: Professional consulting services - Q3 2025\n\nTotal Invoice Amount: $15,750.00 USD\n\n\n\nBeneficiary Bank Information\n\nBank Name: JPMorgan Chase Bank, N.A.\n\nBank Address: 270 Park Avenue, New York, NY 10017, USA\n\nBank Account Number: 4578923456789012\n\nSWIFT Code: CHASUS33\n\nABA Routing Number: 021000021\n\nACH Routing Number: 021000021\n\n\n\nInvoice Line Items\n
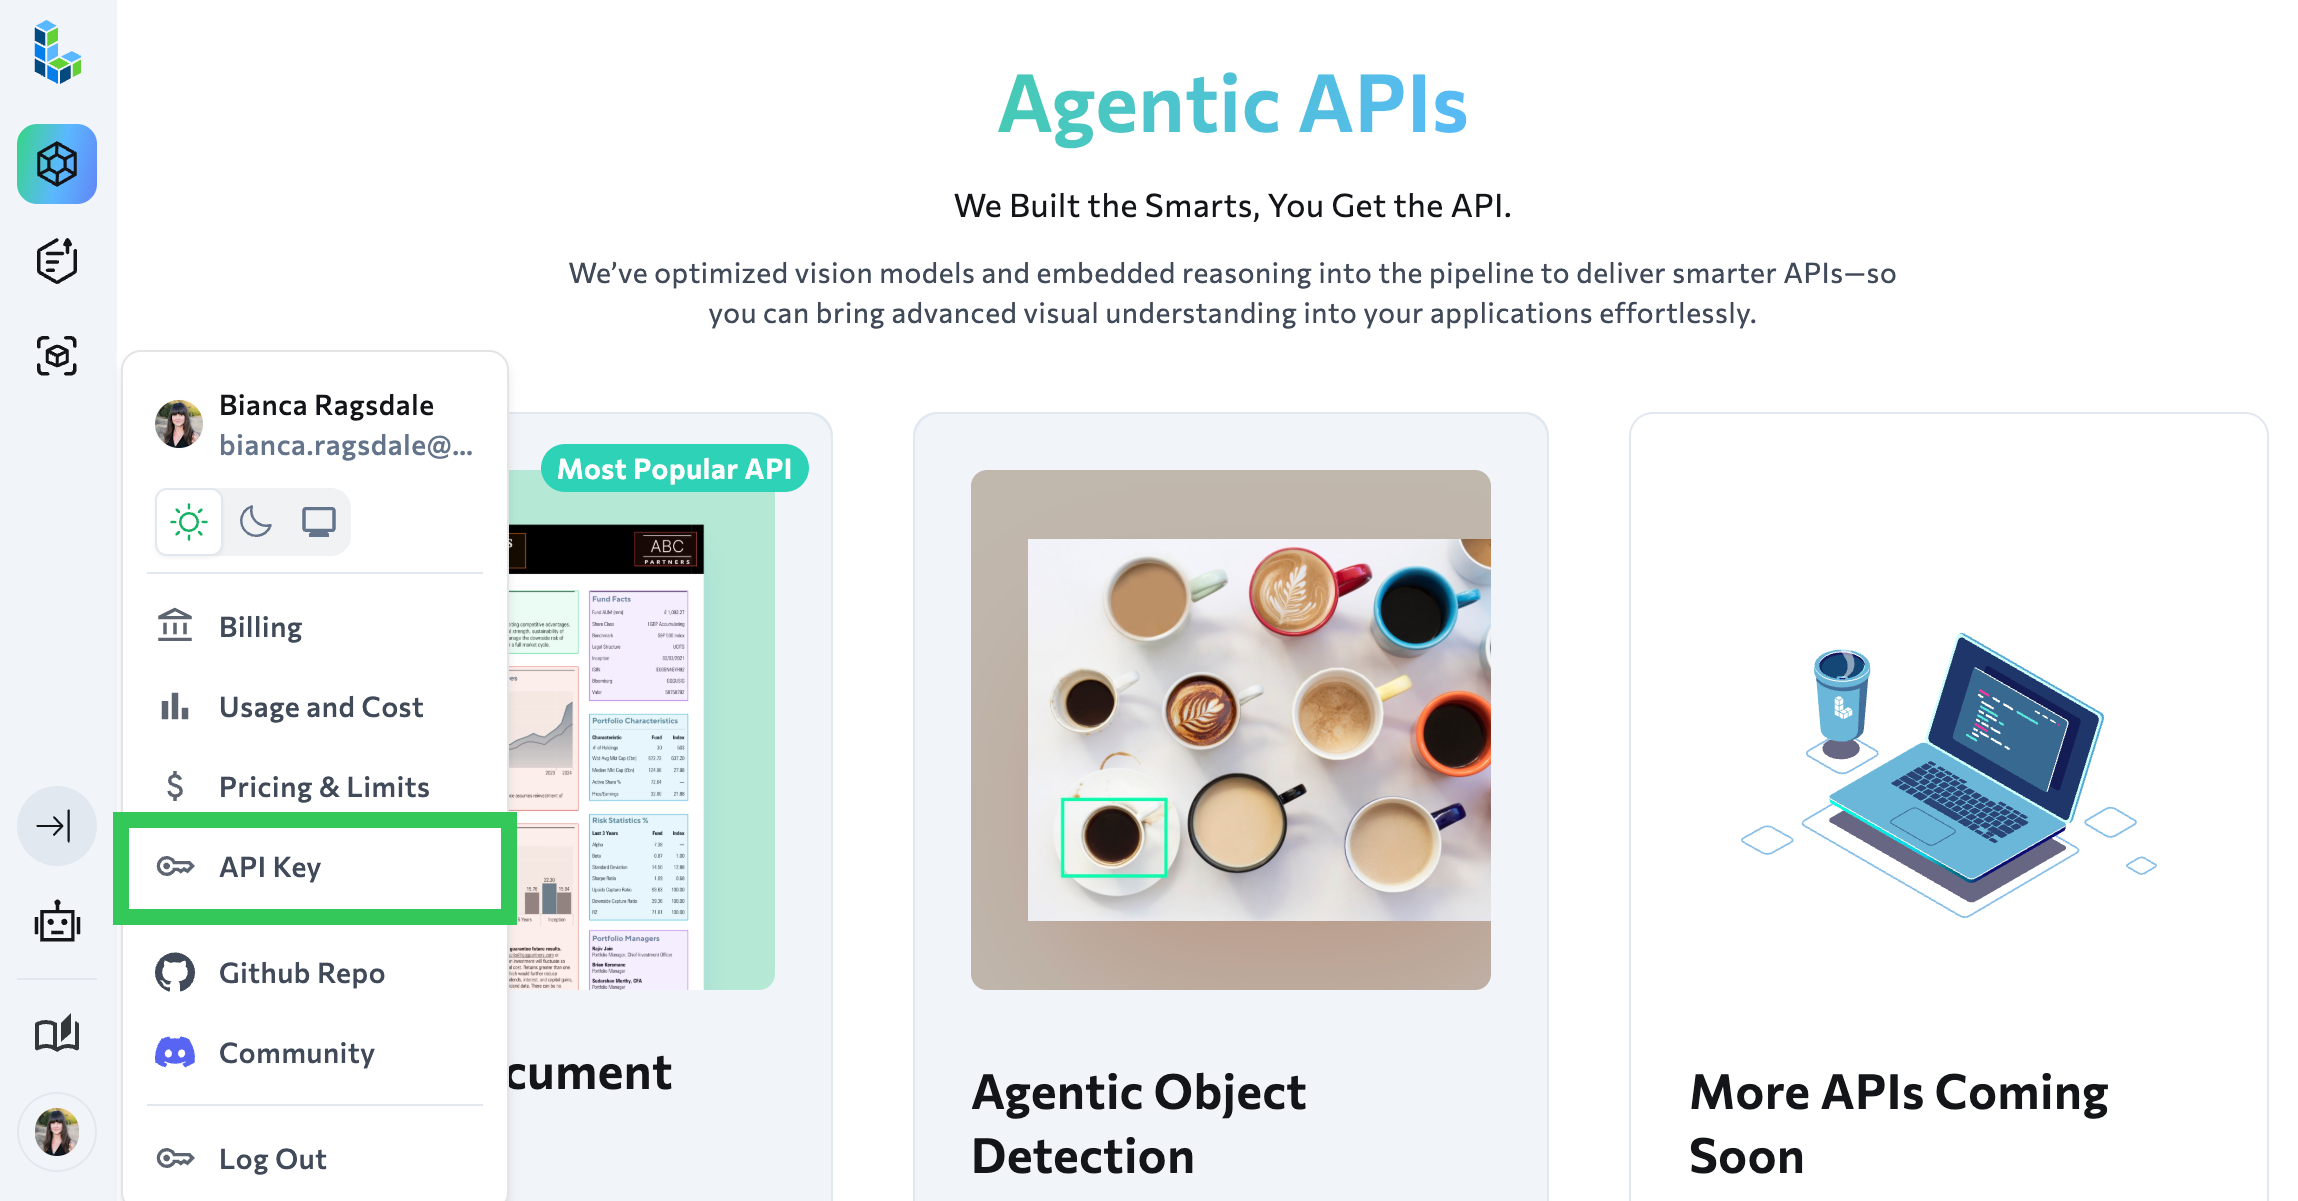
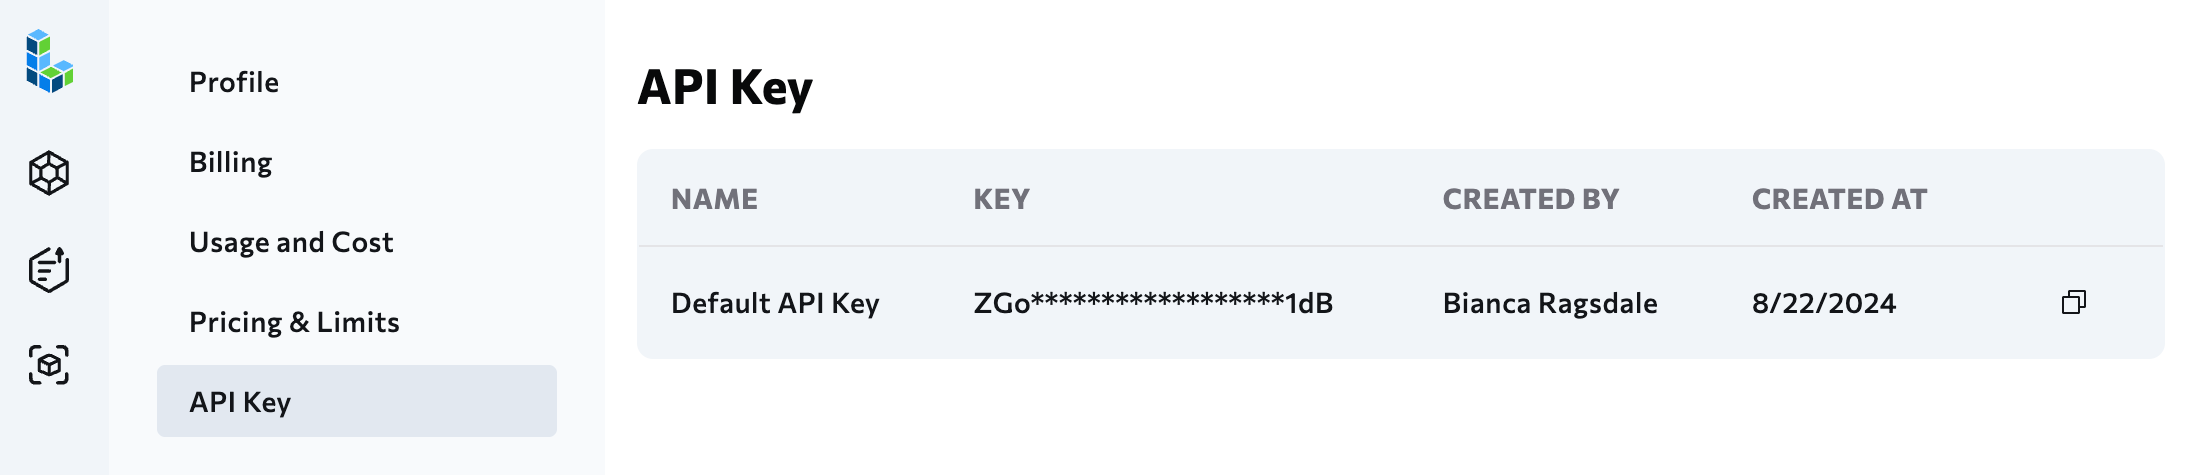
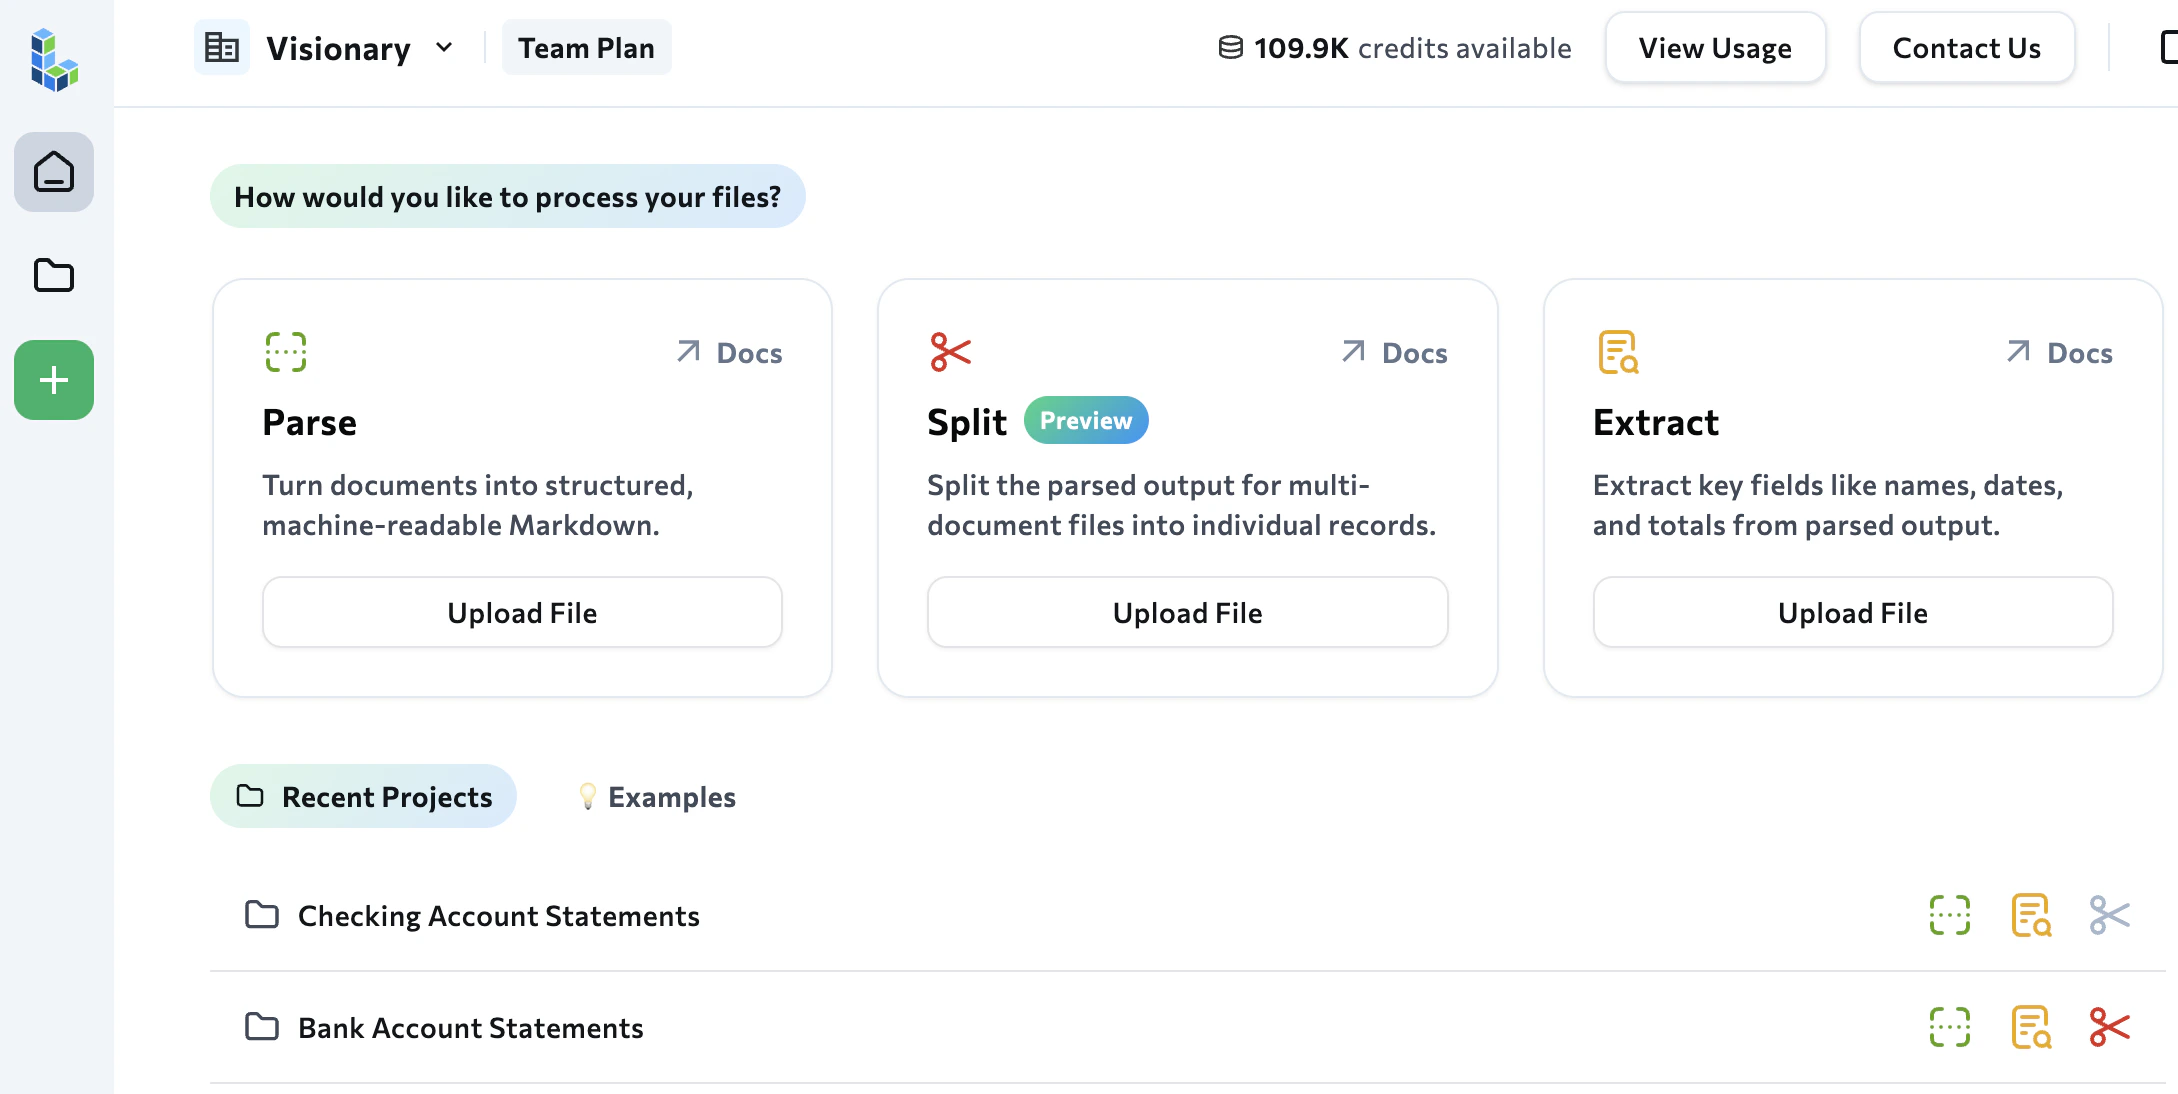
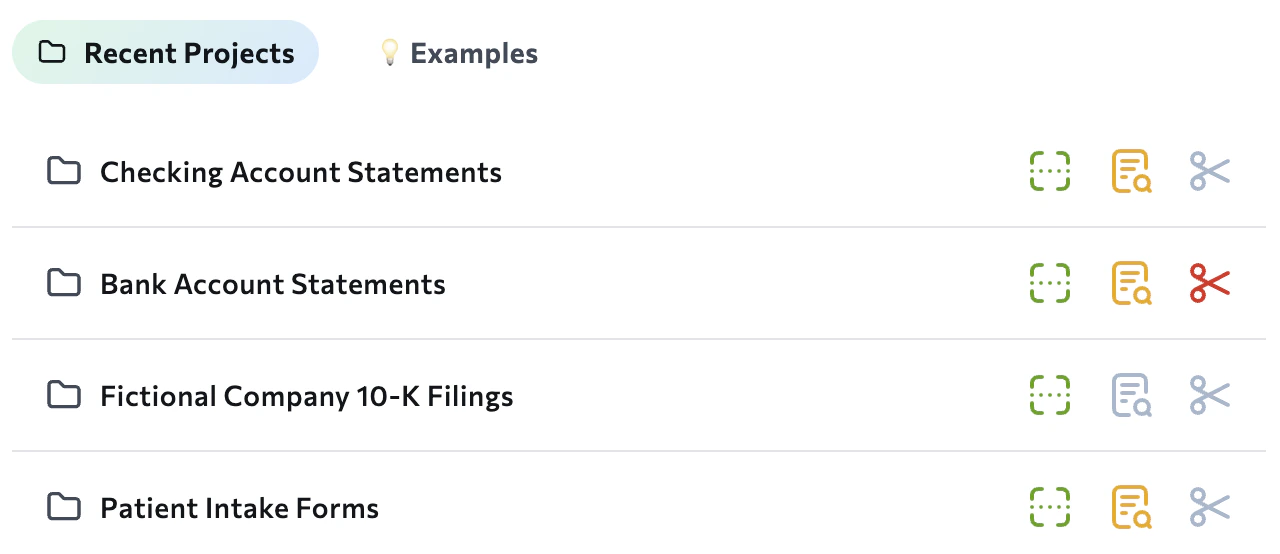
DescriptionAmount
Strategic planning consultation (40 hours @ $150/hr)$6,000.00
Market analysis report preparation$3,500.00
Implementation roadmap development$2,250.00
Executive presentation materials$1,500.00
Follow-up consultation sessions (15 hours @ $150/hr)$2,250.00
Travel expenses (reimbursable)$250.00
TOTAL$15,750.00
\n\n\n\nWire Transfer Instructions\n\nPayment Method: International Wire Transfer\nCurrency: USD (United States Dollars)\nBeneficiary Name: ABC Consulting Services LLC\n\n\n\nBeneficiary Address: 1234 Business Park Drive, Suite 500, Los Angeles, CA 90210, USA\n\nPurpose of Payment: Payment for professional consulting services as per Invoice #INV-2025-0847\n\n\n\n- Special Instructions:\n - Please include invoice number INV-2025-0847 in the payment reference\n - All bank charges to be borne by the sender\n - Payment should be received within 3-5 business days\n - Please send wire confirmation receipt to accounting@abcconsulting.com\n - For any questions regarding this transfer, contact: +1 (555) 123-4567\n\n\n\n**Urgency:** Standard processing (3-5 business days acceptable)\n\n\n\nForm completed on: September 3, 2025\n\nReference Number: WT-2025-0847", 'chunks':[ { 'markdown':'# WIRE TRANSFER FORM', 'type':'text', 'id':'33335548-e7c3-40bd-898e-4f23d6c99d34', 'grounding':{ 'box':{ 'left':0.2622728943824768, 'top':0.07604080438613892, 'right':0.7369285821914673, 'bottom':0.10924206674098969 }, 'page':0 } }, { 'markdown':'Invoice Information\n\nInvoice Description: Professional consulting services - Q3 2025\n\nTotal Invoice Amount: $15,750.00 USD', 'type':'text', 'id':'0777dc07-855b-4b83-b422-5e8063405249', 'grounding':{ 'box':{ 'left':0.10331332683563232, 'top':0.13015401363372803, 'right':0.8966385126113892, 'bottom':0.2544138431549072 }, 'page':0 } }, { 'markdown':'Beneficiary Bank Information\n\nBank Name: JPMorgan Chase Bank, N.A.\n\nBank Address: 270 Park Avenue, New York, NY 10017, USA\n\nBank Account Number: 4578923456789012\n\nSWIFT Code: CHASUS33\n\nABA Routing Number: 021000021\n\nACH Routing Number: 021000021', 'type':'text', 'id':'7c56b114-cc66-4fe4-99cb-9425a5210747', 'grounding':{ 'box':{ 'left':0.10399597883224487, 'top':0.2693082094192505, 'right':0.895996630191803, 'bottom':0.5048781633377075 }, 'page':0 } }, { 'markdown':'Invoice Line Items\n
DescriptionAmount
Strategic planning consultation (40 hours @ $150/hr)$6,000.00
Market analysis report preparation$3,500.00
Implementation roadmap development$2,250.00
Executive presentation materials$1,500.00
Follow-up consultation sessions (15 hours @ $150/hr)$2,250.00
Travel expenses (reimbursable)$250.00
TOTAL$15,750.00
', 'type':'table', 'id':'b95955a2-3f1d-4b96-be12-d5af677efd60', 'grounding':{ 'box':{ 'left':0.10457819700241089, 'top':0.5198298096656799, 'right':0.8970209956169128, 'bottom':0.8072096705436707 }, 'page':0 } }, { 'markdown':'Wire Transfer Instructions\n\nPayment Method: International Wire Transfer\nCurrency: USD (United States Dollars)\nBeneficiary Name: ABC Consulting Services LLC', 'type':'text', 'id':'d9296cc1-f804-43e2-9f0f-99e7c62eec48', 'grounding':{ 'box':{ 'left':0.10443270206451416, 'top':0.8223555088043213, 'right':0.8968669176101685, 'bottom':0.974624514579773 }, 'page':0 } }, { 'markdown':'Beneficiary Address: 1234 Business Park Drive, Suite 500, Los Angeles, CA 90210, USA\n\nPurpose of Payment: Payment for professional consulting services as per Invoice #INV-2025-0847', 'type':'text', 'id':'f2b8a1d4-4436-4e05-9467-bdaf5ca4bd3b', 'grounding':{ 'box':{ 'left':0.11186572909355164, 'top':0.022329870611429214, 'right':0.8772550821304321, 'bottom':0.09824278950691223 }, 'page':1 } }, { 'markdown':'- Special Instructions:\n - Please include invoice number INV-2025-0847 in the payment reference\n - All bank charges to be borne by the sender\n - Payment should be received within 3-5 business days\n - Please send wire confirmation receipt to accounting@abcconsulting.com\n - For any questions regarding this transfer, contact: +1 (555) 123-4567', 'type':'text', 'id':'1d536fff-e204-48d4-a53a-8e524665aec5', 'grounding':{ 'box':{ 'left':0.11558690667152405, 'top':0.10176733136177063, 'right':0.8238765001296997, 'bottom':0.20318034291267395 }, 'page':1 } }, { 'markdown':'**Urgency:** Standard processing (3-5 business days acceptable)', 'type':'text', 'id':'fb34e8c2-0aa6-4866-895d-060c07b717ea', 'grounding':{ 'box':{ 'left':0.11588779091835022, 'top':0.204525887966156, 'right':0.6877880096435547, 'bottom':0.23076602816581726 }, 'page':1 } }, { 'markdown':'Form completed on: September 3, 2025\n\nReference Number: WT-2025-0847', 'type':'text', 'id':'7c686aab-8142-4da2-a7e7-dae4495aade5', 'grounding':{ 'box':{ 'left':0.35991770029067993, 'top':0.26450976729393005, 'right':0.641823947429657, 'bottom':0.3033582866191864 }, 'page':1 } } ], 'splits':[ { 'class':'full', 'identifier':'full', 'pages':[ 0, 1 ], 'markdown':"\n\n# WIRE TRANSFER FORM\n\n\n\nInvoice Information\n\nInvoice Description: Professional consulting services - Q3 2025\n\nTotal Invoice Amount: $15,750.00 USD\n\n\n\nBeneficiary Bank Information\n\nBank Name: JPMorgan Chase Bank, N.A.\n\nBank Address: 270 Park Avenue, New York, NY 10017, USA\n\nBank Account Number: 4578923456789012\n\nSWIFT Code: CHASUS33\n\nABA Routing Number: 021000021\n\nACH Routing Number: 021000021\n\n\n\nInvoice Line Items\n
DescriptionAmount
Strategic planning consultation (40 hours @ $150/hr)$6,000.00
Market analysis report preparation$3,500.00
Implementation roadmap development$2,250.00
Executive presentation materials$1,500.00
Follow-up consultation sessions (15 hours @ $150/hr)$2,250.00
Travel expenses (reimbursable)$250.00
TOTAL$15,750.00
\n\n\n\nWire Transfer Instructions\n\nPayment Method: International Wire Transfer\nCurrency: USD (United States Dollars)\nBeneficiary Name: ABC Consulting Services LLC\n\n\n\nBeneficiary Address: 1234 Business Park Drive, Suite 500, Los Angeles, CA 90210, USA\n\nPurpose of Payment: Payment for professional consulting services as per Invoice #INV-2025-0847\n\n\n\n- Special Instructions:\n - Please include invoice number INV-2025-0847 in the payment reference\n - All bank charges to be borne by the sender\n - Payment should be received within 3-5 business days\n - Please send wire confirmation receipt to accounting@abcconsulting.com\n - For any questions regarding this transfer, contact: +1 (555) 123-4567\n\n\n\n**Urgency:** Standard processing (3-5 business days acceptable)\n\n\n\nForm completed on: September 3, 2025\n\nReference Number: WT-2025-0847", 'chunks':[ '33335548-e7c3-40bd-898e-4f23d6c99d34', '0777dc07-855b-4b83-b422-5e8063405249', '7c56b114-cc66-4fe4-99cb-9425a5210747', 'b95955a2-3f1d-4b96-be12-d5af677efd60', 'd9296cc1-f804-43e2-9f0f-99e7c62eec48', 'f2b8a1d4-4436-4e05-9467-bdaf5ca4bd3b', '1d536fff-e204-48d4-a53a-8e524665aec5', 'fb34e8c2-0aa6-4866-895d-060c07b717ea', '7c686aab-8142-4da2-a7e7-dae4495aade5' ] } ], 'metadata':{ 'filename':'wire-transfer.pdf', 'org_id':None, 'page_count':2, 'duration_ms':7861, 'credit_usage':6.0, 'version':'latest' } } ``` To extract specific fields from the parsed Markdown, see [Extract Data](./ade-extract). ## Run Parse with Our Libraries Click one of the tiles below to learn how to run the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) with our libraries. Run Parse with our Python library. TypeScript TypeScript } href="./ade-typescript#parse-getting-started" > Run Parse with our TypeScript library. # Parse Large Files (Parse Jobs) Source: https://docs.landing.ai/ade/ade-parse-async Parse large documents asynchronously with Parse Jobs, and monitor job status and results. The [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API enables you to parse large documents that exceed the size limits of the standard ADE Parse API. ## Monitor Parse Jobs You can monitor parse jobs with these APIs: * [ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs): Get the status for a specific parse job. * [ADE List Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-list-parse-jobs): List all parse jobs associated with your API key. ## Rate Limits for ADE Parse Jobs The ADE Parse Jobs API allows you to parse large documents. The following table shows the limits for the ADE Parse Jobs API. | Maximum File Size | Maximum Pages | | ----------------- | ------------- | | 1 GB | 6,000 pages | To see the rate limits for all APIs, go to [Rate Limits](./ade-rate-limits). ## API Reference To learn more, go to the reference pages for the Parse Jobs APIs: * [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) * [ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs) * [ADE List Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-list-parse-jobs) ## Save Parsed Output to a URL When calling the [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) endpoint, you can use the `output_save_url` parameter to save the parsed Markdown to a specified URL instead of returning it in the API response. This is useful for managing large documents, integrating with your existing storage workflow, or complying with data retention policies. ### When Parsed Output Is Saved to a URL The parsed Markdown is saved to a URL in these scenarios: * **You specify the `output_save_url` parameter**: The Markdown is saved to your specified URL. * **The parsed Markdown exceeds 1 MB**: The Markdown is automatically saved to a presigned S3 URL generated by Agentic Document Extraction. The URL expires after 1 hour, but time you call the [ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs) API, a new presigned URL is generated. Behavior when the output is saved to a URL: * The `output_url` field in the API response contains the URL where the Markdown is stored. * The `data` field in the API response is `None`. ### URL Requirements If you specify the `output_save_url` parameter, your URL must meet these requirements: * The URL must be a presigned URL that grants write (PUT) access to a single object. * These storage provider methods are tested: * [Amazon S3 presigned URL](https://docs.aws.amazon.com/AmazonS3/latest/userguide/PresignedUrlUploadObject.html) * [Azure Blob Storage shared access signature (SAS)](https://learn.microsoft.com/en-us/azure/storage/common/storage-sas-overview) * [Google Cloud Storage signed URL](https://docs.cloud.google.com/storage/docs/access-control/signed-urls) * Other providers that support presigned URLs may also work, but are not tested. * To maintain security, do not use a publicly accessible URL or expose a storage bucket. * The API cannot access private URLs, such as folders in Google Drive. ### Example: Use Amazon S3 Presigned URLs If you use Amazon S3, you can generate a presigned URL and provide it as the `output_save_url` value. Presigned URLs grant temporary access to a single object in your S3 bucket without requiring authentication in the API request. For more information about presigned URLs with Amazon S3, go to the [Amazon documentation](https://docs.aws.amazon.com/AmazonS3/latest/userguide/PresignedUrlUploadObject.html). Here is a sample script that creates a presigned URL and uses it for a parsing job: ```python theme={null} import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/parse/jobs' # Prepare the request payload output_save_url = generate_presigned_url(...) files = {'document_url': 'https://...', 'output_save_url': output_save_url} response = requests.post(url, files=files, headers=headers) print(response.json()) ``` ## ZDR Requirements When [zero data retention](./zdr) (ZDR) is enabled, you must configure the following parameters to ensure that Agentic Document Extraction does not retain the document content: * **Pass your document as a presigned read URL in the `document_url` parameter**. You cannot use the `document` parameter with ZDR enabled. * **Include the `output_save_url` parameter**. This ensures that the parsed content is saved to your specified URL instead of being returned in the API response. To learn how to configure this parameter, go to [Save Parsed Output to a URL](#save-parsed-output-to-a-url). ## Workflow Overview 1. Parse a document with the [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API. 2. Copy the `job_id` in the API response. 3. To get results from the parsing job, call the [ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs) API with the `job_id`. 4. The parsed content is returned as Markdown in `data.markdown`, or as a URL in `output_url` (in which case `data` is `None`). For more information, go to [Save Parsed Output to a URL](#save-parsed-output-to-a-url). 5. If you need to extract fields: 1. Create an extraction schema. 2. Send the Markdown to the [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) API. ## End-to-End Workflow: Parse and Extract the Output This tutorial walks you through how to parse a document with the ADE Parse Jobs API and then extract a subset of fields from it using the ADE Extract API. For the sake of simplicity, we use a 2-page PDF in this example, with the intention that you will use larger documents in your own use case. We provide a separate script for each endpoint, so you can choose to skip the extraction steps if you don't need them. In this tutorial, we will: * Parse this PDF: MRI Report * Extract these fields: **Exam Date** and **Procedure** ### 1. Download the Document to Process Download the MRI Report and save it to a local directory. ### 2. Create Parse Job & Get Job ID #### Create the Script Copy the script below and save it as `create-parse-job.py` in the same directory as the PDF. ```python [expandable] theme={null} import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/parse/jobs' # Upload a document document = open('mri-report.pdf', 'rb') files = {'document': document} data = {'model': 'dpt-2-latest'} response = requests.post(url, files=files, data=data, headers=headers) print(response.json()) ``` #### Run the Script Run the script from the same directory: ```bash theme={null} python create-parse-job.py ``` This returns the `job_id`: ```json theme={null} {'job_id': 'cmfx34ewm0000hyoqkh9dzd8n'} ``` ### 3. Use job\_id to Get Parsing Results #### Create the Script Copy the script below and save it as `get-parse-results.py` in the same directory as the PDF. Replace `{jobId}` with the `job_id` from the previous step. ```python [expandable] theme={null} import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = f'https://api.va.landing.ai/v1/ade/parse/jobs/{jobId}' response = requests.get(url, headers=headers) response_data = response.json() # Print the full response print(response_data) # Check if job is completed if response_data.get('status') == 'completed': # Check if markdown content is available in data if 'data' in response_data and response_data['data'].get('markdown'): markdown_content = response_data['data']['markdown'] # Save markdown content to file with open('markdown-mri-report.md', 'w', encoding='utf-8') as f: f.write(markdown_content) print("\nMarkdown content saved to a Markdown file.") # Check if output_url is available instead elif response_data.get('output_url'): print("Use the Markdown file specified in `output_url`.") else: print("No Markdown content or `output_url` found in the completed job response.") else: print(f"\nJob status: {response_data.get('status', 'unknown')}.") ``` #### Run the Script Run the script from the same directory: ```bash theme={null} python get-parse-results.py ``` When parsing is complete, the script saves the output to `markdown-mri-report.md`. You will pass this file to the Extract API in the next step. ### 4. Extract Fields from Markdown Now that we have the parsed output in a Markdown file, we're ready to extract these fields: **Exam Date** and **Procedure**. #### Create the Script Copy the script below and save it as `extract-mri-report.py` in the same directory as the Markdown file. ```python [expandable] theme={null} import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/extract' # Define the extraction schema schema = json.dumps({ "type": "object", "properties": { "exam_date": { "description": "The date on which the medical examination or procedure was performed.", "format": "YYYY-MM-DD", "x-alternativeNames": [ "Exam Date", "Date of Exam", "Examination Date" ], "type": "string" }, "procedure": { "description": "The specific medical procedure or examination that was conducted, such as an MRI or X-ray.", "x-alternativeNames": [ "Procedure", "Medical Procedure", "Performed Procedure" ], "type": "string" } } }) # Prepare files and data files = {'markdown': open('markdown-mri-report.md', 'rb')} data = {'schema': schema, 'model': 'extract-latest'} # Run extraction response = requests.post(url, files=files, data=data, headers=headers) # Save the results to a JSON file with open('mri-report_extract_output.json', 'w') as f: json.dump(response.json(), f, indent=2) ``` #### Run the Script Run the script from the same directory: ```bash theme={null} python extract-mri-report.py ``` #### View the Output The results are saved to `mri-report_extract_output.json`. The file includes the extracted fields and metadata: ```json [expandable] theme={null} { "extraction": { "exam_date": "2010-05-20", "procedure": "MRI OF THE LUMBAR SPINE WITH AND WITHOUT CONTRAST" }, "extraction_metadata": { "exam_date": { "references": [ "b5183837-035c-4a54-b324-a4c9e8a68027", "1-3" ], "value": "2010-05-20" }, "procedure": { "references": [ "56340fbe-8a51-46a0-a309-d91abd9b8b00" ], "value": "MRI OF THE LUMBAR SPINE WITH AND WITHOUT CONTRAST" } }, "metadata": { "filename": "markdown-mri-report.md", "org_id": null, "duration_ms": 15080, "credit_usage": 1.3256, "job_id": "dfef14d3b66045b8abaf39788b9d17e8", "version": "extract-20260314", "schema_violation_error": null, "fallback_model_version": null, "warnings": [] } } ``` ## Run Parse Jobs with Our Libraries Click one of the tiles below to learn how to run Parse Jobs with our libraries. Run Parse Jobs with our Python library. TypeScript TypeScript } href="https://docs.landing.ai/ade/ade-typescript#parse-jobs" > Run Parse Jobs with our TypeScript library. # Parse Password-Protected Files Source: https://docs.landing.ai/ade/ade-parse-password Decrypt and parse password-protected PDFs and Office files by passing the document password. Organizations that have [Zero Data Retention (ZDR)](./zdr) enabled can parse password-protected files. To parse a password-protected file, pass the document's password in the `password` parameter when calling the API. ## Supported File Types for Password-Protected Parsing The following file types support password-protected parsing: | Category | Extensions | | -------------- | -------------- | | PDF | PDF | | Text Documents | DOC, DOCX, ODT | | Presentations | PPT, PPTX | | Spreadsheets | XLSX | ## Parse Password-Protected Files with the API Add the `password` parameter to your request when parsing a password-protected file. The parameter is optional. If the file is not password-protected, the value is ignored. ```bash Parse theme={null} curl -X POST "https://api.va.landing.ai/v1/ade/parse" \ -H "Authorization: Bearer YOUR_API_KEY" \ -F "document=@path/to/file.pdf" \ -F "password=YOUR_DOCUMENT_PASSWORD" ``` ```bash Parse Jobs theme={null} curl -X POST "https://api.va.landing.ai/v1/ade/parse/jobs" \ -H "Authorization: Bearer YOUR_API_KEY" \ -F "document_url=https://example.com/path/to/file.pdf" \ -F "password=YOUR_DOCUMENT_PASSWORD" \ -F "output_save_url=https://example.com/path/to/output" ``` If you submit a password-protected file without the `password` parameter, the request returns a 422 error. For more information, go to [Troubleshoot Parsing](./ade-parse-troubleshoot). ## Parse Password-Protected Files with Our Libraries ### Parse ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Replace with your file path response = client.parse( document=Path("/path/to/file/document"), password="YOUR_DOCUMENT_PASSWORD", ) print(response.chunks) # Save Markdown output (useful if you plan to run extract on the Markdown) with open("output.md", "w", encoding="utf-8") as f: f.write(response.markdown) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Replace with your file path const response = await client.parse({ document: fs.createReadStream("/path/to/file/document"), password: "YOUR_DOCUMENT_PASSWORD", }); console.log(response.chunks); // Save Markdown to a file if (response.markdown) { fs.writeFileSync("output.md", response.markdown, "utf-8"); } else { console.log("No 'markdown' field found in the response"); } ``` ### Parse Jobs ```python Python [expandable] theme={null} import time from landingai_ade import LandingAIADE client = LandingAIADE() # Step 1: Create a parse job job = client.parse_jobs.create( document_url="https://example.com/path/to/file.pdf", password="YOUR_DOCUMENT_PASSWORD", output_save_url="https://example.com/path/to/output", ) job_id = job.job_id print(f"Job {job_id} created.") # Step 2: Get the parsing results while True: response = client.parse_jobs.get(job_id) if response.status == "completed": print(f"Job {job_id} completed.") break print(f"Job {job_id}: {response.status} ({response.progress * 100:.0f}% complete)") time.sleep(5) ``` ```typescript TypeScript [expandable] theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE(); // Step 1: Create a parse job const job = await client.parseJobs.create({ document_url: "https://example.com/path/to/file.pdf", password: "YOUR_DOCUMENT_PASSWORD", output_save_url: "https://example.com/path/to/output", }); const jobId = job.job_id; console.log(`Job ${jobId} created.`); // Step 2: Get the parsing results while (true) { const response = await client.parseJobs.get(jobId); if (response.status === "completed") { console.log(`Job ${jobId} completed.`); break; } console.log(`Job ${jobId}: ${response.status} (${(response.progress * 100).toFixed(0)}% complete)`); await new Promise(resolve => setTimeout(resolve, 5000)); } ``` # Custom Prompts for Figure Descriptions Source: https://docs.landing.ai/ade/ade-parse-custom-prompts Customize how figures and images are described during parsing. When you parse a file, the parsing results include descriptions of images called **captions**. Captions appear in the `markdown` field of `figure`-type chunks. For more information, see [Image-Based Chunks](./ade-markdown-response#image-based-chunks). Use the optional `custom_prompts` parameter to tell Agentic Document Extraction how to describe figures during parsing. ```bash highlight={4} theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'custom_prompts={"figure":"YOUR_CUSTOM_PROMPT"}' ``` ## When to Add Custom Prompts Adding custom prompts can be helpful if: * The default image descriptions do not fit your use case. * The downstream processing tasks require the image descriptions to use a specific format or language. * The images or charts are unique to your organization or use case and you need to provide additional context about what they represent. ## Sample Prompts **Make the description more concise** This is helpful if you want to minimize the number of input tokens when running the Split or Extract APIs, or if the images are straightforward and do not need much description. ```bash theme={null} custom_prompts={"figure":"Limit the description to 50 characters. Be concise but communicate the core message of the image. Do not truncate sentences."} ``` **Omit the description** This is helpful if you don't need the image descriptions in your post-parsing tasks. ```bash theme={null} custom_prompts={"figure":"Do not describe the image. Return an empty string."} ``` **Set the language** This is useful if your downstream tasks require descriptions in a specific language. ```bash theme={null} custom_prompts={"figure":"Return the description in Spanish."} ``` **Return a specific format** This is useful if you want to standardize or change how the image is described. ```bash theme={null} custom_prompts={"figure":"If the image is a chart, format the data as an HTML table"} ``` **Use a standard description** This is useful if you want to return the same string for every figure. ```bash theme={null} custom_prompts={"figure":"Only return this string as the description: This is an image"} ``` ## Requirements The `custom_prompts` parameter accepts a JSON string. Only the `figure` key is supported. Any other key will be rejected. The custom prompt can include up to 512 characters. ## Use Custom Prompts in the Playground Apply a custom figure prompt to every file in a project directly from the [Playground](https://ade.landing.ai/) without writing any code. 1. Open a project in the [Playground](https://ade.landing.ai/). 2. Click the **Parse** tab. 3. In the top-right corner of the parse result panel, click **Config**. 4. From the **Model** drop-down, select DPT-2. The **Custom Figure Prompt** option is only available with DPT-2. 5. Turn on the **Custom Figure Prompt** toggle and enter your prompt (up to 512 characters). 6. Click **Re-run all files**. The Playground re-parses every file in the project using your prompt. Configure Parse Settings ## Use Custom Prompts with the API ```bash Parse theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'custom_prompts={"figure":"Describe axis labels in detail."}' ``` ```bash Parse Jobs theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'custom_prompts={"figure":"Describe axis labels in detail."}' ``` ## Use Custom Prompts with Our Libraries When using the [ade-python](https://github.com/landing-ai/ade-python) library, pass `custom_prompts` as a JSON string using `json.dumps`. The Parse endpoints use multipart form data, so the parameter does not accept a dictionary directly. You can also pass a string literal (for example, `'{"figure": "YOUR_CUSTOM_PROMPT"}'`), but `json.dumps` is preferred because it handles escaping and formatting automatically, reducing the risk of malformed JSON that causes a 422 error. ### Parse ```python Python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Replace with your file path response = client.parse( document=Path("/path/to/file/document"), custom_prompts=json.dumps({"figure": "YOUR_CUSTOM_PROMPT"}), ) print(response.chunks) # Save Markdown output (useful if you plan to run extract on the Markdown) with open("output.md", "w", encoding="utf-8") as f: f.write(response.markdown) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Replace with your file path const response = await client.parse({ document: fs.createReadStream("/path/to/file/document"), custom_prompts: { figure: "YOUR_CUSTOM_PROMPT" }, }); console.log(response.chunks); // Save Markdown to a file if (response.markdown) { fs.writeFileSync("output.md", response.markdown, "utf-8"); } else { console.log("No 'markdown' field found in the response"); } ``` ### Parse Jobs ```python Python [expandable] theme={null} import json import time from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() # Step 1: Create a parse job job = client.parse_jobs.create( document=Path("/path/to/file/document"), custom_prompts=json.dumps({"figure": "YOUR_CUSTOM_PROMPT"}), ) job_id = job.job_id print(f"Job {job_id} created.") # Step 2: Get the parsing results while True: response = client.parse_jobs.get(job_id) if response.status == "completed": print(f"Job {job_id} completed.") break print(f"Job {job_id}: {response.status} ({response.progress * 100:.0f}% complete)") time.sleep(5) ``` ```typescript TypeScript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); // Step 1: Create a parse job const job = await client.parseJobs.create({ document: fs.createReadStream("/path/to/file/document"), custom_prompts: { figure: "YOUR_CUSTOM_PROMPT" }, }); const jobId = job.job_id; console.log(`Job ${jobId} created.`); // Step 2: Get the parsing results while (true) { const response = await client.parseJobs.get(jobId); if (response.status === "completed") { console.log(`Job ${jobId} completed.`); break; } console.log(`Job ${jobId}: ${response.status} (${(response.progress * 100).toFixed(0)}% complete)`); await new Promise(resolve => setTimeout(resolve, 5000)); } ``` # Document Pre-Trained Transformers (Parsing Models) Source: https://docs.landing.ai/ade/ade-parse-models Choose a parsing model (DPT) and set it when parsing files. ## Parsing Models Overview A **Document Pre-Trained Transformer** (DPT) is the model that powers the parsing capabilities of the ADE Parsing APIs. The DPT identifies document layouts and chunks, then generates descriptive explanations (captions) for those chunks. ## Availability The ability to select a Document Pre-Trained Transformer is available: * in the [Playground](#set-the-model-in-the-playground) * when calling the [ADE Parse](#set-the-model-in-the-api) or [Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) APIs * when using the [Python](https://github.com/landing-ai/ade-python) and [TypeScript](https://github.com/landing-ai/ade-typescript) libraries ## Model Versions and Snapshots The following table lists the available `model` values for the ADE Parse and ADE Async Parse API: | Model Values | Description | | -------------- | -------------------------------------------------------------------------------------------------------------------- | | dpt-2 | The latest snapshot of DPT-2. | | dpt-2-latest | The latest snapshot of DPT-2. | | dpt-2-20250919 | The snapshot of DPT-2 released on September 19, 2025. | | dpt-2-20251103 | The snapshot of DPT-2 released on November 3, 2025. | | dpt-2-20260302 | The snapshot of DPT-2 released on March 2, 2026. [See improvements.](#dpt-2-20260302) | | dpt-2-20260410 | The snapshot of DPT-2 released on April 10, 2026. [See improvements.](#dpt-2-20260410) | | dpt-2-20260903 | The snapshot of DPT-2 released on September 3, 2026, on an updated underlying model. [See details.](#dpt-2-20260903) | The `dpt-1` and `dpt-2-mini` models are deprecated. Use `dpt-2` instead. All organizations are moving to `dpt-2-20260903`. Organizations on subscription and enterprise plans move on October 7, 2026. After your organization moves, every DPT-2 model value, including `dpt-2`, `dpt-2-latest`, and every pinned snapshot, runs on `dpt-2-20260903`, and responses report `dpt-2-20260903` as the model version. To test it before then, set `model` to `dpt-2-20260903`. For details, go to [dpt-2-20260903](#dpt-2-20260903). ### Why Model Versioning Matters When integrating the API, you have two options for specifying the model: 1. **Use a general model name** (like `dpt-2` or `dpt-2-latest`) to always get the newest version. This automatically give you improvements and updates, but parsing results may change when new model versions are released 2. **Use a specific snapshot** (like `dpt-2-20250919`) to pin to an exact model version. This keeps parsing results consistent until the snapshot is retired or migrated, but you won't receive improvements. If you use only a general model name like `dpt-2` in production, your application may produce different results when we release model updates. Consider whether you need consistent results or prefer to receive the latest improvements. ### Understanding Snapshots and -latest **Snapshots** are versions of a model released on specific dates. A snapshot keeps the same parsing behavior until it is retired or migrated to a newer snapshot. For the current migration, go to [dpt-2-20260903](#dpt-2-20260903). The **latest** suffix points to the current default snapshot of that model. The default is not always the newest snapshot. For example, `dpt-2-latest` does not point to `dpt-2-20260903` until your organization moves. ## DPT-2 DPT-2 was introduced in September 2025. It builds upon an earlier model, and offers these advanced features: * **Agentic Table Captioning**: DPT-2 can parse large, complex, no-gridline, and merged-cell tables with unprecedented fidelity. Every cell is preserved, aligned, and made accessible—enabling cell-level grounding so you know exactly where values came from. * **Refined Figure Captioning**: Logos, seals, and small figures are now identified precisely and concisely, eliminating the noise of verbose descriptions. * **Smarter Layout Detection**: Fewer chunks are missed, even in messy scans. DPT-2 can even detect stamps inside tables and process them separately—critical for compliance workflows. * **Expanded Chunk Ontology**: Beyond text, tables, and figures, DPT-2 now recognizes attestation (signatures, stamps, seals), ID cards, logos, barcodes, and QR codes—ensuring all document elements are classified consistently. To learn more, go to [Chunk Types](./ade-chunk-types). ### dpt-2-20260903 The `dpt-2-20260903` snapshot runs DPT-2 on an updated underlying model. One of our third-party model providers is retiring the model that earlier snapshots use, so every organization moves to this snapshot. * **Output close to earlier snapshots**: The snapshot is tuned to match earlier DPT-2 output. Some documents return different text or table formatting. * **No confidence scores**: The `confidence` field in the Parse response is `null`. Your endpoints and request parameters do not change. #### When Your Organization Moves Organizations on subscription and enterprise plans move to `dpt-2-20260903` on October 7, 2026. After your organization moves, `dpt-2`, `dpt-2-latest`, and every pinned DPT-2 snapshot run on `dpt-2-20260903`. Until then, `dpt-2` and `dpt-2-latest` do not change. To test your own documents first, set `model` to `dpt-2-20260903`. ### dpt-2-20260410 The `dpt-2-20260410` snapshot builds on previous DPT-2 snapshots with these improvements: * **Improved cell parsing in forms and tables**: Text positioned at different locations within a cell is now captured more completely. * **Improved column alignment in complex tables**: Cell data now more accurately aligns with its corresponding column headers. ### dpt-2-20260302 The `dpt-2-20260302` snapshot builds on previous DPT-2 snapshots with several improvements, including: * **Table boundary detection**: Tables that were previously split into multiple chunks are now correctly identified as a single table. * **Improved large table accuracy**: Large tables are now parsed more accurately. * **Special characters returned as Unicode**: Characters such as asterisks are now returned as their Unicode characters (for example, `*`) rather than as spelled-out strings like `asterisk`. ### DPT-2 Availability The DPT-2 can be used in these API endpoints: * [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) * [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) ## Set the Model in the API When calling the [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) or [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) endpoint, you can set the model using the `model` parameter. If you omit the `model` parameter, the API will use the latest snapshot of the `dpt-2` model. For example, run the command below to use the latest snapshot of DPT-2. ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest' ``` ## Set the Model with the Library When using the [ade-python](https://github.com/landing-ai/ade-python) library, you can set the model using the `model` parameter in the `parse()` function. If you omit the `model` parameter, the library will use the latest snapshot of the `dpt-2` model. For example, use this code to parse a document with the latest snapshot of DPT-2: ```python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest" ) ``` ## Set the Model in the Playground The Playground's **Model** drop-down defaults to **DPT-3 Pro**, the ADE Gen2 model. To select a DPT-2 parsing model instead: 1. Open a project in the [Playground](https://ade.landing.ai/). 2. Click the **Parse** tab. 3. In the top-right corner of the parse result panel, click **Config**. 4. From the **Model** drop-down, select the model you want to use. 5. Click **Re-run all files**. Configure Parse Settings Switching the model re-parses every file in the project. If you switch back to a model that was already applied to the project, the Playground reuses the cached parse results instead of re-parsing. # Chunk Types Source: https://docs.landing.ai/ade/ade-chunk-types Understand the chunk types ADE returns, such as text, tables, figures, and form fields. ## Chunk Definition A **chunk** is a discrete element extracted from a document, such as a block of text, a table, or a figure. ## Chunk Overview When you send a document to the Agentic Document Extraction API, it analyzes the content on each page, breaks it down into meaningful elements, and returns each one as a chunk. Each chunk includes structured data that describes the content of the chunk and the location of the chunk in the document. This structure makes it easier to understand the extracted data and use it for downstream tasks. Extracted chunks are included in the API response. ## Semantic Chunking The Agentic Document Extraction API uses semantic chunking, which means it intelligently groups content based on meaning rather than just layout or formatting. Instead of splitting documents at arbitrary points like fixed lengths or paragraph breaks, the API identifies coherent units of information (like complete ideas, logical sections, or related data) and extracts them as individual chunks. Semantic chunking improves the relevance and usability of the extracted content, especially in downstream tasks like search, retrieval, and analysis. ## Why Do We Create Chunks? Chunking makes downstream tasks faster, more accurate, and easier to scale. It serves several key purposes: * **Enables downstream apps to process large documents efficiently**: Chunking allows applications like RAG systems and LLMs to index and retrieve smaller, meaningful segments instead of full documents. This helps avoid input size constraints, such as token limits. * **Improves retrieval granularity**: Smaller, semantically meaningful units allow for more accurate and relevant results in downstream tasks like question answering and summarization. * **Supports downstream semantic search and embeddings**: Well-structured chunks provide better inputs for embedding and make it easier to index and retrieve information during search. * **Maintains human readability**: Chunking reflects how a human would naturally read the document, maintaining the visual and logical relationships between elements on the page. ## Chunk Types Each chunk is labeled with a chunk type (`chunk_type` or `type`, depending on the API used), which identifies what kind of content it represents. The chunk types returned by Agentic Document Extraction are: * [`text`](#text) * [`table`](#table) * [`marginalia`](#marginalia) * [`figure`](#figure) * [`logo`](#logo): This is only available when using [DPT-2](./ade-parse-models#dpt-2) * [`card`](#card): This is only available when using [DPT-2](./ade-parse-models#dpt-2) * [`attestation`](#attestation): This is only available when using [DPT-2](./ade-parse-models#dpt-2) * [`scan_code`](#scan_code): This is only available when using [DPT-2](./ade-parse-models#dpt-2) ## Text A `text` chunk type is an element that consists entirely of characters (letters and numbers), such as: * paragraphs * titles and headings * lists * form fields * checkboxes * radio buttons * equations * code blocks * handwritten text ### Output for Key-Value Pairs If the `text` content has key-value pairs, like form fields, the extracted data will be returned as key-value pairs separated by line breaks (`\n`). ### Example: Paragraph Here is an example of the API marking a paragraph as a `text` chunk: Chunk Type: Text Here is the rendered Markdown for that chunk: Chunk Type: Text ### Example: Lists Here is an example of the API marking a list as a `text` chunk: Chunk Type: Text Here is the rendered Markdown for that chunk: Chunk Type: Text ## Table A `table` chunk type is a grid of rows and columns containing data. Agentic Document Extraction doesn't require gridlines to be present, and typically interprets well-aligned sets of data to be part of a table. For example, part of a receipt can be extracted as a table if the purchased items align with the costs. When you parse spreadsheets, sets of data are also interpreted as `table` chunks. ### Example: Receipt Here is an example of the API marking receipt line items as a `table` chunk: Chunk Type: Table Here is the rendered Markdown for that chunk: Chunk Type: Table ### Example: Earnings Statement Here is an example of the API marking part of an earnings statement as a `table` chunk: Chunk Type: Table Here is the rendered Markdown for that chunk: Chunk Type: Table ### Example: Spreadsheet Here is an example of the API marking data in a spreadsheet as a `table` chunk: Chunk Type: Table Here is the rendered Markdown for that chunk: Chunk Type: Table ## Marginalia A `marginalia` chunk type is a set of text in the top, bottom, or side margins of a document, including: * page headers * page footers * page numbers * handwritten notes in margins * line numbers on one side of a page #### Example: Header and Page Number Here is an example of the API marking a header and page number as a `page_header` chunk: Chunk Type: Page Header Here is the rendered Markdown for that chunk: Chunk Type: Page Header ## Figure A `figure` chunk type is an element that contains visual or graphical non-text content, including: * pictures * graphs (bar graphs, line graphs, etc.) * flowcharts * diagrams ### Example: Medical Imaging Here is an example of the API marking a pathology image as a `figure` chunk: Chunk Type: Figure Here is the rendered Markdown for that chunk: Chunk Type: Figure ### Example: Bar Chart Here is an example of the API marking a bar chart as a `figure` chunk: Chunk Type: Figure Here is the rendered Markdown for that chunk: Chunk Type: Figure ## Logo A `logo` chunk type identifies logos. The `logo` chunk type is only available when using [DPT-2](./ade-parse-models#dpt-2). ### Example: Logo in Header Here is an example of the API marking a logo in a document header as a `logo` chunk: Chunk Type: Logo Here is the rendered Markdown for that chunk: Chunk Type: Logo ## Card A `card` chunk type identifies: * ID cards * driver licenses The `card` chunk type is only available when using [DPT-2](./ade-parse-models#dpt-2). ### Example: Driver's License Here is an example of the API marking a driver's license as a `card` chunk: Chunk Type: Card Here is the rendered Markdown for that chunk: Chunk Type: Card ## Attestation An `attestation` chunk type includes: * signatures * stamps * seals The `attestation` chunk type is only available when using [DPT-2](./ade-parse-models#dpt-2). ### Example: Signature Here is an example of the API marking a signature as an `attestation` chunk: Chunk Type: Attestation Here is the rendered Markdown for that chunk: Chunk Type: Attestation ## Scan\_code A `scan_code` chunk type identifies: * QR codes * bar codes The `scan_code` chunk type is only available when using [DPT-2](./ade-parse-models#dpt-2). ### Example: Bar Codes Here is an example of the API marking two barcodes as `scan_code` chunks: Chunk Type: Scan Code Here is the rendered Markdown for these chunks: Chunk Type: Scan Code # JSON Response for Parsing Source: https://docs.landing.ai/ade/ade-json-response Understand the parse JSON response: markdown, chunks, splits, grounding, and metadata fields. When you parse a document with the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) or complete an [ADE Parse Job](https://docs.landing.ai/api-reference/tools/ade-parse-jobs), the parsed data is returned in a structured JSON format. The fields and structure of API responses are detailed in the [API Reference](https://docs.landing.ai/api-reference/tools/ade-parse). This article is designed to give additional context about the returned fields and how to use them. ## Response Structure The response contains the following top-level fields: | Field | Description | | ----------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | [`markdown`](./ade-markdown-response) | Complete Markdown representation of the document. | | [`chunks`](#parsed-chunks-chunks) | Array of `chunk` objects, one for each parsed region. | | [`splits`](#splits) | Array of `split` objects organizing chunks by page or section. | | [`grounding`](#grounding-information-grounding) | Object mapping chunk IDs to detailed grounding information, which includes the page number and bounding box coordinates. | | `metadata` | Processing information (credit usage, duration, filename, job ID, page count, version). For partial content responses, includes a `failed_pages` array listing page numbers that failed to process. | ## Chunk, Table, and Cell Identifiers Each chunk, table, and table cell has a unique identifier (ID) that appears in multiple parts of the API response. Use these IDs to link different sets of information across the response. The ID format depends on the element type: | ID Type | Format | Example | | -------------- | ------------------------------------------ | -------------------------------------- | | Chunk IDs | UUID format | `7d58c5cf-e4f5-4a7e-ba34-0cd7bc6a6506` | | Table IDs | `{page_number}-{base62_sequential_number}` | `0-1` | | Table cell IDs | `{page_number}-{base62_sequential_number}` | `0-2`, `0-3` | ### Sequential Numbering for Tables and Cells Table and cell IDs use sequential numbering within each page. The first table element on the first page has ID `0-1`, and its first cell has ID `0-2`. All subsequent table elements and cells on that page continue this sequential numbering (`0-3`, `0-4`, etc.). The numbering restarts for each new page. For example, the first table on the second page will have ID `1-1`, and its first cell will have ID `1-2`. ## Parsed Chunks (`chunks`) A [chunk](./ade-chunk-types) is a distinct region or element in the parsed document. The `chunks` array contains all parsed chunks from the document in reading order. Each `chunk` object in the `chunks` array contains: | Field | Description | | ----------- | --------------------------------------------------------------------------------------------------------------------------------------- | | `id` | Chunk [unique identifier](#chunk-table-and-cell-identifiers) (UUID format). | | `markdown` | [Markdown](./ade-markdown-response) content for the chunk. | | `type` | [Chunk type](./ade-chunk-types). | | `grounding` | The location of the chunk in the document. Contains page number and [bounding box coordinates](#working-with-bounding-box-coordinates). | ## Splits The `split` parameter is different from the [ADE Split API](./ade-split). If your goal is to separate a document into sub-documents after parsing, use the ADE Split API, not the `split` parameter. The `splits` array groups chunks into logical sections based on the [`split`](./parse#set-up-splits-for-parsing) parameter. Each split object includes the chunks, markdown content, and page numbers for that section. * **If the `split` parameter was omitted**: The API returns the entire document as a single split. * **If page-level splits were used (`split=page`)**: The API organizes chunks by page. For multi-page documents, this creates one split per page. ### Split Object Structure Each `split` object contains: | Field | Description | | ------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `class` | The split type.
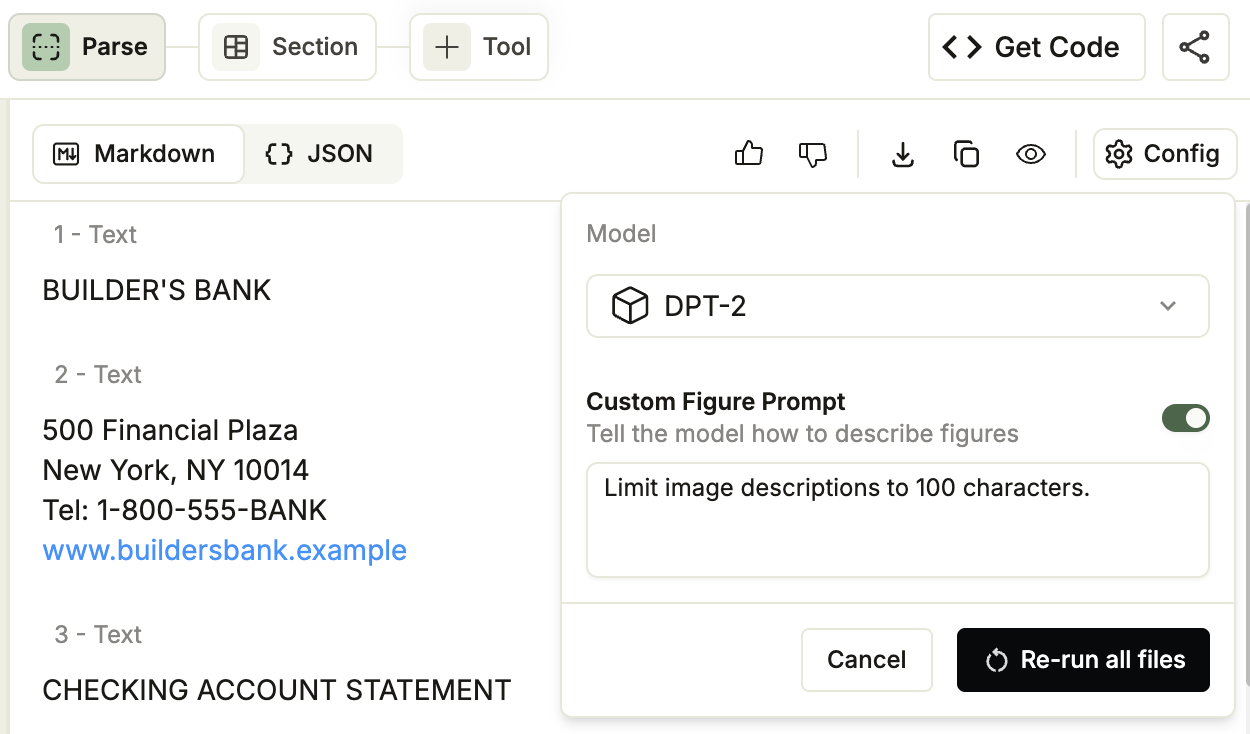
  • `full`: Used when the `split` parameter was not included, and the array includes one entry for the entire document.
  • `page`: Used when the `split` parameter was included, and the array contains an entry for each page.
| | `identifier` | The unique identifier for each entry.
  • `full`: Used when the `split` parameter was not included, and the array includes one entry for the entire document.
  • `page_{number}`: Used when the `split` parameter was included. Includes the zero-indexed page number. Examples: `page_0`, `page_1`
| | `pages` | Array of page numbers (zero-indexed) included in the split. | | `markdown` | Complete markdown content for all chunks in the split. | | `chunks` | Array of [chunk IDs](#chunk-table-and-cell-identifiers) included in the split. | ### Full Document Split vs. Page-Level Split When you omit the `split` parameter, the API returns a single split containing the entire document. When you set `split=page`, the API creates one split per page for multi-page documents. ```json Full Document (Split Omitted) theme={null} "splits": [ { "class": "full", "identifier": "full", "pages": [0], "markdown": "...", "chunks": ["chunk-id-1", "chunk-id-2"] } ] ``` ```json Page-Level Split theme={null} "splits": [ { "class": "page", "identifier": "page_0", "pages": [0], "markdown": "...", "chunks": ["chunk-id-1"] }, { "class": "page", "identifier": "page_1", "pages": [1], "markdown": "...", "chunks": ["chunk-id-2", "chunk-id-3"] } ] ``` ## Grounding Information (`grounding`) **Grounding** is location information that maps each chunk or table cell back to its precise position in the original document. Each grounding entry includes the page number and bounding box coordinates for an element. The `grounding` object contains location data for all chunks and table cells in the parsed document. ### How the Grounding Object Works The `grounding` object is a dictionary where [chunk, table, and cell IDs](#chunk-table-and-cell-identifiers) are keys. To look up grounding information for any element, use its ID. **What's included in the grounding object:** * All chunk IDs from the `chunks` array * Table IDs (for entire tables) * Table cell IDs (individual cells within tables) **Example:** Consider parsing this document containing a table of bank account interest rates: Example document with bank account interest rates The parsed response is shown below, with key elements highlighted in the table: | Line | Description | ID | | ------- | --------------------------------------------------------- | ------------------------------------ | | Line 47 | `grounding` object begins | N/A | | Line 48 | Grounding for the text "Bank Account Rates" | 2831e56d-94f5-4ec4-b001-6e16e188119b | | Line 58 | Grounding for the table chunk | 54905c88-b4b8-45a7-84b5-1dcf5f1d1e60 | | Line 68 | Grounding for the table ID | 0-1 | | Line 78 | Grounding for the first cell in the table, "Account Type" | 0-2 | ```json [expandable] lines highlight={47, 48, 58, 68, 78} theme={null} { "markdown": "\n\n## Bank Account Rates\n\n\n\n\n\n\n\n
Account TypeAPY
Checking0.25%
Savings3.30%
", "chunks": [ { "markdown": "\n\n## Bank Account Rates", "type": "text", "id": "2831e56d-94f5-4ec4-b001-6e16e188119b", "grounding": { "box": { "left": 0.01733572781085968, "top": 0.03853631019592285, "right": 0.46379542350769043, "bottom": 0.212029367685318 }, "page": 0 } }, { "markdown": "\n\n\n\n\n\n
Account TypeAPY
Checking0.25%
Savings3.30%
", "type": "table", "id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60", "grounding": { "box": { "left": 0.018494874238967896, "top": 0.332082062959671, "right": 0.9904391765594482, "bottom": 0.9499841928482056 }, "page": 0 } } ], "splits": [ { "class": "full", "identifier": "full", "pages": [ 0 ], "markdown": "\n\n## Bank Account Rates\n\n\n\n\n\n\n\n
Account TypeAPY
Checking0.25%
Savings3.30%
", "chunks": [ "2831e56d-94f5-4ec4-b001-6e16e188119b", "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" ] } ], "grounding": { "2831e56d-94f5-4ec4-b001-6e16e188119b": { "box": { "left": 0.01733572781085968, "top": 0.03853631019592285, "right": 0.46379542350769043, "bottom": 0.212029367685318 }, "page": 0, "type": "chunkText" }, "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60": { "box": { "left": 0.018494874238967896, "top": 0.332082062959671, "right": 0.9904391765594482, "bottom": 0.9499841928482056 }, "page": 0, "type": "chunkTable" }, "0-1": { "box": { "left": 0.02559941303263648, "top": 0.34709447306434493, "right": 0.9833663842655778, "bottom": 0.9408472995763262 }, "page": 0, "type": "table" }, "0-2": { "box": { "left": 0.025725066969341424, "top": 0.34709447306434493, "right": 0.5043980858495114, "bottom": 0.5451939275066816 }, "page": 0, "type": "tableCell", "position": { "row": 0, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" } }, "0-3": { "box": { "left": 0.5043442644343732, "top": 0.3470990955792963, "right": 0.9832354042503647, "bottom": 0.5451945630018467 }, "page": 0, "type": "tableCell", "position": { "row": 0, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" } }, "0-4": { "box": { "left": 0.025662229745978628, "top": 0.5451932923723879, "right": 0.5043442644343732, "bottom": 0.7430525865339257 }, "page": 0, "type": "tableCell", "position": { "row": 1, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" } }, "0-5": { "box": { "left": 0.5042905263610684, "top": 0.5451939275066816, "right": 0.9833008650173567, "bottom": 0.7429820118984354 }, "page": 0, "type": "tableCell", "position": { "row": 1, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" } }, "0-6": { "box": { "left": 0.02559941303263648, "top": 0.7429820118984354, "right": 0.5042905263610684, "bottom": 0.9408472995763262 }, "page": 0, "type": "tableCell", "position": { "row": 2, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" } }, "0-7": { "box": { "left": 0.5042367730777779, "top": 0.7429113809301333, "right": 0.9833663842655779, "bottom": 0.9408260780878634 }, "page": 0, "type": "tableCell", "position": { "row": 2, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "54905c88-b4b8-45a7-84b5-1dcf5f1d1e60" } } }, "metadata": { "filename": "bank-account-rates.png", "org_id": null, "page_count": 1, "duration_ms": 2836, "credit_usage": 3.0, "job_id": "def6af5f0485497c81ea46bc4c848f83", "version": "dpt-2-20251103", "failed_pages": [] } } ``` ### Fields in the Grounding Object Each key-value pair in the `grounding` object uses an ID as the key (chunk ID, table ID, or cell ID) and location data as the value. Each value is an object with the following fields: | Field | Description | | ---------------------- | --------------------------------------------------------------------------------------------------------------------------------- | | `box` | [Bounding box coordinates](#working-with-bounding-box-coordinates) | | `page` | Zero-indexed page number | | `type` | Detailed classification. See [grounding types](#grounding-types). | | `confidence` | Confidence score for text-based chunks. See [Confidence Score](#confidence-score). | | `low_confidence_spans` | Sections of text with low confidence scores, if any. | | `position` | For table cells only. Cell location in table grid (row, col, spans). See [Table Cell Position](#table-cell-position-information). | **Example:** Example of one key-value pair from the `grounding` object (logo chunk): ```json theme={null} { "grounding": { "49c7b7d0-2d8e-4485-8306-3dd820eb13ed": { "box": { "left": 0.06869561225175858, "top": 0.02685479447245598, "right": 0.1445186734199524, "bottom": 0.08676017820835114 }, "page": 0, "type": "chunkLogo" } } } ``` ### Grounding Types Each entry in the `grounding` object has a `type` field that identifies the element type. #### Why are grounding types different from chunk types? Most grounding types correspond directly to [chunk types](./ade-chunk-types) with a "chunk" prefix. However, the `grounding` object provides more granular location data than the chunks array. For tables, the grounding object includes separate entries for the HTML `` element and individual cells, even though these are not separate chunks. This allows you to look up the precise location of any cell within a table. The following table lists the grounding types and the corresponding chunk types, when applicable. | Grounding Type | Chunk Type | | ------------------ | ------------------------------------------------------------------------------------ | | `chunkAttestation` | `attestation` | | `chunkCard` | `card` | | `chunkFigure` | `figure` | | `chunkLogo` | `logo` | | `chunkMarginalia` | `marginalia` | | `chunkScanCode` | `scan_code` | | `chunkTable` | `table` | | `chunkText` | `text` | | `table` | Special grounding type representing the HTML `
` element within a table chunk. | | `tableCell` | Special grounding type representing an individual cell within a table. | ### Table Grounding Structure For each table in a document, the grounding object includes three types of entries: **table chunk**, **table**, **cell**. These three types form a hierarchy: the **chunk** entry provides the overall table location, while the **table** and **cell** entries provide precise locations for the HTML elements within that chunk. | Entry | Description | Type | | ----- | --------------------------------------------------------------------------- | ------------ | | Chunk | The table as a whole. Use when you need the overall table location. | `chunkTable` | | Table | The HTML `
` element. Use when you need the precise table boundaries. | `table` | | Cells | Each individual cell. Use when you need to locate a specific cell. | `tableCell` | **Example:** Consider parsing this simple 2-cell table: Example table with 2 cells The `grounding` field from the response is shown below, with key elements highlighted in the table: | Line | Description | ID | | ------- | ---------------------------------------------------- | ------------------------------------ | | Line 1 | `grounding` object | N/A | | Line 2 | Grounding for the table chunk | ef24b1ea-8dac-4a24-bf60-704b7c6a6bca | | Line 12 | Grounding for the table ID | 0-1 | | Line 22 | Grounding for the first cell in the table, "Cell 1" | 0-2 | | Line 39 | Grounding for the second cell in the table, "Cell 2" | 0-3 | ```json [expandable] lines highlight={1, 2, 12, 22, 39 } theme={null} "grounding": { "ef24b1ea-8dac-4a24-bf60-704b7c6a6bca": { "box": { "left": 0.15924638509750366, "top": 0.19857195019721985, "right": 0.6330658197402954, "bottom": 0.313611775636673 }, "page": 0, "type": "chunkTable" }, "0-1": { "box": { "left": 0.16758577831817933, "top": 0.20629539815303133, "right": 0.6280869812016796, "bottom": 0.3090690124206503 }, "page": 0, "type": "table" }, "0-2": { "box": { "left": 0.16758577831817933, "top": 0.2062988834957917, "right": 0.39743034595752635, "bottom": 0.3090588206865543 }, "page": 0, "type": "tableCell", "position": { "row": 0, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "ef24b1ea-8dac-4a24-bf60-704b7c6a6bca" } }, "0-3": { "box": { "left": 0.3972880070815534, "top": 0.20629539815303133, "right": 0.6280869812016795, "bottom": 0.3090690124206503 }, "page": 0, "type": "tableCell", "position": { "row": 0, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "ef24b1ea-8dac-4a24-bf60-704b7c6a6bca" } } }, ``` ### Table Cell Position Information Each table cell (`tableCell`) includes a `position` field that provides the cell's location in the table grid. The `row` and `col` values are zero-indexed, where `row: 0, col: 0` represents the first row and first column of the table. The `rowspan` and `colspan` values indicate merged cells, with a value of 1 meaning the cell is not merged in that direction. | Field | Description | | ---------- | ------------------------------------------- | | `row` | Row position (integer, zero-indexed). | | `col` | Column position (integer, zero-indexed). | | `rowspan` | Number of rows the cell spans (integer). | | `colspan` | Number of columns the cell spans (integer). | | `chunk_id` | Associated chunk identifier (string). | #### How to Use the Table Cell Positions Use the table cell position information in the `grounding` to: * Map parsed data back to specific cells in the original table (for example, verify that a dollar amount came from row 2, column 3) * Identify merged cells through the `rowspan` and `colspan` values * Programmatically reference cells by their row and column indices ### Confidence Score Agentic Document Extraction returns confidence scores for text, marginalia, card, and table chunks, as well as table cells, when parsing with DPT-2. Confidence scores measure the confidence level of parsed text in Markdown with respect to the actual text or visual data present in the document. Each score ranges from 0.0 (low confidence) to 1.0 (high confidence). Lower values indicate regions where the model was less certain about the output. For example, here are the confidence score fields for a chunk: ```json Confidence score fields highlight={11-12} theme={null} "grounding": { "42ca60d3-a606-4c9a-a61e-493966b63fd9": { "box": { "left": 0.8607578277587891, "top": 0.9346558451652527, "right": 0.9316827058792114, "bottom": 0.951895534992218 }, "page": 0, "type": "chunkMarginalia", "confidence": 0.991, "low_confidence_spans": [] } } ``` #### Confidence Score Fields The grounding object includes the following confidence-related fields: | Field | Description | | ---------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `confidence` | Overall confidence score for the chunk or element (0.0 to 1.0). When `low_confidence_spans` contains entries, this is the lowest of the span-level or cell-level confidence scores. | | `low_confidence_spans` | Array of objects identifying specific text substrings with confidence scores of 0.95 or lower. Empty array if no low-confidence substrings exist. Learn more in [Low Confidence Spans](#low-confidence-spans). | #### Low Confidence Spans The `low_confidence_spans` array contains substrings that have confidence scores of 0.95 or lower. Each object in the `low_confidence_spans` array contains: | Field | Description | | ------------ | ---------------------------------------------------------------------------------------------------------------------------------------------- | | `text` | The substring that has low confidence. | | `span` | Two-element array `[start, end]` indicating the character position range of the substring within the chunk's text. Positions are zero-indexed. | | `confidence` | Confidence score for this specific substring (0.0 to 1.0). | For example, in the parse response below, the API has low confidence for two spans of text within the chunk. ```json Low confidence spans highlight={11-27} theme={null} "grounding": { "6be7d3cf-6664-42c7-906c-4957882e40ff": { "box": { "left": 0.24479518830776215, "top": 0.9269143342971802, "right": 0.6804859042167664, "bottom": 0.9461647272109985 }, "page": 0, "type": "chunkText", "confidence": 0.25, "low_confidence_spans": [ { "text": " 1220", "span": [ 8, 13 ], "confidence": 0.25 }, { "text": "15?\"", "span": [ 26, 30 ], "confidence": 0.62 } ] } } ``` #### Chunks and Elements with Confidence Scores Confidence scores are available for text, marginalia, card, and table chunks, as well as table cells. The `tableCell` elements have confidence scores but do not include `low_confidence_spans`
Grounding Type Chunk Type Has Confidence Score Has Low Confidence Spans
chunkText text ✓ ✓
chunkMarginalia marginalia ✓ ✓
chunkCard card ✓ ✓
chunkTable table ✓ ✓
table — — —
tableCell — ✓ —
chunkFigure figure — —
chunkLogo logo — —
chunkAttestation attestation — —
chunkScanCode scan\_code — —
#### Confidence Score Availability Confidence scores are only available when using the ADE Parse or ADE Parse Jobs API with **DPT-2**. #### Null Confidence Scores The confidence score will be `null` in the following situations: * The file was parsed with DPT-1. * The chunk or element does not support confidence scores. See a list of supported elements in [Chunks and Elements with Confidence Scores](#chunks-and-elements-with-confidence-scores). For example, here are the confidence score fields for a logo: ```json Response when confidence score not applicable highlight={9-11} theme={null} "7215c238-8363-4de3-9f34-dd12c42cf5ec": { "box": { "left": 0.6948671936988831, "top": 0.9627023339271545, "right": 0.9369598031044006, "bottom": 1 }, "page": 0, "type": "chunkLogo", "confidence": null, "low_confidence_spans": [] } ``` #### How to Use Confidence Scores Confidence scores are not a calibrated probability of correctness. Use them as a ranking or triage signal to flag and prioritize content for human review, rather than as an exact measure of error likelihood. #### Factors That Can Lower Confidence Scores Certain document characteristics may result in lower confidence scores: * Low-resolution or degraded scans * Handwritten text that is difficult to read * Superscripts and subscripts * Characters or punctuation that look alike, such as commas and periods * Words split across lines with a hyphen * Line endings where it's unclear whether the text continues in the same paragraph or starts a new one #### False Positives The system is designed to over-flag rather than risk missing potential issues. As a result, some regions may be marked as low confidence even when the parsed output is correct. These false positives mean you may need to review some content that is actually correct, but they help reduce the likelihood of missing content that contains errors. ## When to Use Chunk-Level vs. Global Grounding Grounding information is available at the chunk level (`chunks[].grounding`) and at the global level (`grounding`). Each has a different level of detail:
Field Description Global Grounding Object Chunk-Level Grounding
box Bounding box coordinates ✓ ✓
page Zero-indexed page number ✓ ✓
confidence Confidence score ✓ ✖
low\_confidence\_spans Sections of text with low confidence scores, if any ✓ ✖
type Detailed element type ✓ ✖
position Table cell position ✓ ✖
Choose the appropriate source based on your workflow: **Use the global `grounding` object when:** * You need table cell positions or other HTML element grounding * You need confidence scores * You need to understand relationships between elements * Building comprehensive document analysis workflows * You need the complete, authoritative grounding data for all elements in the document **Use chunk-level grounding (`chunks[].grounding`) when:** * Iterating through chunks sequentially and need each chunk's location immediately * Working with a single chunk in isolation * Building simple workflows where each chunk is processed independently ## Working with Bounding Box Coordinates The `grounding` objects include the bounding box coordinates for each chunk in the `box` object: | Field | Description | | -------- | -------------------- | | `left` | Left edge position | | `top` | Top edge position | | `right` | Right edge position | | `bottom` | Bottom edge position | ### Bounding Box Values All bounding box coordinates use normalized values between 0 and 1, where: * `(0, 0)` represents the top-left corner of the page * `(1, 1)` represents the bottom-right corner of the page ### Convert Bounding Box Values To convert bounding box values to pixel coordinates, multiply the normalized values by the image dimensions: ``` x1 = left * image_width y1 = top * image_height x2 = right * image_width y2 = bottom * image_height ``` For practical examples of working with bounding box coordinates, go to [Link Extracted Data to Document Locations](./ade-extract-grounding-sample). ## Example Response The following is the API response when parsing this single-page Product Specifications Sheet. The document contains text, a logo, a table, a barcode, and more. The `split` parameter was omitted in the API call. ```json [expandable] theme={null} { "markdown": "\n\n# Product Specification Sheet\n\nPremium Wireless Headphones - Model WH-3000\n\n\n\n<::logo: Acme\nAcme\nBlue rectangular background with rounded corners, featuring three overlapping white circles and the text \"Acme\" below them::>\n\n\n\n**Product Description:** Premium over-ear wireless headphones featuring advanced noise cancellation technology, superior sound quality, and all-day comfort. Designed for professionals and audiophiles who demand exceptional audio performance.\n\n\n\nTechnical Specifications\n\n\n\n\n\n\n\n
FeatureSpecification
Battery LifeUp to 30 hours with ANC on
ConnectivityBluetooth 5.3, USB-C
Driver Size40mm dynamic drivers
Weight250 grams
Charging Time2.5 hours (full charge)
\n\n\n\nProduct Identification\n\n\n\n<::scan_code: Barcode (UPC-A)\n012345678905\nUPC: 012345678905 | SKU: WH-3000-BLK\nThis is a standard black and white barcode with clear, readable numbers and text below it. The quality is excellent with no discernible issues.::>\n\n\n\nAcme Technologies • Revision 1.2 • February 2026 • For internal use only", "chunks": [ { "markdown": "\n\n# Product Specification Sheet\n\nPremium Wireless Headphones - Model WH-3000", "type": "text", "id": "d52a402e-ecbe-45bb-b645-6f879533062d", "grounding": { "box": { "left": 0.16788743436336517, "top": 0.14442312717437744, "right": 0.6138156652450562, "bottom": 0.20980927348136902 }, "page": 0 } }, { "markdown": "\n\n<::logo: Acme\nAcme\nBlue rectangular background with rounded corners, featuring three overlapping white circles and the text \"Acme\" below them::>", "type": "logo", "id": "e82c9292-b032-4115-88b1-8e63a453fa62", "grounding": { "box": { "left": 0.6695178747177124, "top": 0.13189411163330078, "right": 0.8306078910827637, "bottom": 0.21691173315048218 }, "page": 0 } }, { "markdown": "\n\n**Product Description:** Premium over-ear wireless headphones featuring advanced noise cancellation technology, superior sound quality, and all-day comfort. Designed for professionals and audiophiles who demand exceptional audio performance.", "type": "text", "id": "e2d9311c-6034-4a19-845c-8b3bbb607220", "grounding": { "box": { "left": 0.16763517260551453, "top": 0.24475212395191193, "right": 0.8179030418395996, "bottom": 0.3363903760910034 }, "page": 0 } }, { "markdown": "\n\nTechnical Specifications\n\n\n\n\n\n\n\n
FeatureSpecification
Battery LifeUp to 30 hours with ANC on
ConnectivityBluetooth 5.3, USB-C
Driver Size40mm dynamic drivers
Weight250 grams
Charging Time2.5 hours (full charge)
", "type": "table", "id": "6ad71883-8f01-4ca8-854e-67fdf98705c0", "grounding": { "box": { "left": 0.16853490471839905, "top": 0.3461304306983948, "right": 0.8309106826782227, "bottom": 0.6140876412391663 }, "page": 0 } }, { "markdown": "\n\nProduct Identification", "type": "text", "id": "a111a086-c0ce-4177-b9d6-32813583c09c", "grounding": { "box": { "left": 0.17146995663642883, "top": 0.6203439235687256, "right": 0.40161988139152527, "bottom": 0.6445382833480835 }, "page": 0 } }, { "markdown": "\n\n<::scan_code: Barcode (UPC-A)\n012345678905\nUPC: 012345678905 | SKU: WH-3000-BLK\nThis is a standard black and white barcode with clear, readable numbers and text below it. The quality is excellent with no discernible issues.::>", "type": "scan_code", "id": "36cfe5fe-1d1f-4025-9fed-8dd30c61e512", "grounding": { "box": { "left": 0.35067588090896606, "top": 0.6593142151832581, "right": 0.6467784643173218, "bottom": 0.7614949345588684 }, "page": 0 } }, { "markdown": "\n\nAcme Technologies • Revision 1.2 • February 2026 • For internal use only", "type": "text", "id": "769360a9-738e-4d46-9815-1c6fadc44fef", "grounding": { "box": { "left": 0.17040444910526276, "top": 0.7973303198814392, "right": 0.6371863484382629, "bottom": 0.8179382681846619 }, "page": 0 } } ], "splits": [ { "class": "full", "identifier": "full", "pages": [ 0 ], "markdown": "\n\n# Product Specification Sheet\n\nPremium Wireless Headphones - Model WH-3000\n\n\n\n<::logo: Acme\nAcme\nBlue rectangular background with rounded corners, featuring three overlapping white circles and the text \"Acme\" below them::>\n\n\n\n**Product Description:** Premium over-ear wireless headphones featuring advanced noise cancellation technology, superior sound quality, and all-day comfort. Designed for professionals and audiophiles who demand exceptional audio performance.\n\n\n\nTechnical Specifications\n\n\n\n\n\n\n\n
FeatureSpecification
Battery LifeUp to 30 hours with ANC on
ConnectivityBluetooth 5.3, USB-C
Driver Size40mm dynamic drivers
Weight250 grams
Charging Time2.5 hours (full charge)
\n\n\n\nProduct Identification\n\n\n\n<::scan_code: Barcode (UPC-A)\n012345678905\nUPC: 012345678905 | SKU: WH-3000-BLK\nThis is a standard black and white barcode with clear, readable numbers and text below it. The quality is excellent with no discernible issues.::>\n\n\n\nAcme Technologies • Revision 1.2 • February 2026 • For internal use only", "chunks": [ "d52a402e-ecbe-45bb-b645-6f879533062d", "e82c9292-b032-4115-88b1-8e63a453fa62", "e2d9311c-6034-4a19-845c-8b3bbb607220", "6ad71883-8f01-4ca8-854e-67fdf98705c0", "a111a086-c0ce-4177-b9d6-32813583c09c", "36cfe5fe-1d1f-4025-9fed-8dd30c61e512", "769360a9-738e-4d46-9815-1c6fadc44fef" ] } ], "grounding": { "d52a402e-ecbe-45bb-b645-6f879533062d": { "box": { "left": 0.16788743436336517, "top": 0.14442312717437744, "right": 0.6138156652450562, "bottom": 0.20980927348136902 }, "page": 0, "type": "chunkText" }, "e82c9292-b032-4115-88b1-8e63a453fa62": { "box": { "left": 0.6695178747177124, "top": 0.13189411163330078, "right": 0.8306078910827637, "bottom": 0.21691173315048218 }, "page": 0, "type": "chunkLogo" }, "e2d9311c-6034-4a19-845c-8b3bbb607220": { "box": { "left": 0.16763517260551453, "top": 0.24475212395191193, "right": 0.8179030418395996, "bottom": 0.3363903760910034 }, "page": 0, "type": "chunkText" }, "6ad71883-8f01-4ca8-854e-67fdf98705c0": { "box": { "left": 0.16853490471839905, "top": 0.3461304306983948, "right": 0.8309106826782227, "bottom": 0.6140876412391663 }, "page": 0, "type": "chunkTable" }, "0-1": { "box": { "left": 0.17681816766455002, "top": 0.3838889918624204, "right": 0.8229430485888809, "bottom": 0.6081938563658866 }, "page": 0, "type": "table" }, "0-2": { "box": { "left": 0.17681816766455002, "top": 0.38390272737304887, "right": 0.4088692768884933, "bottom": 0.4210832942672924 }, "page": 0, "type": "tableCell", "position": { "row": 0, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-3": { "box": { "left": 0.40885843457119975, "top": 0.3838889918624204, "right": 0.8229109083847056, "bottom": 0.42110282924189346 }, "page": 0, "type": "tableCell", "position": { "row": 0, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-4": { "box": { "left": 0.17683986982706765, "top": 0.4210723476432389, "right": 0.40885843457119975, "bottom": 0.45900337698896576 }, "page": 0, "type": "tableCell", "position": { "row": 1, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-5": { "box": { "left": 0.4088473778820912, "top": 0.4210832942672924, "right": 0.8229174171863827, "bottom": 0.45899898681702755 }, "page": 0, "type": "tableCell", "position": { "row": 1, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-6": { "box": { "left": 0.17686202113997704, "top": 0.45899898681702755, "right": 0.4088473778820912, "bottom": 0.4960768409028701 }, "page": 0, "type": "tableCell", "position": { "row": 2, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-7": { "box": { "left": 0.40883656585659384, "top": 0.45899115081094266, "right": 0.822923787547722, "bottom": 0.4960756768254202 }, "page": 0, "type": "tableCell", "position": { "row": 2, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-8": { "box": { "left": 0.17688367164390373, "top": 0.4960756768254202, "right": 0.40883656585659384, "bottom": 0.5339128041911175 }, "page": 0, "type": "tableCell", "position": { "row": 3, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-9": { "box": { "left": 0.4088255320780733, "top": 0.4960735986896906, "right": 0.8229302909456246, "bottom": 0.533930464401036 }, "page": 0, "type": "tableCell", "position": { "row": 3, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-a": { "box": { "left": 0.17690576166324445, "top": 0.533902913573485, "right": 0.4088255320780733, "bottom": 0.5709324331603126 }, "page": 0, "type": "tableCell", "position": { "row": 4, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-b": { "box": { "left": 0.4088147366922871, "top": 0.5339128041911175, "right": 0.8229366506791294, "bottom": 0.5709510466955219 }, "page": 0, "type": "tableCell", "position": { "row": 4, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-c": { "box": { "left": 0.17692738041744768, "top": 0.5709220105206869, "right": 0.4088147366922871, "bottom": 0.6081720470002152 }, "page": 0, "type": "tableCell", "position": { "row": 5, "col": 0, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "0-d": { "box": { "left": 0.40880387715616723, "top": 0.5709324331603126, "right": 0.8229430485888809, "bottom": 0.6081938563658866 }, "page": 0, "type": "tableCell", "position": { "row": 5, "col": 1, "rowspan": 1, "colspan": 1, "chunk_id": "6ad71883-8f01-4ca8-854e-67fdf98705c0" } }, "a111a086-c0ce-4177-b9d6-32813583c09c": { "box": { "left": 0.17146995663642883, "top": 0.6203439235687256, "right": 0.40161988139152527, "bottom": 0.6445382833480835 }, "page": 0, "type": "chunkText" }, "36cfe5fe-1d1f-4025-9fed-8dd30c61e512": { "box": { "left": 0.35067588090896606, "top": 0.6593142151832581, "right": 0.6467784643173218, "bottom": 0.7614949345588684 }, "page": 0, "type": "chunkScanCode" }, "769360a9-738e-4d46-9815-1c6fadc44fef": { "box": { "left": 0.17040444910526276, "top": 0.7973303198814392, "right": 0.6371863484382629, "bottom": 0.8179382681846619 }, "page": 0, "type": "chunkText" } }, "metadata": { "filename": "product-specs.pdf", "org_id": null, "page_count": 1, "duration_ms": 14358, "credit_usage": 3.0, "job_id": "dbad0c1be3874904bf9cec3e5e536471", "version": "dpt-2-20251103", "failed_pages": [] } } ``` # Markdown Response Source: https://docs.landing.ai/ade/ade-markdown-response Understand the Markdown that Parse returns, including anchor tags and chunk- and split-level fields. When you call the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) endpoint ([https://api.va.landing.ai/v1/ade/parse](https://api.va.landing.ai/v1/ade/parse)), the API response includes `markdown` fields at three levels: * **Top-level `markdown` field**: Contains the complete parsed document content as Markdown * **Chunk-level `markdown` fields**: Each object in the `chunks` array includes its own `markdown` field containing only the content for that specific chunk * **Split-level `markdown` fields**: Each object in the `splits` array includes a `markdown` field containing the content for that specific section of the document All `markdown` fields use the same formatting and include embedded [HTML anchor tags](#anchor-tags) that link the content to specific chunks in the `chunks` array. These anchors enable you to trace content back to its location in the original document. ### Markdown Fields in Context To better understand how these `markdown` fields work together, let's look at the parsing response for this pallet label: Pallet Label Below is the full parsing response for this document with the `markdown` fields highlighted. Notice that each chunk's HTML anchor tag (the `` element) appears consistently across all `markdown` fields. This consistency means you can reference any chunk by its ID, whether you're working with the complete document Markdown, a specific split, or an individual chunk. ```json Markdown Fields {2,5,19,33,47,68} [expandable] theme={null} { "markdown": "\n\nSKU\nWH-2847-BLK\n\n\n\nQUANTITY\n\n48 Units\n\n\n\n<::scan_code: Barcode\n\nThis is a clear, well-defined linear barcode with distinct black bars on a white background, showing no visible quality issues.::>\n\n\n\n2847 0000 4812\n---\n", "chunks": [ { "markdown": "\n\nSKU\nWH-2847-BLK", "type": "text", "id": "69a645fe-8617-4be8-b66f-68d7788755c0", "grounding": { "box": { "left": 0.06628379225730896, "top": 0.09509064257144928, "right": 0.4664609134197235, "bottom": 0.2678269147872925 }, "page": 0 } }, { "markdown": "\n\nQUANTITY\n\n48 Units", "type": "text", "id": "bdaf2198-0fdc-4c94-be54-a49ca796ea0f", "grounding": { "box": { "left": 0.06750398874282837, "top": 0.3068091869354248, "right": 0.3204823434352875, "bottom": 0.47341251373291016 }, "page": 0 } }, { "markdown": "\n\n<::scan_code: Barcode\n\nThis is a clear, well-defined linear barcode with distinct black bars on a white background, showing no visible quality issues.::>", "type": "scan_code", "id": "65fe085e-b8c8-46e0-848c-f0c32ccf16e8", "grounding": { "box": { "left": 0.11207544803619385, "top": 0.5374823212623596, "right": 0.8830909729003906, "bottom": 0.8660760521888733 }, "page": 0 } }, { "markdown": "\n\n2847 0000 4812\n---\n", "type": "text", "id": "9e551c40-3eaa-4d77-a219-50b7f4a57e05", "grounding": { "box": { "left": 0.28996485471725464, "top": 0.9088556170463562, "right": 0.7057502269744873, "bottom": 0.9888754487037659 }, "page": 0 } } ], "splits": [ { "class": "page", "identifier": "page_0", "pages": [ 0 ], "markdown": "\n\nSKU\nWH-2847-BLK\n\n\n\nQUANTITY\n\n48 Units\n\n\n\n<::scan_code: Barcode\n\nThis is a clear, well-defined linear barcode with distinct black bars on a white background, showing no visible quality issues.::>\n\n\n\n2847 0000 4812\n---\n", "chunks": [ "69a645fe-8617-4be8-b66f-68d7788755c0", "bdaf2198-0fdc-4c94-be54-a49ca796ea0f", "65fe085e-b8c8-46e0-848c-f0c32ccf16e8", "9e551c40-3eaa-4d77-a219-50b7f4a57e05" ] } ], "grounding": { "69a645fe-8617-4be8-b66f-68d7788755c0": { "box": { "left": 0.06628379225730896, "top": 0.09509064257144928, "right": 0.4664609134197235, "bottom": 0.2678269147872925 }, "page": 0, "type": "chunkText" }, "bdaf2198-0fdc-4c94-be54-a49ca796ea0f": { "box": { "left": 0.06750398874282837, "top": 0.3068091869354248, "right": 0.3204823434352875, "bottom": 0.47341251373291016 }, "page": 0, "type": "chunkText" }, "65fe085e-b8c8-46e0-848c-f0c32ccf16e8": { "box": { "left": 0.11207544803619385, "top": 0.5374823212623596, "right": 0.8830909729003906, "bottom": 0.8660760521888733 }, "page": 0, "type": "chunkScanCode" }, "9e551c40-3eaa-4d77-a219-50b7f4a57e05": { "box": { "left": 0.28996485471725464, "top": 0.9088556170463562, "right": 0.7057502269744873, "bottom": 0.9888754487037659 }, "page": 0, "type": "chunkText" } }, "metadata": { "filename": "pallet-label.png", "org_id": null, "page_count": 1, "duration_ms": 4226, "credit_usage": 3, "job_id": "y2xvbwlqc1p9ynwfkx4tx7q7q", "version": "dpt-2-20250919" } } ``` ## Markdown Structure The `markdown` field includes a parsed chunk or a sequence of chunks. Each chunk begins with an [HTML anchor tag](#anchor-tags) containing a unique identifier, followed by the chunk content. For example, the following `markdown` field contains two chunks: * A figure chunk (ID: `4c29090b-b75e-4d5f-95b6-24a7d5668486`) with a description of the image * A text chunk (ID: `ae2e4e41-9443-4fb5-bced-199915f97dec`) containing formatted address information ```json theme={null} "markdown": "\n\n<::An illustration of a sun with eight rays extending outwards.: figure::>\n\n\n\n**Eliza Smith**\n123 Main St.\nMountain View, CA 94041" ``` ### Anchor Tags Each chunk begins with an HTML anchor tag containing the chunk's unique identifier. The `id` attribute contains the UUID that matches the corresponding entry in the `chunks` array, enabling you to trace content back to its location in the original document. ```html theme={null} ``` ### Content Format by Chunk Type The Markdown content format varies based on the [chunk type](./ade-chunk-types): * [Text-Based Chunks](#text-based-chunks) * [Image-Based Chunks](#image-based-chunks) * [Table Chunks](#table-chunks) * [Spreadsheets](#spreadsheets) #### Text-Based Chunks For text-based chunks (`text`, `marginalia`), content appears as standard Markdown text: ```markdown theme={null} ## Heading Text Paragraph content with **bold** and *italic* formatting. ``` #### Image-Based Chunks Image-based chunks (`figure`, `logo`, `card`, `attestation`, `scan_code`) use a special delimiter format that wraps the caption or description: ```markdown theme={null} <::Caption or description of the visual element: figure::> ``` #### Table Chunks Table chunks (`table`) appear as HTML table markup. Most table elements include unique `id` attributes. These IDs use the format `{page_number}-{base62_sequential_number}`, where the page number starts at 0 and the sequential number increments for each element within the page. If a page contains multiple tables, the ID numbering continues sequentially across all tables on that page. Table cells that span multiple rows or columns include `rowspan` or `colspan` attributes in the HTML markup. This ID system allows you to trace individual cells, rows, and tables back to their locations in the original document. The [JSON response](./ade-json-response#table-cell-position-information) also includes position information (row, column, rowspan, colspan) for each table cell in the grounding object. ```markdown theme={null}
Product Summary
ProductRevenue
Hardware15,230
Software8,540
``` #### Spreadsheets When you parse spreadsheets, data is identified as `table` chunks, and embedded images or charts are identified as `figure` chunks. Table chunks appear as HTML table markup. Most table elements include unique `id` attributes. These IDs use the format `{tab_name}-{cell_reference}`, where the tab name is the name of the spreadsheet tab and the cell reference uses standard spreadsheet notation (column letter followed by row number, such as A1, B2, or C3). The table itself uses a range-based ID format: `{tab_name}-{start_cell}:{end_cell}` (for example, `Sheet 1-A1:B4`). This ID system allows you to trace individual cells back to their locations in the original spreadsheet. For example, here is a screenshot of a spreadsheet, followed by the Markdown output. Spreadsheet ```markdown theme={null} { "markdown": "\n\n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n
ProgramInterest Rate
15 Year Fixed-Rate Mortgage0.05125
30 Year Fixed-Rate Mortgage0.05875
10/1 ARM0.05625
", "type": "table", "id": "Sheet 1-A1:B4", "grounding": null } ``` For a list of supported spreadsheet types, go to [Supported File Types](./ade-file-types). ### Chunk Separators Chunks are separated by double newlines (`\n\n`), except for the final chunk in the document. ## How do I find the Markdown response for the ADE Parse Jobs API? If you call the [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API, the API responds with the `job_id`. The parsing results, including the `markdown` field, are returned when you check the parsing job status with the [ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs) API. # Troubleshoot Parsing Source: https://docs.landing.ai/ade/ade-parse-troubleshoot Resolve Parse and Parse Jobs errors using status codes, causes, and fixes for failed or partial results. Use this section to troubleshoot issues encountered when calling the parse APIs: * **[ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse)**: `/v1/ade/parse` * **[ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs)**: `/v1/ade/parse/jobs` * **[ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-job)**: `/v1/ade/parse/jobs/{job_id}` * **[ADE List Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-list-parse-jobs)**: `/v1/ade/parse/jobs` ## Common Status Codes These status codes apply to all parse endpoints. | Status Code | Name | Description | What to Do | | ----------- | ----------------- | ----------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- | | 401 | Unauthorized | Missing or invalid API key. | Check that your `apikey` header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. | ## ADE Parse This section covers errors for the ADE Parse API. ### Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Document parsed successfully and returned immediately. | Continue with normal operations. | | 206 | Partial Content | Document parsed but some pages failed during processing. | Review the `failed_pages` field in the metadata. See [Status 206](#status-206-partial-content). | | 400 | Bad Request | Invalid request due to document download failure or unsupported model version. | Review error message for specific issue. See [Status 400](#status-400-bad-request). | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See [Status 422](#status-422-unprocessable-entity). | | 500 | Internal Server Error | All pages failed to process. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500](#status-500-internal-server-error). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit (475 seconds). | Reduce document size or number of pages. See [Status 504](#status-504-gateway-timeout). | ### Status 206: Partial Content **Applies to:** ADE Parse and ADE Get Parse Jobs This response occurs when the document was parsed successfully but some pages failed during processing. The response includes: * A 206 status code * Parsed content for successful pages * A `failed_pages` array in the metadata listing which pages failed (zero-indexed) * **For ADE Get Parse Jobs only:** A `failure_reason` field with details about the failures Because the API returns at least partial results, the API call consumes credits. **What to do:** * Review the `failed_pages` field in the metadata to identify which pages failed. * For ADE Get Parse Jobs, also review the `failure_reason` field for details about the failures. * Check if the failed pages are corrupted or have unusual formatting. * If the issue persists with specific pages, contact [support@landing.ai](mailto:support@landing.ai). ### Status 400: Bad Request This status code indicates invalid request parameters or client-side errors. Review the specific error message to identify the issue. #### Error: Failed to download document from URL This error occurs when the API cannot download the document from the provided `document_url`. **Error message:** ``` Failed to download document from URL: {error_details} ``` **What to do:** * Verify the URL is accessible and returns valid content. * Check network connectivity and URL permissions. * Ensure the URL points to a supported document type. #### Error: Invalid Document Format Agentic Document Extraction converts text documents and presentations to PDFs before parsing them. This error occurs when a text document or presentation cannot be converted to PDF. The file may be password-protected or corrupted. **Error message:** ``` Invalid document format. The file may be corrupted or password-protected. ``` **What to do:** * Verify the document is not corrupted by opening it in the appropriate application (such as Microsoft Word or Microsoft PowerPoint). * Open the document in the appropriate application (such as Microsoft Word or Microsoft PowerPoint) and resave it. #### Error: Unsupported model This error occurs when an invalid or unsupported model version is specified. **Error message:** ``` Unsupported model: {version} ``` **What to do:** * Check the API documentation for supported model versions. * If you don't specify a version, the API uses the latest version by default. * Verify the model version string is formatted correctly. #### Error: Deprecated model version This error occurs when the `model` parameter specifies a deprecated model version. The DPT-1 family (`dpt-1`, `dpt-1-latest`, and dated snapshots) and `dpt-2-mini` are deprecated. **Error message:** ``` The specified model version '{version}' is deprecated. Please use a supported model version. See https://docs.landing.ai/dpt3/parse for the latest models. ``` **What to do:** Update the `model` parameter to a supported version, such as `dpt-2`. See [Parsing Models](./ade-parse-models). ### Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error message and adjust your request parameters. #### Error: Cannot provide both 'document' and 'document\_url' This error occurs when both a document file and a URL to a document are provided in the same request. **Error message:** ``` Cannot provide both 'document' and 'document_url'. Please provide only one. ``` **What to do:** Choose one input method and remove the other from your request: * Provide a document file using the `document` parameter. * Provide a URL to a document using the `document_url` parameter. #### Error: Must provide either 'document' or 'document\_url' This error occurs when your request does not include either the `document` or `document_url` parameter. **Error message:** ``` Must provide either 'document' or 'document_url'. ``` **What to do:** Add one of these parameters to your request: * Use the `document` parameter to upload a document file. * Use the `document_url` parameter to provide a URL to a document. #### Error: Invalid URL format This error occurs when the `document_url` parameter contains an invalid URL. **Error message:** ``` Invalid URL format: {url} ``` **What to do:** * Verify the URL is properly formatted with a valid protocol (http\:// or https\://). * Check for typos or missing characters in the URL. * Ensure the URL is properly encoded if it contains special characters. #### Error: PDF must not exceed X pages This error occurs when the PDF page count exceeds your account's page limit. **Error message:** ``` PDF must not exceed {limit} pages. ``` **What to do:** * Reduce the PDF page count. To see the maximum number of pages allowed, go to [Rate Limits](./ade-rate-limits). * Consider using the [ADE Parse Jobs](./ade-parse-async) API, which allows you to process longer documents. #### Error: PDF contains zero pages This error occurs when the PDF file has no pages. **Error message:** ``` PDF contains zero pages. Please provide a PDF with at least one page. ``` **What to do:** Use a valid PDF file that contains at least one page of content. #### Error: Failed to open or read PDF This error occurs when the PDF file is corrupted or cannot be opened. **Error message:** ``` Failed to read PDF document: {error_details} ``` or ``` Failed to open PDF. Ensure it is a valid PDF file. ``` **What to do:** * Use a valid, non-corrupted PDF file. * Open the PDF in a PDF reader to verify it's not corrupted. * Re-save or re-export the PDF. #### Error: Document Is Password-Protected This error occurs when you submit a password-protected file without providing the `password` parameter. **Error message:** ``` Document is password-protected. Please provide the password parameter. ``` **What to do:** * **If you have ZDR enabled**: Add the `password` parameter to your request. For more information, go to [Parse Password-Protected Files](./ade-parse-password). * **If you don't have ZDR enabled**: Parsing password-protected files is not supported for your account. Remove the password and try again. #### Error: Failed to Decrypt Document This error occurs if you have [Zero Data Retention (ZDR)](./zdr) enabled, included the `password` parameter (see [Parse Password-Protected Files](./ade-parse-password)), and the password is incorrect or the file is corrupted. **Error message:** ``` Failed to decrypt {document_type} document. The password is incorrect or the file is corrupted. ``` **What to do:** * Verify the password is correct. * Open the file in the appropriate application to confirm it is not corrupted. #### Error: Password-Protected Documents Not Supported for Your Account This error occurs when the `password` parameter is included in the request but [Zero Data Retention (ZDR)](./zdr) is not enabled on your account. **Error message:** ``` Password-protected documents are not currently supported for your account. Please remove the password from your document before uploading. ``` **What to do:** * Remove the password from the document before uploading and try again. * To parse password-protected files, enable ZDR on your account. For more information, go to [Zero Data Retention](./zdr). #### Error: Multiple document files detected This error occurs when multiple document files are included in the request. **Error message:** ``` Multiple document files detected (X). Please provide only one document file. ``` **What to do:** Send only one document file per request. #### Error: File is empty This error occurs when the uploaded file contains no data. **Error message:** ``` File is empty. ``` **What to do:** Ensure you are uploading a valid file with content (not an empty file). #### Error: Failed to Convert Document to Supported Format Agentic Document Extraction converts text documents and presentations to PDFs before parsing them. This error occurs when a document is converted to PDF successfully but the resulting PDF is empty or contains no extractable content. **Error message:** ``` Failed to convert document to supported format ``` **What to do:** * Verify the document contains actual content, not just blank pages or empty slides. * Check that the document doesn't consist only of unsupported elements (such as embedded objects that cannot be converted). * Open the document in the appropriate application (such as Microsoft Word or Microsoft PowerPoint) and resave it. #### Error: Unsupported Format This error occurs when the uploaded file format is not supported. **Error message:** ``` Unsupported format: {mime_type} ({filename}). Supported formats: {supported_formats} ``` **What to do:** * Check the list of [supported file types](./ade-file-types). * Convert your document to a supported format before uploading. * Verify the file extension matches the actual file content. #### Error: Unsupported Spreadsheet Format This error occurs when the uploaded spreadsheet file format is not supported. **Error message:** ``` Unsupported format: {filename}. Supported formats: .xlsx, .csv ``` **What to do:** * Convert your spreadsheet to .xlsx or .csv format. * Verify the file extension matches the actual file content. #### Error: Spreadsheet File Too Large This error occurs when the uploaded spreadsheet exceeds the 50 MB size limit. **Error message:** ``` Spreadsheet file too large (max 50 MB). Please split into smaller files. ``` **What to do:** * Split your spreadsheet into multiple smaller files. * Remove unnecessary data or sheets to reduce file size. #### Error: Invalid `custom_prompts` Value **Applies to:** ADE Parse and ADE Parse Jobs This error occurs when the `custom_prompts` parameter fails validation. Common causes include: * The figure prompt exceeds 512 characters * An unsupported key is used (only `figure` is supported) * The value for the `figure` key is not a string * The value is not a JSON object * The value is not valid JSON **Error messages:** ``` custom_prompts['figure'] must be 512 characters or fewer. ``` ``` Input should be 'figure' ``` **What to do:** * Ensure `custom_prompts` is a valid JSON string in object format: `{"figure": "your prompt"}`. * Use only the `figure` key. Any other key will be rejected. * Keep the figure prompt to 512 characters or fewer. * For more information, see [Custom Prompts for Figure Descriptions](./ade-parse-custom-prompts). #### Error: `custom_prompts` Not Supported for Model **Applies to:** ADE Parse and ADE Parse Jobs This error occurs when the `custom_prompts` parameter is used with a model that does not support it. **Error message:** ``` custom_prompts is not supported for the '{model_name}' model. Please use a different model or remove the custom_prompts parameter. ``` **What to do:** * Use DPT-2 when using `custom_prompts`. For more information, see [Custom Prompts for Figure Descriptions](./ade-parse-custom-prompts). ### Status 500: Internal Server Error This error indicates all pages in the document failed to process. **Error message:** ``` Failed to process the document ``` **What to do:** * Retry the request. * Check if the document has unusual formatting or corrupted content. * If the document is very large, process individual pages. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ### Status 504: Gateway Timeout This error occurs when the parsing process exceeds the timeout limit (475 seconds). The work is cancelled, so retrying starts the parse from the beginning. You are not billed for a request that times out. **Error message:** ``` Request timed out after {seconds} seconds ``` **What to do:** * Reduce the document size or number of pages. * Split large documents into smaller files. * Use the [ADE Parse Jobs](./ade-parse-async) API instead. Jobs are not subject to the synchronous timeout. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## ADE Parse Jobs This section covers errors for the ADE Parse Jobs API, which creates asynchronous parse jobs. ### Status Codes | Status Code | Name | Description | What to Do | | ----------- | -------------------- | --------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------- | | 202 | Accepted | Job created successfully and queued for processing. | Use the returned `job_id` to check job status with the [ADE Get Parse Jobs](#ade-get-parse-jobs) API. | | 400 | Bad Request | Invalid request parameters. | Review the error message for details. See [Status 400](#status-400-bad-request-2). | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. Common errors include missing required fields, ZDR configuration issues, or invalid input. See errors below. | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. | ### Status 400: Bad Request #### Error: output\_save\_url must be present if zeroDataRetention is enabled This error occurs when Zero Data Retention (ZDR) is enabled but no output save URL is provided. **Error message:** ``` output_save_url must be present if zeroDataRetention is enabled ``` **What to do:** When using Zero Data Retention (ZDR), you must provide an `output_save_url` where the parsed results will be saved. The results will not be returned in the API response when ZDR is enabled. #### Error: Only document\_url is accepted if zeroDataRetention is enabled This error occurs when Zero Data Retention (ZDR) is enabled but a document file is uploaded instead of providing a URL. **Error message:** ``` Only document_url is accepted if zeroDataRetention is enabled ``` **What to do:** When using Zero Data Retention (ZDR), you must use the `document_url` parameter to provide a URL to your document. Direct file uploads via the `document` parameter are not supported with ZDR. ### Status 500: Internal Server Error This error indicates a server-side failure during job creation or enqueuing. **Error message:** ``` Failed to enqueue job for processing ``` or ``` Internal server error during document parsing ``` or ``` Failed to create async job ``` or ``` Failed to upload document to S3 ``` **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## ADE Get Parse Jobs Use this section to troubleshoot issues encountered when calling the **[ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-job)** API. ### Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ------------------------------------------------------ | ----------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Job status retrieved successfully. | Check the `status` field. If `completed`, results are in the `data` field (for small results) or `output_url` field (for large results or ZDR). | | 206 | Partial Content | Job completed but some pages failed during processing. | Review the `failed_pages` field in the metadata and the `failure_reason` field. See [Status 206](#status-206-partial-content). | | 404 | Not Found | Job with the specified ID not found. | Verify the job ID is correct. The job may belong to a different API key. | | 422 | Unprocessable Entity | Input validation failed. | Verify the job ID format is correct. | | 500 | Internal Server Error | Server error during job status retrieval. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | ### Job Status Values The `status` field in the response indicates the current state of the job: | Status | Description | | ------------ | --------------------------------------------------------------------------- | | `pending` | Job is queued and waiting to be processed. | | `processing` | Job is currently being processed. | | `completed` | Job completed successfully. Results are available in the response. | | `failed` | Job failed during processing. Check the `failure_reason` field for details. | | `cancelled` | Job was cancelled. | ### Understanding the Response **For completed jobs:** * If results are less than 1 MB, they appear in the `data` field as a `ParseResponse` object. * If results are 1 MB or larger, the `output_url` field contains a presigned S3 URL (expires after 1 hour). * If Zero Data Retention is enabled, results are always saved to your `output_save_url` and not included in the response. **For failed jobs:** * Check the `failure_reason` field for error details. * Common failure reasons include document processing errors or timeout. **Progress tracking:** * The `progress` field shows completion as a decimal from 0 to 1 (e.g., 0.5 = 50% complete). * Progress is based on the number of pages processed. ### Partial Content in Completed Jobs A job can have status `completed` even if some pages failed to process. When this occurs, the API returns a 206 status code. For details on handling partial content, see [Status 206: Partial Content](#status-206-partial-content). ## ADE List Parse Jobs Use this section to troubleshoot issues encountered when calling the **[ADE List Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-list-parse-jobs)** API. ### Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | -------------------------------- | -------------------------------------------------------------------------------------- | | 200 | Success | Job list retrieved successfully. | Review the list of jobs and their statuses. | | 500 | Internal Server Error | Server error during job listing. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | ### Query Parameters You can filter and paginate the job list using these parameters: * `page`: Page number for pagination (default: 1) * `page_size`: Number of jobs per page (default: 10) * `status`: Filter by job status (`pending`, `processing`, `completed`, `failed`, `cancelled`) ### Understanding the Response The response contains: * `jobs`: Array of job summaries with `job_id`, `status`, `received_at` timestamp, and `progress`. * `has_more`: Boolean indicating if more pages are available. * For failed jobs, the `failure_reason` field provides error details. ## When Are Credits Consumed? Credits are consumed only when the ADE Parse or ADE Get Parse Jobs API returns a 200 or 206 status code. All other responses, including errors, do not consume credits. # Extract Data Source: https://docs.landing.ai/ade/ade-extract Pull specific fields from parsed documents with a schema for high-volume, repeatable extraction. ## Overview Use the [ADE Extract API](https://docs.landing.ai/api-reference/tools/ade-extract) to pull specific data fields from parsed documents. You define a schema that specifies which fields to extract, and ADE Extract returns their values in a structured, predictable format. ADE Extract is designed for high-volume, repeatable workflows: use it when you need to retrieve the same set of fields from many documents, such as pulling invoice totals, contract dates, or form field values. Results are consistent across documents with varying layouts because extraction is schema-driven. ## Extraction Capabilities The following capabilities are available with model [`extract-20260314`](./ade-extract-models#extract-20260314) or later. * **Unlimited schema size**: No limits on the number of fields, nested levels, or characters in a schema. * **Semantic field matching**: Use the [`x-alternativeNames`](./ade-extract-schema-json#alternative-names) keyword to define alternative labels for a field. The model maps fields by meaning, so fields with different names across documents resolve to the same schema field. * **Consistent formatting**: Use the [`format`](./ade-extract-schema-json#format) keyword to specify how extracted values should be formatted. * **Improved handling of large content**: Better extraction from large tables, large arrays, and long documents. * **Cross-page table reconstruction**: Tables that span page breaks are returned as a single array, with no post-processing needed. For schema-building capabilities including master schemas and schema drift detection, see [Build Extraction Schemas with the API](./ade-extract-schema-api). ## Run Parse First ADE Extract runs after [Parse](./parse), which is required as the first step in all ADE workflows. It can also follow [Split](./ade-split) if you're working with multi-document files. ## Get Started: Extraction Workflow You can use the schema extraction wizard directly in our [Playground](https://ade.landing.ai/) to build and validate an extraction schema. The Playground generates scripts that you can then copy and use in your own code: 1. Use the schema extraction wizard in our [Playground](./ade-extract-playground) to build a schema tailored to your documents. Build a Schema with the Wizard 2. Copy the script for the method you plan on using: the [ade-python library](./ade-python#extract-getting-started) or the [API](#use-ade-extract-to-extract-fields-from-markdown). Export the Relevant Format 3. Paste the script into your code. ## Use the ADE Extract API to Extract Fields from Markdown Use the ADE Extract API to extract data from the Markdown output created by the [ADE Parse API](./parse). See the full ADE Extract API reference [here](https://docs.landing.ai/api-reference/tools/ade-extract). ### Specify Documents to Run Extraction On The ADE Extract API offers two parameters for specifying the document you want to extract from: * `markdown`: Specify the actual Markdown file you want to run extraction on. * `markdown_url`: Include the URL to the Markdown file you want to run extraction on. ### Set the Extraction Schema Set the extraction schema in the `schema` parameter. The schema must meet specific format and property requirements. For detailed guidance, see [JSON Schema for Extraction](./ade-extract-schema-json). ### Set the `strict` Parameter Use the optional `strict` parameter to control how the API handles schemas that include [keywords that cause errors](./ade-extract-schema-json#keywords-that-cause-errors). * If `strict` is `false`: the API continues processing and returns a `206` (Partial Content). * If `strict` is `true`: the API stops processing and returns a `422` (Unprocessable Entity). In both cases, the API returns `422` if the schema fails validation, and `206` if the extracted output does not conform to the schema after extraction completes. ### Extracted Output For details about the extraction response structure and fields, see [JSON Response for Extraction](./ade-extract-response). ## Run Extract with Our Libraries Click one of the tiles below to learn how to run the [ADE Extract API](https://docs.landing.ai/api-reference/tools/ade-extract) with our libraries. Run Extract with our Python library. TypeScript TypeScript } href="./ade-typescript#extract-getting-started" > Run Extract with our TypeScript library. ## Use Parse Markdown for Best Results The ADE Extract API is optimized for Markdown generated by the ADE Parse API. The parsed output includes element IDs, anchor tags, chunk tags, and other metadata that ADE Extract uses during the extraction process. ADE Extract can also process generic Markdown files or edited Parse Markdown, but results may be less accurate. For best results: * Use only Markdown output from the ADE Parse API, not generic Markdown files. * Do not edit the Markdown from ADE Parse before passing it to ADE Extract. # Extraction Schema (JSON) Source: https://docs.landing.ai/ade/ade-extract-schema-json Structure the JSON schema that tells Extract which fields to pull and how to format output. ## Overview An extraction schema is a JSON object that defines which fields to extract from a document and how to structure the output. You pass the schema to the ADE Extract API along with Markdown content generated by the ADE Parse API. You can build extraction schemas using the [Playground](https://ade.landing.ai/) or the [ADE Build Extract Schema API](./ade-extract-schema-api), both of which generate valid schemas automatically. Use this article as a reference for understanding how schemas are structured and how the API handles unsupported keywords. The schema requirements in this article apply to [`extract-20260314`](./ade-extract-models#extract-20260314) and later. For information about earlier versions, see [Earlier Versions of Extract](#earlier-versions-of-extract). When using the [ade-python](https://github.com/landing-ai/ade-python) library, you can also pass a Pydantic model class instead of a JSON schema. For more information, go to [Python Library](./ade-python). ## Basic Structure The extraction schema must follow this structure: ```json theme={null} { "type": "object", "properties": { "your_field_name": { "type": "string", "description": "Describe what to extract." } } } ``` **Example** This schema extracts two fields from an invoice. It also includes the optional `x-alternativeNames` keyword to account for field name variations across documents: ```json theme={null} { "type": "object", "properties": { "total_invoice_amount": { "description": "The total monetary value of the invoice, including all charges and taxes.", "x-alternativeNames": [ "Total Invoice Amount", "Grand Total", "Amount Due" ], "type": "number" }, "bank_name": { "description": "The official name of the bank where the payment will be deposited.", "x-alternativeNames": [ "Bank Name", "Beneficiary Bank", "Financial Institution" ], "type": "string" } } } ``` Schemas generated by the [Playground](./ade-extract-playground) or the [ADE Build Extract Schema API](./ade-extract-schema-api) automatically include root-level `description` and `required` keywords. These are currently ignored by the ADE Extract API. ### Top-Level Type Requirement The top-level `type` keyword must be `"object"`. Schemas with a different top-level type will return an error. In the following example, the highlighted line shows the required top-level `type` keyword: ```json highlight={2} theme={null} { "type": "object", "properties": {} } ``` ## Define Each Field Each field you want to extract is defined as a property inside the `properties` keyword. Each property can include the following: | | Required | Description | | ------------------------------------------ | --------------------------- | ---------------------------------------------------------------------------- | | [Field name](#field-names) | Required | The key used to identify the extracted value in the output. | | [`type`](#supported-field-types) | Required | The data type of the extracted value. | | [`description`](#field-descriptions) | Optional | Natural-language description of what to extract. | | [`enum`](#restrict-values-with-enum) | Optional | Restricts the extracted value to a set of allowed values. | | [`format`](#format) | Optional | Instructions for how to format the extracted value. | | [`x-alternativeNames`](#alternative-names) | Optional | Alternative labels for the field that may appear across different documents. | | [`properties`](#properties-for-objects) | Required for `object` types | Defines the fields within a nested object. | | [`items`](#format-arrays-with-items) | Required for `array` types | Defines the structure of items in an array. | ### Field Names **Required.** The field name is the key that identifies each property in the `properties` object and determines how the extracted value is labeled in the output. Field names can contain letters, numbers, underscores, and hyphens. Use descriptive, specific names that clearly indicate what data to extract: * `invoice_number` instead of `number` * `patient_name` instead of `name` In the following example, the highlighted lines are field names: ```json highlight={4, 13} theme={null} { "type": "object", "properties": { "account_holder": { "description": "The name of the individual or entity who owns the bank account.", "x-alternativeNames": [ "Account Holder", "Account Owner", "Primary Account Holder" ], "type": "string" }, "ending_balance": { "description": "The total amount of money in the account at the end of a specific period.", "x-alternativeNames": [ "Ending Balance", "Final Balance", "Closing Balance" ], "type": "number" } } } ``` ### Supported Field Types **Required.** Use the `type` keyword to define the data type of the extracted value. Supported types are: | Type | Description | | --------- | -------------------------------------------------------------------------------------------------------------------------------------- | | `array` | A list of items. To see an example, go to [Arrays](#format-arrays-with-items). | | `boolean` | True or false values. | | `integer` | Whole numbers. | | `number` | Numeric values, including decimals. Use this type for monetary values or when you need to perform calculations on the extracted value. | | `object` | A nested structure. To see an example, go to [Nested Objects](#nested-objects). | | `string` | Text values. | In the following example, the highlighted line shows the `type` keyword: ```json highlight={12} theme={null} { "type": "object", "properties": { "statement_date": { "description": "The date on which the financial statement was issued.", "format": "Month DD, YYYY", "x-alternativeNames": [ "Statement Date", "Date of Statement", "Billing Date" ], "type": "string" } } } ``` To restrict a field to a specific set of allowed values, use the [`enum`](#restrict-values-with-enum) keyword. ### Restrict Values with Enum **Optional.** Use the `enum` keyword to restrict the extracted value to a specific set of allowed values. Only string values are supported. Include `"type": "string"` in the field definition. Any non-string values are converted to strings. For example, the following schema restricts the extracted account type to one of three allowed values. The highlighted lines show the `type` and `enum` keywords: ```json highlight={5, 12-16} theme={null} { "type": "object", "properties": { "account_type": { "type": "string", "description": "The classification of the bank account, such as checking or savings, with specific features.", "x-alternativeNames": [ "Account Type", "Type of Account", "Account Category" ], "enum": [ "Premium Checking", "Basic Checking", "Savings" ] } } } ``` In the Playground, "enum" appears as a field type option in the **Type** drop-down menu. When you export the schema, the Playground outputs this correctly using the `enum` keyword. ### Field Descriptions **Optional.** Use the `description` keyword to help the API identify and extract the correct data. The more specific your descriptions, the more accurate the extraction. Include the following in your descriptions: * Exactly what data to extract * What to include or exclude (for example, "excluding tax" or "including area code") In the following example, the highlighted line shows the `description` keyword: ```json highlight={6} theme={null} { "type": "object", "properties": { "total_amount": { "type": "number", "description": "Total amount in USD, excluding tax" } } } ``` ### Format **Optional.** Use the `format` keyword to specify how the extracted value should be formatted. This is most commonly applied to `string` fields. The `format` keyword accepts natural-language instructions and standard [JSON Schema format values](https://www.learnjsonschema.com/2020-12/format-annotation/format/). Natural-language instructions offer more flexibility, since you can describe formatting requirements that don't have a standard equivalent. We recommend experimenting with different values to find what works best for your use case. The following examples illustrate the range of options: | `format` value | Output example | | ------------------------------------------------------- | ------------------ | | `YYYY-MM-DD` | `2026-01-17` | | `Month DD, YYYY` | `January 17, 2026` | | `Currency amount with the $ symbol, for example $12.50` | `$170.23` | | `Two-letter US state code` | `CA` | In the following example, the highlighted line shows the `format` keyword: ```json highlight={6} theme={null} { "type": "object", "properties": { "statement_date": { "type": "string", "format": "YYYY-MM-DD", "description": "The date on which the financial statement was issued." } } } ``` ### Alternative Names **Optional.** Use the `x-alternativeNames` keyword to list alternative labels for a field. This helps the API locate the correct data when documents use different labels for the same field, such as "Invoice Number" versus "Reference Number." In the following example, the highlighted lines show the `x-alternativeNames` keyword: ```json highlight={6-10} theme={null} { "type": "object", "properties": { "total_amount": { "type": "number", "x-alternativeNames": [ "Total Amount", "Grand Total", "Amount Due" ], "description": "The total monetary value of the invoice." } } } ``` ### Properties (For Objects) **Required for `object` types.** Use the `properties` keyword to define the fields within a nested object. For a full example, see [Nested Objects](#nested-objects). ### Format Arrays with `items` **Required for `array` types.** Use the `items` keyword to define the structure of items in an array. For a full example, see [Arrays](#arrays). ## Nested Objects Use nested objects when the data you want to extract has a natural hierarchical structure. For example, an invoice might include a billing address with multiple sub-fields (street, city, state, and ZIP code), or a patient form might have separate sections for personal details and insurance information. In the following example, the highlighted lines show a nested `properties` keyword inside the `invoice` object: ```json highlight={6-19} theme={null} { "type": "object", "properties": { "invoice": { "type": "object", "properties": { "number": { "type": "string", "description": "Invoice number" }, "date": { "type": "string", "description": "Invoice date" }, "total": { "type": "number", "description": "Total amount" } } } } } ``` ## Arrays Use arrays to extract repeating structures from a document, such as all rows in a table. Each item in the array follows the same schema, making arrays well-suited for data like transaction lists, invoice line items, or lists of charges. To define an array field: 1. Set `"type": "array"` on the field. 2. Include the `items` keyword to define the structure of each item. 3. Inside `items`, define the fields each item should contain. The following example extracts financial transactions from a bank statement, where each transaction is an object with three fields: ```json highlight={11, 12-44} theme={null} { "type": "object", "properties": { "transactions": { "description": "A list of all financial transactions recorded for the account.", "x-alternativeNames": [ "Transaction History", "Activity Log", "Movements" ], "type": "array", "items": { "type": "object", "properties": { "date": { "description": "The date when the transaction occurred.", "format": "YYYY-MM-DD", "x-alternativeNames": [ "Transaction Date", "Date of Transaction", "Activity Date" ], "type": "string" }, "description": { "description": "A brief description of the transaction.", "x-alternativeNames": [ "Transaction Description", "Details", "Item" ], "type": "string" }, "type": { "description": "The type of transaction, for example debit, credit, deposit, or withdrawal.", "x-alternativeNames": [ "Transaction Type", "Category", "Kind" ], "type": "string" } } } } } } ``` ## Keyword Support The ADE Extract API only supports a specific set of JSON Schema keywords. Unsupported keywords either cause errors or are silently ignored, depending on the keyword. ### Supported Keywords The ADE Extract API supports the following keywords. For details on each, see [Define Each Field](#define-each-field). * [`description`](#field-descriptions) * [`enum`](#restrict-values-with-enum) (string values only) * [`format`](#format) * [`items`](#format-arrays-with-items) * [`properties`](#properties-for-objects) * [`type`](#supported-field-types) * [`x-alternativeNames`](#alternative-names) ### Ignored Keywords The following keywords are not supported but will not cause errors. The API removes or resolves them before running extraction. | Keyword | How the API handles it | | ---------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | Reference keywords: `$anchor`, `$defs`, `$id`, `$ref`, `$schema`, `definitions` | Used to define and reference reusable schema components. All references are resolved during schema conversion. The keywords are then removed. | | Recursive and dynamic keywords: `$dynamicAnchor`, `$dynamicRef`, `$recursiveAnchor`, `$recursiveRef` | Used for self-referential schemas. All references are resolved during schema conversion. The keywords are then removed. | | `anyOf` | To ensure consistent output, each field is limited to a specific type.
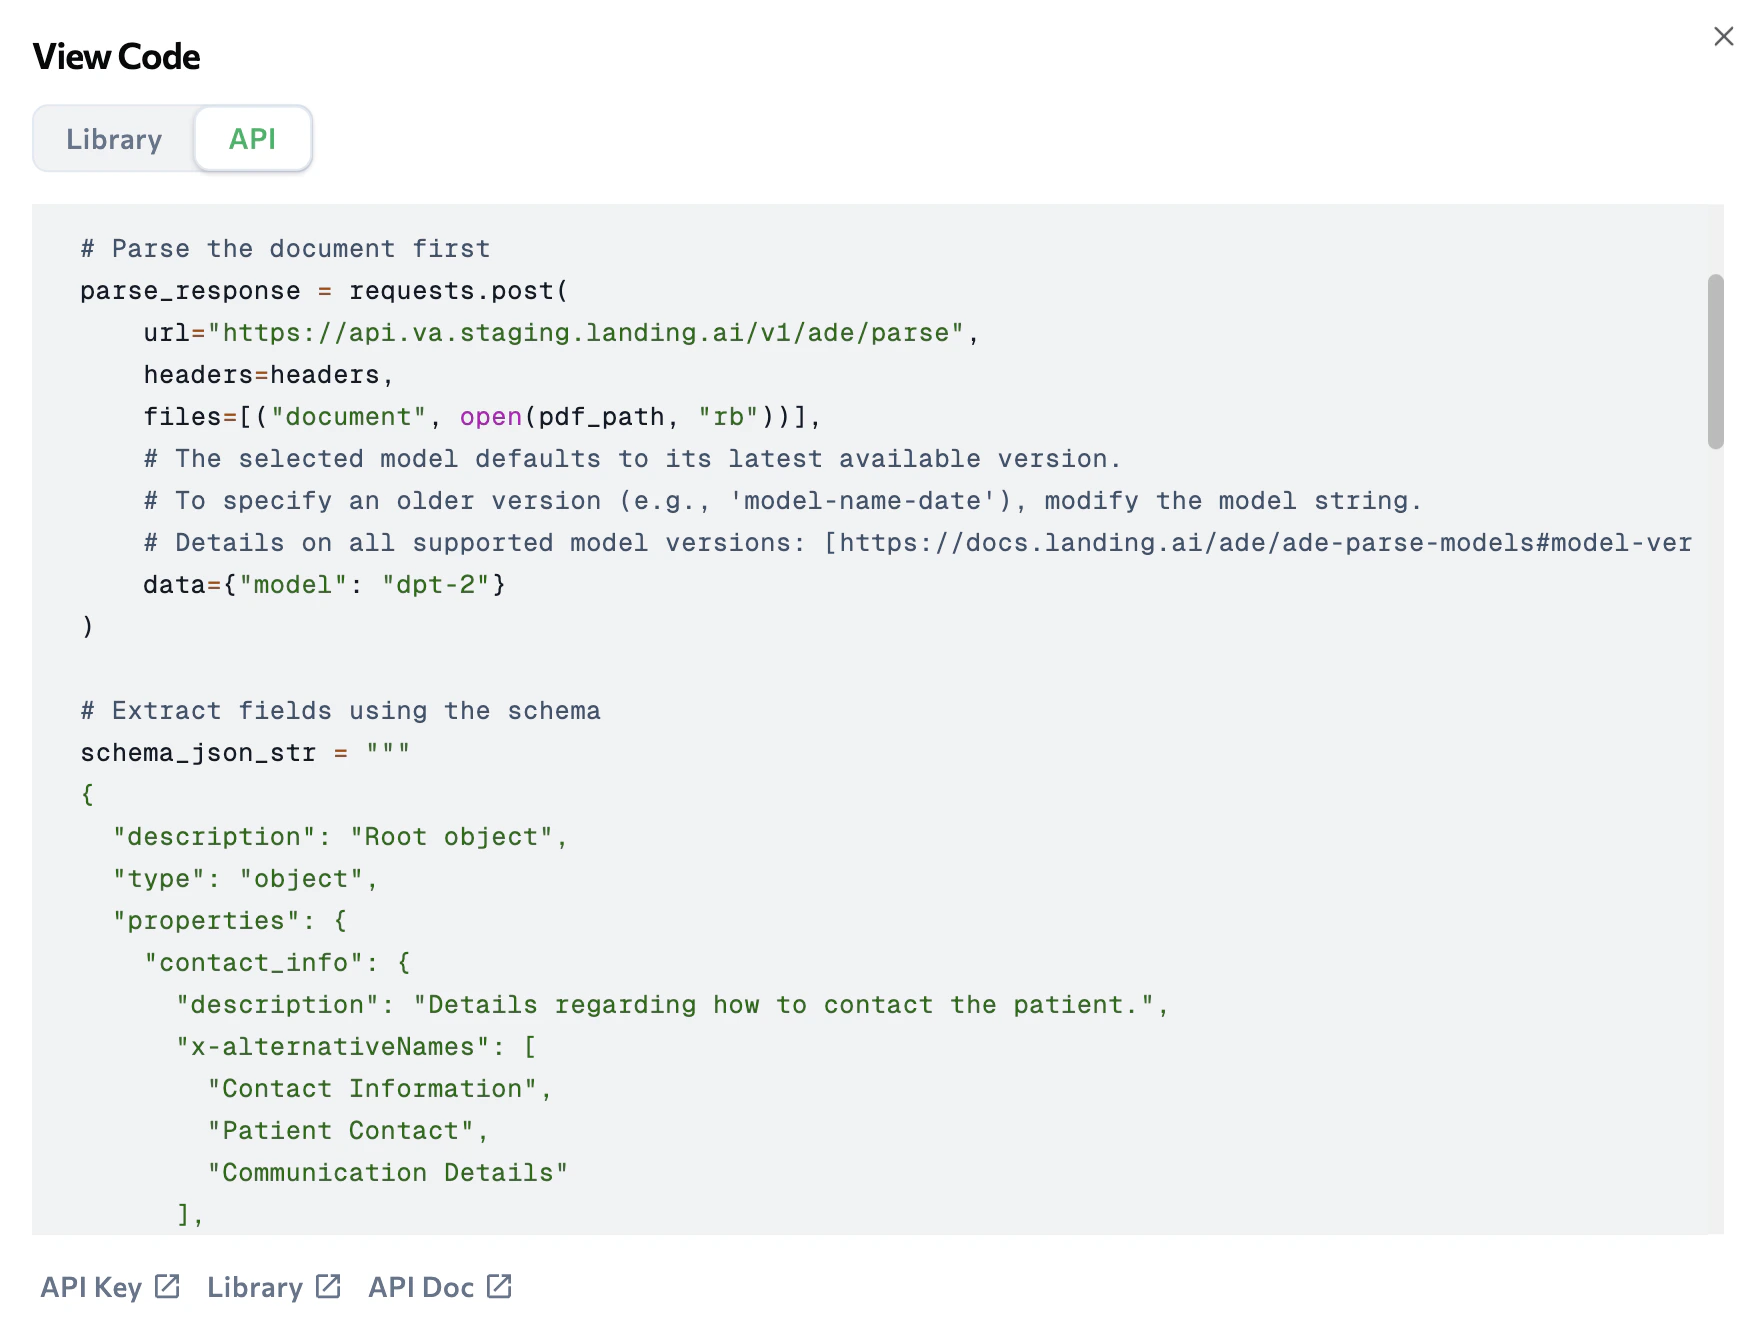
If one of the `anyOf` types is `null`, the API removes `null` and sets the `type` to the other specified type.

If none of the types are `null`, the API falls back to `string`, since that is least likely to cause issues. | | `default` | If `default` is `null`, the API removes the keyword. If `default` is any other value, the API returns a 206. | | `nullable` | The API removes the keyword. All fields are nullable by default. For more information, see [Missing Fields and Nullable Fields](#missing-fields-and-nullable-fields). | | `required` | The API removes the keyword. The API considers all fields to be required. | | `title` | The API removes the keyword. Typically, the title does not give additional information that is not already present in the field name or description. | ### Keywords That Cause Errors Whether the API returns a `206` (Partial Content) or `422` (Unprocessable Entity) depends on the `strict` parameter. If `strict` is `false`, the API returns a `206`. If `strict` is `true`, the API returns a `422`. For more information, see [Set the strict Parameter](./ade-extract#set-the-strict-parameter). **Any keyword not listed in [Supported Keywords](#supported-keywords) or [Ignored Keywords](#ignored-keywords) will cause the API to return an error.** The following list provides common examples and is not exhaustive: * `allOf` * `const` * `maxItems` * `maxLength` * `maximum` * `minItems` * `minLength` * `minimum` * `oneOf` * `pattern` * `propertyOrdering` * `uniqueItems` ## How the API Handles Required Fields The ADE Extract API treats all fields as required and always attempts to extract every property defined in your schema. The `required` keyword is not supported and is ignored if included. For more information, see [Ignored Keywords](#ignored-keywords). If the API cannot find a field in the document, it returns `null` rather than an error. For more information, see [How the API Handles Missing Fields](#how-the-api-handles-missing-fields). ## How the API Handles Missing Fields All fields are nullable, meaning the API returns `null` when it cannot find a field in the document rather than returning an error. Because of this, the API ignores `null` and `nullable` if included in your schema. For more information, see [Ignored Keywords](#ignored-keywords). For example, if your schema includes a `first_name` field but the document does not contain a first name, the API returns `null` for that field. The exact behavior depends on the field type: | Field type | Behavior when not found | | ----------------------------------------------------------- | ----------------------------------------------------------------------- | | Primitive fields (`boolean`, `integer`, `number`, `string`) | Returns `null`. | | `array` | Returns an empty array: `[]`. | | `object` | Never returns `null`, but all primitive fields within it return `null`. | ## Schema Validation The API processes your schema and output in three stages: * [Before Extraction: Validate Schema Structure](#validate-schema-structure-before-extraction) * [During Processing: Convert Schema](#convert-schema-during-processing) * [After Extraction: Validate Extracted Output Against Schema](#validate-extracted-output-against-schema-after-extraction) ### Validate Schema Structure (Before Extraction) The API checks that your schema is valid JSON and follows the required structure. If validation fails, the API returns a `422` error before processing begins. ```json theme={null} { "error": "Invalid JSON schema provided for fields_schema." } ``` ### Convert Schema (During Processing) The API converts your schema before running extraction. If the schema includes [keywords that cause errors](#keywords-that-cause-errors), the behavior depends on the `strict` parameter: * If `strict` is `false`: the API continues and returns a `206` (Partial Content). * If `strict` is `true`: the API stops and returns a `422` (Unprocessable Entity). For more information, see [Set the strict Parameter](./ade-extract#set-the-strict-parameter). ### Validate Extracted Output Against Schema (After Extraction) After extraction completes, the API validates that the extracted output matches your schema. If it does not, the API returns a `206` (Partial Content) with any successfully extracted data. Because the API returns at least partial results, the API call consumes credits. ## FAQs for Extraction Schemas ### Does the order of properties in the schema need to match the order of the fields in the document? No. The order of properties in the schema has no impact on extraction. For example, a property defined last in the schema can still extract data from a field that appears at the top of the document. ### Is there a maximum number of fields that can be extracted? No. There is no maximum number of properties in an extraction schema. ### Can I put formatting and alternative names in the description field? You can include formatting instructions and alternative field names in `description`, but using the dedicated `format` and `x-alternativeNames` keywords is more effective. When you use dedicated keywords, the API knows exactly what each piece of information is: `format` contains only formatting instructions, and `x-alternativeNames` contains only alternative field labels. This allows the API to apply each more precisely than if the same information were embedded in a general description. For more information, see [Format](#format) and [Alternative Names](#alternative-names). ### What is the best practice for writing field descriptions? Be as specific as needed so there is no ambiguity about what to extract. Think of it as natural-language instructions (like prompting an LLM). The clearer and more specific it is, the better the results. You may want to iterate on your descriptions to find what works best for your use case. For more information, see [Field Descriptions](#field-descriptions). ## Earlier Versions of Extract The supported schema structure for the ADE Extract API has changed over time. Extraction schemas generated by Agentic Document Extraction before April 2, 2026 may not be compatible with the current API. Update your schema to meet the requirements described in this article. # Extraction Model Versions Source: https://docs.landing.ai/ade/ade-extract-models Choose an extraction model and set it when running extraction. An extraction model powers the field extraction capabilities of the [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) API. It analyzes your Markdown content and extracts structured data according to your JSON schema. You can specify a model when calling the [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) API directly or when using the [client libraries](#set-the-model-with-the-client-libraries). If you don't specify a model, the API uses the latest extraction model (currently `extract-20260314`). ```shell {5} theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'schema=...' \ -F 'markdown=@markdown.md' \ -F 'model=extract-20260314' ``` ## Model Versions The following table lists the available `model` values for the ADE Extract API: | Model Values | Description | | ------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `extract-20260903` | Use the extraction model snapshot released on September 3, 2026, on an updated underlying model. For more information, go to [extract-20260903](#extract-20260903). | | `extract-20260314` | Use the extraction model snapshot released on March 14, 2026. For more information, go to [extract-20260314](#extract-20260314). This is the default model. | | `extract-latest` | Use the latest extraction model snapshot. | These models have been deprecated and will result in errors: `extract-20250930` and `extract-20251024`. ### Why Model Versioning Matters When integrating the API, you have two options for specifying the model: 1. **Use `extract-latest`** to always get the newest version. This automatically gives you improvements and updates, but extraction results may change when new model versions are released. 2. **Use a specific version** (like `extract-20260314`) to pin to an exact model version. This keeps extraction results consistent until the version is retired or migrated, but you won't receive improvements. ## extract-20260903 This model version runs extraction on an updated underlying model. One of our third-party model providers is retiring the model that earlier versions use. The version is tuned to match `extract-20260314`, and some field values may differ. `extract-latest` and requests without a `model` value still use `extract-20260314`. Organizations on subscription and enterprise plans move to `extract-20260903` on October 7, 2026. After your organization moves, every extraction model value, including `extract-latest` and pinned versions, runs on `extract-20260903`. To test your own documents first, set `model` to `extract-20260903`. ## extract-20260314 This model version introduces the following capabilities: * **Unlimited schema size**: No limits on the number of fields, nesting levels, or characters in a schema. * **Semantic field matching**: Use the [`x-alternativeNames`](./ade-extract-schema-json#alternative-names) keyword to define alternative labels for a field. The model maps fields by meaning, so fields with different names across documents resolve to the same schema field. * **Cross-page table reconstruction**: Tables that span page breaks are returned as a single array, with no post-processing needed. * **Master schemas**: Generate a single schema from multiple documents to handle field and layout variation across document types. Available in the [Playground](./ade-extract-playground) and via the [ADE Build Extract Schema API](./ade-extract-schema-api). * **Schema drift detection**: Update an existing schema when new or changed fields appear in your documents. Available in the [Playground](./ade-extract-playground) and via the [ADE Build Extract Schema API](./ade-extract-schema-api). This version also introduces the `metadata.warnings` field in the API response. For more information, go to [Warnings](./ade-extract-troubleshoot#warnings). Extraction model `extract-20260314` has different JSON schema requirements than the previous model. Learn about all schema requirements in [Extraction Schema (JSON)](./ade-extract-schema-json). ## Set the Model in the API When calling the [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) endpoint, you can set the model using the `model` parameter. If you omit the `model` parameter, the API uses the latest model. This example shows how to specify a model: ```shell {5} theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'schema={"type": "object", "properties": {"field1": {"type": "string"}, "field2": {"type": "string"}}}' \ -F 'markdown=@markdown.md' \ -F 'model=extract-latest' ``` ## Set the Model with the Client Libraries When using the Python or TypeScript library, you can set the model using the `model` parameter in the `extract()` method. If you omit the `model` parameter, the library will use the latest extraction model. ```python {20} Python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE # Define your extraction schema schema_dict = { "type": "object", "properties": { "field1": {"type": "string"}, "field2": {"type": "string"} } } client = LandingAIADE() schema_json = json.dumps(schema_dict) response = client.extract( schema=schema_json, markdown=Path("/path/to/output.md"), model="extract-latest" ) ``` ```typescript {26} TypeScript theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; // Define your extraction schema const schemaDict = { type: "object", properties: { field1: { type: "string" }, field2: { type: "string" } } }; const client = new LandingAIADE(); const schemaJson = JSON.stringify(schemaDict); // Parse the document first const parseResponse = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest" }); // Extract with the specified model const extractResponse = await client.extract({ schema: schemaJson, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); ``` ## The Playground Uses the Most Recent Model The [Playground](https://ade.landing.ai/) always uses the most recent extraction model. If you pin a specific model version in your code, results may differ slightly from what you see in the Playground. ## The Model Impacts the Schema Requirements Different model versions have different [JSON schema requirements](./ade-extract-schema-json). For details on supported keywords, field types, and structure, see [Extraction Schema (JSON)](./ade-extract-schema-json). # Schema Wizard: Build Extraction Schemas in the Playground Source: https://docs.landing.ai/ade/ade-extract-playground Build and test an extraction schema visually with the Playground schema wizard. Use the schema wizard in the [Playground](https://ade.landing.ai/demo/doc-extraction) to build and test an extraction schema. The schema defines which fields to extract from your documents and is used with the [ADE Extract API](./ade-extract). You can also create a schema [manually](./ade-extract-schema-json) or with the [ADE Build Extract Schema API](./ade-extract-schema-api). The wizard is a good option if: * You want the Playground to enforce schema rules and formatting requirements automatically, without needing to know them yourself * You want immediate visual feedback on how the schema performs on your files * You prefer a visual, guided experience over writing JSON directly ## Workflow Use our AI-powered tools to generate a schema. Update and edit the schema, and see how it works with your document. Export your schema to use with our library or API. All files and their corresponding schemas are saved to a project. You can access these in **Projects**. ## Create a Schema * [Create a Schema with AI](#create-a-schema-with-ai) * [Upload a Schema](#upload-a-schema) ### Create a Schema with AI **Suggest Schema** calls the [ADE Build Extract Schema API](./ade-extract-schema-api) and consumes credits. See [Build Extract Schema API pricing](./ade-credit-consumption#credit-costs-for-the-build-extract-schema-api). The Extract tool in the Playground generates a schema based on the files in your project. It factors in the data in the files and the file structures. Fields and layouts from each file are incorporated, so the schema covers variation across all the documents in the project. To create an extraction schema: 1. Go to the [Playground](https://ade.landing.ai/). 2. Click the **Extract** tile. Start Extract 3. Upload files and click **Create Project**. (Continue to the next step while the files are parsed in the background.) 4. (Optional) Enter natural-language instructions for the extraction in the **Guidelines** text box. This can include: * Data to include * Data to exclude * Context about the files 5. Click **Suggest Schema**. Smart Suggestions 6. The app reviews the files in the project and creates a master schema. Review the generated fields before continuing. Smart Suggestions 7. Click [**Run This File**](#run-the-schema-on-your-files) to validate the schema on the selected file. Smart Suggestions 8. When the schema is ready, [use the schema](#use-the-schema). ### Upload a Schema If you have an existing extraction schema you want to edit, you can upload it to the Playground to validate it. You can then edit it just like any schema created in the Playground. **Start a new project with your own schema** To start with your own extraction schema: 1. Go to the [Playground](https://ade.landing.ai/). 2. Click the **Extract** tile. Start Extract 3. Upload files and click **Create Project**. (Continue to the next step while the files are parsed in the background.) 4. Click **Upload JSON Schema**. Upload JSON Schema 5. Select the JSON file you want to load. 6. The app loads the JSON file into the **Schema** panel. **Upload a schema to an existing project** You can also upload a schema after you've started building one. The uploaded schema is saved as a new version. To upload a schema to an existing project: 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. In the **Schema** panel, click **...** and select **Import Schema**. Import Schema 5. Select the JSON file you want to load. 6. The app loads the JSON file into the **Schema** panel. ## Edit and Validate the Schema After creating a schema in the [Playground](https://ade.landing.ai/), you can edit and validate it. You can add fields, update descriptions, remove fields, and validate the full schema. * [Edit, Add, or Remove Fields Manually](#edit-add-or-remove-fields-manually) * [Refine Schema with AI](#refine-schema-with-ai) * [Run the Schema on Your Files](#run-the-schema-on-your-files) * [Start Over](#start-over) ### Edit, Add, or Remove Fields Manually Click a field to see and edit additional information, like the format, description, and alternative names. For detailed information about the field options, go to [Extraction Schema (JSON)](./ade-extract-schema-json). To add, edit, or remove fields: 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. If you have multiple versions of the schema, make sure that the schema you want to use is selected. 5. Make your changes: * **Add a field**: Scroll to the bottom of the **Schema** panel and click **New Field**. * **Edit a field**: Click the field and update it. * **Remove a field**: Hover over the field and click the **Delete** icon. 6. After making any changes to the schema, click **Update Schema**. ### Refine Schema with AI **Refine Schema** calls the [ADE Build Extract Schema API](./ade-extract-schema-api) and consumes credits. See [Build Extract Schema API pricing](./ade-credit-consumption#credit-costs-for-the-build-extract-schema-api). After creating a schema, you can edit it using the AI-powered "Refine Schema" tool. To refine a schema using AI: 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. If you have multiple versions of the schema, make sure that the schema you want to use is selected. 5. You can do one or both of the following: * Describe the edits you want to make in the **Refine Schema** text box. * If you want to add more files that should be factored into the schema, click the **+** icon and select those files. 6. Click **Update**. The schema updates based on the input you provided. Refine Schema ### Run the Schema on Your Files **Run This File** calls the [ADE Extract API](./ade-extract) and consumes credits. See [Extract API pricing](./ade-credit-consumption#credit-costs-for-the-extract-api). Run the schema on one or more files to validate that it extracts the expected data. To run the schema: 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. In the **Files** panel, select the file you want to run the schema on. 5. If you have multiple versions of the schema, make sure that the schema you want to use is selected. 6. Click **Run This File**. Run the extraction schema on the file The **Extracted Results** panel refreshes and displays two sets of content: * **Extraction**: The list of extracted key-value pairs. * **Extract Metadata**: The key-value pairs and their unique IDs (`references`). For more information about extraction output, go to [JSON Response for Extraction](./ade-extract-response). Extracted Results ### Start Over After you create a schema, you can start over. This creates a new blank schema, saved as the next version, while retaining all existing schema versions. You can then manually add fields, refine the schema with AI, or import a schema. To start over: 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. In the **Schema** panel, click **...** and select **Start Over**. Start Over 5. When prompted, click **Start Fresh**. ## Use the Schema After you create and validate a schema, you are ready to use it. * [Get a Ready-to-Use Parse and Extract Script](#get-a-ready-to-use-parse-and-extract-script): Get a ready-to-use script for Parse and Extract that uses the schema you created. * [Export the Schema](#export-the-schema): Download the schema as a JSON file to use in your own code. ### Get a Ready-to-Use Parse and Extract Script After you create a schema, Agentic Document Extraction generates a script that covers both the [ADE Parse](./parse) and [ADE Extract](./ade-extract) steps using the schema you built. The Playground provides two versions: one for calling the APIs directly, and one for the [ade-python library](./ade-python). **To get the script:** 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. If you have multiple versions of the schema, make sure that the schema you want to use is selected. 5. Click **Code**. View the Schema Code 6. The **View Code** pop-up opens. Click the **Library** or **API** tab to see the code for each extraction method. 7. Click the **Download** or **Copy** buttons to get the code. Get the Schema Code ### Export the Schema After you create a schema, you can export it as a downloadable JSON file to use in your own code. **To export the schema:** 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. If you have multiple versions of the schema, make sure that the schema you want to use is selected. 5. In the **Schema** panel, click **...** and select **Export Schema**. Export Schema 6. The extraction schema is downloaded as a JSON file. ## Schema Versions The Playground saves a new version of the schema each time you run **Suggest Schema**, **Refine Schema**, or import a schema. Previous versions are retained even after you use **Start Over**. Use schema versions to compare results or roll back to an earlier version if a schema update doesn't perform as expected. To view a previous version, click the drop-down menu in the **Schema** panel and select the version you want to see. Schema Versions ## Download or Copy Extracted Data You can download or copy extracted data directly from the Playground. This is useful for spot-checking results during schema development. For production use, retrieve extracted data through the [ADE Extract API](./ade-extract) or [ade-python library](./ade-python). To download or copy the extracted data: 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Extract** tab. 4. If the **Extracted Results** panel doesn't display, create or edit a schema and click **Run This File**. 5. Click the **Download** or **Copy** buttons to get the extracted data. Copy the Extracted Values # Build Extraction Schemas with the API Source: https://docs.landing.ai/ade/ade-extract-schema-api Generate a JSON extraction schema programmatically from parsed Markdown with the Build Extract Schema API. Use the [ADE Build Extract Schema API](https://docs.landing.ai/api-reference/tools/ade-build-schema) to programmatically generate a JSON extraction schema from the Markdown output of the [ADE Parse API](./parse). The API analyzes the Markdown content and returns a schema you can pass directly to the [ADE Extract API](./ade-extract). Each call to the ADE Build Extract Schema API consumes credits. See [Build Extract Schema API pricing](./ade-credit-consumption#credit-costs-for-the-build-extract-schema-api). ## When to Use the Schema Builder API The [ADE Build Extract Schema API](https://docs.landing.ai/api-reference/tools/ade-build-schema) is useful when you want to automate schema creation or refinement as part of a larger pipeline, without using the [Playground schema wizard](./ade-extract-playground). Use the API to: * [Build a master schema](#generate-a-master-schema-from-markdown-files) from multiple documents to handle field and layout variation across document types. * [Detect schema drift](#detect-schema-drift-and-refine-an-existing-schema) by passing updated documents alongside an existing schema to surface new or changed fields before they reach your pipeline. For schema format requirements and supported field types, see [Extraction Schema (JSON)](./ade-extract-schema-json). ## API Reference See the full ADE Build Extract Schema API reference [here](https://docs.landing.ai/api-reference/tools/ade-build-schema). Endpoint: `https://api.va.landing.ai/v1/ade/extract/build-schema` ## Request Parameters At least one of `markdowns`, `markdown_urls`, or `prompt` must be provided. | Parameter | Type | Required | Description | | --------------- | ---------------- | -------- | ----------------------------------------------------------------------------------------------------------------------------- | | `model` | string | No | The extraction model to use. Use `extract-latest` for the latest version. | | `markdowns` | file or string | No | One or more Markdown files or inline Markdown strings to analyze. Provide multiple Markdown files for better schema coverage. | | `markdown_urls` | array of strings | No | URLs to Markdown files to analyze. | | `prompt` | string | No | Instructions for how to generate or modify the schema. | | `schema` | string | No | An existing JSON schema to refine or iterate on. | ## Response The response contains: * `extraction_schema` (string): The generated JSON schema, returned as a string. * `metadata`: Includes `job_id`, `duration_ms`, `credit_usage`, and `version`. ## Workflows ### Generate a Master Schema from Markdown Files Pass one or more Markdown files to generate a schema based on the content. The API identifies the fields present in the Markdown and returns an extraction schema. ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdowns=@markdown.md' \ -F 'model=extract-latest' ``` To build a master schema that covers multiple document types, pass multiple Markdown files that represent the range of layouts you expect to process. The API generates a single schema that handles field and layout variation across all of them: ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdowns=@markdown_1.md' \ -F 'markdowns=@markdown_2.md' \ -F 'model=extract-latest' ``` ### Generate a Schema from a Prompt Use the `prompt` parameter to specify which fields to extract. This is useful when you only need a subset of the fields in the Markdown file, or when you want to shape the field names and structure. ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdowns=@markdown.md' \ -F 'model=extract-latest' \ -F 'prompt=Extract the vendor name, invoice date, and total amount due' ``` You can also use `prompt` without any Markdown input to generate a schema based on instructions alone: ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'model=extract-latest' \ -F 'prompt=Create a schema for extracting patient name, date of birth, and insurance provider from medical intake forms' ``` ### Detect Schema Drift and Refine an Existing Schema Pass an existing schema in the `schema` parameter to refine it. This is useful for schema drift detection: if a new document type enters your pipeline (for example, invoices from a new vendor that uses a different layout and field names), you can pass the new Markdown alongside your current schema. The API surfaces new or changed fields so you can update the schema before it affects your pipeline. To refine a schema based on a Markdown file: ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdowns=@markdown.md' \ -F 'model=extract-latest' \ -F 'schema={"type":"object","properties":{"vendor":{"type":"string"},"total":{"type":"number"}}}' ``` To update a schema based on a prompt: ```bash theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'model=extract-latest' \ -F 'schema={"type":"object","properties":{"vendor":{"type":"string"},"total":{"type":"number"}}}' \ -F 'prompt=Add a field for the invoice number and make the total field return a string with the currency symbol' ``` # JSON Response for Extraction Source: https://docs.landing.ai/ade/ade-extract-response Understand the extraction JSON response: extracted values, field references, and metadata. When you extract structured data with the [ADE Extract API](https://docs.landing.ai/api-reference/tools/ade-extract), the extracted data and metadata are returned in a structured JSON format. ## Response Structure The response contains the following top-level fields: * [`extraction`](#extracted-data-extraction): The extracted key-value pairs as defined by your schema. * [`extraction_metadata`](#extraction-metadata-extraction_metadata): Metadata showing which chunks were referenced for each extracted field. * [`metadata`](#processing-metadata-metadata): Processing information including credit usage, duration, filename, job ID, version, schema validation errors, and warnings. ## Extracted Data (`extraction`) The `extraction` field contains the structured data extracted from your document, formatted according to your JSON schema. The structure matches your input schema exactly. For a simple schema: ```json theme={null} { "type": "object", "properties": { "employee_name": { "type": "string", "description": "The employee's full name" }, "employee_ssn": { "type": "string", "description": "The employee's Social Security Number" }, "gross_pay": { "type": "number", "description": "The gross pay amount" } } } ``` The `extraction` field returns: ```json theme={null} { "employee_name": "MICHAEL D BRYAN", "employee_ssn": "555-50-1234", "gross_pay": 6000.00 } ``` ## Extraction Metadata (`extraction_metadata`) The `extraction_metadata` field has the same structure as your extraction schema, but each field contains a dictionary with `references` that lists the HTML element IDs where the data was found. The `references` field can contain: * **Chunk IDs**: UUID-format IDs (e.g., `72ba3cca-01e5-407b-9fc4-81f54f9f0c51`) that reference entire chunks like text blocks or figures * **Table cell IDs**: Format `{page_number}-{base62_sequential_number}` (e.g., `0-u`) when extracted data comes from table cells * **Other HTML element IDs**: Any ID attribute from HTML elements within the [`markdown` fields](./ade-markdown-response) from the parsed output This metadata is useful for: * Tracing which parts of the document contributed to each extracted field * Debugging extraction issues * Building confidence scores or validation logic * Creating audit trails for extracted data ### Simple Schema Metadata For a simple extraction schema, the metadata includes the value and references for each field. When data is extracted from text chunks, references contain chunk IDs (UUIDs): ```json theme={null} { "employee_name": { "value": "MICHAEL D BRYAN", "references": [ "72ba3cca-01e5-407b-9fc4-81f54f9f0c51" ] }, "employee_ssn": { "value": "555-50-1234", "references": [ "a3f5d8c9-2b4e-4a1c-8f7e-9d6c5b4a3e2f" ] } } ``` When data is extracted from table cells, references contain table cell IDs: ```json theme={null} { "employee_name": { "value": "JANE HARPER", "references": [ "75a62de4-5120-44bf-a6dd-b2aa63db18c6" ] }, "gross_pay": { "value": 452.43, "references": [ "0-u" ] } } ``` In this example, `"0-u"` is a table cell ID where `0` indicates page 0 and `u` is the base62-encoded sequential number for that cell. ### Nested Schema Metadata For nested extraction schemas, the metadata preserves the same nested structure: ```json theme={null} { "patient_details": { "patient_name": { "value": "John Smith", "references": [ "72ba3cca-01e5-407b-9fc4-81f54f9f0c51" ] }, "date": { "value": "2024-01-15", "references": [ "72ba3cca-01e5-407b-9fc4-81f54f9f0c51" ] } }, "emergency_contact_information": { "emergency_contact_name": { "value": "Jane Smith", "references": [ "5b8865b9-1a81-46df-bcf7-0bdbed9130dc" ] }, "relationship_to_patient": { "value": "Spouse", "references": [ "5b8865b9-1a81-46df-bcf7-0bdbed9130dc" ] } } } ``` ## Processing Metadata (`metadata`) The `metadata` field provides information about the extraction process: | Field | Type | Description | | ------------------------ | -------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `filename` | string | The name of the input file. | | `org_id` | string | Organization identifier. | | `duration_ms` | number | Processing time in milliseconds. | | `credit_usage` | number | Number of credits consumed. | | `job_id` | string | Unique job identifier. | | `version` | string | Model version used for extraction. For more information, go to [Extraction Model Versions](./ade-extract-models). | | `fallback_model_version` | string \| null | The extract model that was actually used when the initial extraction attempt failed with the requested version. `null` if no fallback occurred. | | `schema_violation_error` | string \| null | Error message if extracted data doesn't conform to the input schema. `null` if the schema is valid. For more information, go to [Troubleshoot Extraction](./ade-extract-troubleshoot). | | `warnings` | array | Structured warning objects generated during extraction. Each warning has a `code` that identifies the warning type and a `msg` (human-readable description). For more information, go to [Warnings](./ade-extract-troubleshoot#warnings). | ## Example Response Here is a complete example showing the extraction response structure: ```json theme={null} { "extraction": { "account_holder_name": "SUSAN SAMPLE", "account_number": "02782-5094431", "closing_balance": 3664.79 }, "extraction_metadata": { "account_holder_name": { "references": [ "55d1b275-b539-4af7-ac85-3396f62c216e" ], "value": "SUSAN SAMPLE" }, "account_number": { "references": [ "dd784487-910c-4cb7-8bb2-d4a7ef3d952b", "0-3" ], "value": "02782-5094431" }, "closing_balance": { "references": [ "0-e" ], "value": 3664.79 } }, "metadata": { "credit_usage": 0.8583999999999999, "duration_ms": 9893, "filename": "upload.md", "job_id": "1c08692d839c4c33bd85aebfafeab5e9", "org_id": "lgy5xucm9xnq", "version": "extract-20260314", "fallback_model_version": null, "schema_violation_error": null, "warnings": [] } } ``` # Asynchronous Extraction (Extract Jobs) Source: https://docs.landing.ai/ade/ade-extract-async The [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) API enables you to extract structured data from large Markdown documents asynchronously. Instead of waiting for a single request to finish, you create a job, receive a `job_id` immediately, and retrieve the results when the job is complete. Use Extract Jobs for long-running extractions, such as when extracting from long documents or when using large, complex schemas. ## Run Parse First ADE Extract runs on the Markdown output created by [Parse](./parse), which is required as the first step in all ADE workflows. For large documents, use [Parse Jobs](./ade-parse-async) to generate the Markdown, then pass that Markdown to Extract Jobs. ## Monitor Extract Jobs You can monitor extract jobs with these APIs: * [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs): Get the status for a specific extract job. * [ADE List Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-list-extract-jobs): List all extract jobs associated with your API key. ## Rate Limits for ADE Extract Jobs Extract Jobs have their own per-hour rate limit, separate from the other ADE APIs. Each extract job counts as a single submission (one page equivalent) toward this limit, regardless of the size of the Markdown document. To see the rate limits for all APIs, go to [Rate Limits](./ade-rate-limits). ## API Reference To learn more, go to the reference pages for the Extract Jobs APIs: * [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) * [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) * [ADE List Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-list-extract-jobs) For credit consumption rates, see [Credit Consumption](./ade-credit-consumption#credit-costs-for-the-extract-api). ## Workflow Overview 1. Create an extraction schema. For schema requirements, see [JSON Schema for Extraction](./ade-extract-schema-json). 2. Submit the Markdown and schema to the [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) API. 3. Get the `job_id` from the API response. 4. Poll the [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) API with the `job_id` until `status` is `completed`. 5. Read the extracted fields from the completed job response. For the field structure, see [JSON Response for Extraction](./ade-extract-response). ## Job Statuses The [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) API returns the current `status` of a job: | Status | Description | | :----------- | :-------------------------------------------------------------------------------------------------------------- | | `pending` | The job is queued and has not started. | | `processing` | The job is running. The `progress` field stays `0.0` until the job is `completed`. | | `completed` | The job finished. The extracted fields are in the `data` field, or in the `output_url` field for large results. | | `failed` | The job did not finish. See the `failure_reason` field for details. | | `cancelled` | The job was cancelled. | ## Extract Job Response When the [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) API returns a job, the response wraps the extraction results with job-level fields: | Field | Description | | :--------------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `job_id` | The unique identifier for the job. | | `status` | The current state of the job. See [Job Statuses](#job-statuses). | | `received_at` | Unix timestamp (in seconds) for when the job was received. | | `created_at` | Unix timestamp (in seconds) for when the job was created. | | `progress` | Either `0.0` (not yet complete) or `1.0` (complete). | | `org_id` | The organization ID associated with the job. | | `version` | The model snapshot used for the extraction. | | `data` | The extraction results, returned when the job is complete and you did not set an `output_save_url`. This object follows the same structure as the standard ADE Extract API response, including the extraction `metadata` (with `schema_violation_error`, `warnings`, and `fallback_model_version`). See [JSON Response for Extraction](./ade-extract-response). | | `output_url` | A URL to download the extraction results, returned when the result is larger than 1 MB or you set an `output_save_url`. When `output_url` is present, `data` is `null`. | | `metadata` | Job-level metadata summarizing the job, such as `filename`, `duration_ms`, `credit_usage`, and `version`. | | `failure_reason` | If the job failed, a message describing what went wrong. Otherwise, `null`. | This example shows the structure of a completed job response, with the extraction abbreviated: ```json theme={null} { "job_id": "cmf8x2k9p0001abcd1234efgh", "status": "completed", "received_at": 1781819747, "created_at": 1781819747, "progress": 1.0, "org_id": "a1b2c3d4e5f6", "version": "extract-20260314", "data": { "extraction": { "exam_date": "2010-05-20", "procedure": "MRI OF THE LUMBAR SPINE WITH AND WITHOUT CONTRAST" }, "extraction_metadata": { "exam_date": { "references": ["93996806-781d-4404-bfa4-f6e49323a227"], "value": "2010-05-20" } }, "metadata": { "filename": "markdown-mri-report.md", "duration_ms": 6807, "credit_usage": 1.4, "version": "extract-20260314", "schema_violation_error": null, "warnings": [] } }, "output_url": null, "metadata": { "filename": "markdown-mri-report.md", "duration_ms": 8100, "credit_usage": 1.4, "version": "extract-20260314" }, "failure_reason": null } ``` ## ZDR Requirements When [zero data retention](./zdr) (ZDR) is enabled, you must configure the following parameters so that Agentic Document Extraction does not retain your content: * **Pass your Markdown in the `markdown_url` parameter**. You cannot upload a local file with the `markdown` parameter when ZDR is enabled. * **Include the `output_save_url` parameter**. This saves the extracted content to your specified URL instead of returning it in the API response. ## End-to-End Workflow: Parse a Document and Extract Fields This tutorial walks you through how to parse a document into Markdown, create an extract job from that Markdown, and retrieve the extracted fields. The script runs all three steps in sequence and polls for the results, so you never copy the `job_id` by hand. For simplicity, this example uses a short, 2-page PDF and the synchronous [Parse](./parse) API. For large documents, use [Parse Jobs](./ade-parse-async) to generate the Markdown. ### 1. Download the Document Download the sample MRI Report and save it to a local directory. ### 2. Create the Script Copy the script below and save it as `extract-job.py` in the same directory as the PDF. ```python [expandable] theme={null} import requests import json import time headers = { # Replace YOUR_API_KEY with your API key 'Authorization': 'Bearer YOUR_API_KEY' } # 1. Parse the document into Markdown # Replace mri-report.pdf with the path to your document parse_url = 'https://api.va.landing.ai/v1/ade/parse' parse_files = {'document': open('mri-report.pdf', 'rb')} parse_data = {'model': 'dpt-2-latest'} parse_response = requests.post(parse_url, files=parse_files, data=parse_data, headers=headers) parse_response.raise_for_status() markdown = parse_response.json()['markdown'] # Save the Markdown so it can be uploaded to the extract job with open('markdown-mri-report.md', 'w', encoding='utf-8') as f: f.write(markdown) # Define the extraction schema schema = json.dumps({ "type": "object", "properties": { "exam_date": { "description": "The date on which the medical examination or procedure was performed.", "format": "YYYY-MM-DD", "type": "string" }, "procedure": { "description": "The specific medical procedure or examination that was conducted, such as an MRI or X-ray.", "type": "string" } } }) # 2. Create the extract job extract_url = 'https://api.va.landing.ai/v1/ade/extract/jobs' extract_files = {'markdown': open('markdown-mri-report.md', 'rb')} extract_data = {'schema': schema, 'model': 'extract-latest'} create_response = requests.post(extract_url, files=extract_files, data=extract_data, headers=headers) create_response.raise_for_status() job_id = create_response.json()['job_id'] print(f"Created job: {job_id}") # 3. Poll the job until it finishes, then save the results # This loop polls until the job reaches a final status. For production use, # consider adding a timeout and exponential backoff instead of polling forever. while True: job = requests.get(f'{extract_url}/{job_id}', headers=headers) job.raise_for_status() result = job.json() status = result.get('status') print(f"Job status: {status}") if status == 'completed': if result.get('data'): # The extracted fields are returned inline in the data field with open('extract_output.json', 'w') as f: json.dump(result['data'], f, indent=2) print("Results saved to extract_output.json.") elif result.get('output_url'): # Large results or ZDR jobs return a download URL instead of inline data print(f"Download the results from: {result['output_url']}") break if status in ('failed', 'cancelled'): print(f"Job {status}: {result.get('failure_reason')}") break time.sleep(5) # wait before checking again ``` ### 3. Run the Script Run the script from the same directory: ```bash theme={null} python extract-job.py ``` ### 4. View the Results When the job status is `completed`, the script saves the extracted fields to `extract_output.json`. The completed job returns the results in one of two ways: | Field | When It's Returned | Contents | | :----------- | :---------------------------------------------------------------------- | :--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `data` | The result is 1 MB or smaller and you did not set an `output_save_url`. | The extracted fields, returned inline. This field follows the same structure as the standard ADE Extract API response. See [JSON Response for Extraction](./ade-extract-response). | | `output_url` | The result is larger than 1 MB, or you set an `output_save_url`. | A temporary URL to download the results. The `data` field is `null`, and the URL expires one hour after you request the job. | ## Library Support Extract Jobs is not available in the Python or TypeScript libraries. Call the Extract Jobs APIs directly. # Troubleshoot Extraction Source: https://docs.landing.ai/ade/ade-extract-troubleshoot Resolve Extract and Build Extract Schema errors using status codes, causes, and fixes. Use this section to troubleshoot issues encountered when calling the extraction APIs: * **[ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract)**: `/v1/ade/extract` * **[ADE Build Extract Schema](https://docs.landing.ai/api-reference/tools/ade-build-schema)**: `/v1/ade/extract/build-schema` * **[ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs)**: `/v1/ade/extract/jobs` * **[ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs)**: `/v1/ade/extract/jobs/{job_id}` * **[ADE List Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-list-extract-jobs)**: `/v1/ade/extract/jobs` ## Common Status Codes These status codes apply to all extraction endpoints. | Status Code | Name | Description | What to Do | | ----------- | ----------------- | ----------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------- | | 401 | Unauthorized | Missing or invalid API key. | Check that your `apikey` header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. | ## ADE Extract This section covers errors for the ADE Extract API. ### Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ---------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | 200 | Success | Extraction completed successfully and extracted data conforms to the schema. | Continue with normal operations. | | 206 | Partial Content | Extraction completed but extracted data does not fully conform to the schema. | Review the `schema_violation_error` field in the response and adjust your schema or document. See [Status 206: Partial Content](#status-206-partial-content). | | 400 | Bad Request | Invalid request due to malformed input, unsupported version, or client-side extraction errors. | Review error message for specific issue. See [Status 400: Bad Request](#status-400-bad-request). | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See [Status 422: Unprocessable Entity](#status-422-unprocessable-entity). | | 500 | Internal Server Error | Server error during processing. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500: Internal Server Error](#status-500-internal-server-error). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit (475 seconds). | Reduce document size or simplify extraction schema. See [Status 504: Gateway Timeout](#status-504-gateway-timeout). | ### Status 206: Partial Content This response occurs when extraction completes successfully but the extracted data does not fully conform to the provided JSON schema. The API returns a 206 status code with the extracted data and a `schema_violation_error` field that contains details about the validation failure. For `extract-20260314` and above, the `metadata.warnings` field also contains structured warning objects. See [Warnings](#warnings). The errors in this section may appear in the `schema_violation_error` field when you receive a 206 status code. Because the API returns at least partial results, the API call consumes credits. **What to do:** * Review the specific validation error in the `schema_violation_error` field. * Verify the JSON schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. * Check if the document contains the expected data in the expected format. #### Extracted data does not completely conform to the requested schema This occurs when the extracted data violates the JSON schema validation rules. The message includes details from the validation process. **Message:** ``` Extracted data does not completely conform to the requested schema. See below error for details. {validation_error_details} Please read our documentation for more information: https://docs.landing.ai/ade/ade-extract-troubleshoot ``` **What to do:** * Review the validation details to identify the specific schema violation. * Verify the JSON schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. * Check if the document contains the expected data in the expected format. #### Null value returned The API returns null when it cannot locate a field's value in the document. This can occur because the data is not in the document, or because the API could not locate it. For more information, go to [How the API Handles Missing Fields](./ade-extract-schema-json#how-the-api-handles-missing-fields). **Error message:** ``` The value at 'field_name' was not found in the document, so null was returned. Since the schema requires a non-null value, verify that the document indeed doesn't contain this data, and if so, update the schema to allow null by adding 'null' to the field's type (e.g., type: ['string', 'null']) or by setting nullable: true. ``` **What to do:** * Check whether the document actually contains the expected data. If it does not, the null result is correct. * If the document does contain the data but the API could not find it, revise your schema to help the API locate the field: * Add or refine the `description` to be more specific about what to extract. * Add entries to `x-alternativeNames` that match how the field label appears in the document. For more information, go to [Field Descriptions](./ade-extract-schema-json#field-descriptions) and [Alternative Names](./ade-extract-schema-json#alternative-names). ### Status 400: Bad Request This status code indicates invalid request parameters or client-side errors. Review the specific error message to identify the issue. #### Error: Invalid JSON schema This error occurs when the `extraction_schema` parameter contains invalid JSON. **Error message:** ``` Invalid JSON schema: Expecting value: line 1 column 1 (char 0) ``` **What to do:** * Verify your extraction schema is valid JSON. * Check for syntax errors (missing commas, quotes, brackets). * Verify the JSON schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. #### Error: Failed to download document from URL This error occurs when the API cannot download the Markdown file from the provided `markdown_url`. **Error message:** ``` Failed to download document from URL: {error_details} ``` **What to do:** * Verify the URL is accessible and returns valid content. * Check network connectivity and URL permissions. * Ensure the URL points to a Markdown file (.md extension). #### Error: Field extraction invalid This error occurs when the extraction process fails due to issues with the extraction schema or the extracted data. **Error message:** ``` Field extraction invalid: {error_details} ``` **What to do:** * Review the error details in the response. * Verify the JSON schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. * Ensure all required fields are properly defined in the schema. * Check if the document contains data that matches the schema structure. #### Error: Invalid extract version This error occurs when an unsupported model version is specified. **Error message:** ``` Invalid extract version '{version}' provided. Valid versions are: {list_of_versions} or use 'extract-latest' to use the latest version. ``` **What to do:** * Use one of the supported versions listed in the error message. * Use `extract-latest` to automatically use the latest version. * If you don't specify a version, the API uses the latest version by default. * For more information, go to [Extraction Model Versions](./ade-extract-models#model-versions). ### Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error message and adjust your request parameters. #### Error: The provided schema must have "type": "object" for the root This error occurs when the `extraction_schema` is a valid JSON object, but its `type` keyword is not set to `"object"`. The extraction engine requires the root schema to explicitly declare `"type": "object"`. **Error message:** ``` Field extraction validation error: The provided schema must have "type": "object" for the root. ``` **What to do:** Set `"type": "object"` at the root of your schema. **Correct:** ```json {2} theme={null} { "type": "object", "properties": { "invoice_number": { "type": "string", "description": "Invoice number" } } } ``` **Incorrect:** ```json {2} theme={null} { "type": "array", "items": { "type": "object", "properties": { "invoice_number": { "type": "string", "description": "Invoice number" } } } } ``` #### Error: The provided JSON must parse to an object at the root This error occurs when the `extraction_schema` parameter is valid JSON, but the root value is not a JSON object. For example, the root is a JSON array (`[...]`), a string, or a number rather than `{...}`. **Error message:** ``` Field extraction validation error: The provided JSON must parse to an object at the root. ``` **What to do:** Wrap your schema in a JSON object (`{...}`). **Correct:** ```json {1,8} theme={null} { "type": "object", "properties": { "invoice_number": {"type": "string"}, "vendor_name": {"type": "string"}, "total": {"type": "number"} } } ``` **Incorrect:** ```json theme={null} ["invoice_number", "vendor_name", "total"] ``` #### Error: The provided JSON object was not a valid JSON schema This error occurs when the `extraction_schema` parameter contains a JSON object that does not conform to the JSON Schema specification. **Error message:** ``` Field extraction validation error: The provided JSON object was not a valid JSON schema. Error: {error_details} ``` **What to do:** * Review the error details to identify the specific schema issue. * Verify your schema follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). #### Error: The provided schema contains recursive local \$ref cycles This error occurs when the extraction schema contains circular `$ref` references (for example, a schema that references itself). **Error message:** ``` Field extraction validation error: The provided schema contains recursive local `$ref` cycles, which are not supported. ``` **What to do:** Remove circular `$ref` references from your schema. Restructure nested types to avoid self-referencing definitions. #### Error: The following schema fields were not supported This error occurs when the extraction schema contains [keywords that cause errors](./ade-extract-schema-json#keywords-that-cause-errors) and the `strict` parameter is set to `true`. When `strict` is `false`, the API removes the unsupported keywords and continues processing. The API returns `200` if extraction succeeds with valid output, or `206` if the extracted output does not conform to the original schema. For more information, go to [Set the strict Parameter](./ade-extract#set-the-strict-parameter). **Error message:** ``` Field extraction validation error: The following schema fields were not supported: {keywords} ``` **What to do:** * Remove the unsupported keywords listed in the error message from your schema. * For a list of keywords that cause errors, go to [Keywords That Cause Errors](./ade-extract-schema-json#keywords-that-cause-errors). #### Error: Cannot provide both 'markdown' and 'markdown\_url' This error occurs when both a Markdown file and a URL to a Markdown file are provided in the same request. **Error message:** ``` Cannot provide both 'markdown' and 'markdown_url'. Please provide only one. ``` **What to do:** Choose one input method: * Provide a Markdown file using the `markdown` parameter, OR * Provide a URL to a Markdown file using the `markdown_url` parameter. #### Error: Must provide either 'markdown' or 'markdown\_url' This error occurs when your request does not include either the `markdown` or `markdown_url` parameter. **Error message:** ``` Must provide either 'markdown' or 'markdown_url'. ``` **What to do:** Add one of these parameters to your request: * Use the `markdown` parameter to upload a Markdown file, OR * Use the `markdown_url` parameter to provide a URL to a Markdown file. #### Error: No markdown file or URL provided This error occurs when you include a `markdown` or `markdown_url` parameter in your request, but the value is empty or blank. **Error message:** ``` No markdown file or URL provided. ``` **What to do:** * If using `markdown`: Ensure you are uploading a valid Markdown file (not an empty file or blank value). * If using `markdown_url`: Ensure the parameter contains a valid URL (not an empty string or blank value). * Verify that your request properly includes the file or URL value. #### Error: Invalid URL format This error occurs when the `markdown_url` parameter contains a value that is not a valid URL. **Error message:** ``` Invalid URL format: {url} ``` **What to do:** * Verify the URL is properly formatted with a valid protocol (http\:// or https\://). * Check for typos or missing characters in the URL. * Ensure the URL is properly encoded if it contains special characters. #### Error: Multiple Markdown files detected This error occurs when multiple Markdown files are included in the request. **Error message:** ``` Multiple markdown files detected (X). Please provide only one document file. ``` **What to do:** Send only one Markdown file per request. #### Error: Unsupported format This error occurs when you provide a file other than Markdown (.md) to the extract endpoint, such as PDF, DOCX, XLSX, or image files. **Error message:** ``` Unsupported format: {mime_type} ({filename}). Supported formats: MD ``` **What to do:** * The extract endpoint only accepts Markdown files with a .md extension. * If you have a PDF, DOCX, or other document format, use the [Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) endpoint to convert your document to Markdown first. * Ensure your file has a .md extension and contains valid UTF-8 encoded Markdown content. ### Status 500: Internal Server Error This error indicates an unexpected server error occurred during processing. **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ### Status 504: Gateway Timeout This error occurs when the extraction process exceeds the timeout limit (475 seconds). **Error message:** ``` Request timed out after 475 seconds ``` **What to do:** * Reduce the size of your Markdown document. * Simplify your extraction schema and verify it follows the guidelines described in [Extraction Schema (JSON)](./ade-extract-schema-json). Update your JSON schema if needed. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ### Model Fallback Behavior The `metadata.fallback_model_version` field is included in the API response to support legacy behavior. When using `extract-20251024`, the API may automatically fall back to `extract-20250930` if your JSON schema is too complex. If a fallback occurred, `metadata.fallback_model_version` contains the model version that was used instead. For more information about the response structure, go to [JSON Response for Extraction](./ade-extract-response). When using `extract-20260314`, the API does not fall back to an earlier model. **What to do:** To avoid unexpected fallback behavior, use the most recent extraction model. For more information, go to [Extraction Model Versions](./ade-extract-models). ### Warnings For `extract-20260314`, the `metadata.warnings` field contains an array of structured warning objects. Each warning has a `code` that identifies the warning type and a `msg` with a human-readable description. If you use an earlier extraction model version, this field is absent from the response. Any warning in the `warnings` array causes the API to return a 206 status code. The following warning codes can appear: | Warning Code | Description | | ---------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------- | | `nonconformant_schema` | The schema contains issues that affected extraction. | | `nonconformant_output` | The extracted output does not fully conform to the schema. This warning also populates the `schema_violation_error` field for backward compatibility. | For more information about the response structure, go to [JSON Response for Extraction](./ade-extract-response#processing-metadata-metadata). ## ADE Build Extract Schema This section covers errors for the ADE Build Extract Schema API. ### Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ---------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------- | | 200 | Success | Schema generated successfully. | Continue with normal operations. | | 400 | Bad Request | Invalid request due to a download failure, unsupported version, or invalid schema. | Review the error message for the specific issue. See errors below. | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See errors below. | | 500 | Internal Server Error | Server error during schema generation. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit (475 seconds). | Reduce document size. See errors below. | ### Status 400: Bad Request This status code indicates invalid request parameters or client-side errors. Review the specific error message to identify the issue. #### Error: Invalid extract version This error occurs when an unsupported model version is specified. **Error message:** ``` Invalid extract version '{version}' provided. Valid versions are: {list_of_versions} or use 'extract-latest' to use the latest version. ``` **What to do:** * Use one of the supported versions listed in the error message. * Use `extract-latest` to automatically use the latest version. * If you don't specify a version, the API uses the latest version by default. * For more information, go to [Extraction Model Versions](./ade-extract-models#model-versions). #### Error: Failed to download document from URL This error occurs when the API cannot download a Markdown file from one of the provided `markdown_urls`. **Error message:** ``` Failed to download document from URL {url}: {error_details} ``` **What to do:** * Verify each URL is accessible and returns valid content. * Check network connectivity and URL permissions. * Ensure each URL points to a Markdown file (.md extension). #### Error: Schema generation invalid This error occurs when the schema generation request is rejected by the processing service. **Error message:** ``` Schema generation invalid: {error_details} ``` **What to do:** * Review the error details in the response. * Check that any provided `schema` parameter is valid JSON. * Verify that your Markdown content is readable and well-formed. ### Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error message and adjust your request parameters. #### Error: Must provide at least one of 'markdowns', 'markdown\_urls', 'schema', or 'prompt' This error occurs when your request does not include any input. **Error message:** ``` Must provide at least one of 'markdowns', 'markdown_urls', 'schema', or 'prompt'. ``` **What to do:** Add at least one of the following to your request: * `markdowns`: One or more Markdown files or inline Markdown strings. * `markdown_urls`: One or more URLs to Markdown files. * `schema`: An existing JSON schema to refine. * `prompt`: A description of the schema you want to generate. #### Error: Invalid URL format This error occurs when a URL in the `markdown_urls` parameter is not a valid URL. **Error message:** ``` Invalid URL format: {url} ``` **What to do:** * Verify the URL is properly formatted with a valid protocol (http\:// or https\://). * Check for typos or missing characters in the URL. * Ensure the URL is properly encoded if it contains special characters. #### Error: Invalid existing schema JSON This error occurs when the `schema` parameter contains invalid JSON. **Error message:** ``` Invalid existing schema JSON: {error_details} ``` **What to do:** * Verify your schema is valid JSON. * Check for syntax errors (missing commas, quotes, or brackets). #### Error: Unsupported format This error occurs when a file provided via `markdowns` or `markdown_urls` is not a Markdown (.md) file. **Error message:** ``` Unsupported format: {mime_type} ({filename}). Supported formats: MD ``` **What to do:** * The build-schema endpoint only accepts Markdown files with a .md extension. * If you have a PDF, DOCX, or other document format, use the [Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) to convert it to Markdown first. * Ensure your file has a .md extension and contains valid UTF-8 encoded Markdown content. #### Error: Schema generation validation error This error occurs when the schema generation request fails validation in the processing service. **Error message:** ``` Schema generation validation error: {error_details} ``` **What to do:** * Review the error details in the response. * Check that your inputs are valid: well-formed Markdown content, valid JSON for the `schema` parameter, and clear instructions in the `prompt` parameter. ### Status 500: Internal Server Error This error indicates an unexpected server error occurred during schema generation. **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ### Status 504: Gateway Timeout This error occurs when schema generation exceeds the timeout limit (475 seconds). **Error message:** ``` Request timed out after {seconds} seconds ``` **What to do:** * Reduce the size and number of Markdown files in the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## ADE Extract Jobs This section covers errors for the Extract Jobs APIs: * [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) creates a job. * [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) returns the status and results for a job. * [ADE List Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-list-extract-jobs) lists your jobs. The [Common Status Codes](#common-status-codes) also apply to these endpoints. The Extract Jobs APIs return errors in a `message` field, except for the create endpoint, which returns errors in an `error` field. ### Create an Extract Job: Status Codes These status codes apply to the [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) API (`/v1/ade/extract/jobs`). | Status Code | Name | Description | What to Do | | ----------- | --------------------- | --------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------- | | 202 | Accepted | The job was queued successfully. The response contains the `job_id`. | Poll the [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) API with the `job_id` to track status and retrieve results. | | 400 | Bad Request | Invalid request, such as an invalid JSON schema, an unreachable Markdown URL, or a zero data retention (ZDR) configuration error. | Review the error message. See [Create an Extract Job: Status 400](#create-an-extract-job-status-400-bad-request). | | 422 | Unprocessable Entity | Input validation failed, such as a missing Markdown input or an unsupported file format. | Review your request parameters. See [Create an Extract Job: Status 422](#create-an-extract-job-status-422-unprocessable-entity). | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Each job counts as one submission toward your hourly limit, regardless of document size. See [Rate Limits](./ade-rate-limits). | | 500 | Internal Server Error | Server error while creating the job. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | #### Create an Extract Job: Status 400: Bad Request For an invalid JSON schema or an unreachable Markdown URL, the cause and fix match the ADE Extract API. See [Error: Invalid JSON schema](#error-invalid-json-schema) and [Error: Failed to download document from URL](#error-failed-to-download-document-from-url). The following errors are specific to ZDR-enabled requests. ##### Error: output\_save\_url must be present if zeroDataRetention is enabled This error occurs when ZDR is enabled but the request does not include the `output_save_url` parameter. **Error message:** ``` output_save_url must be present if zeroDataRetention is enabled ``` **What to do:** Include the `output_save_url` parameter so the extracted content is saved to your URL instead of being returned in the response. For more information, go to [ZDR Requirements](./ade-extract-async#zdr-requirements). ##### Error: Only markdown\_url is accepted if zeroDataRetention is enabled This error occurs when ZDR is enabled but the request uploads a local Markdown file with the `markdown` parameter. **Error message:** ``` Only markdown_url is accepted if zeroDataRetention is enabled ``` **What to do:** Pass your Markdown using the `markdown_url` parameter instead of uploading a local file. For more information, go to [ZDR Requirements](./ade-extract-async#zdr-requirements). #### Create an Extract Job: Status 422: Unprocessable Entity For a missing Markdown input or an unsupported file format, the messages and fixes match the ADE Extract API. See [Error: No markdown file or URL provided](#error-no-markdown-file-or-url-provided) and [Error: Unsupported format](#error-unsupported-format). ### Get an Extract Job: Status Codes These status codes apply to the [ADE Get Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs) API (`/v1/ade/extract/jobs/{job_id}`). | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ---------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | The job was retrieved. When `status` is `completed`, the response includes the extracted data. | Read the `status` field. If `failed`, see [Failed Jobs](#failed-jobs). | | 206 | Partial Content | The job completed, but the extracted data does not fully conform to the schema. | Review the `schema_violation_error` and `warnings` fields. See [Status 206: Partial Content](#status-206-partial-content). | | 404 | Not Found | No job with the given ID exists for your API key. | See [Get an Extract Job: Status 404](#get-an-extract-job-status-404-not-found). | | 500 | Internal Server Error | Server error while retrieving the job. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | #### Failed Jobs A 200 response with `status` set to `failed` means the job did not complete. The `failure_reason` field describes what went wrong. Because extraction runs in the background, errors that occur during processing (including timeouts) are reported here rather than as an HTTP error code on this endpoint. **What to do:** * Review the `failure_reason` field for the cause. * If the failure reason indicates a timeout, reduce the size of your Markdown document or simplify your extraction schema, then submit a new job. * Otherwise, verify your Markdown input and schema, then submit a new job. #### Get an Extract Job: Status 404: Not Found This error occurs when no job matches the `job_id`, or the job belongs to a different API key. **Error message:** ``` Job {job_id} not found ``` **What to do:** * Verify the `job_id` matches the value returned when you created the job. * Confirm you are using the same API key that created the job. ### List Extract Jobs: Status Codes These status codes apply to the [ADE List Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-list-extract-jobs) API (`/v1/ade/extract/jobs`). | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ----------------------------------------------------------------------- | -------------------------------------------------------------------------------------- | | 200 | Success | The list of jobs was retrieved. | Continue with normal operations. | | 422 | Unprocessable Entity | Invalid query parameters, such as an out-of-range `page` or `pageSize`. | Review the `page`, `pageSize`, and `status` query parameters. | | 500 | Internal Server Error | Server error while listing jobs. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). | ## When Are Credits Consumed? * **ADE Extract**: Credits are consumed only when the API returns a 200 or 206 status code. All other responses, including errors, do not consume credits. * **ADE Build Extract Schema**: Credits are consumed only when the API returns a 200 status code. All other responses, including errors, do not consume credits. * **ADE Extract Jobs**: Credits are consumed only when a job reaches the `completed` status (including completions returned with a 206 status code). Failed and cancelled jobs do not consume credits. # Classify Source: https://docs.landing.ai/ade/ade-classify Label each page of a document by type to route pages before parsing (Preview). Use the [ADE Classify API](https://docs.landing.ai/api-reference/tools/ade-classify) to classify each page in a document by type. You provide a document and a list of classes, and the API assigns a class to each page. Use those classes to decide how to handle each page downstream, for example which pages to parse, how to split a batch, or which extraction schema to apply. ADE Classify is in Preview. This feature is still in development and may not return accurate results. Do not use this feature in production environments. ## Example Use Cases * **Financial Services**: Financial institutions receiving batches of mixed documents can classify pages to identify bank statements, utility bills, and identification documents before routing them to the appropriate processing pipeline. * **Healthcare**: Healthcare systems ingesting patient records can classify pages to identify intake forms, pathology reports, and medication lists before parsing or extraction. * **Legal**: Legal teams processing incoming documents can classify pages by section type (for example, cover page, terms, signature page) before routing each page to the appropriate review workflow. * **Insurance**: Insurance companies receiving claim submissions can classify pages to identify claim forms, invoices, and medical records before extraction. For credit consumption rates, see [Credit Consumption](./ade-credit-consumption#credit-costs-for-the-classify-api). ## Process Overview Follow these steps to classify pages in a document: 1. **Define your class list** by creating the classes that describe the page types in your document. Learn more about [Classes](#classes). 2. **Classify your document** using the [ADE Classify API](https://docs.landing.ai/api-reference/tools/ade-classify). Pass your document and class list. All pages are classified concurrently. 3. **Use the classification results** in your downstream workflows. Route pages to [Parse](./parse), [Split](./ade-split), [Extract](./ade-extract), or other systems based on the class assigned to each page. Learn more about the [response structure](./ade-classify-response). ## Classes A class is an object with a required `class` name and an optional `description`. Include a description when the class name alone may be ambiguous (for example, `"spec"` vs `"manual"`). You can omit the description when the name is self-explanatory. You can mix classes with and without descriptions in the same request. ## Classify in the Playground Use the [Playground](https://ade.landing.ai) to build and test classification classes before incorporating them into your code. Upload a document, define your classes, and validate the results. When the pages are classified as expected, use the downloaded classes with the [API](#classify-with-the-api), [Python library](./ade-python#classify-getting-started), or [TypeScript library](./ade-typescript#classify-getting-started) to classify documents at scale. 1. Go to the [Playground](https://ade.landing.ai). 2. Select the file you want to classify. 3. Click **Classify**. 4. Click **Define Classes**. 5. List or describe the classes you want to apply to the pages and click **Suggest Classes**. (To create the class schema yourself, click **Start from Scratch**.) 6. The app generates classes and class descriptions based on your input. Review the generated classes and descriptions before continuing. 7. Click **Classify** to validate the classes on the selected file. (Click the drop-down menu to select whether to classify the **Current File**, **All Files**, or **Custom**.) 8. Review the results. If needed, continue editing the classes and their descriptions. 9. When the pages are classified as expected, [get a ready-to-use script for classification](#get-a-ready-to-use-classify-script) or [download the class schema](#export-the-class-schema-to-json) to use in your own code. ### Get a Ready-to-Use Classify Script After you create a class schema, Agentic Document Extraction generates a script to classify files based on the class schema you created. The Playground provides two versions: one for calling the API directly, and one for the [ade-python library](./ade-python). **To get the script:** 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Classify** tab. 4. Click **Get Code**. Get the Code 5. The **View Code** pop-up opens. Click the **Library** or **API** tab to see the code for each method. 6. Click the **Download** or **Copy** buttons to get the code. View the Code ### Export the Class Schema to JSON After you create a class schema, you can export it as a JSON file that you can pass to the `classes` parameter in the [API](#classify-with-the-api), [Python library](./ade-python#classify-getting-started), or [TypeScript library](./ade-typescript#classify-getting-started). **To export the schema:** 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Classify** tab. 4. In the **Schema** panel, click **...** and select **Download Classes**. The classes and descriptions are downloaded as a JSON file. ## Classify with the API Classify the pages in a document by calling the [ADE Classify](https://docs.landing.ai/api-reference/tools/ade-classify) endpoint. This example classifies a document that may contain invoices, bank statements, and earnings statements. The `invoice` and `bank_statement` classes include descriptions; `earnings statement` does not. ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/classify' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'classes=[{"class":"invoice","description":"A commercial bill with line items, totals, and payment terms"},{"class":"bank_statement","description":"A monthly summary of account transactions"},{"class":"earnings statement"}]' \ -F 'document=@document.pdf' ``` ### Parameters Get the full parameters from the [API reference](https://docs.landing.ai/api-reference/tools/ade-classify). | Parameter | Required | Description | | -------------- | --------------------- | --------------------------------------------------------------------------------------------------------------------------------------------- | | `document` | Required (choose one) | The document file to classify. | | `document_url` | Required (choose one) | A URL pointing to the document to classify. | | `classes` | Required | A JSON array of class objects. Each object requires a `class` name and accepts an optional `description`. Pass as a JSON string in form data. | | `model` | Optional | The classification model version to use (for example, `classify-20260420`). Defaults to the latest version. | ## Use Classify with Our Libraries Click one of the tiles below to learn how to use the [ADE Classify](https://docs.landing.ai/api-reference/tools/ade-classify) API with our libraries. Use ADE Classify with our Python library. TypeScript TypeScript } href="./ade-typescript#classify-getting-started" > Use ADE Classify with our TypeScript library. ## Supported File Types The ADE Classify API supports all file types that Parse supports, except spreadsheets (CSV, XLSX), up to 200 MB. For the full list, see [Supported File Types](./ade-file-types). ## Share Your Feedback ADE Classify is in public preview and we are actively looking for feedback to improve it. To share your experience, [schedule a feedback session with us](https://landing-ai.zoom.us/zbook/landingai-fatimasalehbhai/landingai-ade-feedback). Come prepared to discuss: * What is working well * Any challenges you've encountered and how the feature could improve * The email address for your Agentic Document Extraction account, found in your [profile page](https://ade.landing.ai/settings/personal/profile) * The documents you used * The code you used # JSON Response for Classification Source: https://docs.landing.ai/ade/ade-classify-response Understand the classification JSON response: per-page class labels and processing metadata. When you classify a document with the [ADE Classify API](https://docs.landing.ai/api-reference/tools/ade-classify), the results are returned in a structured JSON format. ## Example Response The following example shows a classification response for a nine-page document containing bank statements and pay stubs: ```json [expandable] theme={null} { "classification": [ { "class": "bank statement", "reason": "Checking account statement for Sarah J. Mitchell from Builder's Bank for the period of September 1 to September 30, 2025.", "suggested_class": null, "page": 0 }, { "class": "bank statement", "reason": "Continuation of the transaction history and account summary for the September 2025 bank statement.", "suggested_class": null, "page": 1 }, { "class": "bank statement", "reason": "Checking account statement for Sarah J. Mitchell from Builder's Bank for the period of October 1 to October 31, 2025.", "suggested_class": null, "page": 2 }, { "class": "bank statement", "reason": "Continuation of the transaction history and account summary for the October 2025 bank statement.", "suggested_class": null, "page": 3 }, { "class": "bank statement", "reason": "Informational page containing bank policies, fraud protection details, and contact information.", "suggested_class": null, "page": 4 }, { "class": "pay stub", "reason": "Earnings statement from Acme Corporation for Sarah J. Mitchell for the pay period ending August 31, 2025.", "suggested_class": null, "page": 5 }, { "class": "pay stub", "reason": "Summary of gross pay, deductions, and net pay for the Acme Corporation earnings statement.", "suggested_class": null, "page": 6 }, { "class": "pay stub", "reason": "Earnings statement from Acme Corporation for Sarah J. Mitchell for the pay period ending September 15, 2025.", "suggested_class": null, "page": 7 }, { "class": "pay stub", "reason": "Summary of gross pay, deductions, and net pay for the second Acme Corporation earnings statement.", "suggested_class": null, "page": 8 } ], "metadata": { "filename": "SarahMitchell-loan-docs.pdf", "org_id": "f6t71a157bx9", "page_count": 9, "duration_ms": 10865, "credit_usage": 4.5, "job_id": "c19ab8c311db41b391c50a56a4cdea5c", "version": "classify-20260420" } } ``` ## Response Structure The response contains the following top-level fields: | Field | Type | Description | | ---------------------------------------------------- | ------ | ------------------------------------------------------------------------ | | [`classification`](#per-page-results-classification) | array | Per-page classification results. | | [`metadata`](#processing-metadata-metadata) | object | Processing information including credit usage, duration, and page count. | ## Per-Page Results (`classification`) The `classification` field contains an array of results, one per page in the document. Each object includes: | Field | Type | Description | | ----------------- | -------------- | ---------------------------------------------------------------------------------------------------------------------------------------- | | `page` | number | The page number (0-indexed). | | `class` | string | The class label assigned to this page (for example, `"Invoice"`). When a page cannot be confidently classified, this value is `unknown`. | | `reason` | string | An explanation of why this class was assigned. Use this to understand the classification decision and refine your class list if needed. | | `suggested_class` | string \| null | The closest matching class when `class` is `unknown`; otherwise `null`. | ### Unknown Pages When a page cannot be confidently classified into any of the classes you defined, the API returns `unknown` in the `class` field and a value in `suggested_class`. Use this to review borderline pages or adjust your class list. ## Processing Metadata (`metadata`) The `metadata` field provides information about the classification process: | Field | Type | Description | | -------------- | ------ | --------------------------------------------- | | `filename` | string | The name of the input document. | | `org_id` | string | Organization identifier. | | `page_count` | number | Total number of pages in the document. | | `duration_ms` | number | Processing time in milliseconds. | | `credit_usage` | number | Number of credits consumed. | | `job_id` | string | Unique identifier for the classification job. | | `version` | string | The model version used for classification. | # Troubleshoot Classification Source: https://docs.landing.ai/ade/ade-classify-troubleshoot Resolve Classify API errors using status codes, causes, and recommended fixes. Use this section to troubleshoot issues encountered when calling the [ADE Classify](https://docs.landing.ai/api-reference/tools/ade-classify) API. ## Common Status Codes | Status Code | Name | Description | What to Do | | ----------- | ---------------------- | ----------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Classification completed successfully. | Continue with normal operations. | | 400 | Bad Request | Invalid request parameters. | Review the error message. See [Status 400](#status-400-bad-request). | | 401 | Unauthorized | Missing or invalid API key. | Check that your API key header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 413 | Content Too Large | The document exceeds the 200 MB size limit. | Reduce the file size and retry. See [Status 413](#status-413-content-too-large). | | 415 | Unsupported Media Type | The document could not be read or converted. | Convert the document to PDF and retry. See [Status 415](#status-415-unsupported-media-type). | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See [Status 422](#status-422-unprocessable-entity). | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. | | 500 | Internal Server Error | Server error during classification. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500](#status-500-internal-server-error). | | 502 | Bad Gateway | The classification service returned an error. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 502](#status-502-bad-gateway). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit. | Reduce document size or number of pages. See [Status 504](#status-504-gateway-timeout). | ## Status 400: Bad Request This status code indicates invalid request parameters or client-side errors. Review the specific error message to identify the issue. ### Error: Invalid document URL This error occurs when the URL provided in `document_url` cannot be fetched. The URL may be invalid, unreachable, or return a non-200 response. **What to do:** * Verify the URL is correct and publicly accessible. * Confirm the server hosting the document does not require authentication or block external requests. * If the document is behind a firewall or requires credentials, download it locally and upload it using the `document` parameter instead. ## Status 413: Content Too Large This error occurs when the document you submit exceeds the 200 MB file size limit. **What to do:** * Reduce the file size before uploading. * If the document is a PDF, consider compressing it or splitting it into smaller files before classifying. ## Status 415: Unsupported Media Type This error occurs when a document in a supported office format (such as DOCX or PPTX) could not be converted to PDF for processing. This is a server-side conversion failure, not a format restriction. **What to do:** * Convert the document to PDF before uploading and retry. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error message and adjust your request parameters. ### Error: Unsupported file format This error occurs when you submit a file type that the ADE Classify API does not support. **What to do:** * Convert your document to a supported format before calling the API. * For supported file formats, see [Supported File Types](./ade-classify#supported-file-types). ### Error: Both document fields provided This error occurs when you include both `document` and `document_url` in the same request. **What to do:** * Include only one document input per request: either upload a file using `document` or provide a URL using `document_url`. ## Status 500: Internal Server Error This error indicates an unexpected server error occurred during classification. **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 502: Bad Gateway This error occurs when the internal classification service fails to process the document, typically due to a transient error in the LLM service. **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 504: Gateway Timeout This error occurs when the classification process exceeds the timeout limit. **What to do:** * Reduce the size of your document or the number of pages being classified. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## When Are Credits Consumed? Credits are consumed only when the ADE Classify API returns a 200 status code. All other responses, including errors, do not consume credits. # Section Source: https://docs.landing.ai/ade/ade-section Generate a hierarchical table of contents from a parsed document (Preview). Use the [ADE Section API](https://docs.landing.ai/api-reference/tools/ade-section) to generate a hierarchical table of contents (TOC) from a parsed document. ADE Section analyzes the semantic structure of your document and returns a flat, reading-order list of sections and subsections, each with a title, hierarchy level, section number, and a reference to the starting chunk in the parsed document. Section in the Playground ADE Section is in Preview. This feature is still in development and may not return accurate results. Do not use this feature in production environments. ## Example Use Cases Use ADE Section in workflows that need to navigate, scope, or retrieve content by section: * **Extraction pipelines**: Scope extraction queries to specific sections of a document (for example, "extract all tables in the Claims section"). * **RAG and search**: Use section-aware chunking instead of sliding-window chunking for more relevant retrieval results. * **Document review**: Generate a navigable TOC for long documents such as insurance policies, contracts, reports, and technical manuals. * **Cross-document analysis**: Process large document batches and compare structure across a corpus. * **LLM applications**: Provide context windows organized by section rather than arbitrary token splits. ## How It Works ADE Section accepts the Markdown output from ADE Parse (which contains [reference anchors](./ade-markdown-response#anchor-tags)) and returns a structured table of contents. ADE Section automatically infers the document's hierarchy. You can also pass an optional `guidelines` parameter to control how sections are grouped. The response includes two formats for the same TOC: * **`table_of_contents`**: A structured JSON array for programmatic use * **`table_of_contents_md`**: A Markdown-formatted TOC you can prepend to the document for navigation The TOCs that ADE Section generates are in English, regardless of the source document language. ## Run Parse First The ADE Section API requires the Markdown output from the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) as input. The Markdown must contain [reference anchors](./ade-markdown-response#anchor-tags) (``) that ADE Section uses to map sections back to specific chunks in the original document. ## Section in the Playground Use the [Playground](https://ade.landing.ai) to test sectioning visually before incorporating it into your code. Upload a document, review the generated table of contents, and adjust the structure if needed. When the table of contents matches your use case, use the generated script with the [API](#section-with-the-api), [Python library](./ade-python#section-getting-started), or [TypeScript library](./ade-typescript#section-getting-started) to section documents at scale. 1. Go to the [Playground](https://ade.landing.ai). 2. Open a project and upload the file you want to section. Parse runs first. 3. After parsing completes, click **+ Tool** in the top toolbar and select **Section**. ADE Section runs on every parsed file in the project. Section will run also automatically on any files later uploaded to the project. 4. In the **Results** panel, review the generated table of contents. The header shows the number of top-level sections, the number of subsections, and the maximum depth. 5. Hover over a section in the tree to highlight its chunks in the document viewer. Click a section to filter the viewer to just that section's chunks. Click the section again to restore the full view. 6. You can toggle between a visual representation of the results (**Formatted**) and the actual API JSON response (**JSON**). 7. (Optional) Enter natural-language instructions refining the sectioning in the **Guidelines** text box and click **Update and Run**. For more details, go to [Refine the Table of Contents with Guidelines](#refine-the-table-of-contents-with-guidelines). 8. Once the structure matches your use case, [get a ready-to-use script](#get-a-ready-to-use-section-script). ### Refine the Table of Contents with Guidelines To adapt the structure to your use case, pass a natural-language guideline to control how ADE Section groups content. Guidelines are optional and apply per file. Only the most recent guideline for a file is kept; submitting a new guideline replaces the previous result. To submit a guideline: 1. Go to the [Playground](https://ade.landing.ai/) and open a project that has Section enabled. 2. Select the file you want to refine. 3. At the bottom of the **Section** panel, click **Add Custom Section Guidelines (Optional)** to expand that panel. 4. Enter natural-language instructions or click one of the suggestions to prefill the input. 5. Click **Update and Run**. ADE Section regenerates the table of contents for the selected file using your guideline. Submit Section Guidelines ### Get a Ready-to-Use Section Script After you create a table of contents, Agentic Document Extraction generates a script to section files using the current guideline (if any). The Playground provides two versions: one for calling the API directly, and one for the [ade-python library](./ade-python). **To get the script:** 1. Go to the [Playground](https://ade.landing.ai/). 2. Open a project. 3. Click the **Section** tab. 4. Click **Get Code**. Get the Code 5. The **View Code** pop-up opens. Click the **Library** or **API** tab to see the code for each method. 6. Click the **Download** or **Copy** buttons to get the code. View the Code ## Section with the API Section a document by calling the [ADE Section](https://docs.landing.ai/api-reference/tools/ade-section) endpoint. ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/section' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parsed_output.md' \ -F 'model=section-latest' ``` ### Parameters Get the full parameters from the [API reference](https://docs.landing.ai/api-reference/tools/ade-section). | Parameter | Required | Description | | :------------- | :--------------------------------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `markdown` | Required if `markdown_url` omitted | The Markdown output from the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse). Accepts a file upload or a raw string. | | `markdown_url` | Required if `markdown` omitted | A URL pointing to a Markdown file to fetch and section. | | `guidelines` | Optional | Natural-language instructions that control how the hierarchy is built. When omitted, the API infers structure automatically. Examples:
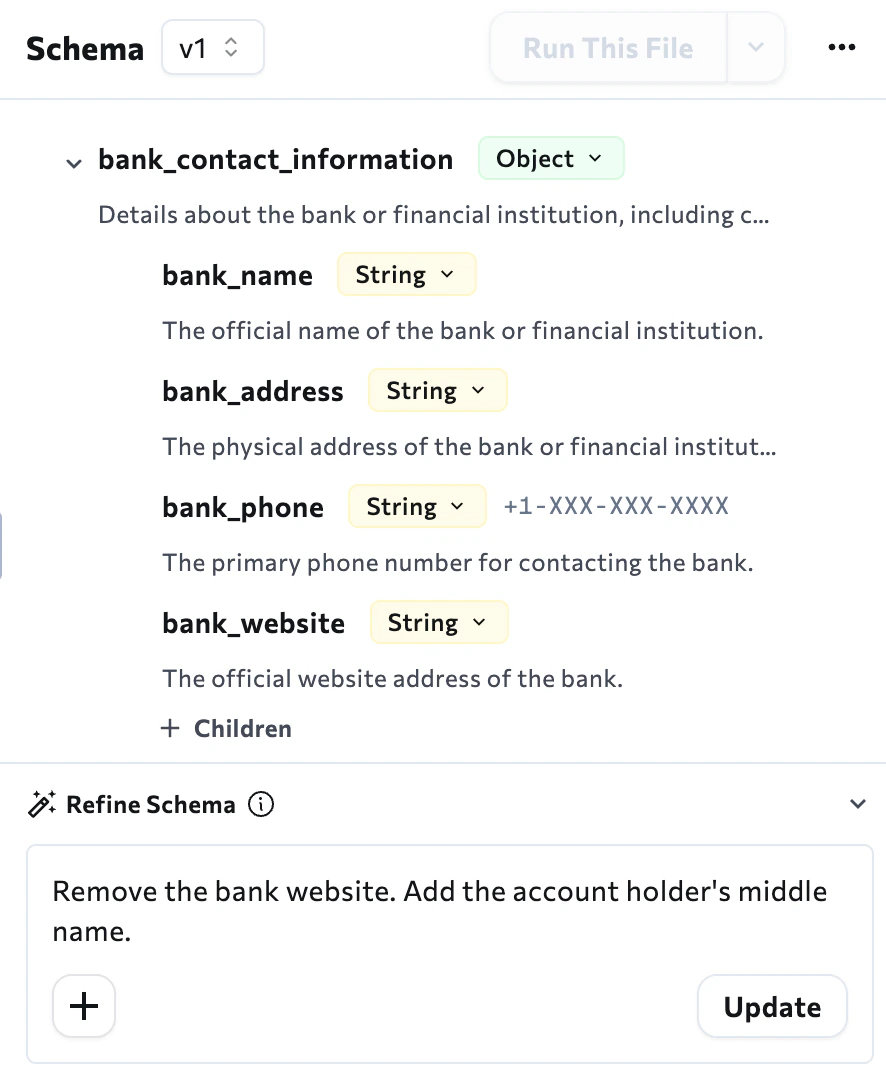
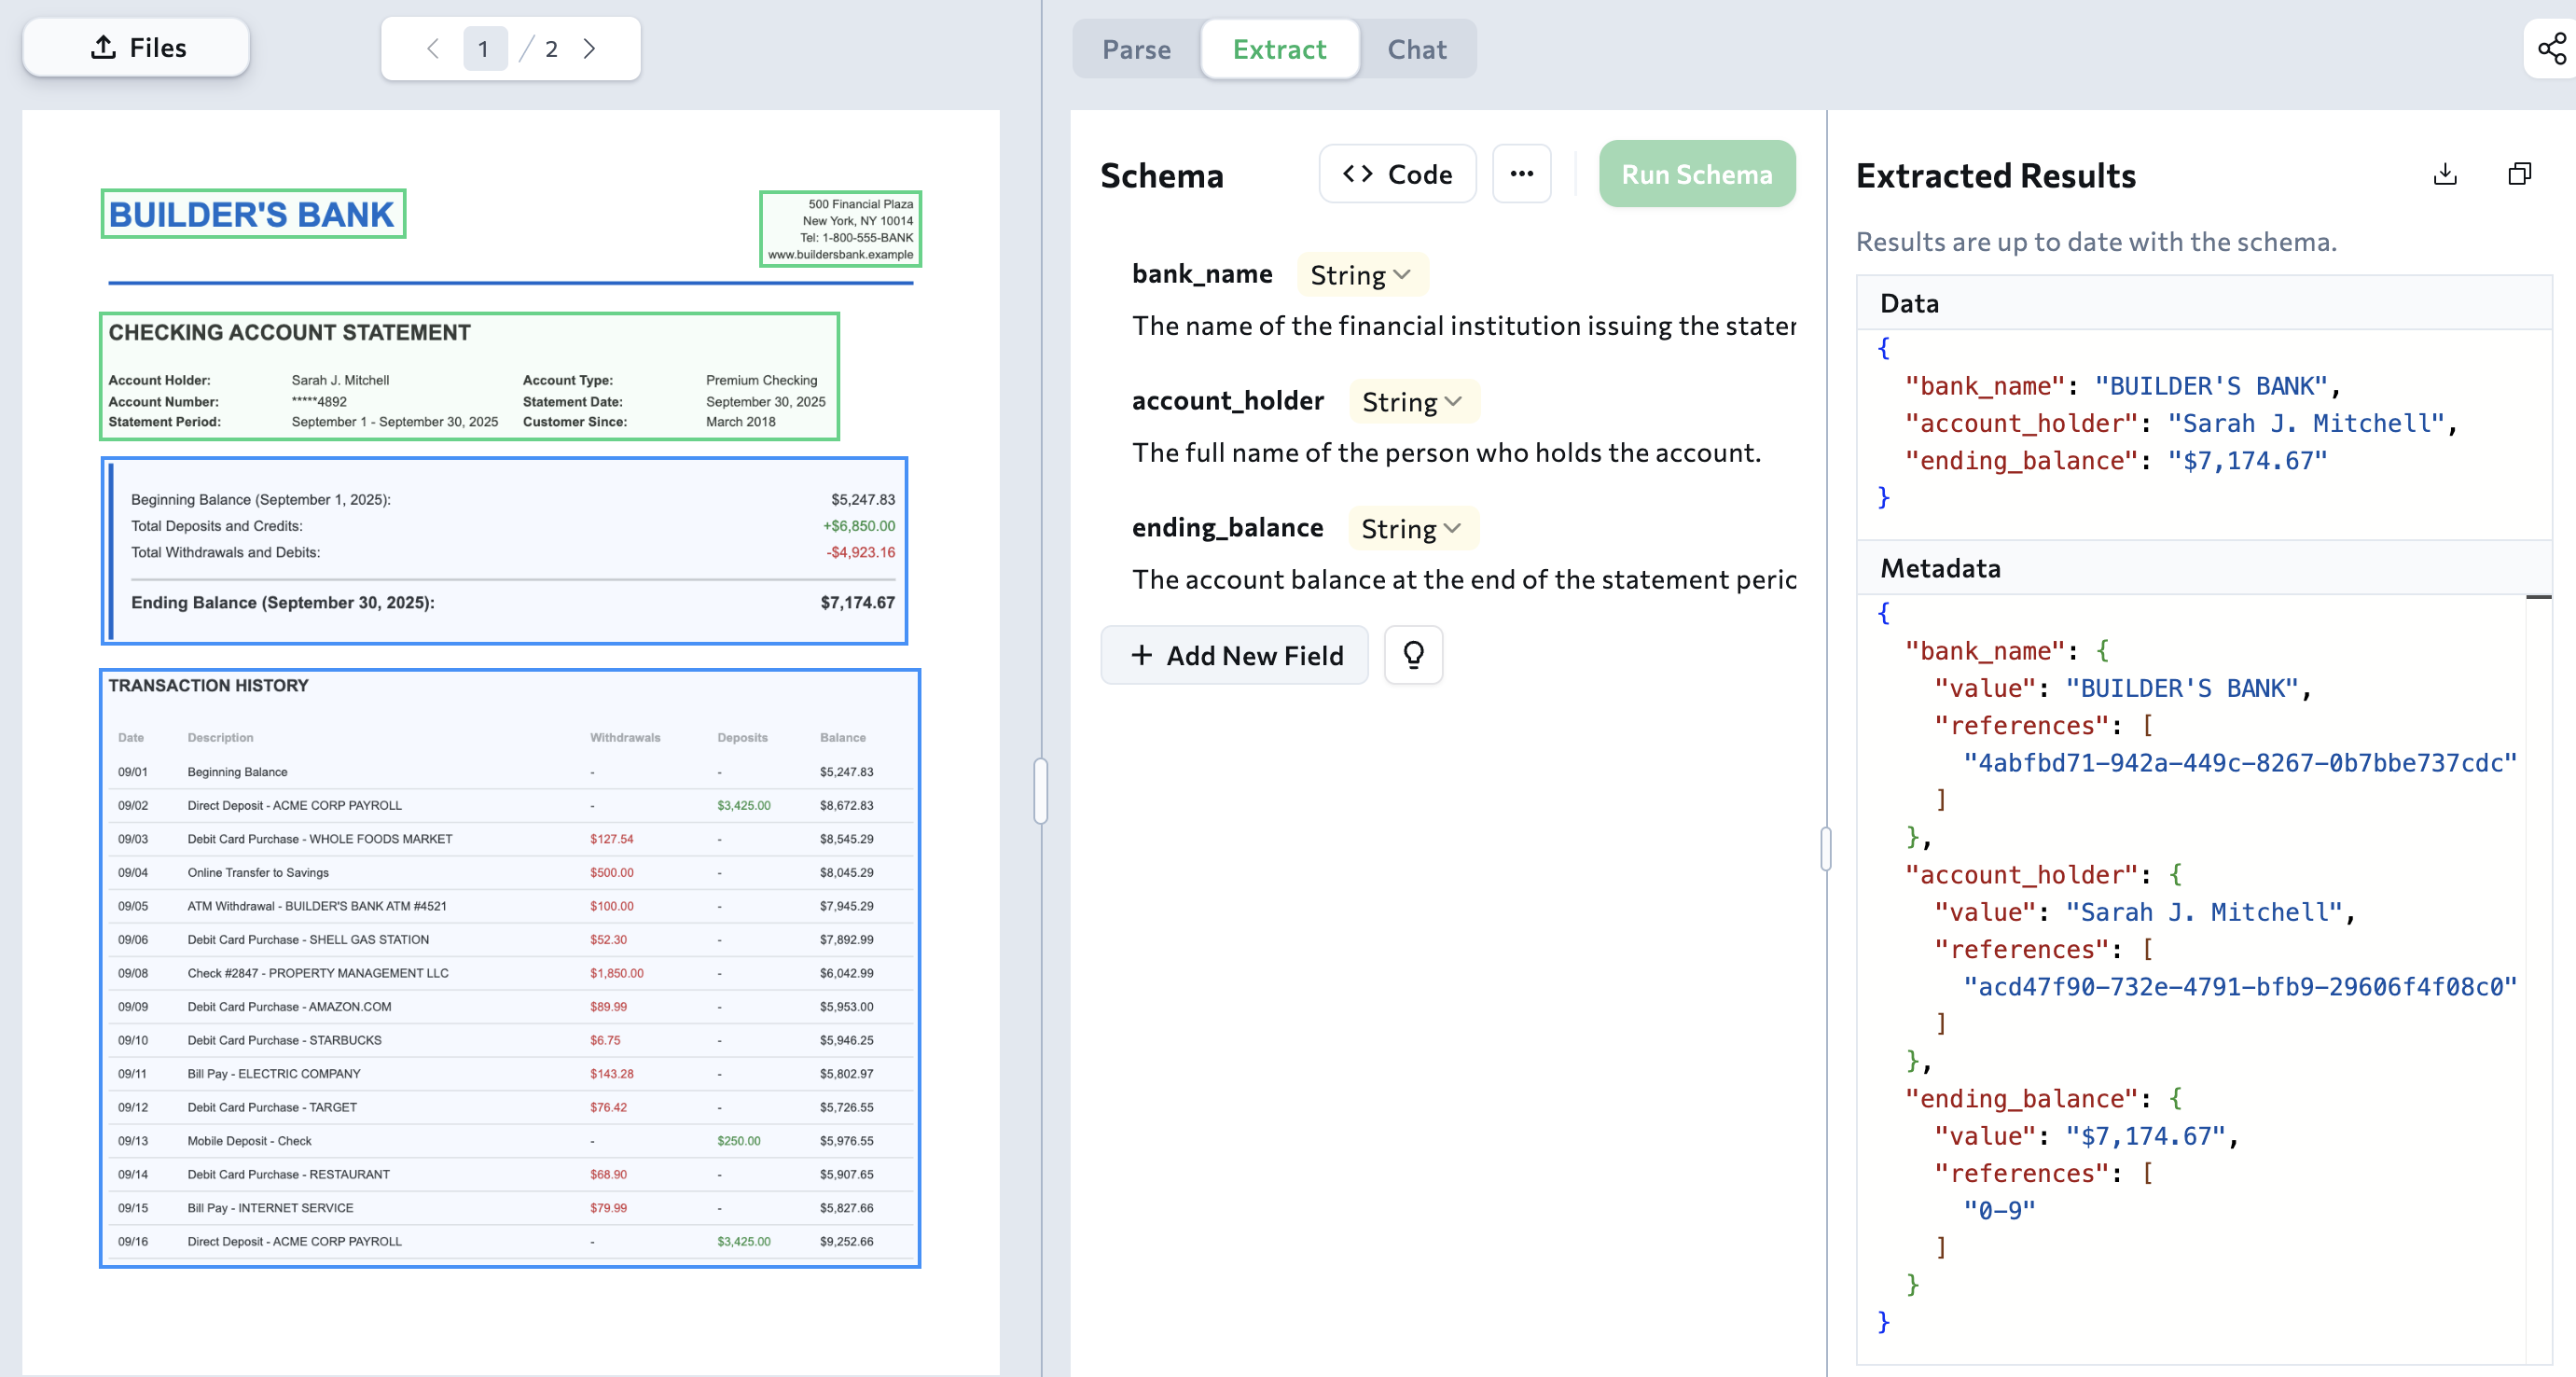
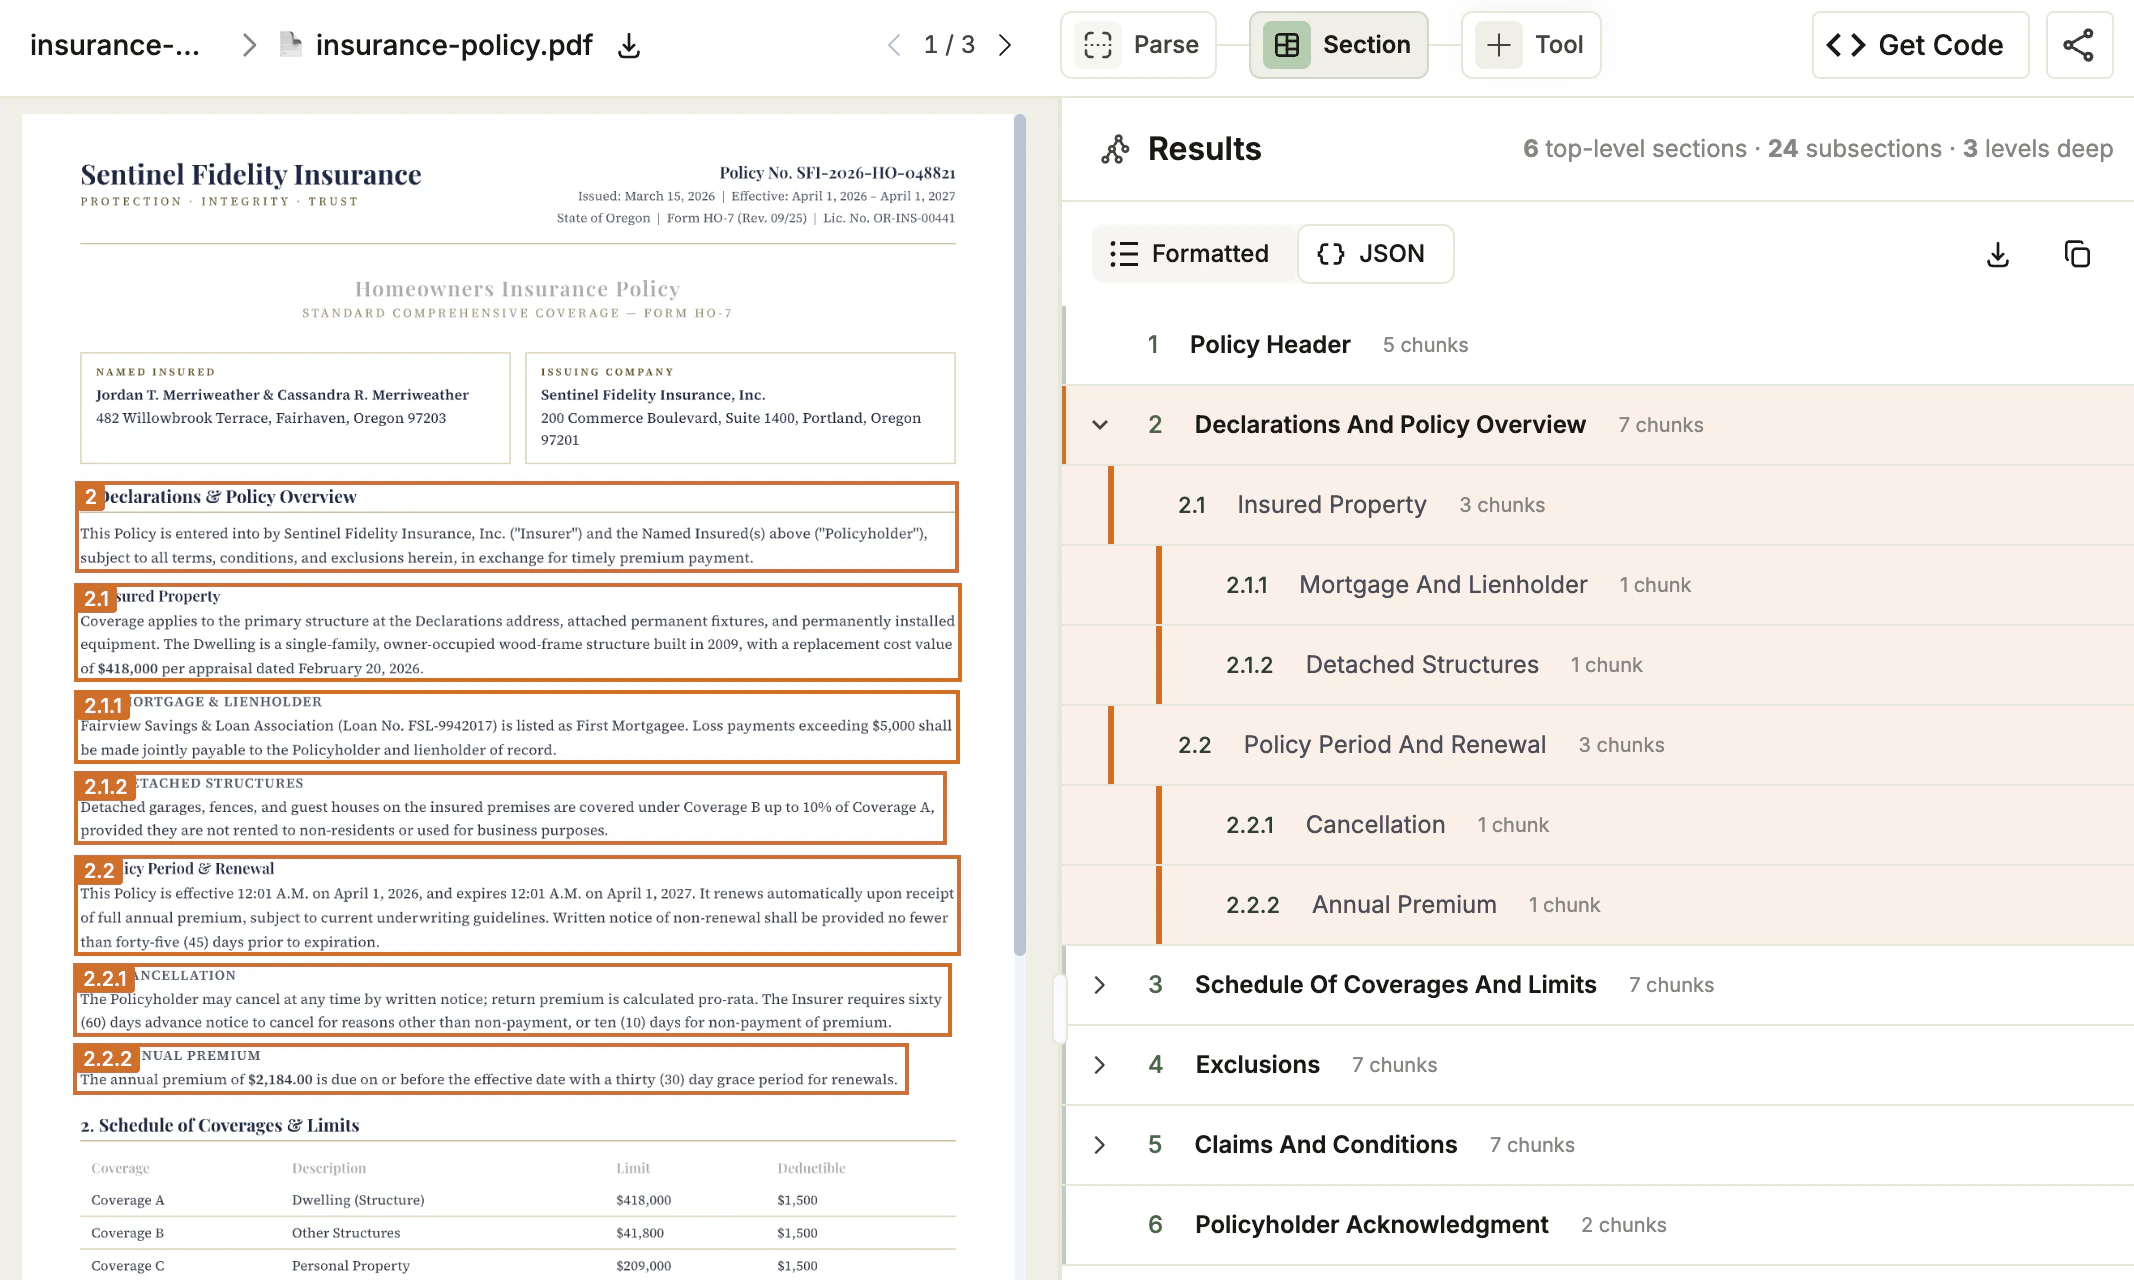
• `"Treat each numbered article as a top-level section"`
• `"Create a flat structure, no more than 2 levels deep"`
• `"Separate the introduction and appendices from the main body"` | | `model` | Optional | The section model version to use. If omitted, the API uses the latest model. For more information, see [Section Model Versions](./ade-section-models). | For detailed information about the API response, go to [JSON Response for Sectioning](./ade-section-response). For credit consumption rates, see [Credit Consumption](./ade-credit-consumption#credit-costs-for-the-section-api). ## Use Section with Our Libraries Click one of the tiles below to learn how to use the [ADE Section](https://docs.landing.ai/api-reference/tools/ade-section) API with our libraries. Use ADE Section with our Python library. TypeScript TypeScript } href="./ade-typescript#section-getting-started" > Use ADE Section with our TypeScript library. ## Share Your Feedback ADE Section is in public preview and we are actively looking for feedback to improve it. To share your experience, [schedule a feedback session with us](https://landing-ai.zoom.us/zbook/landingai-fatimasalehbhai/landingai-ade-feedback). Come prepared to discuss: * What is working well * Any challenges you've encountered and how the feature could improve * The email address for your Agentic Document Extraction account, found in your [profile page](https://ade.landing.ai/settings/personal/profile) * The documents you used * The code you used # Section Model Versions Source: https://docs.landing.ai/ade/ade-section-models Choose a Section model and set it when running the section process. A section model powers the document structure analysis capabilities of the [ADE Section](https://docs.landing.ai/api-reference/tools/ade-section) API. The model analyzes parsed Markdown content and generates a hierarchical table of contents. You can specify a model when calling the [ADE Section](https://docs.landing.ai/api-reference/tools/ade-section) API directly or when using the [client libraries](#set-the-model-with-the-client-libraries). If you don't specify a model, the API uses the latest section model (currently `section-20260406`). ## Model Versions The following table lists the available `model` values for the ADE Section API: | Model Values | Description | | ------------------ | --------------------------------------------------------- | | `section-20260406` | Use the section model snapshot released on April 6, 2026. | | `section-latest` | Use the latest section model snapshot. | ### Why Model Versioning Matters When integrating the API, you have two options for specifying the model: 1. **Use `section-latest`** to always get the newest version. This automatically gives you improvements and updates, but results may change when new model versions are released. 2. **Use a specific version** (like `section-20260406`) to pin to an exact model version. This ensures consistent results over time, but you won't receive improvements. ## Set the Model in the API When calling the [ADE Section](https://docs.landing.ai/api-reference/tools/ade-section) endpoint, you can set the model using the `model` parameter. If you omit the `model` parameter, the API uses the latest model. This example shows how to specify a model: ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/section' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parsed_output.md' \ -F 'model=section-latest' ``` ## Set the Model with the Client Libraries When using the Python or TypeScript library, you can set the model using the `model` parameter in the `section()` method. If you omit the `model` parameter, the library will use the latest section model. ```python {8} Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.section( markdown=Path("/path/to/parsed_output.md"), model="section-latest" ) ``` ```typescript {8} TypeScript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const response = await client.section({ markdown: fs.createReadStream("/path/to/parsed_output.md"), model: "section-latest" }); ``` # JSON Response for Sectioning Source: https://docs.landing.ai/ade/ade-section-response Understand the Section JSON response: section titles, hierarchy levels, numbers, and chunk references. When you section a document with the [ADE Section API](https://docs.landing.ai/api-reference/tools/ade-section), the results are returned in a structured JSON format. ## Example Response This example shows the information that ADE Section returns for a sample homeowner's insurance policy. You can download the source document to follow along: Insurance Policy PDF The screenshot below shows the first page of the document. First page of a homeowner's insurance policy ADE Section analyzed the full document and returned a hierarchical table of contents. The **Declarations And Policy Overview** section on the first page appears as section `2` (level 1) in the response. **Insured Property** and **Policy Period And Renewal** are its level 2 subsections, each with their own level 3 sub-subsections. Each entry's `start_reference` points to the chunk where that section begins in the parsed document. ```json [expandable] theme={null} { "table_of_contents": [ { "title": "Policy Header", "level": 1, "section_number": "1", "start_reference": "1c4b7184-346d-490f-a7bf-bf2442bcbd7c" }, { "title": "Declarations And Policy Overview", "level": 1, "section_number": "2", "start_reference": "494d766e-5cf1-48c4-a580-73061b722b90" }, { "title": "Insured Property", "level": 2, "section_number": "2.1", "start_reference": "1e6c9100-f461-4bb8-8dcd-8ae0311a97c0" }, { "title": "Mortgage And Lienholder", "level": 3, "section_number": "2.1.1", "start_reference": "95e79ad7-72b5-4c9f-9717-8488996c6795" }, { "title": "Detached Structures", "level": 3, "section_number": "2.1.2", "start_reference": "4c1e087b-aee9-4494-9789-735388a7579c" }, { "title": "Policy Period And Renewal", "level": 2, "section_number": "2.2", "start_reference": "de55b7d5-df5c-480e-8b91-0f9f10f5b059" }, { "title": "Cancellation", "level": 3, "section_number": "2.2.1", "start_reference": "7cc48544-b2ec-4e34-b2a1-ae1b3b7d17a6" }, { "title": "Annual Premium", "level": 3, "section_number": "2.2.2", "start_reference": "b8c0ba71-d786-4f89-a07f-3fcfc0edd734" }, { "title": "Schedule Of Coverages And Limits", "level": 1, "section_number": "3", "start_reference": "3700c26c-dd67-4dda-a712-081becb9ab63" }, { "title": "Coverage A Dwelling", "level": 2, "section_number": "3.1", "start_reference": "de789af4-1585-4b3f-9193-4253a9e58f6b" }, { "title": "Ordinance Or Law", "level": 3, "section_number": "3.1.1", "start_reference": "c7eaad71-19ca-4ab4-90cb-e8e9581ededc" }, { "title": "Named Storm Deductible", "level": 3, "section_number": "3.1.2", "start_reference": "d1300436-0131-49d1-a98a-1f46ece31c23" }, { "title": "Coverage C Personal Property", "level": 2, "section_number": "3.2", "start_reference": "80ed234f-1824-4def-b7fb-6883c3fa2b52" }, { "title": "Sub Limits", "level": 3, "section_number": "3.2.1", "start_reference": "0c3e0c5a-80ee-49f6-9ca5-52941547d4bd" }, { "title": "Business Property", "level": 3, "section_number": "3.2.2", "start_reference": "60aba72b-ca56-4806-97b0-bdf580669943" }, { "title": "Exclusions", "level": 1, "section_number": "4", "start_reference": "29529f14-e489-4f2a-bea8-0eef68f431b0" }, { "title": "Earth Movement And Flood", "level": 2, "section_number": "4.1", "start_reference": "51c3a6b7-7b78-404e-a1f3-b39be8498294" }, { "title": "Ensuing Loss", "level": 3, "section_number": "4.1.1", "start_reference": "908cf899-f5af-40c8-9829-4e09da9083c9" }, { "title": "Concurrent Causation", "level": 3, "section_number": "4.1.2", "start_reference": "f48d2861-3d9a-4db6-b2d1-78d22013c3fb" }, { "title": "Other Exclusions", "level": 2, "section_number": "4.2", "start_reference": "3336ee6d-9723-4fe1-914f-75109187cc0a" }, { "title": "Wear And Tear", "level": 3, "section_number": "4.2.1", "start_reference": "f66ab1c5-d5fe-42ac-bf71-56a3c769a0a6" }, { "title": "Vacancy", "level": 3, "section_number": "4.2.2", "start_reference": "75eff73f-3166-45dd-9140-a9182f858e47" }, { "title": "Claims And Conditions", "level": 1, "section_number": "5", "start_reference": "35ccfa20-00fb-462e-b375-aaa1b84a1d8f" }, { "title": "Duties After A Loss", "level": 2, "section_number": "5.1", "start_reference": "a08d6602-32b0-41e0-ad85-5d951dfc93c0" }, { "title": "Notice Deadline", "level": 3, "section_number": "5.1.1", "start_reference": "a68996f1-acd7-403e-bb68-58a7fbe336f0" }, { "title": "Emergency Repairs", "level": 3, "section_number": "5.1.2", "start_reference": "edd78fe8-08d6-4f55-a19b-d15a2a05464b" }, { "title": "Dispute Resolution", "level": 2, "section_number": "5.2", "start_reference": "bdf63da4-4f34-48f0-82a2-cece1ef666d0" }, { "title": "Suit Limitation", "level": 3, "section_number": "5.2.1", "start_reference": "db860fc2-e02e-4efa-8205-553b392b63ca" }, { "title": "Loss Payment", "level": 3, "section_number": "5.2.2", "start_reference": "0f7081fd-75c2-4e0f-8355-b4d66a13c20f" }, { "title": "Policyholder Acknowledgment", "level": 1, "section_number": "6", "start_reference": "065d0342-0c5b-4fbc-9888-b78ac5e0fefc" }, { "title": "Signature Lines", "level": 1, "section_number": "7", "start_reference": "f47e4117-eda0-477d-9a76-482bff511444" } ], "table_of_contents_md": "- [Policy Header](#1c4b7184-346d-490f-a7bf-bf2442bcbd7c)\n- [Declarations And Policy Overview](#494d766e-5cf1-48c4-a580-73061b722b90)\n - [Insured Property](#1e6c9100-f461-4bb8-8dcd-8ae0311a97c0)\n - [Mortgage And Lienholder](#95e79ad7-72b5-4c9f-9717-8488996c6795)\n - [Detached Structures](#4c1e087b-aee9-4494-9789-735388a7579c)\n - [Policy Period And Renewal](#de55b7d5-df5c-480e-8b91-0f9f10f5b059)\n - [Cancellation](#7cc48544-b2ec-4e34-b2a1-ae1b3b7d17a6)\n - [Annual Premium](#b8c0ba71-d786-4f89-a07f-3fcfc0edd734)\n- [Schedule Of Coverages And Limits](#3700c26c-dd67-4dda-a712-081becb9ab63)\n - [Coverage A Dwelling](#de789af4-1585-4b3f-9193-4253a9e58f6b)\n - [Ordinance Or Law](#c7eaad71-19ca-4ab4-90cb-e8e9581ededc)\n - [Named Storm Deductible](#d1300436-0131-49d1-a98a-1f46ece31c23)\n - [Coverage C Personal Property](#80ed234f-1824-4def-b7fb-6883c3fa2b52)\n - [Sub Limits](#0c3e0c5a-80ee-49f6-9ca5-52941547d4bd)\n - [Business Property](#60aba72b-ca56-4806-97b0-bdf580669943)\n- [Exclusions](#29529f14-e489-4f2a-bea8-0eef68f431b0)\n - [Earth Movement And Flood](#51c3a6b7-7b78-404e-a1f3-b39be8498294)\n - [Ensuing Loss](#908cf899-f5af-40c8-9829-4e09da9083c9)\n - [Concurrent Causation](#f48d2861-3d9a-4db6-b2d1-78d22013c3fb)\n - [Other Exclusions](#3336ee6d-9723-4fe1-914f-75109187cc0a)\n - [Wear And Tear](#f66ab1c5-d5fe-42ac-bf71-56a3c769a0a6)\n - [Vacancy](#75eff73f-3166-45dd-9140-a9182f858e47)\n- [Claims And Conditions](#35ccfa20-00fb-462e-b375-aaa1b84a1d8f)\n - [Duties After A Loss](#a08d6602-32b0-41e0-ad85-5d951dfc93c0)\n - [Notice Deadline](#a68996f1-acd7-403e-bb68-58a7fbe336f0)\n - [Emergency Repairs](#edd78fe8-08d6-4f55-a19b-d15a2a05464b)\n - [Dispute Resolution](#bdf63da4-4f34-48f0-82a2-cece1ef666d0)\n - [Suit Limitation](#db860fc2-e02e-4efa-8205-553b392b63ca)\n - [Loss Payment](#0f7081fd-75c2-4e0f-8355-b4d66a13c20f)\n- [Policyholder Acknowledgment](#065d0342-0c5b-4fbc-9888-b78ac5e0fefc)\n- [Signature Lines](#f47e4117-eda0-477d-9a76-482bff511444)\n", "metadata": { "filename": "insurance_policy-md.md", "org_id": "org_123", "duration_ms": 15435, "credit_usage": 6.0588, "job_id": "17aa1381fe97495f8b9be76baba9932c", "version": "section-20260406" } } ``` ## Response Structure The response contains the following top-level fields: | Field | Description | | -------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------- | | [`table_of_contents`](#table-of-contents-table_of_contents) | A flat, reading-order array of section entries with hierarchy levels and chunk references. | | [`table_of_contents_md`](#markdown-table-of-contents-table_of_contents_md) | A Markdown-formatted version of the same TOC with anchor links. | | [`metadata`](#processing-metadata-metadata) | Processing information including credit usage, duration, filename, job ID, and model version. | ## Table of Contents (`table_of_contents`) The `table_of_contents` field contains a flat array of all sections and subsections in the order they appear in the document. The flat list structure is optimized for retrieval use cases. You can iterate the list directly without recursion. Each entry includes: | Field | Description | | ----------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | `title` | The generated text for the section heading. | | `level` | The hierarchy depth. Top-level sections are `1`, subsections are `2`, sub-subsections are `3`, and so on. | | `section_number` | The hierarchical number for this section (for example, `"1"`, `"1.2"`, `"1.2.3"`). Use this field to reconstruct parent-child relationships: entry `"2.1"` is a child of entry `"2"`. | | `start_reference` | The ID of the chunk where this section begins. This corresponds to a `chunks[].id` value from the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) response. | ## Markdown Table of Contents (`table_of_contents_md`) The `table_of_contents_md` field provides a ready-to-use Markdown-formatted TOC. Each entry is an anchor link pointing to the corresponding [reference anchor](./ade-markdown-response#anchor-tags) in the document Markdown. Indentation represents the hierarchy level. You can prepend this string to the document's full Markdown to enable in-document navigation: ```text theme={null} - [Introduction](#uuid_a1) - [Methods](#uuid_b2) - [Data Collection](#uuid_c3) - [Survey Design](#uuid_d4) ``` ## Processing Metadata (`metadata`) The `metadata` field provides information about the sectioning process: | Field | Description | | -------------- | -------------------------------------------------------------------------------------------------------------- | | `filename` | The name of the input Markdown file. | | `org_id` | Organization identifier. | | `duration_ms` | Processing time in milliseconds. | | `credit_usage` | Number of credits consumed. | | `job_id` | Unique job identifier. | | `version` | Model version used for sectioning. For more information, go to [Section Model Versions](./ade-section-models). | # Troubleshoot Sectioning Source: https://docs.landing.ai/ade/ade-section-troubleshoot Resolve Section API errors using status codes, causes, and recommended fixes. Use this section to troubleshoot issues encountered when calling the [ADE Section](https://docs.landing.ai/api-reference/tools/ade-section) API ([https://api.va.landing.ai/v1/ade/section](https://api.va.landing.ai/v1/ade/section)). ## Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ----------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Sectioning completed successfully. | Continue with normal operations. | | 400 | Bad Request | Invalid request due to Markdown download failure from URL. | Review error message for specific issue. See [Status 400](#status-400-bad-request). | | 401 | Unauthorized | Missing or invalid API key. | Check that your `Authorization` header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See [Status 422](#status-422-unprocessable-entity). | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. | | 500 | Internal Server Error | Server error during sectioning. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500](#status-500-internal-server-error). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit. | Reduce Markdown content size. See [Status 504](#status-504-gateway-timeout). | ## Status 400: Bad Request This status code indicates a client-side error. Review the specific error message to identify the issue. ### Error: Failed to download document from URL This error occurs when the API cannot download the Markdown file from the provided `markdown_url`. **Error message:** ``` Failed to download document from URL: {error_details} ``` **What to do:** * Verify the URL is accessible and returns valid content. * Check network connectivity and URL permissions. * Ensure the URL points to a Markdown file (.md extension). ## Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error message and adjust your request parameters. ### Error: No markdown provided This error occurs when your request does not include the `markdown` parameter or `markdown_url` parameter, or when the values are empty. **Error message:** ``` Must provide either 'markdown' or 'markdown_url'. ``` **What to do:** Add one of these parameters to your request: * Use the `markdown` parameter to upload a Markdown file or provide inline Markdown content, OR * Use the `markdown_url` parameter to provide a URL to a Markdown file. ### Error: Both 'markdown' and 'markdown\_url' provided This error occurs when your request includes both the `markdown` and `markdown_url` parameters. **Error message:** ``` Cannot provide both 'markdown' and 'markdown_url'. ``` **What to do:** Remove one of the parameters. Use either `markdown` (to upload a file or provide inline content) or `markdown_url` (to specify a URL), but not both in the same request. ### Error: Invalid 'markdown\_url' format This error occurs when the value provided for `markdown_url` is not a valid URL. **Error message:** ``` Invalid URL format: {url} ``` **What to do:** * Verify that the URL is correctly formatted (for example, `https://example.com/document.md`). * Ensure the URL includes a scheme (`https://` or `http://`). ### Error: Multiple markdown files detected This error occurs when multiple Markdown files are included in the request. **Error message:** ``` Multiple markdown files detected (X). Please provide only one document file. ``` **What to do:** Send only one Markdown file per request. ### Error: Unsupported format This error occurs when you provide a file other than Markdown (.md) to the section endpoint. **Error message:** ``` Unsupported format: {mime_type} ({filename}). Supported formats: MD ``` **What to do:** * The section endpoint only accepts Markdown files with a .md extension. * If you have a PDF, DOCX, or other document format, use the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) to convert your document to Markdown first, then pass the parsed Markdown output to the section endpoint. * Ensure your file has a .md extension and contains valid UTF-8 encoded Markdown content. ### Error: Missing reference anchors This error occurs when the Markdown content does not contain reference anchors. The section endpoint requires Markdown output from the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse), which includes `` anchors that ADE Section uses to map sections to chunks. **Error message:** ``` Invalid markdown: missing reference anchors. Markdown must contain reference delimiters. Use the parse tool to generate properly formatted markdown. ``` **What to do:** * Do not pass plain Markdown or documents you have formatted manually. Use the Markdown output from the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) as input. * Confirm the Markdown content contains `` anchor tags before sending it to the section endpoint. ## Status 500: Internal Server Error This error indicates an unexpected server error occurred during sectioning. **What to do:** * Retry the request. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 504: Gateway Timeout This error occurs when the sectioning process exceeds the timeout limit. **What to do:** * Reduce the size of your Markdown document. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Best Practices for Avoiding Errors * **Use parsed Markdown**: Always pass Markdown content generated by the [ADE Parse API](./parse). The section endpoint requires structured Markdown with [reference anchors](./ade-markdown-response#anchor-tags) (``). * **Use guidelines sparingly**: The `guidelines` parameter is optional. Start without guidelines to see the default behavior before customizing the hierarchy. ## When Are Credits Consumed? Credits are consumed only when the ADE Section API returns a 200 status code. All other responses, including errors, do not consume credits. # Split Source: https://docs.landing.ai/ade/ade-split Separate a parsed document into classified sub-documents by type (Preview). Use the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) API to split a parsed document into multiple classified sub-documents. Organizations typically use Split when they receive batched documents that contain multiple document types or multiple instances of the same document type. The API classifies each sub-document and returns the full Markdown content for downstream processing. Splitting occurs after [parsing](https://docs.landing.ai/api-reference/tools/ade-parse) but before [extraction](https://docs.landing.ai/api-reference/tools/ade-extract). You can use Split without performing extraction. ADE Split is in Preview. This feature is still in development and may not return accurate results. Do not use this feature in production environments. ## Example Use Cases * **Financial Services**: Financial institutions processing Know Your Customer (KYC) documentation often receive PDFs containing multiple document types for each customer, such as bank statements, utility bills, and identification documents. After parsing the batch, the ADE Split API separates and classifies each document type. * **Healthcare**: Healthcare systems ingesting patient records may receive batched PDFs containing intake forms, pathology reports, and medication lists. The ADE Split API separates these documents by type for routing to appropriate systems. * **Accounting**: Accounting departments processing expense documentation receive PDFs with multiple invoices and receipts. The ADE Split API separates each document and can use identifiers like invoice numbers or dates to create individual splits for each transaction. * **Academic Research**: Research institutions and libraries processing academic articles receive PDFs containing article bodies, references, and supplemental materials. The ADE Split API separates these sections for indexing, citation extraction, or archival purposes. * **Product Documentation**: Organizations managing product catalogs receive PDFs containing specifications for multiple products. The ADE Split API separates each product's specifications, enabling automated data entry into product databases or comparison tools. * **Technical Documentation**: Companies distributing multilingual instruction manuals receive PDFs with the same content repeated in different languages. The ADE Split API separates the manual by language, allowing each version to be routed to the appropriate regional system or translation workflow. For credit consumption rates, see [Credit Consumption](./ade-credit-consumption#credit-costs-for-the-split-api). ## Process Overview Follow these steps to split a document into classified sub-documents: 1. **Parse your document** using the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse). The ADE Split API requires Markdown content from the parse API as input. Save the Markdown output for the next step. 2. **Define your Split Rules** by creating a set of Split Types that describe the different document types or sections in your file. Learn more about [Split Rules](#split-rules). The easiest way to create and test Split Rules is in the [Playground](#split-in-the-playground). 3. **Run the ADE Split API** by passing the parsed Markdown content and your Split Rules. Choose your method: * [Split in the Playground](#split-in-the-playground): Test and refine your Split Rules interactively * [Split with the API](#split-with-the-api): Integrate splitting into your application * [Split with the Python & TypeScript Libraries](#use-split-with-our-libraries): Use our libraries 4. **Use the split results** in your downstream workflows. The API returns each classified sub-document with its full Markdown content. Learn more about the [response structure](./ade-split-response). ## Split Rules Split Rules define how the ADE Split API classifies and separates a document into sub-documents. The Split Rules are a collection of all Split Types you define for a single API call. Each Split Rule consists of a: * [Split Type](#split-types) * [Description](#descriptions-optional) (optional) * [Identifier](#identifiers-optional) (optional) Split Rules are defined differently depending on whether you use the Playground, API, or one of our libraries. See the interface-specific sections below for more information on how to create and pass the Split Rules for your method. ### Split Types Split Types define how your document is classified into sections, such as pay stubs, bank statements, and W-2s. You can define up to 19 Split Types in one API call. If the API cannot determine which Split Type a page belongs to, it classifies the page as **Uncategorized**. ### Descriptions (Optional) The Description provides additional context about what a Split Type represents. Detailed descriptions help the API identify what information to include in each split and improve classification accuracy. Descriptions can also impact how the API interprets Identifiers. For example, these two descriptions for clinical notes produce different identifier behavior: * **Less specific description**: "A clinical note documenting a patient's office visit, including history, exam, assessment, and plan, authored by a provider." The API might consider multiple dates as potential identifiers. * **More specific description**: "A clinical note documenting a patient's office visit, including history, exam, assessment, and plan, authored by a provider. Each note is separated by office visit date. Do not look at any other dates. Only include date before the words 'office visit'." The API only considers dates directly before "office visit" as identifiers. ### Identifiers (Optional) When your document contains multiple instances of the same Split Type, use an Identifier to specify what makes each instance unique, such as invoice number, order ID, or date. The API creates a separate split for each unique value of the Identifier. For example, if your document contains 6 pay stubs and you specify "Pay Stub Date" as the identifier, the API creates 6 separate splits—one for each unique date value. ### Example A document contains 1 bank statement and 6 pay stubs with different dates. You define two Split Types: * **Bank Statement** (no identifier needed) * **Pay Stub** with "Pay Stub Date" as the identifier The API returns 7 splits: 1 bank statement and 6 pay stubs, each separated by payment date. ## Split in the Playground To make it as easy as possible to split documents, we've created a wizard in our [Playground](https://ade.landing.ai/my/playground/ade) that guides you through the process. The Playground is designed as a proof-of-concept to help you understand what the API can do and how it might fit into your workflows. After you've split a document in the Playground copy the code to use it in API calls or our Python and TypeScript libraries so that you can scale. 1. Go to the [Playground](https://ade.landing.ai/my/playground/ade). 2. Click **Split**. 3. Select the file you want to split. 4. Agentic Document Extraction loads and parses the file in the background. 5. You can now create the [Split Rules](#split-rules), which determine how the document is split into sub-documents. There are a few ways to do this: * **View Suggested Split Rules**: The app automatically recommends rules based on the parsed content. We recommend trying this approach first, and then editing the rules if needed. * **Write a Split Rules Prompt**: Write a prompt that tells the app what specific Split Types and Identifiers should be used. The app then generates rules based on this prompt. * **Start from Scratch**: Manually define the Split Rules. 6. After creating your first round of Split Rules, edit them if needed. 7. Click **Split Document** to see the results, which open in a new panel. You can toggle between a visual representation of the results and the actual API JSON response. 8. You can continue to edit the Split Rules if needed. 9. When the document splits as expected, copy the code so that you can scale the API call. ## Split with the API Split a document by calling the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) endpoint. This example splits a document containing bank statements and pay stubs: ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/split' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@markdown.md' \ -F 'split_class=[{"name": "Bank Statement", "description": "Document from a bank that summarizes all account activity over a period of time."}, {"name": "Pay Stub", "description": "Document that details an employee'\''s earnings, deductions, and net pay for a specific pay period.", "identifier": "Pay Stub Date"}]' \ -F 'model=split-latest' ``` ### Parameters Get the full parameters from the [API reference](https://docs.landing.ai/api-reference/tools/ade-split). * **`markdown`** (required): The Markdown output from the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse). You can pass the Markdown content directly or reference a file. * **`split_class`** (required): A JSON array defining the [Split Rules](#split-rules). Each Split Type is a JSON object with: * [`name`](#split-types): The Split Type name (required) * [`description`](#descriptions-optional): Additional context about the Split Type (optional) * [`identifier`](#identifiers-optional): The field that makes each instance unique (optional) * **`model`** (optional): The model version to use for splitting. If omitted, the API uses the latest model. For more information, see [Split Model Versions](./ade-split-models). ## Use Split with Our Libraries Click one of the tiles below to learn how to use the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) API with our libraries. Use Split with our Python library. TypeScript TypeScript } href="./ade-typescript#split-getting-started" > Use Split with our TypeScript library. ## Additional Considerations on Splitting * Each page in a document can only be assigned to one Split Type. If one page has content that could belong to more than one Split Type, the API chooses the Split Type that the page matches more closely. * The ADE Split API is different from the `split` parameter in the ADE Parse API. The ADE Split API separates a document into sub-documents after parsing, while the `split` parameter can be used during parsing to organize the parsed output by page. # Split Model Versions Source: https://docs.landing.ai/ade/ade-split-models Choose a split model and set it when splitting files. A split model powers the classification and splitting capabilities of the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) API. The model analyzes parsed Markdown content and classifies pages into the Split Types you define, then separates the document into sub-documents. You can specify a model when calling the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) API directly or when using the [client libraries](#set-the-model-with-the-client-libraries). If you don't specify a model, the API uses the latest split model (currently `split-20251105`). ## Model Versions The following table lists the available `model` values for the ADE Split API: | Model Values | Description | | ---------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | | `split-20260903` | Use the split model snapshot released on September 3, 2026, on an updated underlying model. To test it, set `model` to `split-20260903`. `split-latest` still uses `split-20251105`. | | `split-20251105` | Use the split model snapshot released on November 5, 2025. | | `split-latest` | Use the latest split model snapshot. | ### Why Model Versioning Matters When integrating the API, you have two options for specifying the model: 1. **Use `split-latest`** to always get the newest version. This automatically gives you improvements and updates, but results may change when new model versions are released. 2. **Use a specific version** (like `split-20251105`) to pin to an exact model version. This ensures consistent results over time, but you won't receive improvements. ## Set the Model in the API When calling the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) endpoint, you can set the model using the `model` parameter. If you omit the `model` parameter, the API uses the latest model. This example shows how to specify a model: ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/split' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@markdown.md' \ -F 'split_class=[{"name": "section_type", "description": "Type of document section (e.g., header, paragraph, table)"}]' \ -F 'model=split-latest' ``` ## Set the Model with the Client Libraries When using the Python or TypeScript library, you can set the model using the `model` parameter in the `split()` method. If you omit the `model` parameter, the library will use the latest split model. ```python {13} Python theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.split( markdown=Path("/path/to/parsed_output.md"), split_class=json.dumps([ {"name": "Invoice", "description": "Payment request document"}, {"name": "Receipt", "description": "Payment confirmation document"} ]), model="split-latest" ) ``` ```typescript {12} TypeScript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const response = await client.split({ markdown: fs.createReadStream("/path/to/parsed_output.md"), split_class: [ { name: "Invoice", description: "Payment request document" }, { name: "Receipt", description: "Payment confirmation document" } ], model: "split-latest" }); ``` ## The Playground Uses the Latest Model Version The Playground uses the latest model version. # JSON Response for Splitting Source: https://docs.landing.ai/ade/ade-split-response Understand the Split JSON response: classified sub-documents and processing metadata. When you split a document with the [ADE Split API](https://docs.landing.ai/api-reference/tools/ade-split), the classified splits and metadata are returned in a structured JSON format. ## Response Structure The response contains the following top-level fields: * [`splits`](#splits-array-splits): Array of split objects containing the classified sub-documents. * [`metadata`](#processing-metadata-metadata): Processing information including credit usage, duration, filename, job ID, page count, and model version. ## Splits Array (`splits`) The `splits` field contains an array of classified sub-documents. Each split object includes: * **`classification`**: The Split Type name assigned to this sub-document (e.g., "Bank Statement", "Pay Stub"). * **`identifier`**: The unique identifier value for this split (e.g., "2024-01-15", "Invoice #12345"). This field is `null` if no identifier was specified for this Split Type. * **`pages`**: Array of zero-indexed page numbers that belong to this split. * **`markdowns`**: Array of [Markdown](./ade-markdown-response) content strings, one for each page in this split. The order matches the `pages` array. ### Classification and Identifiers The `classification` field corresponds to the Split Type names you defined in your [Split Rules](./ade-split#split-rules). If the API cannot classify a page, it assigns the classification "Uncategorized". When you specify an identifier in your Split Rules (such as "Date" or "Invoice Number"), the API creates separate splits for each unique identifier value it finds. The `identifier` field contains the extracted value (e.g., "2024-01-15" or "INV-001"). ### Pages and Markdown Content The `pages` array lists which pages belong to each split. Pages are zero-indexed, so the first page is `0`. The `markdowns` array contains the Markdown content for each page. Each element corresponds to the page at the same index in the `pages` array. For example, if `pages` is `[0, 1, 2]`, then `markdowns[0]` contains the Markdown for page 0, `markdowns[1]` contains the Markdown for page 1, and `markdowns[2]` contains the Markdown for page 2. ## Processing Metadata (`metadata`) The `metadata` field provides information about the split process: * **`filename`**: The name of the input Markdown file. * **`org_id`**: Organization identifier. * **`page_count`**: Total number of pages in the document. * **`duration_ms`**: Processing time in milliseconds. * **`credit_usage`**: Number of credits consumed. * **`job_id`**: Unique job identifier. * **`version`**: Model version used for splitting. For more information, go to [Split Model Versions](./ade-split-models). ## Example Response Here is a complete example showing a split response for a document containing bank statements and pay stubs: ```json theme={null} { "splits": [ { "classification": "Bank Statement", "identifier": null, "pages": [0], "markdowns": [ "\n\n## Bank Statement\n\nAccount Number: 1234567890\n\nStatement Period: January 1 - January 31, 2025\n\n| Date | Description | Amount |\n|------|-------------|--------|\n| 01/05 | Deposit | $2,500.00 |\n| 01/12 | Withdrawal | -$500.00 |\n\nEnding Balance: $2,000.00" ] }, { "classification": "Pay Stub", "identifier": "2025-01-15", "pages": [1], "markdowns": [ "\n\n## Pay Stub\n\nEmployee: John Smith\n\nPay Date: January 15, 2025\n\nGross Pay: $6,000.00\n\nNet Pay: $4,500.00" ] }, { "classification": "Pay Stub", "identifier": "2025-01-30", "pages": [2], "markdowns": [ "\n\n## Pay Stub\n\nEmployee: John Smith\n\nPay Date: January 30, 2025\n\nGross Pay: $6,000.00\n\nNet Pay: $4,500.00" ] } ], "metadata": { "filename": "mixed-documents.md", "org_id": "org_abc123", "page_count": 3, "duration_ms": 2145, "credit_usage": 3.0, "job_id": "split_xyz789", "version": "split-20251105" } } ``` In this example: * The document was split into 3 sub-documents: 1 bank statement and 2 pay stubs. * The bank statement has no identifier (set to `null`). * Each pay stub is identified by its pay date ("2025-01-15" and "2025-01-30"), creating separate splits even though they have the same classification. * Each split contains the page numbers and Markdown content for that sub-document. # Troubleshoot Splitting Source: https://docs.landing.ai/ade/ade-split-troubleshoot Resolve Split API errors using status codes, causes, and recommended fixes. Use this section to troubleshoot issues encountered when calling the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) API ([https://api.va.landing.ai/v1/ade/split](https://api.va.landing.ai/v1/ade/split)). ## Common Status Codes | Status Code | Name | Description | What to Do | | ----------- | --------------------- | ----------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------- | | 200 | Success | Split classification completed successfully. | Continue with normal operations. | | 400 | Bad Request | Invalid request due to markdown download failure from URL. | Review error message for specific issue. See [Status 400](#status-400-bad-request). | | 401 | Unauthorized | Missing or invalid API key. | Check that your `apikey` header is present and contains a valid [API key](./agentic-api-key). | | 402 | Payment Required | Your account does not have enough credits to complete processing. | If you have multiple accounts, make sure you're using the correct [API key](./agentic-api-key). Add more credits to your account. | | 422 | Unprocessable Entity | Input validation failed. | Review your request parameters. See [Status 422](#status-422-unprocessable-entity). | | 429 | Too Many Requests | Rate limit exceeded. | Wait before retrying. Reduce request frequency and implement exponential backoff. | | 500 | Internal Server Error | Server error during split classification. | Retry. If the issue persists, contact [support@landing.ai](mailto:support@landing.ai). See [Status 500](#status-500-internal-server-error). | | 504 | Gateway Timeout | Request processing exceeded the timeout limit. | Reduce markdown content size. See [Status 504](#status-504-gateway-timeout). | ## Status 400: Bad Request This status code indicates invalid request parameters or client-side errors. Review the specific error message to identify the issue. ### Error: Failed to download document from URL This error occurs when the API cannot download the Markdown file from the provided `markdown_url`. **Error message:** ``` Failed to download document from URL: {error_details} ``` **What to do:** * Verify the URL is accessible and returns valid content. * Check network connectivity and URL permissions. * Ensure the URL points to a Markdown file (.md extension). ## Status 422: Unprocessable Entity This status code indicates input validation failures. Review the error message and adjust your request parameters. ### Error: No markdown file, content, or URL provided This error occurs when your request does not include the `markdown` parameter or `markdown_url` parameter, or when the values are empty. **Error message:** ``` No markdown file, content, or URL provided. ``` **What to do:** Add one of these parameters to your request: * Use the `markdown` parameter to upload a Markdown file or provide inline Markdown content, OR * Use the `markdown_url` parameter to provide a URL to a Markdown file. ### Error: Multiple markdown files detected This error occurs when multiple Markdown files are included in the request. **Error message:** ``` Multiple markdown files detected (X). Please provide only one markdown file. ``` **What to do:** Send only one Markdown file per request. ### Error: Unsupported format This error occurs when you provide a file other than Markdown (.md) to the split endpoint, such as PDF, DOCX, XLSX, or image files. **Error message:** ``` Unsupported format: {mime_type} ({filename}). Supported formats: MD ``` **What to do:** * The split endpoint only accepts Markdown files with a .md extension. * If you have a PDF, DOCX, or other document format, use the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) endpoint to convert your document to Markdown first, then pass the parsed Markdown output to the split endpoint. * Ensure your file has a .md extension and contains valid UTF-8 encoded Markdown content. ### Error: split\_class must contain at most 19 split classification names This error occurs when you provide more than 19 Split Types in the `split_class` parameter. **Error message:** ``` split_class must contain at most 19 split classification names ``` **What to do:** * Reduce the number of Split Types to 19 or fewer. * Consider combining similar Split Types or removing less important ones. * For more information, see [Split Types](./ade-split#split-types). ## Status 500: Internal Server Error This error indicates an unexpected server error occurred during split classification. **Error message:** ``` Internal server error during split classification ``` **What to do:** * Retry the request. * Verify your [Split Rules](./ade-split#split-rules) are properly formatted with valid Split Type names, descriptions, and identifiers. * Check that your Markdown content is valid and properly formatted. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Status 504: Gateway Timeout This error occurs when the split classification process exceeds the timeout limit. **Error message:** ``` Request timed out after {seconds} seconds ``` **What to do:** * Reduce the size of your Markdown document. * If processing a very large document, consider splitting it into smaller sections before using the split endpoint. * If the error persists, contact [support@landing.ai](mailto:support@landing.ai). ## Best Practices for Avoiding Errors * **Use parsed Markdown**: Always pass Markdown content that has been generated by the [ADE Parse API](./parse). The split endpoint expects structured Markdown with the specific format produced by the parse API. * **Define clear Split Rules**: Provide detailed descriptions for each Split Type to help the model accurately classify your document sections. For guidance, see [Split Rules](./ade-split#split-rules). * **Use appropriate identifiers**: Only specify identifiers when your document contains multiple instances of the same Split Type that need to be separated. For guidance, see [Identifiers](./ade-split#identifiers-optional). ## When Are Credits Consumed? Credits are consumed only when the ADE Split API returns a 200 status code. All other responses, including errors, do not consume credits. # Rate Limits Source: https://docs.landing.ai/ade/ade-rate-limits See how page-per-hour rate limits work by pricing plan and at the organization level. Rate limits help ensure that the API stays fast and available for everyone. Rate limits prevent any single user or accidental spike in traffic from slowing things down for others. ## Maximum Pages per Hour Rate limits apply per pricing plan and are the same for both ADE Parse and ADE Parse Jobs endpoints. Higher pricing plans have increased rate limits to support larger processing volumes. The [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) API has its own per-hour limit, separate from the Parse and Parse Jobs limit. Each extract job counts as a single submission (one page equivalent) toward this limit, regardless of the size of the Markdown document. Hourly rate limits are distributed per minute to ensure consistent API performance for all users. This distribution means your requests are processed evenly throughout the hour rather than all at once. Rate limits apply at the organization level. All requests from any user or API key within your organization count toward the same limit. ## Maximum Pages per Document The maximum number of pages you can parse in a single PDF depends on the API endpoint and parsing method. The table below shows the page limits for each combination. | Endpoint | [Playground](https://ade.landing.ai/demo/doc-extraction) | API Request / [ade-python library](https://github.com/landing-ai/ade-python) | | ---------------------------------------------------------------------------- | -------------------------------------------------------- | ---------------------------------------------------------------------------- | | [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) | 100 pages | 100 pages | | [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) | N/A1 | 1 GB or
6,000 pages | 1. The Playground does not use ADE Parse Jobs. # Supported File Types Source: https://docs.landing.ai/ade/ade-file-types See which file types ADE can parse, including PDFs, images, Office files, and spreadsheets. Agentic Document Extraction can parse the file types listed in the table below. Support depends on the method you use: the [Playground](https://ade.landing.ai/my/playground/ade), [API](https://docs.landing.ai/api-reference/tools/ade-parse), or our [Python](https://github.com/landing-ai/ade-python) and [TypeScript](https://github.com/landing-ai/ade-typescript) libraries.
File Type Playground API/Library
PDF
PDF ✓
up to 100 pages
✓
see [Rate Limits](./ade-rate-limits)
Images
JPEG ✓ ✓
JPG ✓ ✓
PNG ✓ ✓
APNG × ✓
BMP × ✓
DCX × ✓
DDS × ✓
DIB × ✓
GD × ✓
GIF × ✓
ICNS × ✓
JP2 (JP2000) × ✓
PCX × ✓
PPM × ✓
PSD × ✓
TGA × ✓
TIF × ✓
TIFF × ✓
WEBP ✓ ✓
Text Documents
(see notes [here](#file-conversion-for-text-documents-and-presentations))
DOC (Word) ✓ ✓
DOCX (Word) ✓ ✓
ODT (OpenDocument Text) ✓ ✓
Presentations
(see notes [here](#file-conversion-for-text-documents-and-presentations))
PPT (PowerPoint) ✓ ✓
PPTX (PowerPoint) ✓ ✓
Spreadsheets
(see notes [here](#spreadsheet-considerations))

CSV (comma-separated values) ✓
(up to 10 MB)
✓
(up to 50 MB)
XLSX (Microsoft Excel) ✓
(up to 10 MB)
✓
(up to 50 MB)
To parse password-protected files, go to [Parse Password-Protected Files](./ade-parse-password). ## File Conversion for Text Documents and Presentations Agentic Document Extraction converts text documents and presentations to PDFs before parsing them. This conversion may change the document layout and increase or decrease the number of pages. For example, unsupported fonts may be replaced with larger alternatives, causing text to wrap differently or overflow onto additional pages. While the conversion process may impact the layout, Agentic Document Extraction still parses content correctly. ## Spreadsheet Considerations Agentic Document Extraction supports XLSX files with up to 65,536 rows and 65,536 columns per file. If an XLSX file exceeds these limits, Agentic Document Extraction parses the file and returns data within the supported limits. Content in rows and columns beyond the limits is not parsed. When you load a spreadsheet in the Playground, a render limit applies and only a truncated version of the spreadsheet is displayed. This does not affect the parsing results. # European Union (EU) Source: https://docs.landing.ai/ade/ade-eu Use the EU-hosted ADE for data residency, GDPR compliance, and lower latency for European users. Agentic Document Extraction is available in the European Union (EU) here: [https://ade.eu-west-1.landing.ai/](https://ade.eu-west-1.landing.ai/). Agentic Document Extraction in the EU provides: * **Data residency**: All data is stored and processed within the EU * **GDPR compliance**: The EU-hosted version of Agentic Document Extraction is compliant with the General Data Protection Regulation (GDPR) * **Regional performance**: Reduced latency for European users ## GDPR and Compliance Refer to the resources below to learn more about GDPR and compliance. Enterprise plans support SSO via SAML 2.0 and OpenID Connect (OIDC), allowing your organization to manage access through your existing identity provider (IdP). Enterprise plans can restrict an organization's API access to approved IP addresses and CIDR ranges. The Trust Center is your central resource for accessing our security documentation, compliance reports, and real-time system status. This page outlines our security posture, compliance with industry standards, and the measures we take to safeguard your data across our products and infrastructure. ## EU Pricing For EU subscription plans and pricing, go to [Plans & Billing](./ade-pricing). Pricing is the same in the US and EU regions. ## Differences When Using the EU Using Agentic Document Extraction in the EU works the same as the default US deployment, with only a few key differences outlined in this article: * [Create an account](#create-an-account-in-the-eu): Use the EU URL * [Get your API key](#get-your-api-key-for-the-eu): Use the EU URL * [Call the API directly](#call-the-api-directly-in-the-eu): Use the EU endpoint * [Use the library](#use-the-library-with-the-eu): Set the EU endpoint as an environment variable ### Create an Account in the EU Create an account and access the Playground in the EU here: [https://ade.eu-west-1.landing.ai/home](https://ade.eu-west-1.landing.ai/home). ### Get Your API Key for the EU To get your API key for the EU, go to [https://ade.eu-west-1.landing.ai/settings/api-key](https://ade.eu-west-1.landing.ai/settings/api-key). Use this API key when using the library or calling the API directly in the EU. API keys are deployment-specific. An API key created in the US will not work for the EU, and vice versa. ### Call the API Directly in the EU To ensure your API calls are processed in the EU, replace the default base URL with the EU base URL: **US:** `https://api.va.landing.ai`\ **EU:** `https://api.va.eu-west-1.landing.ai` For example: * US: `https://api.va.landing.ai/v1/ade/parse` * EU: `https://api.va.eu-west-1.landing.ai/v1/ade/parse` ### Use the Library with the EU To connect the library to the EU deployment, set the `environment` parameter to `eu` when initializing the client. ```python Python theme={null} from landingai_ade import LandingAIADE client = LandingAIADE( environment="eu", ) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; const client = new LandingAIADE({ environment: "eu" }); ``` # Security and Privacy Source: https://docs.landing.ai/ade/ade-security Review ADE security practices, zero data retention, and compliance certifications (GDPR, SOC 2, HIPAA). LandingAI is committed to protecting your data and maintaining the highest security standards for Agentic Document Extraction. Refer to the resources below to learn about our security practices, zero data retention (ZDR) option, compliance certifications (GDPR, SOC 2 Type II, HIPAA), and more. Enterprise plans support SSO via SAML 2.0 and OpenID Connect (OIDC), allowing your organization to manage access through your existing identity provider (IdP). Enterprise plans can restrict an organization's API access to approved IP addresses and CIDR ranges. The Trust Center is your central resource for accessing our security documentation, compliance reports, and real-time system status. This page outlines our security posture, compliance with industry standards, and the measures we take to safeguard your data across our products and infrastructure. # Credit Consumption Source: https://docs.landing.ai/ade/ade-credit-consumption Understand credit consumption rates for the ADE Gen1 Parse, Extract, Build Schema, Classify, Section, and Split APIs. This page covers credit consumption for the ADE Gen1 APIs. For plans and billing, see [Plans & Billing](./ade-pricing). ## Credit Costs The credit consumption is determined by the specific API endpoint called. * [Parse APIs](#credit-costs-for-the-parse-apis) * [Extract API](#credit-costs-for-the-extract-api) * [Build Extract Schema API](#credit-costs-for-the-build-extract-schema-api) * [Classify API](#credit-costs-for-the-classify-api) * [Section API](#credit-costs-for-the-section-api) * [Split API](#credit-costs-for-the-split-api) ### Credit Costs for the Parse APIs This section explains credit use for these APIs: * [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) * [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) #### Documents The number of credits used to parse a document is based on the number of pages and the features used in parsing, as shown in the following table. | Feature | Credit Cost | Notes | | :-------------- | :------------- | :--------------------------------------------------------------------------- | | Parsing | 3 credits/page | Each page processed includes parsing. | | ZDR (HIPAA/BAA) | +1 credit/page | Additional charge when enabled.
Available on Team and Enterprise plans. | #### Spreadsheets The number of credits used to parse a spreadsheet is based on the number of sheets and embedded images. For supported spreadsheet formats, see [Supported File Types](./ade-file-types). | Feature | Credit Cost | Notes | | :-------------- | :----------------------------------- | :--------------------------------------------------------------------------- | | Parsing | 1 credit/sheet | Each sheet processed includes parsing. | | Embedded images | 3 credits/image | Cost per embedded image, chart, or logo. | | ZDR (HIPAA/BAA) | +1 credit/sheet
+1 credit/image | Additional charge when enabled.
Available on Team and Enterprise plans. | **Example:** A spreadsheet with 1 sheet and 2 embedded images: * Base cost: 1 credit (sheet) + 6 credits (2 images) = **7 credits** * With ZDR enabled: 7 credits (base) + 1 credit (sheet) + 2 credits (2 images) = **10 credits** ### Credit Costs for the Extract API This section explains credit use for these APIs: * [ADE Extract API](https://docs.landing.ai/api-reference/tools/ade-extract) * [ADE Extract Jobs](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) The number of credits used to extract data is based on both the number of input characters and output characters, and is rounded up to the nearest tenth decimal place. The same credit costs apply whether you extract data synchronously with the ADE Extract API or asynchronously with the [ADE Extract Jobs](./ade-extract-async) API. | Factor | Credit Cost | Notes | | :---------------------- | :---------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | 5,000 input characters | 1 credit | Input characters are the number of characters in the Markdown file that is passed to the API. | | 1,000 output characters | 1 credit | Output characters are the number of characters in the `extraction` object returned by the API, excluding whitespace used for indentation. (Other spaces, like the spaces after colons in key-value pairs, are not removed.) | **Formula** Here is the formula used to calculate the credit cost: ```text theme={null} credits = (input characters ÷ 5,000) + (output characters ÷ 1,000) Result is rounded up to the nearest tenth decimal place. ``` #### Sample Cost for the Extract API **Input Characters** Let's say you run the ADE Extract API on a Markdown file with the following content. The file has 2,270 characters. Therefore, **the number of input characters is 2,270.** ``` \n\nAROMA CAFE\n1211 Green Street\nNew York, NY 10005\n\n\n\n12/27/2019\n\n\n\n08:26 PM\n\n\n\nTAB 8 HOST MAGGIE\n\n\n\nAMEX ##########19883\n\n\n\n\n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n \n
QTYDESCAMT
1Americano$3.19
1Almond Scone$1.99
116oz Bottle Water$2.99
\n\n\n\nAMT: $8.70\n\nSUBTOTAL: $8.17\nTAX: $0.53\n\nBALANCE: $8.70\n\n\n\nSummary : This image displays a barcode consisting of a series of vertical black and white lines, used for encoding information in a machine-readable format.\n\nbarcode:\n Barcode Details :\n • The barcode is composed of alternating black and white vertical bars of varying thickness.\n • No human-readable numeric or alphanumeric string is visible below or above the barcode.\n • Barcode type is not explicitly indicated; the pattern resembles a standard linear barcode (e.g., Code 128 or EAN-13), but cannot be definitively identified without further context.\n • The barcode contains approximately 60–70 modules (individual bars and spaces).\n • Quiet zones (blank margins) are present on both the left and right sides of the barcode.\n • The barcode is horizontally oriented and centered on a white background.\n • No additional text, logo, or annotation is present.\n\nAnalysis :\n • The barcode is designed for machine scanning and does not convey any human-readable information in this image.\n • The absence of a numeric string or label means the encoded data cannot be determined visually.\n • The presence of quiet zones and consistent bar height suggests it is formatted for standard retail or inventory use.\n\n\n\nSAMPLE RECEIPT ``` **Output Characters** Let's say you extract multiple fields from the Markdown file, and the following is the content in the `extraction` object returned by the API. The response has 475 characters. Therefore, **the number of output characters is 475.** ``` {'merchant': {'name': 'AROMA CAFE', 'address': '1211 Green Street', 'city_state_zip': 'New York, NY 10005'}, 'transaction': {'date': '2019-12-27', 'time': '20:26', 'payment_method': 'AMEX ##########19883', 'tab_host': 'TAB 8 HOST MAGGIE'}, 'items': [{'qty': '1', 'desc': 'Americano', 'amt': '3.19'}, {'qty': '1', 'desc': 'Almond Scone', 'amt': '1.99'}, {'qty': '1', 'desc': '16oz Bottle Water', 'amt': '2.99'}], 'totals': {'subtotal': '8.17', 'tax': '0.53', 'total': '8.70'}} ``` **Calculate the Total** Now that you have your input and output character counts, you can calculate the credit cost: | Step | Calculation | Result | | ----------------------- | --------------------------------------- | ---------- | | Input credits | 2,270 ÷ 5,000 | 0.454 | | Output credits | 475 ÷ 1,000 | 0.475 | | Total (before rounding) | 0.454 + 0.475 | 0.929 | | Final cost | Round up to nearest tenth decimal place | 1.0 credit | ### Credit Costs for the Build Extract Schema API This section explains credit use for this API: * [ADE Build Extract Schema API](https://docs.landing.ai/api-reference/tools/ade-build-schema) The number of credits used to build an extraction schema is based on both the number of input characters and output characters, and is rounded up to the nearest tenth decimal place. | Factor | Credit Cost | Notes | | :---------------------- | :---------- | :----------------------------------------------------------------------------------------------------------------------------------- | | 5,000 input characters | 1 credit | Input characters are the combined total number of characters in the `markdowns`, `markdown_urls`, `prompt`, and `schema` parameters. | | 1,000 output characters | 1 credit | Output characters are the number of characters in the schema returned by the API. | **Formula** Here is the formula used to calculate the credit cost: ```text theme={null} credits = (input characters ÷ 5,000) + (output characters ÷ 1,000) Result is rounded up to the nearest tenth decimal place. ``` #### Sample Cost for the Build Extract Schema API Let's say you have an existing schema built from two bank statements. You want to add and remove some fields in the schema, so you call the ADE Build Extract Schema API to refine the schema. **Input Characters** The API includes the following parameters. | Parameter | Content | Characters | | :---------- | :----------------------------------------------------- | ---------: | | `markdowns` | The parsed output of the first bank statement | 9,116 | | `markdowns` | The parsed output of the second bank statement | 7,314 | | `schema` | The existing extraction schema that you want to refine | 9,089 | | `prompt` | Instructions to add and remove specific fields | 214 | | **Total** | | **25,733** | **Output Characters** Running the API call generates the following updated schema. | Content | Characters | | :------------- | ---------: | | Updated schema | 8,585 | **Calculate the Total** Now that you have your input and output character counts, you can calculate the credit cost. | Step | Calculation | Result | | :---------------------- | :-------------------------------------- | :----------- | | Input credits | 25,733 ÷ 5,000 | 5.1466 | | Output credits | 8,585 ÷ 1,000 | 8.585 | | Total (before rounding) | 5.1466 + 8.585 | 13.7316 | | Final cost | Round up to nearest tenth decimal place | 13.8 credits | ### Credit Costs for the Classify API This section explains credit use for this API: * [ADE Classify API](https://docs.landing.ai/api-reference/tools/ade-classify) The number of credits used to classify a document is based on the number of pages, and is rounded up to the nearest tenth decimal place. | Factor | Credit Cost | Notes | | :------- | :--------------- | :------------------------------------------------------------ | | Per page | 0.5 credits/page | Each page processed by the Classify API consumes 0.5 credits. | **Formula** Here is the formula used to calculate the credit cost: ```text theme={null} credits = number of pages × 0.5 Result is rounded up to the nearest tenth decimal place. ``` **Example:** A 10-page document costs 10 × 0.5 = **5.0 credits**. ### Credit Costs for the Section API This section explains credit use for this API: * [ADE Section API](https://docs.landing.ai/api-reference/tools/ade-section) The number of credits used to section a document is based on both the number of input characters and output characters, and is rounded up to the nearest tenth decimal place. | Factor | Credit Cost | Notes | | :---------------------- | :---------- | :--------------------------------------------------------------------------------------------------- | | 5,000 input characters | 1 credit | Input characters are the number of characters in the Markdown file passed to the API. | | 1,000 output characters | 1 credit | Output characters are the number of characters in the `table_of_contents` field returned by the API. | **Formula** Here is the formula used to calculate the credit cost: ```text theme={null} credits = (input characters ÷ 5,000) + (output characters ÷ 1,000) Result is rounded up to the nearest tenth decimal place. ``` ### Credit Costs for the Split API This section explains credit use for this API: * [ADE Split API](https://docs.landing.ai/api-reference/tools/ade-split) The number of credits used to split documents is based on the number of input characters, and is rounded up to the nearest tenth decimal place. | Factor | Credit Cost | Notes | | :--------------------- | :---------- | :-------------------------------------------------------------------------------------------- | | 5,000 input characters | 1 credit | Input characters are the number of characters in the Markdown file that is passed to the API. | **Formula** Here is the formula used to calculate the credit cost: ```text theme={null} credits = (input characters ÷ 5,000) Result is rounded up to the nearest tenth decimal place. ``` # Overview Source: https://docs.landing.ai/ade/ade-sf-overview Learn how to parse and extract data from documents in Snowflake with the ADE Marketplace app. Agentic Document Extraction (ADE) parses and extracts structured data from unstructured documents like PDFs and images. It identifies elements such as text, tables, and form fields, and returns them as Markdown and hierarchical JSON with exact page and coordinate references. Agentic Document Extraction is available as an application in the Snowflake Marketplace. Snowflake customers can use the Agentic Document Extraction app to parse and extract data from: * documents staged in Snowflake. * documents available at publicly accessible URLs. ## How ADE on Snowflake Works When you run the [parsing](./ade-sf-parse-cloud) or [extraction](./ade-sf-extract-cloud) procedure, the relevant files are sent to the Agentic Document Extraction service, which is hosted by LandingAI. The results display directly in Snowsight. ## Billing When you use the Agentic Document Extraction app, documents are processed using your Agentic Document Extraction account that is hosted by LandingAI. Billing for processing documents (like running parsing and field extraction) is managed by LandingAI. ## Zero Data Retention The ADE on Snowflake application cannot be used when Zero Data Retention (ZDR) is enabled in your organization. To use this application, turn off ZDR or use an organization that does not have ZDR enabled. ## ADE on Snowflake Checklist To install and start using the Agentic Document Extraction app on Snowflake, complete the following steps: **In Agentic Document Extraction:** 1. If you haven't already, [create an Agentic Document Extraction account](https://ade.landing.ai/). 2. [Get your API key](https://ade.landing.ai/my/settings/api-key). **In Snowsight:** 1. [Install the app](./ade-sf-install). Ensure that you grant the app access to external endpoints during the setup process. 2. [Enter your API key in the app](./ade-sf-install#enter-api-key). 3. If you want to parse documents staged in Snowflake, [grant the app access to the stages that have the files you want to parse](./ade-sf-grant-access-to-stages). 4. [Parse your files](./ade-sf-parse-cloud). 5. (Optional) [Run field extraction on the parsed output](./ade-sf-extract-cloud). # Install and Update Source: https://docs.landing.ai/ade/ade-sf-install Install and update the ADE app from the Snowflake Marketplace. ## Installation Requirements * Before installing any apps from the Snowflake Marketplace, a user with the ORGADMIN role must accept the Consumer Terms of Service for the Snowflake Marketplace. For more details, go to the [Snowflake Documentation](https://other-docs.snowflake.com/en/collaboration/consumer-becoming#accept-the-snowflake-provider-and-consumer-terms-of-service). * To install an app, you must use the ACCOUNTADMIN role or another role with the IMPORT SHARE and CREATE privileges. For more details, go to the [Snowflake Documentation](https://other-docs.snowflake.com/en/native-apps/consumer-installing). * Agentic Document Extraction is not available on Snowflake trial accounts. ## Request the App Access to the Agentic Document Extraction app is available by request. To request the app, follow the instructions below: 1. Open the [LandingAI](https://app.snowflake.com/marketplace/providers/GZTYZ12K65BX/LandingAI) provider page in the Snowflake Marketplace. 2. Locate and click the **Agentic Document Extraction** listing. 3. Click **Request App**. Request app 4. Fill out and submit the request form. 5. The LandingAI team will review the request and contact you with more information. ## Install the App After you have [requested the app](#request-the-app) and have been granted access to it, follow the instructions below to install it in Snowflake: 1. Go to **Snowsight** > **Catalog** > **Apps** > **Recently Shared with You**. 2. Locate and click the **Agentic Document Extraction - App** listing. 3. Click **Get**. Get app 4. If you want to change the name of the application, click **Options** and enter a name in **Application Name**. 5. Click **Get**. Get app 6. A pop-up indicates that the installation process has begun. Installation in progress 7. After this process is complete, click **Configure** on the pop-up. (You will also get an email notifying you that you can access the app.) If you've navigated away from the page, go to **Snowsight** > **Catalog** > **Apps**. Click the app listing. Although the app appears in Installed Apps, configuration is not complete. Configure 8. The app opens. 9. In the pop-up that displays, grant egress access by clicking **Connect**. **The app requires this access to function.** Egress access allows the app to connect to the Agentic Document Extraction service over the internet. Egress access pop-up The pop-up displays the following message: > AGENTIC\_DOCUMENT\_EXTRACTION\_\_APP would like to connect to the following external endpoints > > This app requires Internet access to connect to the LandingAI Agentic Document Extraction service. The app will not function without this access. After clicking **Connect**, the following objects are created in your Snowflake environment. You can change the default values if needed. (`APP_NAME` is replaced with the name of your [app](./ade-sf-app-name).) * **Network rule**: APP\_NAME\_EGRESS\_NETWORK\_RULE * **Location**: APP\_NAME\_APP\_DATA.CONFIGURATION * **External access integration**: APP\_NAME\_EGRESS\_EXTERNAL\_ACCESS For more information about external network access, see the [Snowflake Documentation](https://docs.snowflake.com/en/developer-guide/external-network-access/external-network-access-overview). 10. After enabling egress access, [enter your API key](#enter-api-key). ## Enter API Key To parse documents or run extraction, you must enter your API key in the Agentic Document Extraction app in Snowsight. Only one API key can be entered in the app at a time. In case multiple users access the app, the API key is masked in the interface. **In Agentic Document Extraction:** 1. If you haven't already, [create an Agentic Document Extraction account](https://ade.landing.ai/). 2. [Get your API key](https://ade.landing.ai/my/settings/api-key). **In Snowsight:** 1. Go to **Catalog** > **Apps** > **Agentic Document Extraction - App**. 2. Click **Settings** (if the app does not automatically open to this tab). 3. Enter your API key. 4. Click **Add API Key**. Enter API key 5. The app saves the API key, generates procedures for using Agentic Document Extraction, and unlocks usage instructions on the Home page. This might take a few minutes. ## Next Steps After you install the app and enter your API key in the app, you are ready to [parse documents](./ade-sf-parse-cloud) and [extract data](./ade-sf-extract-cloud). ## App Updates The app is automatically updated when a new version is released. Users cannot manually update the app. ## Troubleshooting Tips ### Error: Connect to allow the app to access the LandingAI Agentic Document Extraction service During the installation process, you might get this error: > Connect to allow the app to access the LandingAI Agentic Document Extraction service > > This app requires Internet access to connect to the LandingAI Agentic Document Extraction service. The app will not function without this access. > > There was an error initializing the configuration flow. Close the dialog and try again later. If you get this error message, try selecting a different warehouse from the drop-down menu in the top right corner. # Parse Documents Source: https://docs.landing.ai/ade/ade-sf-parse-cloud Parse documents staged in Snowflake or at public URLs with the api.parse procedure. ## Prerequisites **In Agentic Document Extraction:** 1. If you haven't already, [create an Agentic Document Extraction account](https://ade.landing.ai/). 2. [Get your API key](https://ade.landing.ai/my/settings/api-key). **In Snowsight:** 1. [Install the app](./ade-sf-install). 2. [Enter your API key in the app](./ade-sf-install#enter-api-key). 3. If you want to parse documents staged in Snowflake, [grant the app access to the stages that have the files you want to parse](./ade-sf-grant-access-to-stages). ## Set Up the Session Before running a parse or extract procedure, run the command below to set your session to use the Agentic Document Extraction application and procedures. Replace this placeholder with the [name of your instance](./ade-sf-app-name) of Agentic Document Extraction: `APP_NAME`. ```sql theme={null} USE "APP_NAME"; ``` ## Parse To parse documents, use the `api.parse` procedure. The `api.parse` procedure sends a document from a Snowflake stage or publicly accessible URL to the LandingAI-hosted Agentic Document Extraction service, and saves the parsed content to an output table (defaults to `db.parse_output`). The `api.parse` procedure runs the [ADE Parse Jobs API](./ade-parse-async). ## Optional Parameters The `api.parse` procedure supports these optional parameters: * **`model`**: Specify the model version to use for parsing. For full details on parsing models, go to [Document Pre-Trained Transformers (Parsing Models)](./ade-parse-models). * **`split`**: Specify how to [split](./parse#set-up-splits-for-parsing) the document. * **`output_table`**: Specify a [custom output table name](#specify-a-custom-output-table) instead of the default `parse_output`. ## Specify a Custom Output Table You can specify a custom table name for storing parse results instead of using the default `parse_output`: ```sql theme={null} CALL api.parse( file_path => 'https://ade.landing.ai/pdfs/invoice_1.pdf', output_table => 'my_custom_results' ); SELECT * FROM db.my_custom_results; ``` The procedure automatically creates the table (if it doesn't exist) with the following schema: * DOC\_ID * SOURCE\_URL * FILENAME * PAGE\_COUNT * MODEL\_VERSION * PARSED\_AT * STATUS\_CODE * MARKDOWN * CHUNKS * SPLITS * GROUNDING * METADATA * ERROR ### Example with Optional Parameters ```sql theme={null} CALL api.parse( file_path => 'https://ade.landing.ai/pdfs/invoice_1.pdf', model => 'dpt-2-latest', output_table => 'invoice_results' ); SELECT * FROM db.invoice_results; ``` ## Parse Return Object The `api.parse` procedure returns an OBJECT with the following fields: * **`message`**: Success or error message * **`output_table`**: Name of the table where results were saved (such as "db.parse\_output") * **`doc_id`**: Unique document identifier for the parsed document * **`status_code`**: HTTP status code for the request This return object is useful when chaining parse and extract operations together. You can capture the result into a variable and pass it to `api.extract`. Example of capturing the return object: ```sql theme={null} DECLARE result OBJECT; BEGIN CALL api.parse( 'https://ade.landing.ai/pdfs/invoice_1.pdf' ) INTO :result; RETURN result; END; ``` ## Use build\_scoped\_file\_url for Staged Files You can use the `build_scoped_file_url()` function to reference files in Snowflake stages. ```sql theme={null} CALL api.parse( file_path => build_scoped_file_url('@your_db.your_schema.your_stage', '/sample_image.png') ); SELECT * FROM db.parse_output; ``` ## Sample Scenarios This section provides examples of how to run the `api.parse` procedure in different scenarios. * [Parse a File at a Publicly Accessible URL](#parse-a-file-at-a-publicly-accessible-url) * [Parse a Staged File](#parse-a-staged-file) * [Parse Multiple Staged Files](#parse-multiple-staged-files) ### Parse a File at a Publicly Accessible URL Run the command below to parse a single file at a publicly accessible URL. We've provided a sample file to help you get started. Replace this placeholder with your information: `APP_NAME`. ```sql theme={null} USE "APP_NAME"; CALL api.parse( 'https://ade.landing.ai/pdfs/invoice_1.pdf' ); SELECT * FROM db.parse_output; ``` ### Parse a Staged File Before parsing staged files, you must grant the application access to your stage. For more information, go to [Grant Access to Stages](./ade-sf-grant-access-to-stages). Run the command below to parse a single file in a Snowflake stage. Replace these placeholders with your information: `APP_NAME`, `your_db`, `your_schema`, `your_stage`, and `path/to/file.pdf`. ```sql theme={null} USE "APP_NAME"; CALL api.parse( '@your_db.your_schema.your_stage/path/to/file.pdf' ); SELECT * FROM db.parse_output; ``` #### Sample Script: Parse a Staged File Let's say you have the following setup: * **APP\_NAME**: AGENTIC\_DOCUMENT\_EXTRACTION\_\_APP * **Database**: DEMO\_DB * **Schema**: DEMO\_SCHEMA * **Stage**: DEMO\_STAGE * **PDF**: statement-jane-harper.pdf First, grant the application access to the stage: ```sql theme={null} GRANT USAGE ON DATABASE DEMO_DB TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; GRANT USAGE ON SCHEMA DEMO_DB.DEMO_SCHEMA TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; GRANT READ, WRITE ON STAGE DEMO_DB.DEMO_SCHEMA.DEMO_STAGE TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; ``` Then, parse the PDF: ```sql theme={null} USE "AGENTIC_DOCUMENT_EXTRACTION__APP"; CALL api.parse( '@DEMO_DB.DEMO_SCHEMA.DEMO_STAGE/statement-jane-harper.pdf' ); SELECT * FROM db.parse_output; ``` ### Parse Multiple Staged Files Before parsing staged files, you must grant the application access to your stage. For more information, go to [Grant Access to Stages](./ade-sf-grant-access-to-stages). One way to process multiple documents is to call the `api.parse` procedure for each file. The procedure saves the results to the `db.parse_output` table, where you can query all parsed documents. Here's an example of processing multiple files and then viewing the results. Replace these placeholders with your information: `APP_NAME`, `your_db`, `your_schema`, and `your_stage`. ```sql theme={null} USE "APP_NAME"; -- Parse multiple files CALL api.parse('@your_db.your_schema.your_stage/file1.pdf'); CALL api.parse('@your_db.your_schema.your_stage/file2.pdf'); CALL api.parse('@your_db.your_schema.your_stage/file3.pdf'); -- View all parsed results SELECT * FROM db.parse_output; ``` #### Sample Script: Parse Multiple Staged Files Let's say you have the following setup: * **APP\_NAME**: AGENTIC\_DOCUMENT\_EXTRACTION\_\_APP * **Database**: DEMO\_DB * **Schema**: DEMO\_SCHEMA * **Stage**: DEMO\_STAGE (contains PDFs and images) The DEMO\_STAGE contains the following files: * statement-george-mathew\.png * statement-jane-harper.pdf * statement-john-doe.png * statement-john-smith.png First, grant the application access to the stage: ```sql theme={null} GRANT USAGE ON DATABASE DEMO_DB TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; GRANT USAGE ON SCHEMA DEMO_DB.DEMO_SCHEMA TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; GRANT READ, WRITE ON STAGE DEMO_DB.DEMO_SCHEMA.DEMO_STAGE TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; ``` Then, parse the documents: ```sql theme={null} USE "AGENTIC_DOCUMENT_EXTRACTION__APP"; -- Parse each document CALL api.parse('@DEMO_DB.DEMO_SCHEMA.DEMO_STAGE/statement-george-mathew.png'); CALL api.parse('@DEMO_DB.DEMO_SCHEMA.DEMO_STAGE/statement-jane-harper.pdf'); CALL api.parse('@DEMO_DB.DEMO_SCHEMA.DEMO_STAGE/statement-john-doe.png'); CALL api.parse('@DEMO_DB.DEMO_SCHEMA.DEMO_STAGE/statement-john-smith.png'); -- View all parsed results SELECT * FROM db.parse_output; ``` ## Remove Parse Output Tables Each time you run the `api.parse` procedure, the results are saved to an output table (defaults to `db.parse_output`). Over time, you may want to remove these tables to start fresh or clean up old results. This is especially useful if you have specified [custom output table names](#specify-a-custom-output-table) and accumulated multiple tables. To remove parse output tables: 1. Go to **Catalog** > **Apps** > **Agentic Document Extraction - App**. 2. Click **Settings**. 3. Navigate to **SQL Execution**. 4. Enter the following SQL command in the SQL field: ```sql theme={null} DROP TABLE IF EXISTS APP_NAME.DB.TABLE_NAME; ``` 5. Replace these placeholders with your information: * `APP_NAME`: The [name of your app instance](./ade-sf-app-name) * `DB`: The app's database name (use `db`) * `TABLE_NAME`: The name of the table you want to remove (such as `parse_output` or your custom table name) 6. Click **Run Query**. # Extract Fields from Parsed Output Source: https://docs.landing.ai/ade/ade-sf-extract-cloud Extract key-value pairs from parsed Markdown in Snowflake with the api.extract procedure. To extract fields from documents, first parse a document with the [api.parse](./ade-sf-parse-cloud) procedure. Then use the `api.extract` procedure to extract key-value pairs from the Markdown returned by the `api.parse` procedure. ## Prerequisites Before you can extract fields, you must parse a document. For more information, go to [Parse Documents](./ade-sf-parse-cloud). ## Set Up the Session Before running a parse or extract procedure, run the command below to set your session to use the Agentic Document Extraction application and procedures. Replace this placeholder with the [name of your instance](./ade-sf-app-name) of Agentic Document Extraction: `APP_NAME`. ```sql theme={null} USE "APP_NAME"; ``` ## Extract To extract fields from parsed documents, use the `api.extract` procedure. The `api.extract` procedure sends the Markdown and a JSON schema to the LandingAI-hosted Agentic Document Extraction service, and saves the extracted data to an output table (defaults to `db.extract_output`). The `api.extract` procedure runs the [ADE Extract API](https://docs.landing.ai/api-reference/tools/ade-extract). ## Required Inputs The `api.extract` procedure requires: * **Markdown content** from `api.parse` * **JSON schema** that defines which fields to extract and their expected format. For more information, go to [Create a JSON Schema for Field Extraction](https://docs.landing.ai/ade/ade-extract-schema-json). The procedure accepts these inputs using different methods. For details, go to [Methods for Passing the Markdown](#methods-for-passing-the-markdown) and [Methods for Passing the JSON Schema](#methods-for-passing-the-json-schema). ## Optional Parameters The `api.extract` procedure supports these optional parameters: * **`doc_id`**: Document ID from parse output; provide this to link the extraction results to the original parsed document * **`output_table`**: Specify a custom output table name instead of the default `extract_output` * **`model`**: Specify the model version to use for extraction. For full details on extraction models, go to [Extraction Model Versions](./ade-extract-models). ## Extract Return Object The `api.extract` procedure returns an OBJECT with the following fields: * **`message`**: Success or error message * **`output_table`**: Name of the table where results were saved (such as "db.extract\_output"). For the table schema, go to [Extract Output Table Schema](#extract-output-table-schema). * **`doc_id`**: Document ID from the parse output (for linking results) * **`extraction_id`**: Unique extraction job identifier * **`status_code`**: HTTP status code for the request This return object is useful when chaining parse and extract operations together, and for tracking extraction jobs and debugging. ## Extract Output Table Schema The extraction results are stored in the table specified by `output_table` in the [return object](#extract-return-object). By default, this is `db.extract_output`. The table has the following schema: * **DOC\_ID**: Document ID from parse output; you can use this to link extraction results to the original parsed document in `parse_output` * **EXTRACTION\_JOB\_ID**: Unique extraction job identifier * **SOURCE\_MARKDOWN**: First 10,000 characters of input Markdown (for reference) * **MODEL\_VERSION**: Model version used for extraction * **EXTRACTED\_AT**: Timestamp when extraction completed * **STATUS\_CODE**: HTTP status code (200 for success) * **EXTRACTION**: VARIANT containing the extracted data matching your schema * **EXTRACTION\_METADATA**: VARIANT with extraction metadata * **METADATA**: VARIANT with job metadata * **ERROR**: VARIANT containing error information (if extraction failed) Example query to access nested extraction data: ```sql theme={null} SELECT DOC_ID, EXTRACTION:field_name::STRING AS field_value, EXTRACTION:nested:field::NUMBER AS nested_value FROM db.extract_output WHERE STATUS_CODE = 200; ``` ## Methods for Passing the Markdown You can pass the Markdown content to `api.extract` using two methods: * [Pass the Parse Result Object Directly](#pass-the-parse-result-object-directly) * [Pass Markdown Explicitly](#pass-markdown-explicitly) ### Pass the Parse Result Object Directly You can pass the result object from `api.parse` directly to `api.extract`. This is the most streamlined approach for chaining parse and extract operations. You can combine this with any method for passing the JSON schema. Use this method when you: * Want to chain parse and extract in a single script block * Need to avoid querying the parse output table * Want to automatically link parse and extract results **Procedure Signature** ```sql theme={null} PROCEDURE api.extract( parse_result OBJECT, schema STRING, output_table STRING DEFAULT NULL, model STRING DEFAULT NULL ) ``` #### Example The procedure automatically: * Extracts the `doc_id` from the parse result * Retrieves the Markdown from the parse output table * Links the extraction result with the parse result via `doc_id` ```sql theme={null} DECLARE parse_result OBJECT; extract_result OBJECT; BEGIN -- Parse the document CALL api.parse( 'https://ade.landing.ai/pdfs/invoice_1.pdf' ) INTO :parse_result; -- Extract using the parse result directly CALL api.extract( :parse_result, 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json' ) INTO :extract_result; RETURN extract_result; END; ``` ### Pass Markdown Explicitly You can query the Markdown directly from the `parse_output` table and pass it as a parameter. Use this method when you've already parsed documents and want to extract from them separately. You can combine this with any method for passing the JSON schema. **Procedure Signature** ```sql theme={null} PROCEDURE api.extract( markdown STRING, schema STRING, doc_id STRING DEFAULT NULL, output_table STRING DEFAULT NULL, model STRING DEFAULT NULL ) ``` #### Example ```sql theme={null} CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE doc_id = 'your_doc_id'), schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => 'your_doc_id' ); SELECT * FROM db.extract_output; ``` ## Methods for Passing the JSON Schema You can pass the JSON schema to `api.extract` using multiple methods: * [Include the JSON Schema Inline](#include-the-json-schema-inline) * [Use a Staged Schema File](#use-a-staged-schema-file) * [Pass a URL to an Externally Hosted JSON Schema (Demo Files Only)](#pass-a-url-to-an-externally-hosted-json-schema-demo-files-only) ### Include the JSON Schema Inline Provide the schema as an inline JSON string. You can combine this with any method for passing the Markdown. Use this method when you: * Have a simple schema specific to one query * Want to keep all logic contained in a single script * Prototype or test schema definitions #### Example ```sql theme={null} CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE doc_id = 'your_doc_id'), schema => '{ "type": "object", "properties": { "title": { "type": "string", "title": "Document Title", "description": "The main title of the document." }, "content": { "type": "string", "title": "Main Content", "description": "The primary content or text from the document." } }, "required": ["title", "content"] }', doc_id => 'your_doc_id' ); SELECT * FROM db.extract_output; ``` ### Use a Staged Schema File Use `build_scoped_file_url()` to reference a schema file in a Snowflake stage. You can combine this with any method for passing the Markdown. Use this method when you: * Store your schema files in Snowflake stages * Want to version control schemas alongside your data * Need to reference schemas from internal stage locations #### Example ```sql theme={null} CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE doc_id = 'your_doc_id'), schema => build_scoped_file_url('@your_db.your_schema.your_stage', '/simple_schema.json'), doc_id => 'your_doc_id' ); SELECT * FROM db.extract_output; ``` ### Pass a URL to an Externally Hosted JSON Schema (Demo Files Only) This method only works with schema files hosted at `https://ade.landing.ai`, which were granted access during app installation. To use schemas from other URLs or locations, use another method for passing the JSON schema. Provide the schema as a URL parameter. You can combine this with any method for passing the Markdown. #### Example ```sql theme={null} CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE doc_id = 'your_doc_id'), schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => 'your_doc_id' ); SELECT * FROM db.extract_output; ``` ## Batch Processing with EXECUTE IMMEDIATE For processing multiple documents at once, you can use Snowflake's scripting capabilities to loop through parsed documents and extract data from each. This approach is useful when you have many documents already parsed and want to extract structured data from all of them in one operation. ```sql theme={null} EXECUTE IMMEDIATE $$ DECLARE res RESULTSET DEFAULT ( SELECT MARKDOWN, DOC_ID FROM db.parse_output WHERE STATUS_CODE = 200 ); cur CURSOR FOR res; BEGIN FOR record IN cur DO LET markdown STRING := record.MARKDOWN; LET doc_id STRING := record.DOC_ID; CALL api.extract( markdown => :markdown, schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => :doc_id, output_table => 'batch_extract_results' ); END FOR; RETURN 'Processing complete'; END; $$; -- View all extracted results SELECT * FROM db.batch_extract_results; ``` ## Sample Scenarios This section provides examples of how to run the `api.extract` procedure in different scenarios. * [Parse and Extract Data from Files at Publicly Accessible URLs](#parse-and-extract-data-from-files-at-publicly-accessible-urls) * [Parse and Extract Data from a Staged File](#parse-and-extract-data-from-a-staged-file) * [Parse and Extract Data from All Files in a Stage](#parse-and-extract-data-from-all-files-in-a-stage) ### Parse and Extract Data from Files at Publicly Accessible URLs Run the command below to parse multiple files at publicly accessible URLs, and then extract data from the parsed output. We've provided the sample files to help you get started. This example uses an externally hosted JSON schema at `https://ade.landing.ai`, which is only available for demo purposes. For production use, use an [inline schema](#include-the-json-schema-inline) or a [staged schema file](#use-a-staged-schema-file). Replace this placeholder with your information: `APP_NAME`. ```sql theme={null} USE "APP_NAME"; -- Step 1: Parse invoice files CALL api.parse('https://ade.landing.ai/pdfs/invoice_1.pdf'); CALL api.parse('https://ade.landing.ai/pdfs/invoice_2.pdf'); CALL api.parse('https://ade.landing.ai/pdfs/invoice_3.pdf'); CALL api.parse('https://ade.landing.ai/pdfs/invoice_4.pdf'); -- Step 2: Extract structured data from each parsed invoice CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_1.pdf'), schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => (SELECT DOC_ID FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_1.pdf') ); CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_2.pdf'), schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => (SELECT DOC_ID FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_2.pdf') ); CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_3.pdf'), schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => (SELECT DOC_ID FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_3.pdf') ); CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_4.pdf'), schema => 'https://ade.landing.ai/pdfs/InvoiceExtractionSchema.json', doc_id => (SELECT DOC_ID FROM db.parse_output WHERE SOURCE_URL = 'https://ade.landing.ai/pdfs/invoice_4.pdf') ); -- Step 3: View extracted data SELECT SPLIT_PART(p.SOURCE_URL, '/', -1) AS filename, e.EXTRACTION:invoice_info:invoice_date::STRING AS invoice_date, e.EXTRACTION:company_info:supplier_name::STRING AS supplier_name, e.EXTRACTION:line_items[0]:description::STRING AS first_line_item_description, e.EXTRACTION:totals_summary:total_due::FLOAT AS total_due FROM db.extract_output e JOIN db.parse_output p ON e.DOC_ID = p.DOC_ID ORDER BY filename; ``` ### Parse and Extract Data from a Staged File Before parsing staged files, you must grant the application access to your stage. For more information, go to [Grant Access to Stages](./ade-sf-grant-access-to-stages). Run the command below to parse a single file in a Snowflake stage, and then extract data from the parsed output. Replace these placeholders with your information: `APP_NAME`, `your_db`, `your_schema`, `your_stage`, `path/to/file.pdf`, and the JSON schema fields. ```sql theme={null} USE "APP_NAME"; -- Step 1: Parse the staged file CALL api.parse( '@your_db.your_schema.your_stage/path/to/file.pdf' ); -- Step 2: Extract structured data using inline schema CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE FILENAME = 'file.pdf'), schema => '{ "type": "object", "properties": { "field1": {"type": "string"}, "field2": {"type": "string"} }, "required": ["field1", "field2"] }', doc_id => (SELECT DOC_ID FROM db.parse_output WHERE FILENAME = 'file.pdf') ); -- Step 3: View extracted fields SELECT EXTRACTION:field1::STRING AS field1, EXTRACTION:field2::STRING AS field2 FROM db.extract_output; ``` #### Sample Script: Parse and Extract a Staged File Let's say you have the following setup: * **APP\_NAME**: AGENTIC\_DOCUMENT\_EXTRACTION\_\_APP * **Database**: DEMO\_DB * **Schema**: DEMO\_SCHEMA * **Stage**: DEMO\_STAGE * **PDF**: statement-jane-harper.pdf You want to extract these fields from the file: * Employee Name * Employee Social Security Number First, grant the application access to the stage: ```sql theme={null} GRANT USAGE ON DATABASE DEMO_DB TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; GRANT USAGE ON SCHEMA DEMO_DB.DEMO_SCHEMA TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; GRANT READ, WRITE ON STAGE DEMO_DB.DEMO_SCHEMA.DEMO_STAGE TO APPLICATION "AGENTIC_DOCUMENT_EXTRACTION__APP"; ``` Then, parse the file and extract fields from `statement-jane-harper.pdf`: ```sql theme={null} USE "AGENTIC_DOCUMENT_EXTRACTION__APP"; -- Step 1: Parse the staged file CALL api.parse( '@DEMO_DB.DEMO_SCHEMA.DEMO_STAGE/statement-jane-harper.pdf' ); -- Step 2: Extract structured data using inline schema CALL api.extract( markdown => (SELECT MARKDOWN FROM db.parse_output WHERE FILENAME = 'statement-jane-harper.pdf'), schema => '{ "title": "Employee Payroll Field Extraction Schema", "description": "Schema for extracting key employee payroll fields.", "type": "object", "properties": { "employee_name": { "title": "Employee Name", "description": "The full name of the employee as it appears on the payroll document.", "type": "string" }, "employee_ssn": { "title": "Employee Social Security Number", "description": "The Social Security Number of the employee, formatted as XXX-XX-XXXX.", "type": "string" } } }', doc_id => (SELECT DOC_ID FROM db.parse_output WHERE FILENAME = 'statement-jane-harper.pdf') ); -- Step 3: View extracted fields SELECT EXTRACTION:employee_name::STRING AS employee_name, EXTRACTION:employee_ssn::STRING AS employee_ssn FROM db.extract_output; ``` ### Parse and Extract Data from All Files in a Stage Before parsing staged files, you must grant the application access to your stage. For more information, go to [Grant Access to Stages](./ade-sf-grant-access-to-stages). Run the script below to iterate through all files in a Snowflake stage, parse each file, and extract data from the parsed output. This example uses Snowflake's CURSOR functionality to filter and process multiple files from a stage. Replace these placeholders with your information: `@your_db.your_schema.your_stage`, filtering criteria, and the JSON schema. ```sql theme={null} -- Example: Parse and extract all PDFs on a stage using some filtering criteria DECLARE file_cursor CURSOR FOR SELECT RELATIVE_PATH FROM DIRECTORY(@your_db.your_schema.your_stage) WHERE SIZE < 1000000 -- Files smaller than 1MB (1,000,000 bytes) AND LOWER(RELATIVE_PATH) LIKE '%your_file_pattern%.pdf' -- Only process PDF files matching your pattern LIMIT 10; current_file_path STRING; full_stage_path STRING; parse_ret OBJECT; extract_ret OBJECT; BEGIN FOR file_record IN file_cursor DO current_file_path := file_record.RELATIVE_PATH; full_stage_path := '@"your_db"."your_schema"."your_stage"/' || :current_file_path; -- Parse document using direct stage path CALL api.parse(file_path => :full_stage_path) INTO :parse_ret; -- Extract using the parse return object CALL api.extract( parse_result => :parse_ret, schema => '{"type": "object", "properties": {...}}' -- Replace with your JSON schema ) INTO :extract_ret; END FOR; END; -- View parsed results SELECT * FROM db.parse_output; -- View extracted results SELECT * FROM db.extract_output; ``` # Grant Agentic Document Extraction Access to Stages Source: https://docs.landing.ai/ade/ade-sf-grant-access-to-stages Grant the ADE Snowflake app access to the stages that hold the files you want to parse or extract. To [parse](./ade-sf-parse-cloud) or [extract data](./ade-sf-extract-cloud) from files in Snowflake stages, grant Agentic Document Extraction access to those stages. To grant Agentic Document Extraction access to a stage: 1. Make a note of the **database**, **schema**, and **stage** that you want to grant access to. 2. Open [Snowsight](https://app.snowflake.com). 3. Create a new worksheet and run the following SQL commands. Replace these placeholders with your information: `YOUR_DB`, `YOUR_SCHEMA`, `YOUR_STAGE`, and `APP_NAME`. (To locate your app name, go to [App Name](./ade-sf-app-name)). ```sql theme={null} GRANT USAGE ON DATABASE YOUR_DB TO APPLICATION "APP_NAME"; GRANT USAGE ON SCHEMA YOUR_DB.YOUR_SCHEMA TO APPLICATION "APP_NAME"; GRANT READ, WRITE ON STAGE YOUR_DB.YOUR_SCHEMA.YOUR_STAGE TO APPLICATION "APP_NAME"; ``` # App Name Source: https://docs.landing.ai/ade/ade-sf-app-name Find your Snowflake app name for use in SQL commands that manage the ADE app. Some SQL commands for managing Agentic Document Extraction require the name of your instance of the app. In the SQL commands throughout this documentation, `APP_NAME` is used as a placeholder for your app name. The default app name is `AGENTIC_DOCUMENT_EXTRACTION__APP`. You need your app name to: * [Parse documents](./ade-sf-parse-cloud) * [Extract fields from parsed output](./ade-sf-extract-cloud) * [Grant app access to stages](./ade-sf-grant-access-to-stages) ## App Name in Sample Scripts Sample scripts in the app interface automatically use your app name. When you copy these scripts, you do not need to change the app name. ## Locate the Name of Your App You can get the name of your instance of Agentic Document Extraction in Snowsight: 1. Open [Snowsight](https://app.snowflake.com). 2. Go to **Catalog** > **Apps** > **Agentic Document Extraction - App**. 3. The app opens to the **Home** page. 4. Identify the app name in the first line of the scripts. For example, in the screenshot below, the name of the app is `AGENTIC_DOCUMENT_EXTRACTION__APP`. App Name # LandingLens and LandingEdge Documentation Source: https://docs.landing.ai/landinglens-landingedge Find LandingLens and LandingEdge documentation, now hosted on a dedicated site. LandingLens and LandingEdge documentation has moved to this dedicated site: [https://landinglens.docs.landing.ai/](https://landinglens.docs.landing.ai/). Build and deploy computer vision models for object detection, classification, segmentation, and anomaly detection. Use the LandingEdge app or Docker to run LandingLens models on-premises for real-time visual inspection. # Legacy ADE Features Source: https://docs.landing.ai/ade/ade-overview-legacy Review deprecated ADE features: the legacy endpoint, the agentic-doc library, and the DPT-1 and DPT-2 mini models. The `v1/tools/agentic-document-analysis` endpoint, the `agentic-doc` Python library, and the DPT-1 and `dpt-2-mini` parsing models are deprecated. Requests that use the legacy endpoint or a deprecated model return an error. ## Legacy ADE Endpoint The legacy Agentic Document Extraction endpoint (`v1/tools/agentic-document-analysis`) was the original endpoint for document processing. It combined document parsing and field extraction into a single API call. This endpoint has been replaced with separate, function-specific APIs: * **[ADE Parse API](./parse)**: Converts documents into structured Markdown with hierarchical JSON * **[ADE Split API](./ade-split)**: Classifies and separates documents into sub-documents * **[ADE Extract API](./ade-extract)**: Extracts specific data fields from parsed documents ## Legacy agentic-doc Library The [agentic-doc](https://github.com/landing-ai/ade-cli/tree/legacy) Python library is deprecated. Use the [ade-python](./ade-python) library for all new projects. ## Deprecated DPT-1 Parsing Model DPT-1 was the original Document Pre-Trained Transformer (DPT) model for Agentic Document Extraction. It powered basic document parsing and was the only model available when Agentic Document Extraction launched. DPT-1 has been replaced by DPT-2, which builds on DPT-1 and adds support for complex tables, additional chunk types (such as logos, barcodes, and signatures), and improved layout detection. DPT-1 is deprecated. To migrate, update the `model` parameter in your API calls or library code from `dpt-1` to `dpt-2`. For more information, go to [Document Pre-Trained Transformers (Parsing Models)](./ade-parse-models). ## Deprecated DPT-2 Mini Parsing Model The `dpt-2-mini` model was a lightweight variant of DPT-2. It is deprecated. To migrate, update the `model` parameter in your API calls or library code from `dpt-2-mini` to `dpt-2`. # ADE Parse Source: https://docs.landing.ai/api-reference/tools/ade-parse Parse a document or spreadsheet. This endpoint parses documents (PDF, images) and spreadsheets (XLSX, CSV) into structured Markdown, chunks, and metadata. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/parse openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/parse: post: tags: - Tools summary: ADE Parse description: |- Parse a document or spreadsheet. This endpoint parses documents (PDF, images) and spreadsheets (XLSX, CSV) into structured Markdown, chunks, and metadata. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse`. operationId: tool_ade_parse_v1_ade_parse_post requestBody: content: multipart/form-data: schema: $ref: '#/components/schemas/ParseRequestWithEncryptedPassword' required: true responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/ParseResponse' '206': description: There were some pages that failed to be parsed. content: application/json: schema: $ref: '#/components/schemas/ParseResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' '429': description: Rate limit exceeded security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest' # Set the model (optional) - lang: Python label: Python source: >- import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/parse' # Set the model (optional) data = { 'model': 'dpt-2-latest' } # Upload a document document = open('document.pdf', 'rb') files = {'document': document} response = requests.post(url, files=files, data=data, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('document', fs.createReadStream('document.pdf')); // Set the model (optional) form.append('model', 'dpt-2-latest'); axios.post('https://api.va.landing.ai/v1/ade/parse', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ParseRequestWithEncryptedPassword: properties: model: anyOf: - type: string - type: 'null' title: Model description: The version of the model to use for parsing. document: anyOf: - type: string format: binary - type: 'null' title: Document description: >- A file to be parsed. The file can be a PDF or an image. See the list of supported file types here: https://docs.landing.ai/ade/ade-file-types. Either this parameter or the `document_url` parameter must be provided. document_url: anyOf: - type: string - type: 'null' title: Document Url description: >- The URL to the file to be parsed. The file can be a PDF or an image. See the list of supported file types here: https://docs.landing.ai/ade/ade-file-types. Either this parameter or the `document` parameter must be provided. split: anyOf: - $ref: '#/components/schemas/SplitType' - type: 'null' description: >- If you want to split documents into smaller sections, include the split parameter. Set the parameter to page to split documents at the page level. The splits object in the API output will contain a set of data for each page. password: anyOf: - type: string - type: 'null' title: Password description: >- Password for encrypted document files. If the document is password-protected, provide the password to decrypt and process the document. Ignored for unencrypted documents. custom_prompts: anyOf: - type: string contentMediaType: application/json contentSchema: $ref: '#/components/schemas/CustomPrompts' - type: 'null' title: Custom Prompts description: >- Optional JSON string mapping chunk types to custom parsing prompts. Only the `figure` key is supported, for example '{"figure":"Describe axis labels in detail."}'. type: object title: ParseRequestWithEncryptedPassword ParseResponse: properties: markdown: type: string title: Markdown chunks: items: $ref: '#/components/schemas/ParseChunk' type: array title: Chunks splits: items: $ref: '#/components/schemas/ParseSplit' type: array title: Splits grounding: additionalProperties: anyOf: - $ref: '#/components/schemas/ParseResponseGrounding' - $ref: '#/components/schemas/ParseResponseTableCellGrounding' type: object title: Grounding metadata: $ref: '#/components/schemas/ParseMetadata' type: object required: - markdown - chunks - splits - metadata title: ParseResponse HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError SplitType: type: string enum: - page const: page title: SplitType ParseChunk: properties: markdown: type: string title: Markdown type: type: string title: Type id: type: string title: Id grounding: $ref: '#/components/schemas/ParseGrounding' type: object required: - markdown - type - id - grounding title: ParseChunk ParseSplit: properties: class: type: string title: Class identifier: type: string title: Identifier pages: items: type: integer type: array title: Pages markdown: type: string title: Markdown chunks: items: type: string type: array title: Chunks type: object required: - class - identifier - pages - markdown - chunks title: ParseSplit ParseResponseGrounding: properties: box: $ref: '#/components/schemas/ParseGroundingBox' page: type: integer title: Page type: $ref: '#/components/schemas/GroundingType' confidence: anyOf: - type: number - type: 'null' title: Confidence low_confidence_spans: items: $ref: '#/components/schemas/Patch' type: array title: Low Confidence Spans type: object required: - box - page - type title: ParseResponseGrounding ParseResponseTableCellGrounding: properties: box: $ref: '#/components/schemas/ParseGroundingBox' page: type: integer title: Page type: $ref: '#/components/schemas/GroundingType' confidence: anyOf: - type: number - type: 'null' title: Confidence position: anyOf: - $ref: '#/components/schemas/ParseResponseTableCellGroundingPosition' - type: 'null' type: object required: - box - page - type title: ParseResponseTableCellGrounding ParseMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id page_count: type: integer title: Page Count duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id version: anyOf: - type: string - type: 'null' title: Version failed_pages: items: type: integer type: array title: Failed Pages type: object required: - filename - org_id - page_count - duration_ms - credit_usage - job_id - version title: ParseMetadata ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError ParseGrounding: properties: box: $ref: '#/components/schemas/ParseGroundingBox' page: type: integer title: Page type: object required: - box - page title: ParseGrounding ParseGroundingBox: properties: left: type: number title: Left top: type: number title: Top right: type: number title: Right bottom: type: number title: Bottom type: object required: - left - top - right - bottom title: ParseGroundingBox GroundingType: type: string enum: - chunkLogo - chunkCard - chunkAttestation - chunkScanCode - chunkForm - chunkTable - chunkFigure - chunkText - chunkMarginalia - chunkTitle - chunkPageHeader - chunkPageFooter - chunkPageNumber - chunkKeyValue - table - tableCell title: GroundingType Patch: properties: text: type: string title: Text span: prefixItems: - type: integer - type: integer type: array maxItems: 2 minItems: 2 title: Span confidence: type: number title: Confidence type: object required: - text - span - confidence title: Patch ParseResponseTableCellGroundingPosition: properties: row: type: integer title: Row col: type: integer title: Col rowspan: type: integer title: Rowspan colspan: type: integer title: Colspan chunk_id: type: string title: Chunk Id type: object required: - row - col - rowspan - colspan - chunk_id title: ParseResponseTableCellGroundingPosition securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Extract Source: https://docs.landing.ai/api-reference/tools/ade-extract Extract structured data from Markdown using a JSON schema. This endpoint processes Markdown content and extracts structured data according to the provided JSON schema. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/extract openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/extract: post: tags: - Tools summary: ADE Extract description: |- Extract structured data from Markdown using a JSON schema. This endpoint processes Markdown content and extracts structured data according to the provided JSON schema. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract`. operationId: tool_ade_extract_v1_ade_extract_post requestBody: content: multipart/form-data: schema: $ref: '#/components/schemas/ExtractRequest' required: true responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/ExtractResponse' '206': description: >- Extraction completed with success but there was a schema validation error. content: application/json: schema: $ref: '#/components/schemas/ExtractResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' '429': description: Rate limit exceeded security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/extract' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'schema={"type": "object", "properties": {"field1": {"type": "string"}, "field2": {"type": "string"}}}' \ -F 'markdown=@markdown.md' \ -F 'model=extract-latest' - lang: Python label: Python source: >- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/extract' # Read the schema file as a string with open('schema.json', 'r') as f: schema_content = f.read() # Prepare files and data files = {'markdown': open('markdown.md', 'rb')} data = { 'schema': schema_content, 'model': 'extract-latest' } # Run extraction response = requests.post(url, files=files, data=data, headers=headers) # Return the results print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdown', fs.createReadStream('markdown.md')); form.append('schema', fs.readFileSync('schema.json', 'utf8')); form.append('model', 'extract-latest'); axios.post('https://api.va.landing.ai/v1/ade/extract', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ExtractRequest: properties: model: anyOf: - type: string - type: 'null' title: Model description: >- The version of the model to use for extraction. Use `extract-latest` to use the latest version. markdown: anyOf: - type: string format: binary - type: string - type: 'null' title: Markdown description: The Markdown file or Markdown content to extract data from. markdown_url: anyOf: - type: string - type: 'null' title: Markdown Url description: The URL to the Markdown file to extract data from. schema: type: string title: Schema description: >- JSON schema for field extraction. This schema determines what key-values pairs are extracted from the Markdown. The schema must be a valid JSON object and will be validated before processing the document. strict: type: boolean title: Strict description: >- If True, reject schemas with unsupported fields (HTTP 422). If False, prune unsupported fields and continue. Only applies to extract versions that support schema validation. default: false type: object required: - schema title: ExtractRequest ExtractResponse: properties: extraction: type: object title: Extraction description: The extracted key-value pairs. extraction_metadata: type: object title: Extraction Metadata description: The extracted key-value pairs and the chunk_reference for each one. metadata: $ref: '#/components/schemas/ExtractMetadata' description: The metadata for the extraction process. type: object required: - extraction - extraction_metadata - metadata title: ExtractResponse HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError ExtractMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id version: anyOf: - type: string - type: 'null' title: Version schema_violation_error: anyOf: - type: string - type: 'null' title: Schema Violation Error description: >- A detailed error message shows why the extracted data does not fully conform to the input schema. Null means the extraction result is consistent with the input schema. fallback_model_version: anyOf: - type: string - type: 'null' title: Fallback Model Version description: >- The extract model that was actually used to extract the data when the initial extraction attempt failed with the requested version. warnings: items: $ref: '#/components/schemas/ExtractWarning' type: array title: Warnings description: >- Structured warnings from the extraction process. Each warning is an instance of ExtractWarning with 'code' (e.g. 'nonconformant_schema') and 'msg' (human-readable description). Present only for extract versions from extract-20260314 and above that support structured warnings. type: object required: - filename - org_id - duration_ms - credit_usage - job_id - version title: ExtractMetadata ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError ExtractWarning: properties: code: $ref: '#/components/schemas/ExtractWarningCode' description: The type of warning, used to translate to a status code downstream msg: type: string title: Msg description: Human-readable description of the warning with more details type: object required: - code - msg title: ExtractWarning ExtractWarningCode: type: string enum: - nonconformant_schema - nonconformant_output title: ExtractWarningCode securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Extract Jobs Source: https://docs.landing.ai/api-reference/tools/ade-extract-jobs Extract structured data asynchronously. This endpoint creates a job that handles the processing for large markdown documents. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/jobs`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/extract/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/extract/jobs: post: tags: - Tools summary: ADE Extract Jobs description: >- Extract structured data asynchronously. This endpoint creates a job that handles the processing for large markdown documents. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/jobs`. operationId: tool_ade_extract_jobs_v1_ade_extract_jobs_post requestBody: required: true content: multipart/form-data: schema: $ref: '#/components/schemas/AsyncExtractRequest' responses: '202': description: Job queued successfully content: application/json: schema: $ref: '#/components/schemas/JobCreationResponse' example: job_id: 12345678-1234-1234-1234-123456789012 '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' '429': description: Rate limit exceeded security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'schema={"type": "object", "properties": {"field1": {"type": "string"}, "field2": {"type": "string"}}}' \ -F 'markdown=@markdown.md' \ -F 'model=extract-latest' - lang: Python label: Python source: >- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/extract/jobs' # Read the schema file as a string with open('schema.json', 'r') as f: schema_content = f.read() # Prepare files and data files = {'markdown': open('markdown.md', 'rb')} data = { 'schema': schema_content, 'model': 'extract-latest' } response = requests.post(url, files=files, data=data, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdown', fs.createReadStream('markdown.md')); form.append('schema', fs.readFileSync('schema.json', 'utf8')); form.append('model', 'extract-latest'); axios.post('https://api.va.landing.ai/v1/ade/extract/jobs', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: AsyncExtractRequest: properties: model: anyOf: - type: string - type: 'null' title: Model description: >- The version of the model to use for extraction. Use `extract-latest` to use the latest version. markdown: anyOf: - type: string format: binary - type: string - type: 'null' title: Markdown description: The Markdown file or Markdown content to extract data from. markdown_url: anyOf: - type: string - type: 'null' title: Markdown Url description: The URL to the Markdown file to extract data from. schema: type: string title: Schema description: >- JSON schema for field extraction. This schema determines what key-values pairs are extracted from the Markdown. The schema must be a valid JSON object and will be validated before processing the document. strict: type: boolean title: Strict description: >- If True, reject schemas with unsupported fields (HTTP 422). If False, prune unsupported fields and continue. Only applies to extract versions that support schema validation. default: false output_save_url: anyOf: - type: string - type: 'null' title: Output Save Url description: >- If zero data retention (ZDR) is enabled, you must enter a URL for the extracted output to be saved to. When ZDR is enabled, the extracted content will not be in the API response. type: object required: - schema title: AsyncExtractRequest description: |- Request model for async extract endpoint. Extends ExtractRequest with output_save_url for ZDR support. JobCreationResponse: properties: job_id: type: string title: Job Id type: object required: - job_id title: JobCreationResponse HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE List Extract Jobs Source: https://docs.landing.ai/api-reference/tools/ade-list-extract-jobs List all async extract jobs associated with your API key. Returns the list of jobs or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/jobs`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json get /v1/ade/extract/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/extract/jobs: get: tags: - Tools summary: ADE List Extract Jobs description: >- List all async extract jobs associated with your API key. Returns the list of jobs or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/jobs`. operationId: tool_ade_list_extract_jobs_v1_ade_extract_jobs_get parameters: - name: page in: query required: false schema: type: integer minimum: 0 description: Page number (0-indexed) default: 0 title: Page description: Page number (0-indexed) - name: pageSize in: query required: false schema: type: integer maximum: 100 minimum: 1 description: Number of items per page default: 10 title: Pagesize description: Number of items per page - name: status in: query required: false schema: anyOf: - enum: - cancelled - completed - failed - pending - processing type: string - type: 'null' description: Filter by job status. title: Status description: Filter by job status. responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/JobsListResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X GET 'https://api.va.landing.ai/v1/ade/extract/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/extract/jobs' response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const url = 'https://api.va.landing.ai/v1/ade/extract/jobs'; axios.get(url, { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: JobsListResponse: properties: jobs: items: $ref: '#/components/schemas/JobSummary' type: array title: Jobs org_id: anyOf: - type: string - type: 'null' title: Org Id has_more: type: boolean title: Has More default: false type: object required: - jobs title: JobsListResponse description: Response for listing jobs. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError JobSummary: properties: job_id: type: string title: Job Id status: type: string title: Status received_at: type: integer title: Received At created_at: type: integer title: Created At description: >- Unix timestamp (seconds) for when the job was created. Mirrors received_at; exposed so clients have an explicit creation time. default: 0 progress: type: number maximum: 1 minimum: 0 title: Progress description: Job completion as a decimal from 0 (not started) to 1 (complete). failure_reason: anyOf: - type: string - type: 'null' title: Failure Reason type: object required: - job_id - status - received_at - progress title: JobSummary description: Summary of a job for listing. ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Get Extract Jobs Source: https://docs.landing.ai/api-reference/tools/ade-get-extract-jobs Get the status for an async extract job. Returns the job status or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/jobs/{job_id}`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json get /v1/ade/extract/jobs/{job_id} openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/extract/jobs/{job_id}: get: tags: - Tools summary: ADE Get Extract Jobs description: |- Get the status for an async extract job. Returns the job status or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/jobs/{job_id}`. operationId: tool_ade_get_extract_jobs_v1_ade_extract_jobs__job_id__get parameters: - name: job_id in: path required: true schema: type: string title: Job Id responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/ExtractJobStatusResponse' '206': description: >- Extraction completed with success but there was a schema validation error. content: application/json: schema: $ref: '#/components/schemas/ExtractJobStatusResponse' '404': description: Job ID not found '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: >- curl -X GET 'https://api.va.landing.ai/v1/ade/extract/jobs/{job_id}' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = f'https://api.va.landing.ai/v1/ade/extract/jobs/{job_id}' response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const url = `https://api.va.landing.ai/v1/ade/extract/jobs/{jobId}`; axios.get(url, { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ExtractJobStatusResponse: properties: job_id: type: string title: Job Id description: A unique identifier for this extract job. status: type: string title: Status description: >- The current state of the job: `pending`, `processing`, `completed`, `failed`, or `cancelled`. received_at: type: integer title: Received At description: Unix timestamp (in seconds) for when the job was received. created_at: type: integer title: Created At description: Unix timestamp (in seconds) for when the job was created. default: 0 progress: type: number maximum: 1 minimum: 0 title: Progress description: Job completion. Either 0.0 (not yet complete) or 1.0 (complete). org_id: anyOf: - type: string - type: 'null' title: Org Id description: Organization ID. version: anyOf: - type: string - type: 'null' title: Version description: The exact model snapshot used for the extraction. data: anyOf: - $ref: '#/components/schemas/ExtractResponse' - type: 'null' description: >- The extraction results, returned here when the job is complete and you did not set an `output_save_url`. Large results are returned through `output_url` instead. output_url: anyOf: - type: string - type: 'null' title: Output Url description: >- A URL to download the extraction results. Provided when the job is complete and either you set an `output_save_url` or the result is larger than 1 MB. URLs for large results are temporary and expire one hour after you request the job. metadata: anyOf: - $ref: '#/components/schemas/ExtractMetadata' - type: 'null' description: >- Information about the extraction, such as the model version, duration, credit usage, and any schema warnings. failure_reason: anyOf: - type: string - type: 'null' title: Failure Reason description: If the job failed, a message describing what went wrong. type: object required: - job_id - status - received_at - progress title: ExtractJobStatusResponse description: The status of an extract job, plus the results once it completes. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError ExtractResponse: properties: extraction: type: object title: Extraction description: The extracted key-value pairs. extraction_metadata: type: object title: Extraction Metadata description: The extracted key-value pairs and the chunk_reference for each one. metadata: $ref: '#/components/schemas/ExtractMetadata' description: The metadata for the extraction process. type: object required: - extraction - extraction_metadata - metadata title: ExtractResponse ExtractMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id version: anyOf: - type: string - type: 'null' title: Version schema_violation_error: anyOf: - type: string - type: 'null' title: Schema Violation Error description: >- A detailed error message shows why the extracted data does not fully conform to the input schema. Null means the extraction result is consistent with the input schema. fallback_model_version: anyOf: - type: string - type: 'null' title: Fallback Model Version description: >- The extract model that was actually used to extract the data when the initial extraction attempt failed with the requested version. warnings: items: $ref: '#/components/schemas/ExtractWarning' type: array title: Warnings description: >- Structured warnings from the extraction process. Each warning is an instance of ExtractWarning with 'code' (e.g. 'nonconformant_schema') and 'msg' (human-readable description). Present only for extract versions from extract-20260314 and above that support structured warnings. type: object required: - filename - org_id - duration_ms - credit_usage - job_id - version title: ExtractMetadata ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError ExtractWarning: properties: code: $ref: '#/components/schemas/ExtractWarningCode' description: The type of warning, used to translate to a status code downstream msg: type: string title: Msg description: Human-readable description of the warning with more details type: object required: - code - msg title: ExtractWarning ExtractWarningCode: type: string enum: - nonconformant_schema - nonconformant_output title: ExtractWarningCode securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Build Extract Schema Source: https://docs.landing.ai/api-reference/tools/ade-build-extract-schema Generate a JSON schema from Markdown using AI. This endpoint analyzes Markdown content and generates a JSON schema suitable for use with the extract endpoint. It can also refine an existing schema based on new documents or iterate on a schema based on prompt instructions. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/build-schema`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/extract/build-schema openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/extract/build-schema: post: tags: - Tools summary: ADE Build Extract Schema description: |- Generate a JSON schema from Markdown using AI. This endpoint analyzes Markdown content and generates a JSON schema suitable for use with the extract endpoint. It can also refine an existing schema based on new documents or iterate on a schema based on prompt instructions. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/extract/build-schema`. operationId: tool_ade_build_schema_v1_ade_extract_build_schema_post requestBody: content: multipart/form-data: schema: $ref: '#/components/schemas/BuildSchemaRequest' required: true responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/BuildSchemaResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: >- curl -X POST 'https://api.va.landing.ai/v1/ade/extract/build-schema' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdowns=@markdown.md' \ -F 'model=extract-latest' \ -F 'prompt=Extract invoice fields including vendor, date, and total amount' - lang: Python label: Python source: >- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/extract/build-schema' # Prepare files and data files = [('markdowns', open('markdown.md', 'rb'))] data = { 'model': 'extract-latest', 'prompt': 'Extract invoice fields including vendor, date, and total amount' } response = requests.post(url, files=files, data=data, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: >- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdowns', fs.createReadStream('markdown.md')); form.append('model', 'extract-latest'); form.append('prompt', 'Extract invoice fields including vendor, date, and total amount'); axios.post('https://api.va.landing.ai/v1/ade/extract/build-schema', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: BuildSchemaRequest: properties: model: anyOf: - type: string - type: 'null' title: Model description: >- The version of the model to use for schema generation. Use `extract-latest` to use the latest version. markdowns: anyOf: - items: anyOf: - type: string format: binary - type: string type: array - type: 'null' title: Markdowns description: >- Markdown files or inline content strings to analyze for schema generation. Multiple documents can be provided for better schema coverage. markdown_urls: anyOf: - items: type: string type: array - type: 'null' title: Markdown Urls description: URLs to Markdown files to analyze for schema generation. prompt: anyOf: - type: string - type: 'null' title: Prompt description: Instructions for how to generate or modify the schema. schema: anyOf: - type: string - type: 'null' title: Schema description: Existing JSON schema to iterate on or refine. type: object title: BuildSchemaRequest BuildSchemaResponse: properties: extraction_schema: type: string title: Extraction Schema description: The generated JSON schema as a string. metadata: $ref: '#/components/schemas/BuildSchemaMetadata' description: The metadata for the schema generation process. type: object required: - extraction_schema - metadata title: BuildSchemaResponse HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError BuildSchemaMetadata: properties: filename: anyOf: - type: string - type: 'null' title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id duration_ms: type: integer title: Duration Ms default: 0 credit_usage: type: number title: Credit Usage default: 0 job_id: type: string title: Job Id default: '' version: anyOf: - type: string - type: 'null' title: Version warnings: items: $ref: '#/components/schemas/ExtractWarning' type: array title: Warnings description: >- Structured warnings from the extraction process. Each warning is an instance of ExtractWarning with 'code' (e.g. 'nonconformant_schema') and 'msg' (human-readable description). Present only for extract versions from extract-20260314 and above that support structured warnings. type: object title: BuildSchemaMetadata ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError ExtractWarning: properties: code: $ref: '#/components/schemas/ExtractWarningCode' description: The type of warning, used to translate to a status code downstream msg: type: string title: Msg description: Human-readable description of the warning with more details type: object required: - code - msg title: ExtractWarning ExtractWarningCode: type: string enum: - nonconformant_schema - nonconformant_output title: ExtractWarningCode securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Split Source: https://docs.landing.ai/api-reference/tools/ade-split Split classification for documents. This endpoint classifies document sections based on markdown content and split options. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/split`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/split openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/split: post: tags: - Tools summary: ADE Split description: |- Split classification for documents. This endpoint classifies document sections based on markdown content and split options. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/split`. operationId: tool_ade_split_v1_ade_split_post requestBody: content: multipart/form-data: schema: $ref: '#/components/schemas/SplitRequest' required: true responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/SplitResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/split' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@markdown.md' \ -F 'split_class=[{"name": "split type name", "description": "description of split type", "identifier": "unique identifier field"}]' \ -F 'model=split-latest' - lang: Python label: Python source: >- import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/split' # Prepare split classes split_class = [ { 'name': 'split type name', 'description': 'description of split type', 'identifier': 'unique identifier field' } ] # Prepare files and data files = {'markdown': open('markdown.md', 'rb')} data = { 'split_class': json.dumps(split_class), 'model': 'split-latest' } # Run split classification response = requests.post(url, files=files, data=data, headers=headers) # Return the results print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdown', fs.createReadStream('markdown.md')); const splitClass = [ { name: 'split type name', description: 'description of split type', identifier: 'unique identifier field' } ]; form.append('split_class', JSON.stringify(splitClass)); form.append('model', 'split-latest'); axios.post('https://api.va.landing.ai/v1/ade/split', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: SplitRequest: properties: markdown: anyOf: - type: string format: binary - type: string - type: 'null' title: Markdown description: The Markdown file or Markdown content to split. markdown_url: anyOf: - type: string - type: 'null' title: Markdown Url description: The URL to the Markdown file to split. split_class: items: $ref: '#/components/schemas/SplitClass' type: array title: Split Class description: >- List of split classification options/configuration. Can be provided as JSON string in form data. model: anyOf: - type: string - type: 'null' title: Model description: >- Model version to use for split classification. Defaults to the latest version. default: split-20251105 type: object required: - split_class title: SplitRequest description: Request model for split classification endpoint. SplitResponse: properties: splits: items: $ref: '#/components/schemas/SplitData' type: array title: Splits metadata: $ref: '#/components/schemas/SplitMetadata' type: object required: - splits - metadata title: SplitResponse description: Response model for split classification endpoint. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError SplitClass: properties: name: type: string title: Name description: Name of the split classification type description: anyOf: - type: string - type: 'null' title: Description description: Detailed description of what this split type represents identifier: anyOf: - type: string - type: 'null' title: Identifier description: Identifier to partition/group the splits by type: object required: - name title: SplitClass description: Model for split classification option. SplitData: properties: classification: type: string title: Classification identifier: anyOf: - type: string - type: 'null' title: Identifier pages: items: type: integer type: array title: Pages markdowns: items: type: string type: array title: Markdowns type: object required: - classification - identifier - pages - markdowns title: SplitData description: Split data for split classification endpoint. SplitMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id description: Organization ID page_count: type: integer title: Page Count duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id description: Inference history job ID default: '' version: anyOf: - type: string - type: 'null' title: Version description: Model version used for split classification type: object required: - filename - page_count - duration_ms - credit_usage title: SplitMetadata description: Metadata for split classification response. ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Section Source: https://docs.landing.ai/api-reference/tools/ade-section Section parsed markdown into a hierarchical table of contents. This endpoint accepts the markdown output from /ade/parse (with reference anchors) and returns a flat, reading-order list of sections with hierarchy levels and reference ranges. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/section`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/section openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/section: post: tags: - Tools summary: ADE Section description: |- Section parsed markdown into a hierarchical table of contents. This endpoint accepts the markdown output from /ade/parse (with reference anchors) and returns a flat, reading-order list of sections with hierarchy levels and reference ranges. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/section`. operationId: tool_ade_section_v1_ade_section_post requestBody: content: multipart/form-data: schema: $ref: '#/components/schemas/SectionRequest' required: true responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/SectionResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/section' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'markdown=@parsed_output.md' \ -F 'model=section-latest' - lang: Python label: Python source: >- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/section' # Prepare files and data files = {'markdown': open('parsed_output.md', 'rb')} data = { 'model': 'section-latest' } # Run section classification response = requests.post(url, files=files, data=data, headers=headers) # Return the results print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('markdown', fs.createReadStream('parsed_output.md')); form.append('model', 'section-latest'); axios.post('https://api.va.landing.ai/v1/ade/section', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: SectionRequest: properties: markdown: anyOf: - type: string format: binary - type: string - type: 'null' title: Markdown description: >- Parsed markdown with reference anchors (). This is the markdown field from a parse response. markdown_url: anyOf: - type: string - type: 'null' title: Markdown Url description: URL to fetch the markdown from. guidelines: anyOf: - type: string - type: 'null' title: Guidelines description: >- Natural-language instructions to control hierarchy. Examples: 'Group by topic', 'Treat each numbered section as a top-level entry'. model: anyOf: - type: string - type: 'null' title: Model description: Section model version. Defaults to latest. type: object title: SectionRequest description: Request model for section endpoint. SectionResponse: properties: table_of_contents: items: $ref: '#/components/schemas/SectionTOCEntry' type: array title: Table Of Contents table_of_contents_md: type: string title: Table Of Contents Md metadata: $ref: '#/components/schemas/SectionMetadata' type: object required: - table_of_contents - table_of_contents_md - metadata title: SectionResponse description: Response model for section endpoint. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError SectionTOCEntry: properties: title: type: string title: Title level: type: integer title: Level section_number: type: string title: Section Number start_reference: type: string title: Start Reference type: object required: - title - level - section_number - start_reference title: SectionTOCEntry description: A single entry in the flat table of contents. SectionMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id default: '' version: anyOf: - type: string - type: 'null' title: Version type: object required: - filename - duration_ms - credit_usage title: SectionMetadata description: Public metadata for section response. ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Classify Source: https://docs.landing.ai/api-reference/tools/ade-classify Classify the pages of a document into classes you define. This endpoint accepts PDFs, images, and other supported file types (either as a `document` upload or `document_url`) together with a list of `classes`, and returns a classification result for each page. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/classify`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/classify openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/classify: post: tags: - Tools summary: ADE Classify description: |- Classify the pages of a document into classes you define. This endpoint accepts PDFs, images, and other supported file types (either as a `document` upload or `document_url`) together with a list of `classes`, and returns a classification result for each page. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/classify`. operationId: tool_ade_classify_v1_ade_classify_post requestBody: content: multipart/form-data: schema: $ref: '#/components/schemas/ClassifyRequest' required: true responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/ClassifyResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/classify' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'classes=[{"class":"Class 1","description":"Description of Class 1"},{"class":"Class 2","description":"Description of Class 2"}]' \ -F 'document=@document.pdf' - lang: Python label: Python source: >- import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/classify' classes = [ {'class': 'Class 1', 'description': 'Description of Class 1'}, {'class': 'Class 2', 'description': 'Description of Class 2'} ] files = {'document': open('document.pdf', 'rb')} data = {'classes': json.dumps(classes)} response = requests.post(url, files=files, data=data, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('document', fs.createReadStream('document.pdf')); const classes = [ { class: 'Class 1', description: 'Description of Class 1' }, { class: 'Class 2', description: 'Description of Class 2' } ]; form.append('classes', JSON.stringify(classes)); axios.post('https://api.va.landing.ai/v1/ade/classify', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: ClassifyRequest: properties: classes: items: $ref: '#/components/schemas/ClassifyClass' type: array title: Classes description: >- The possible classes that can be assigned to pages in the document. Each entry is an object with a `class` name and an optional `description`. Only one class is assigned per page; unclassifiable pages receive 'unknown'. Can be provided as a JSON string in form data. document: anyOf: - type: string format: binary - type: 'null' title: Document description: >- A file to be classified. Either this parameter or the `document_url` parameter must be provided. document_url: anyOf: - type: string - type: 'null' title: Document Url description: >- The URL of the document to be classified. Either this parameter or the `document` parameter must be provided. model: anyOf: - type: string - type: 'null' title: Model description: Classification model version. Defaults to the latest. type: object required: - classes title: ClassifyRequest ClassifyResponse: properties: classification: items: $ref: '#/components/schemas/ClassificationItem' type: array title: Classification metadata: $ref: '#/components/schemas/ClassifyMetadata' type: object required: - classification - metadata title: ClassifyResponse description: Response model for the classify endpoint. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError ClassifyClass: properties: class: type: string title: Class description: Name of the class. description: anyOf: - type: string - type: 'null' title: Description description: Detailed description of what this class represents. type: object required: - class title: ClassifyClass description: 'A single classification option: a class name plus optional description.' ClassificationItem: properties: class: type: string title: Class description: Predicted class label or 'unknown'. reason: type: string title: Reason description: Reason for the classification (for debugging). default: '' suggested_class: anyOf: - type: string - type: 'null' title: Suggested Class description: Proposed class when the prediction is 'unknown'. page: type: integer title: Page description: Page number (0-based). type: object required: - class - page title: ClassificationItem description: A single page-level classification result. ClassifyMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id page_count: type: integer title: Page Count duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id default: '' version: anyOf: - type: string - type: 'null' title: Version type: object required: - filename - page_count - duration_ms - credit_usage title: ClassifyMetadata description: Metadata for the classify response. ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Parse Jobs Source: https://docs.landing.ai/api-reference/tools/ade-parse-jobs Parse documents asynchronously. This endpoint creates a job that handles the processing for both large documents and large batches of documents. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse/jobs`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json post /v1/ade/parse/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/parse/jobs: post: tags: - Tools summary: ADE Parse Jobs description: |- Parse documents asynchronously. This endpoint creates a job that handles the processing for both large documents and large batches of documents. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse/jobs`. operationId: tool_ade_parse_jobs_v1_ade_parse_jobs_post requestBody: required: true content: multipart/form-data: schema: $ref: '#/components/schemas/AsyncParseRequestWithEncryptedPassword' responses: '202': description: Job queued successfully content: application/json: schema: $ref: '#/components/schemas/JobCreationResponse' example: job_id: 12345678-1234-1234-1234-123456789012 '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' '429': description: Rate limit exceeded security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X POST 'https://api.va.landing.ai/v1/ade/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest' # Set the model (optional) - lang: Python label: Python source: >- import requests import json headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/parse/jobs' # Set the model (optional) data = { 'model': 'dpt-2-latest' } # Upload a document document = open('document.pdf', 'rb') files = {'document': document} response = requests.post(url, files=files, data=data, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const FormData = require('form-data'); const fs = require('fs'); const form = new FormData(); form.append('document', fs.createReadStream('document.pdf')); // Set the model (optional) form.append('model', 'dpt-2-latest'); axios.post('https://api.va.landing.ai/v1/ade/parse/jobs', form, { headers: { 'Authorization': 'Bearer YOUR_API_KEY', ...form.getHeaders() } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: AsyncParseRequestWithEncryptedPassword: properties: model: anyOf: - type: string - type: 'null' title: Model description: The version of the model to use for parsing. document: anyOf: - type: string format: binary - type: 'null' title: Document description: >- A file to be parsed. The file can be a PDF or an image. See the list of supported file types here: https://docs.landing.ai/ade/ade-file-types. Either this parameter or the `document_url` parameter must be provided. document_url: anyOf: - type: string - type: 'null' title: Document Url description: >- The URL to the file to be parsed. The file can be a PDF or an image. See the list of supported file types here: https://docs.landing.ai/ade/ade-file-types. Either this parameter or the `document` parameter must be provided. split: anyOf: - $ref: '#/components/schemas/SplitType' - type: 'null' description: >- If you want to split documents into smaller sections, include the split parameter. Set the parameter to page to split documents at the page level. The splits object in the API output will contain a set of data for each page. password: anyOf: - type: string - type: 'null' title: Password description: >- Password for encrypted document files. If the document is password-protected, provide the password to decrypt and process the document. Ignored for unencrypted documents. custom_prompts: anyOf: - type: string contentMediaType: application/json contentSchema: $ref: '#/components/schemas/CustomPrompts' - type: 'null' title: Custom Prompts description: >- Optional JSON string mapping chunk types to custom parsing prompts. Only the `figure` key is supported, for example '{"figure":"Describe axis labels in detail."}'. output_save_url: anyOf: - type: string - type: 'null' title: Output Save Url description: >- If zero data retention (ZDR) is enabled, you must enter a URL for the parsed output to be saved to. When ZDR is enabled, the parsed content will not be in the API response. type: object title: AsyncParseRequestWithEncryptedPassword JobCreationResponse: properties: job_id: type: string title: Job Id type: object required: - job_id title: JobCreationResponse HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError SplitType: type: string enum: - page const: page title: SplitType ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE List Parse Jobs Source: https://docs.landing.ai/api-reference/tools/ade-list-parse-jobs List all async parse jobs associated with your API key. Returns the list of jobs or an error response. For EU users, use this endpoint: or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse/jobs`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json get /v1/ade/parse/jobs openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/parse/jobs: get: tags: - Tools summary: ADE List Parse Jobs description: >- List all async parse jobs associated with your API key. Returns the list of jobs or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse/jobs`. operationId: tool_ade_list_parse_jobs_v1_ade_parse_jobs_get parameters: - name: page in: query required: false schema: type: integer minimum: 0 description: Page number (0-indexed) default: 0 title: Page description: Page number (0-indexed) - name: pageSize in: query required: false schema: type: integer maximum: 100 minimum: 1 description: Number of items per page default: 10 title: Pagesize description: Number of items per page - name: status in: query required: false schema: anyOf: - enum: - cancelled - completed - failed - pending - processing type: string - type: 'null' description: Filter by job status. title: Status description: Filter by job status. responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/JobsListResponse' '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X GET 'https://api.va.landing.ai/v1/ade/parse/jobs' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = 'https://api.va.landing.ai/v1/ade/parse/jobs' response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const url = 'https://api.va.landing.ai/v1/ade/parse/jobs'; axios.get(url, { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: JobsListResponse: properties: jobs: items: $ref: '#/components/schemas/JobSummary' type: array title: Jobs org_id: anyOf: - type: string - type: 'null' title: Org Id has_more: type: boolean title: Has More default: false type: object required: - jobs title: JobsListResponse description: Response for listing jobs. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError JobSummary: properties: job_id: type: string title: Job Id status: type: string title: Status received_at: type: integer title: Received At created_at: type: integer title: Created At description: >- Unix timestamp (seconds) for when the job was created. Mirrors received_at; exposed so clients have an explicit creation time. default: 0 progress: type: number maximum: 1 minimum: 0 title: Progress description: Job completion as a decimal from 0 (not started) to 1 (complete). failure_reason: anyOf: - type: string - type: 'null' title: Failure Reason type: object required: - job_id - status - received_at - progress title: JobSummary description: Summary of a job for listing. ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # ADE Get Parse Jobs Source: https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs Get the status for an async parse job. Returns the job status or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse/jobs/{job_id}`. ## OpenAPI ````yaml /ade/va_openapi_ade2.json get /v1/ade/parse/jobs/{job_id} openapi: 3.1.0 info: title: >- LandingAI Agentic Document Extraction (ADE) Gen1 API: Parse, Extract, Classify, Split, Section version: 0.1.0 description: >- Convert documents such as PDFs, images, and Office files into structured data with LandingAI's Agentic Document Extraction (ADE) v1 endpoints. Includes Parse (documents to Markdown and structured chunks with grounding), Extract (schema-based field extraction), Classify (page-level classification), Split (separate multi-document files), and Section (hierarchical table of contents), plus asynchronous jobs for parsing and extraction. Documentation: https://docs.landing.ai servers: - url: https://api.va.landing.ai description: Production API security: [] paths: /v1/ade/parse/jobs/{job_id}: get: tags: - Tools summary: ADE Get Parse Jobs description: |- Get the status for an async parse job. Returns the job status or an error response. For EU users, use this endpoint: `https://api.va.eu-west-1.landing.ai/v1/ade/parse/jobs/{job_id}`. operationId: tool_ade_get_parse_jobs_v1_ade_parse_jobs__job_id__get parameters: - name: job_id in: path required: true schema: type: string title: Job Id responses: '200': description: Successful Response content: application/json: schema: $ref: '#/components/schemas/JobStatusResponse' '206': description: There were some pages that failed to be parsed. content: application/json: schema: $ref: '#/components/schemas/JobStatusResponse' '404': description: Job ID not found '422': description: Validation Error content: application/json: schema: $ref: '#/components/schemas/HTTPValidationError' security: - Basic Auth: [] x-codeSamples: - lang: cURL label: cURL source: |- curl -X GET 'https://api.va.landing.ai/v1/ade/parse/jobs/{job_id}' \ -H 'Authorization: Bearer YOUR_API_KEY' - lang: Python label: Python source: |- import requests headers = { 'Authorization': 'Bearer YOUR_API_KEY' } url = f'https://api.va.landing.ai/v1/ade/parse/jobs/{job_id}' response = requests.get(url, headers=headers) print(response.json()) - lang: JavaScript label: Node.js source: |- const axios = require('axios'); const url = `https://api.va.landing.ai/v1/ade/parse/jobs/{jobId}`; axios.get(url, { headers: { 'Authorization': 'Bearer YOUR_API_KEY' } }) .then(response => console.log(response.data)) .catch(error => console.error(error)); components: schemas: JobStatusResponse: properties: job_id: type: string title: Job Id status: type: string title: Status received_at: type: integer title: Received At created_at: type: integer title: Created At description: >- Unix timestamp (seconds) for when the job was created. Mirrors received_at; exposed so clients have an explicit creation time. default: 0 progress: type: number maximum: 1 minimum: 0 title: Progress description: >- Job completion progress as a decimal from 0 to 1, where 0 is not started, 1 is finished, and values between 0 and 1 indicate work in progress. org_id: anyOf: - type: string - type: 'null' title: Org Id version: anyOf: - type: string - type: 'null' title: Version data: anyOf: - $ref: '#/components/schemas/ParseResponse' - $ref: '#/components/schemas/SpreadsheetParseResponse' - type: 'null' title: Data description: >- The parsed output (ParseResponse for documents, SpreadsheetParseResponse for spreadsheets), if the job is complete and the `output_save_url` parameter was not used. output_url: anyOf: - type: string - type: 'null' title: Output Url description: >- The URL to the parsed content. This field contains a URL when the job is complete and either you specified the `output_save_url` parameter or the result is larger than 1MB. When the result exceeds 1MB, the URL is a presigned S3 URL that expires after 1 hour. Each time you GET the job, a new presigned URL is generated. metadata: anyOf: - $ref: '#/components/schemas/ParseMetadata' - type: 'null' failure_reason: anyOf: - type: string - type: 'null' title: Failure Reason type: object required: - job_id - status - received_at - progress title: JobStatusResponse description: Unified response for job status endpoint. HTTPValidationError: properties: detail: items: $ref: '#/components/schemas/ValidationError' type: array title: Detail type: object title: HTTPValidationError ParseResponse: properties: markdown: type: string title: Markdown chunks: items: $ref: '#/components/schemas/ParseChunk' type: array title: Chunks splits: items: $ref: '#/components/schemas/ParseSplit' type: array title: Splits grounding: additionalProperties: anyOf: - $ref: '#/components/schemas/ParseResponseGrounding' - $ref: '#/components/schemas/ParseResponseTableCellGrounding' type: object title: Grounding metadata: $ref: '#/components/schemas/ParseMetadata' type: object required: - markdown - chunks - splits - metadata title: ParseResponse SpreadsheetParseResponse: properties: markdown: type: string title: Markdown description: Full document as HTML with anchor tags and tables chunks: items: $ref: '#/components/schemas/SpreadsheetChunk' type: array title: Chunks description: List of table chunks (HTML) splits: items: $ref: '#/components/schemas/SpreadsheetSplit' type: array title: Splits description: Sheet-based splits metadata: $ref: '#/components/schemas/SpreadsheetParseMetadata' description: Parsing metadata type: object required: - markdown - chunks - splits - metadata title: SpreadsheetParseResponse description: |- Response from /ade/parse-spreadsheet endpoint. Similar structure to ParseResponse but without grounding. ParseMetadata: properties: filename: type: string title: Filename org_id: anyOf: - type: string - type: 'null' title: Org Id page_count: type: integer title: Page Count duration_ms: type: integer title: Duration Ms credit_usage: type: number title: Credit Usage job_id: type: string title: Job Id version: anyOf: - type: string - type: 'null' title: Version failed_pages: items: type: integer type: array title: Failed Pages type: object required: - filename - org_id - page_count - duration_ms - credit_usage - job_id - version title: ParseMetadata ValidationError: properties: loc: items: anyOf: - type: string - type: integer type: array title: Location msg: type: string title: Message type: type: string title: Error Type type: object required: - loc - msg - type title: ValidationError ParseChunk: properties: markdown: type: string title: Markdown type: type: string title: Type id: type: string title: Id grounding: $ref: '#/components/schemas/ParseGrounding' type: object required: - markdown - type - id - grounding title: ParseChunk ParseSplit: properties: class: type: string title: Class identifier: type: string title: Identifier pages: items: type: integer type: array title: Pages markdown: type: string title: Markdown chunks: items: type: string type: array title: Chunks type: object required: - class - identifier - pages - markdown - chunks title: ParseSplit ParseResponseGrounding: properties: box: $ref: '#/components/schemas/ParseGroundingBox' page: type: integer title: Page type: $ref: '#/components/schemas/GroundingType' confidence: anyOf: - type: number - type: 'null' title: Confidence low_confidence_spans: items: $ref: '#/components/schemas/Patch' type: array title: Low Confidence Spans type: object required: - box - page - type title: ParseResponseGrounding ParseResponseTableCellGrounding: properties: box: $ref: '#/components/schemas/ParseGroundingBox' page: type: integer title: Page type: $ref: '#/components/schemas/GroundingType' confidence: anyOf: - type: number - type: 'null' title: Confidence position: anyOf: - $ref: '#/components/schemas/ParseResponseTableCellGroundingPosition' - type: 'null' type: object required: - box - page - type title: ParseResponseTableCellGrounding SpreadsheetChunk: properties: markdown: type: string title: Markdown description: >- Chunk content as HTML table with anchor tag (for tables) or parsed markdown content (for chunks from images) type: type: string title: Type description: >- Chunk type: 'table' for spreadsheet tables, or types from /parse (text, table, figure, form, etc.) for chunks derived from embedded images id: type: string title: Id description: >- Chunk ID - format: '{sheet_name}-{cell_range}' for tables, '{sheet_name}-image-{index}-{anchor_cell}-chunk-{i}-{type}' for parsed image chunks grounding: anyOf: - $ref: '#/components/schemas/ParseGrounding' - type: 'null' description: >- Visual grounding coordinates from /parse API (only for chunks derived from embedded images) type: object required: - markdown - type - id title: SpreadsheetChunk description: |- Chunk from spreadsheet parsing. Can represent: - Table chunks from spreadsheet cells - Parsed content chunks from embedded images (text, table, figure, etc.) SpreadsheetSplit: properties: class: type: string title: Class description: >- Split class: 'page' for per-sheet splits, 'full' for single split with all content identifier: type: string title: Identifier description: >- Split identifier: sheet name for 'page' splits, 'full' for full split sheets: items: type: integer type: array title: Sheets description: >- Sheet indices: single element for 'page' splits, all indices for 'full' split markdown: type: string title: Markdown description: Combined markdown for this split chunks: items: type: string type: array title: Chunks description: Chunk IDs in this split type: object required: - class - identifier - sheets - markdown - chunks title: SpreadsheetSplit description: |- Sheet-based split from spreadsheet parsing. Similar to ParseSplit but grouped by sheet instead of page. Supports both 'page' (per-sheet) and 'full' (all sheets) split types. SpreadsheetParseMetadata: properties: filename: type: string title: Filename description: Original filename org_id: anyOf: - type: string - type: 'null' title: Org Id description: Organization ID sheet_count: type: integer title: Sheet Count description: Number of sheets processed total_rows: type: integer title: Total Rows description: Total rows across all sheets total_cells: type: integer title: Total Cells description: Total non-empty cells across all sheets total_chunks: type: integer title: Total Chunks description: Total chunks (tables + images) extracted total_images: type: integer title: Total Images description: Total images extracted default: 0 duration_ms: type: integer title: Duration Ms description: Processing duration in milliseconds credit_usage: type: number title: Credit Usage description: Credits charged default: 0 job_id: type: string title: Job Id description: Inference history job ID default: '' version: anyOf: - type: string - type: 'null' title: Version description: Model version for parsing images type: object required: - filename - sheet_count - total_rows - total_cells - total_chunks - duration_ms title: SpreadsheetParseMetadata description: Metadata for spreadsheet parsing result. ParseGrounding: properties: box: $ref: '#/components/schemas/ParseGroundingBox' page: type: integer title: Page type: object required: - box - page title: ParseGrounding ParseGroundingBox: properties: left: type: number title: Left top: type: number title: Top right: type: number title: Right bottom: type: number title: Bottom type: object required: - left - top - right - bottom title: ParseGroundingBox GroundingType: type: string enum: - chunkLogo - chunkCard - chunkAttestation - chunkScanCode - chunkForm - chunkTable - chunkFigure - chunkText - chunkMarginalia - chunkTitle - chunkPageHeader - chunkPageFooter - chunkPageNumber - chunkKeyValue - table - tableCell title: GroundingType Patch: properties: text: type: string title: Text span: prefixItems: - type: integer - type: integer type: array maxItems: 2 minItems: 2 title: Span confidence: type: number title: Confidence type: object required: - text - span - confidence title: Patch ParseResponseTableCellGroundingPosition: properties: row: type: integer title: Row col: type: integer title: Col rowspan: type: integer title: Rowspan colspan: type: integer title: Colspan chunk_id: type: string title: Chunk Id type: object required: - row - col - rowspan - colspan - chunk_id title: ParseResponseTableCellGroundingPosition securitySchemes: Basic Auth: type: http description: >- Your unique API key for authentication. Get your API key here: https://va.landing.ai/settings/api-key. If using the EU endpoint, get your API key here: https://va.eu-west-1.landing.ai/settings/api-key. scheme: bearer bearerFormat: Basic ```` # Code Examples and Resources Source: https://docs.landing.ai/ade/ade-code-examples-resources Browse ready-to-use code samples and sample projects for common document processing tasks. Use the resources below to access practical, ready-to-use code samples for common document processing use cases. Whether you need end-to-end examples or specific code snippets, these resources help you implement Agentic Document Extraction quickly. Explore end-to-end examples for common document processing workflows. Browse code samples with examples for the Python and TypeScript libraries. Some of these examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client libraries. Before running a script, set your API key and install the library and any required dependencies. # Parse a Directory of Documents Source: https://docs.landing.ai/ade/ade-parse-directory-sample Loop through a local folder and call the parse API on each supported file to process documents in bulk. ## Overview Parse all documents in a folder by iterating through files and calling the parse API for each supported file type. These examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client library. Before running a script, set your API key and install the library and any required dependencies. ## Scripts ```python Python [expandable] theme={null} from pathlib import Path from landingai_ade import LandingAIADE # Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) client = LandingAIADE() # Replace "data/" with your folder path data_folder = Path("data/") for filepath in data_folder.glob("*"): # Adjust file types as needed for your use case if filepath.suffix.lower() in ['.pdf', '.png', '.jpg', '.jpeg']: print(f"Processing: {filepath.name}") response = client.parse( document=filepath, model="dpt-2-latest" ) print(response.chunks) # Save markdown output (useful if you plan to run extract on the markdown) output_md = filepath.stem + ".md" with open(output_md, "w", encoding="utf-8") as f: f.write(response.markdown) ``` ```typescript TypeScript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; import path from "path"; // Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); // Replace with your folder path containing documents to parse const dataFolder = "data/"; const files = fs.readdirSync(dataFolder); for (const filename of files) { const filepath = path.join(dataFolder, filename); const fileExt = path.extname(filepath).toLowerCase(); // Adjust file types as needed for your use case if (['.pdf', '.png', '.jpg', '.jpeg'].includes(fileExt)) { console.log(`Processing: ${filename}`); const response = await client.parse({ document: fs.createReadStream(filepath), model: "dpt-2-latest" }); console.log(response.chunks); // Save Markdown output (useful if you plan to run extract on the Markdown) const outputMd = path.basename(filepath, fileExt) + ".md"; fs.writeFileSync(outputMd, response.markdown, "utf-8"); } } ``` # Async Parse: Processing Multiple Documents Concurrently Source: https://docs.landing.ai/ade/ade-parse-async-sample Process multiple documents concurrently with async parsing to cut total processing time. ## Overview Process multiple documents concurrently to significantly reduce total processing time compared to sequential requests. These examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client library. Before running a script, set your API key and install the library and any required dependencies. Use AsyncLandingAIADE for async document processing TypeScript TypeScript } href="#typescript" > Use concurrent parsing with Promise.all() or p-limit ## Python Use `AsyncLandingAIADE` when you need to process many lightweight documents (such as invoices, receipts, or forms) efficiently. This async client allows you to send multiple parse requests concurrently using Python's `asyncio`, which significantly reduces total processing time compared to sequential requests. The async approach lets you send multiple requests in parallel. While one document is being processed, another request can be sent. The API server handles the actual document processing in the background. To avoid exceeding the pages per hour limits and receiving `429` errors, use a client-side rate limiter like `aiolimiter` to control concurrency. ```python [expandable] theme={null} import asyncio from pathlib import Path from landingai_ade import AsyncLandingAIADE # Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) client = AsyncLandingAIADE() async def main() -> None: response = await client.parse( document=Path("path/to/file"), model="dpt-2-latest" ) print(response.chunks) # Save markdown output (useful if you plan to run extract on the markdown) with open("output.md", "w", encoding="utf-8") as f: f.write(response.markdown) asyncio.run(main()) ``` ## TypeScript Use concurrent parsing when you need to process many lightweight documents (such as invoices, receipts, or forms) efficiently. The TypeScript library's methods are already asynchronous, allowing you to send multiple parse requests concurrently using JavaScript's `Promise.all()` or `Promise.allSettled()`. This significantly reduces total processing time compared to sequential requests. The concurrent approach lets you send multiple requests in parallel. While one document is being processed, another request can be sent. The API server handles the actual document processing in the background. To avoid exceeding the pages per hour limits and receiving `429` errors, use a concurrency control library like `p-limit` to limit the number of simultaneous requests. ### Basic Concurrent Parsing ```typescript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; import path from "path"; // Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); async function parseMultipleDocuments() { // Replace with your folder path containing documents to parse const dataFolder = "data/"; const files = fs.readdirSync(dataFolder); // Filter for file types (adjust as needed for your use case) const documentFiles = files.filter(filename => { const fileExt = path.extname(filename).toLowerCase(); return ['.pdf', '.png', '.jpg', '.jpeg'].includes(fileExt); }); // Parse all documents concurrently const parsePromises = documentFiles.map(filename => { const filepath = path.join(dataFolder, filename); return client.parse({ document: fs.createReadStream(filepath), model: "dpt-2-latest" }).then(response => ({ filename, response })).catch(error => ({ filename, error: error.message })); }); // Wait for all parsing to complete const results = await Promise.all(parsePromises); // Process results for (const result of results) { if ('error' in result) { console.error(`Failed to parse ${result.filename}: ${result.error}`); } else { console.log(`Successfully parsed ${result.filename}`); // Save Markdown output const outputMd = path.basename(result.filename, path.extname(result.filename)) + ".md"; fs.writeFileSync(outputMd, result.response.markdown, "utf-8"); } } } parseMultipleDocuments(); ``` ### Concurrent Parsing with Rate Limiting To control concurrency and avoid rate limits, use the `p-limit` library: ```bash theme={null} npm install p-limit ``` ```typescript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; import path from "path"; import pLimit from "p-limit"; // Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); // Adjust concurrency limit as needed to avoid rate limits const limit = pLimit(5); async function parseMultipleDocumentsWithRateLimit() { // Replace with your folder path containing documents to parse const dataFolder = "data/"; const files = fs.readdirSync(dataFolder); // Filter for file types (adjust as needed for your use case) const documentFiles = files.filter(filename => { const fileExt = path.extname(filename).toLowerCase(); return ['.pdf', '.png', '.jpg', '.jpeg'].includes(fileExt); }); // Parse all documents with concurrency control const parsePromises = documentFiles.map(filename => { // Wrap each parse call with the rate limiter return limit(async () => { const filepath = path.join(dataFolder, filename); console.log(`Parsing ${filename}...`); try { const response = await client.parse({ document: fs.createReadStream(filepath), model: "dpt-2-latest" }); // Save Markdown output const outputMd = path.basename(filename, path.extname(filename)) + ".md"; fs.writeFileSync(outputMd, response.markdown, "utf-8"); console.log(`Successfully parsed ${filename}`); return { filename, success: true }; } catch (error) { console.error(`Failed to parse ${filename}: ${error.message}`); return { filename, success: false, error: error.message }; } }); }); // Wait for all parsing to complete const results = await Promise.all(parsePromises); // Summary const successful = results.filter(r => r.success).length; const failed = results.filter(r => !r.success).length; console.log(`\nCompleted: ${successful} successful, ${failed} failed`); } parseMultipleDocumentsWithRateLimit(); ``` # Visualize Parsed Chunks: Draw Bounding Boxes Source: https://docs.landing.ai/ade/ade-parse-visualize-sample Draw color-coded bounding boxes on your document to see how each chunk type was parsed. ## Overview Use this script to visualize parsed chunks by drawing color-coded bounding boxes on your document. Each chunk type uses a distinct color, making it easy to see how the document was parsed. The script identifies [chunk types](./ade-chunk-types) and table cells. For PDFs, the script creates a separate annotated PNG for each page (`page_1_annotated.png`, `page_2_annotated.png`). For image files, the script creates a single `page_annotated.png`. The image below shows an example output with bounding boxes drawn on the first page of a PDF (Python library): Annotated PDF Page These examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client library. Before running a script, set your API key and install the library and any required dependencies. ## Scripts ```python Python [expandable] theme={null} from pathlib import Path from landingai_ade import LandingAIADE from PIL import Image, ImageDraw import pymupdf # Define colors for each chunk type CHUNK_TYPE_COLORS = { "chunkText": (40, 167, 69), # Green "chunkTable": (0, 123, 255), # Blue "chunkMarginalia": (111, 66, 193), # Purple "chunkFigure": (255, 0, 255), # Magenta "chunkLogo": (144, 238, 144), # Light green "chunkCard": (255, 165, 0), # Orange "chunkAttestation": (0, 255, 255), # Cyan "chunkScanCode": (255, 193, 7), # Yellow "chunkForm": (220, 20, 60), # Red "tableCell": (173, 216, 230), # Light blue "table": (70, 130, 180), # Steel blue } def draw_bounding_boxes(parse_response, document_path): """Draw bounding boxes around each chunk.""" def create_annotated_image(image, groundings, page_num=0): """Create an annotated image with grounding boxes and labels.""" annotated_img = image.copy() draw = ImageDraw.Draw(annotated_img) img_width, img_height = image.size for gid, grounding in groundings.items(): # Check if grounding belongs to this page (for PDFs) if grounding.page != page_num: continue box = grounding.box # Extract coordinates from box left, top, right, bottom = box.left, box.top, box.right, box.bottom # Convert to pixel coordinates x1 = int(left * img_width) y1 = int(top * img_height) x2 = int(right * img_width) y2 = int(bottom * img_height) # Draw bounding box color = CHUNK_TYPE_COLORS.get(grounding.type, (128, 128, 128)) # Default to gray draw.rectangle([x1, y1, x2, y2], outline=color, width=3) # Draw label background and text label = f"{grounding.type}:{gid}" label_y = max(0, y1 - 20) draw.rectangle([x1, label_y, x1 + len(label) * 8, y1], fill=color) draw.text((x1 + 2, label_y + 2), label, fill=(255, 255, 255)) return annotated_img if document_path.suffix.lower() == '.pdf': pdf = pymupdf.open(document_path) total_pages = len(pdf) base_name = document_path.stem for page_num in range(total_pages): page = pdf[page_num] pix = page.get_pixmap(matrix=pymupdf.Matrix(2, 2)) # 2x scaling img = Image.frombytes("RGB", [pix.width, pix.height], pix.samples) # Create and save annotated image annotated_img = create_annotated_image(img, parse_response.grounding, page_num) annotated_path = f"page_{page_num + 1}_annotated.png" annotated_img.save(annotated_path) print(f"Annotated image saved to: {annotated_path}") pdf.close() else: # Load image file directly img = Image.open(document_path) if img.mode != "RGB": img = img.convert("RGB") # Create and save annotated image annotated_img = create_annotated_image(img, parse_response.grounding) annotated_path = "page_annotated.png" annotated_img.save(annotated_path) print(f"Annotated image saved to: {annotated_path}") return None # Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) client = LandingAIADE() # Replace with your file path document_path = Path("/path/to/file/document") # Parse the document print("Parsing document...") parse_response = client.parse( document=document_path, model="dpt-2-latest" ) print("Parsing complete!") # Draw bounding boxes and create annotated images draw_bounding_boxes(parse_response, document_path) ``` ```typescript TypeScript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; import path from "path"; import { createCanvas, loadImage } from "canvas"; import { pdf } from "pdf-to-img"; // Define colors for each chunk type const CHUNK_TYPE_COLORS: Record = { chunkText: [40, 167, 69], // Green chunkTable: [0, 123, 255], // Blue chunkMarginalia: [111, 66, 193], // Purple chunkFigure: [255, 0, 255], // Magenta chunkLogo: [144, 238, 144], // Light green chunkCard: [255, 165, 0], // Orange chunkAttestation: [0, 255, 255], // Cyan chunkScanCode: [255, 193, 7], // Yellow chunkForm: [220, 20, 60], // Red tableCell: [173, 216, 230], // Light blue table: [70, 130, 180], // Steel blue }; function rgbToString(rgb: [number, number, number]): string { return `rgb(${rgb[0]}, ${rgb[1]}, ${rgb[2]})`; } async function drawAnnotations( imageBuffer: Buffer, groundings: any, pageNum: number ): Promise { // Load the rendered PDF page image const image = await loadImage(imageBuffer); const canvas = createCanvas(image.width, image.height); const ctx = canvas.getContext("2d"); // Draw the original PDF page ctx.drawImage(image, 0, 0); const imgWidth = canvas.width; const imgHeight = canvas.height; // Draw bounding boxes for each grounding for (const [gid, grounding] of Object.entries(groundings)) { const g = grounding as any; // Check if grounding belongs to this page if (g.page !== pageNum) { continue; } const box = g.box; // Convert normalized coordinates to pixel coordinates const x1 = Math.floor(box.left * imgWidth); const y1 = Math.floor(box.top * imgHeight); const x2 = Math.floor(box.right * imgWidth); const y2 = Math.floor(box.bottom * imgHeight); // Get color for this chunk type (default to gray) const color = CHUNK_TYPE_COLORS[g.type] || [128, 128, 128]; const colorString = rgbToString(color); // Draw bounding box ctx.strokeStyle = colorString; ctx.lineWidth = 3; ctx.strokeRect(x1, y1, x2 - x1, y2 - y1); // Draw label background and text const label = `${g.type}:${gid.substring(0, 8)}`; const labelY = Math.max(0, y1 - 20); ctx.fillStyle = colorString; ctx.fillRect(x1, labelY, label.length * 8, 20); ctx.fillStyle = "white"; ctx.font = "12px sans-serif"; ctx.fillText(label, x1 + 2, labelY + 14); } return canvas.toBuffer("image/png"); } async function drawBoundingBoxes(parseResponse: any, documentPath: string) { const fileExtension = path.extname(documentPath).toLowerCase(); if (fileExtension === ".pdf") { // Convert PDF to images using pdf-to-img const document = await pdf(documentPath, { scale: 2.0 }); let pageNum = 0; for await (const page of document) { console.log(`Processing page ${pageNum + 1}...`); // Draw annotations on the rendered PDF page const annotatedBuffer = await drawAnnotations( page, parseResponse.grounding, pageNum ); // Save annotated image const outputPath = `page_${pageNum + 1}_annotated.png`; fs.writeFileSync(outputPath, annotatedBuffer); console.log(`Annotated image saved to: ${outputPath}`); pageNum++; } } else { // Load image file directly const image = await loadImage(documentPath); const canvas = createCanvas(image.width, image.height); const ctx = canvas.getContext("2d"); // Draw the image ctx.drawImage(image, 0, 0); const imgWidth = canvas.width; const imgHeight = canvas.height; // Draw bounding boxes for page 0 for (const [gid, grounding] of Object.entries(parseResponse.grounding)) { const g = grounding as any; if (g.page !== 0) continue; const box = g.box; const x1 = Math.floor(box.left * imgWidth); const y1 = Math.floor(box.top * imgHeight); const x2 = Math.floor(box.right * imgWidth); const y2 = Math.floor(box.bottom * imgHeight); const color = CHUNK_TYPE_COLORS[g.type] || [128, 128, 128]; const colorString = rgbToString(color); ctx.strokeStyle = colorString; ctx.lineWidth = 3; ctx.strokeRect(x1, y1, x2 - x1, y2 - y1); const label = `${g.type}:${gid.substring(0, 8)}`; const labelY = Math.max(0, y1 - 20); ctx.fillStyle = colorString; ctx.fillRect(x1, labelY, label.length * 8, 20); ctx.fillStyle = "white"; ctx.font = "12px sans-serif"; ctx.fillText(label, x1 + 2, labelY + 14); } // Save annotated image const buffer = canvas.toBuffer("image/png"); fs.writeFileSync("page_annotated.png", buffer); console.log("Annotated image saved to: page_annotated.png"); } } // Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); async function visualizeChunks() { // Replace with your file path const documentPath = "/path/to/file/document"; // Parse the document console.log("Parsing document..."); const parseResponse = await client.parse({ document: fs.createReadStream(documentPath), model: "dpt-2-latest" }); console.log("Parsing complete!"); // Draw bounding boxes and create annotated images await drawBoundingBoxes(parseResponse, documentPath); } visualizeChunks(); ``` # Save Parsed Chunks as Images Source: https://docs.landing.ai/ade/ade-parse-save-chunks-images-sample Save each parsed chunk as a separate PNG to build datasets or analyze chunk quality. ## Overview Use this script to extract and save each parsed chunk as a separate PNG. This is useful for building datasets, analyzing chunk quality, or processing individual document regions. These examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client library. Before running a script, set your API key and install the library and any required dependencies. ## Scripts ```python Python [expandable] theme={null} from pathlib import Path from datetime import datetime from landingai_ade import LandingAIADE from PIL import Image import pymupdf def save_chunks_as_images(parse_response, document_path, output_base_dir="groundings"): """Save each parsed chunk as a separate image file.""" # Create timestamped output directory timestamp = datetime.now().strftime("%Y%m%d_%H%M%S") document_name = Path(document_path).stem output_dir = Path(output_base_dir) / f"{document_name}_{timestamp}" def save_page_chunks(image, chunks, page_num): """Save all chunks for a specific page.""" img_width, img_height = image.size # Create page-specific directory page_dir = output_dir / f"page_{page_num}" page_dir.mkdir(parents=True, exist_ok=True) for chunk in chunks: # Check if chunk belongs to this page if chunk.grounding.page != page_num: continue box = chunk.grounding.box # Convert normalized coordinates to pixel coordinates x1 = int(box.left * img_width) y1 = int(box.top * img_height) x2 = int(box.right * img_width) y2 = int(box.bottom * img_height) # Crop the chunk region chunk_img = image.crop((x1, y1, x2, y2)) # Save with descriptive filename filename = f"{chunk.type}.{chunk.id}.png" output_path = page_dir / filename chunk_img.save(output_path) print(f"Saved chunk: {output_path}") if document_path.suffix.lower() == '.pdf': pdf = pymupdf.open(document_path) total_pages = len(pdf) for page_num in range(total_pages): page = pdf[page_num] pix = page.get_pixmap(matrix=pymupdf.Matrix(2, 2)) # 2x scaling for clarity img = Image.frombytes("RGB", [pix.width, pix.height], pix.samples) # Save chunks for this page save_page_chunks(img, parse_response.chunks, page_num) pdf.close() else: # Load image file directly img = Image.open(document_path) if img.mode != "RGB": img = img.convert("RGB") # Save chunks for single page save_page_chunks(img, parse_response.chunks, 0) print(f"\nAll chunks saved to: {output_dir}") return output_dir # Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) client = LandingAIADE() # Replace with your file path document_path = Path("/path/to/file/document") # Parse the document print("Parsing document...") parse_response = client.parse( document=document_path, model="dpt-2-latest" ) print("Parsing complete!") # Save chunks as images save_chunks_as_images(parse_response, document_path) ``` ```typescript TypeScript [expandable] theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; import path from "path"; import { createCanvas, loadImage } from "canvas"; import { pdf } from "pdf-to-img"; async function saveChunksAsImages( parseResponse: any, documentPath: string, outputBaseDir: string = "groundings" ) { // Create timestamped output directory const timestamp = new Date().toISOString().replace(/[:.]/g, "-").slice(0, -5); const documentName = path.basename(documentPath, path.extname(documentPath)); const outputDir = path.join(outputBaseDir, `${documentName}_${timestamp}`); async function savePageChunks( imageBuffer: Buffer, chunks: any[], pageNum: number ) { // Load the page image const image = await loadImage(imageBuffer); const imgWidth = image.width; const imgHeight = image.height; // Create page-specific directory const pageDir = path.join(outputDir, `page_${pageNum}`); if (!fs.existsSync(pageDir)) { fs.mkdirSync(pageDir, { recursive: true }); } // Process each chunk for (const chunk of chunks) { // Check if chunk belongs to this page if (chunk.grounding.page !== pageNum) { continue; } const box = chunk.grounding.box; // Convert normalized coordinates to pixel coordinates const x1 = Math.floor(box.left * imgWidth); const y1 = Math.floor(box.top * imgHeight); const x2 = Math.floor(box.right * imgWidth); const y2 = Math.floor(box.bottom * imgHeight); // Calculate crop dimensions const width = x2 - x1; const height = y2 - y1; // Create canvas for cropped chunk const canvas = createCanvas(width, height); const ctx = canvas.getContext("2d"); // Draw the cropped region ctx.drawImage(image, x1, y1, width, height, 0, 0, width, height); // Save with descriptive filename const filename = `${chunk.type}.${chunk.id}.png`; const outputPath = path.join(pageDir, filename); const buffer = canvas.toBuffer("image/png"); fs.writeFileSync(outputPath, buffer); console.log(`Saved chunk: ${outputPath}`); } } const fileExtension = path.extname(documentPath).toLowerCase(); if (fileExtension === ".pdf") { // Convert PDF to images const document = await pdf(documentPath, { scale: 2.0 }); let pageNum = 0; for await (const page of document) { console.log(`Processing page ${pageNum}...`); await savePageChunks(page, parseResponse.chunks, pageNum); pageNum++; } } else { // Load image file directly const imageBuffer = fs.readFileSync(documentPath); await savePageChunks(imageBuffer, parseResponse.chunks, 0); } console.log(`\nAll chunks saved to: ${outputDir}`); return outputDir; } // Initialize client (uses the API key from the VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); async function extractChunks() { // Replace with your file path const documentPath = "/path/to/file/document"; // Parse the document console.log("Parsing document..."); const parseResponse = await client.parse({ document: fs.createReadStream(documentPath), model: "dpt-2-latest" }); console.log("Parsing complete!"); // Save each chunk as a separate image await saveChunksAsImages(parseResponse, documentPath); } extractChunks(); ``` ## Directory Structure for Saved Images Images are saved with this structure: ``` groundings/ └── document_TIMESTAMP/ └── page_0/ └── ChunkType.CHUNK_ID.png ``` Where: * `TIMESTAMP` is the time and date the document was parsed (format: `YYYYMMDD_HHMMSS` for Python, ISO format for TypeScript) * `page_0` is the zero-indexed page number * `ChunkType` is the [chunk type](./ade-chunk-types) * `CHUNK_ID` is the unique chunk identifier (UUID format) Example output: ``` groundings/ └── document_20250117_143022/ ├── page_0/ │ ├── text.c5f81e1b-37d2-46bf-89e1-4983c1a36444.png │ ├── table.a2b91c3d-48e5-4f67-9123-5678abcdef12.png │ └── figure.e9f12345-6789-4abc-def0-123456789abc.png └── page_1/ ├── text.f1a23456-7890-4bcd-ef12-3456789abcde.png └── marginalia.b3c45678-9012-4def-5678-90abcdef1234.png ``` # Parse & Extract Source: https://docs.landing.ai/ade/ade-parse-extract-sample Parse a document and extract specific fields from it using the Python or TypeScript library. ## Overview This tutorial walks you through how to parse a document with the ADE Parse API and extract specific fields from it with the ADE Extract API. This tutorial uses the [ade-python library](./ade-python) and [ade-typescript library](./ade-typescript). In this tutorial, we will: * Parse this PDF: Wire Transfer Form * Extract these fields: **Bank Name** and **Total Invoice Amount** These examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client library. Before running a script, set your API key and install the library and any required dependencies. The scripts have been tested with PDF and PNG files and may work with other file types supported by Agentic Document Extraction. ## 1. Download the Document to Process Download the Wire Transfer Form and save it to a local directory. ## 2. Create the Script Copy the script for your language and save it as `parse-extract.py` or `parse-extract.ts` in the same directory as the PDF. ```python Python [expandable] theme={null} import json from pathlib import Path from landingai_ade import LandingAIADE # Initialize client (uses VISION_AGENT_API_KEY environment variable) client = LandingAIADE() # Define the extraction schema schema = json.dumps({ "type": "object", "properties": { "bank_name": { "description": "The official name of the bank where the account is held.", "x-alternativeNames": ["Name of Bank", "Financial Institution", "Bank"], "type": "string" }, "total_invoice_amount": { "description": "The total monetary amount of the invoice, including all charges and taxes.", "x-alternativeNames": ["Grand Total", "Amount Due", "Invoice Total"], "type": "number" } } }) # Parse the document # save_to is optional, but saves the full parse response, which is useful for # keeping a record and for other downstream processing tasks parse_response = client.parse( document=Path('wire-transfer.pdf'), model='dpt-2-latest', save_to='output' ) # Extract fields from the parsed output extract_response = client.extract( schema=schema, markdown=parse_response.markdown, model='extract-latest' ) # Save the extract results to a JSON file with open('output/wire-transfer_extract_output.json', 'w') as f: json.dump(extract_response.to_dict(), f, indent=2) ``` ```typescript TypeScript [expandable] theme={null} import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; // Initialize client (uses VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); // Define the extraction schema const schema = JSON.stringify({ type: "object", properties: { bank_name: { description: "The official name of the bank where the account is held.", "x-alternativeNames": ["Name of Bank", "Financial Institution", "Bank"], type: "string" }, total_invoice_amount: { description: "The total monetary amount of the invoice, including all charges and taxes.", "x-alternativeNames": ["Grand Total", "Amount Due", "Invoice Total"], type: "number" } } }); // Parse the document // saveTo is optional, but saves the full parse response, which is useful for // keeping a record and for other downstream processing tasks const parseResponse = await client.parse({ document: fs.createReadStream("wire-transfer.pdf"), model: "dpt-2-latest", saveTo: "output" }); // Extract fields from the parsed output const extractResponse = await client.extract({ schema: schema, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Save the extract results to a JSON file fs.mkdirSync("output", { recursive: true }); fs.writeFileSync( "output/wire-transfer_extract_output.json", JSON.stringify(extractResponse, null, 2) ); ``` ## 3. Run the Script Run the script from the same directory: ```bash Run Python theme={null} python parse-extract.py ``` ```bash Run TypeScript theme={null} npx tsx parse-extract.ts ``` ## 4. View Extraction Output The results are saved to an `output` folder in the same directory. View the extracted fields and metadata in `wire-transfer_extract_output.json`. ```json [expandable] theme={null} { "extraction": { "bank_name": "JPMorgan Chase Bank, N.A.", "total_invoice_amount": 15750.0 }, "extraction_metadata": { "bank_name": { "references": [ "4f64f8d9-ff3a-4c47-aeb5-2ab6eaa9ce7a" ], "value": "JPMorgan Chase Bank, N.A." }, "total_invoice_amount": { "references": [ "deeb001e-6b3e-4c4e-96b1-6f321521ad4f", "0-h" ], "value": 15750.0 } }, "metadata": { "credit_usage": 0.5396, "duration_ms": 11536, "filename": "upload.md", "job_id": "bec005b58d144096b0525af3aa6ed12d", "org_id": null, "version": "extract-20260314", "fallback_model_version": null, "schema_violation_error": null, "warnings": [] } } ``` ## Next Steps Now that you have a working script, you can: * Replace `wire-transfer.pdf` with any document you want to parse and extract from. * Modify the `schema` dictionary to extract different fields. For guidance, see [Extraction Schema (JSON)](./ade-extract-schema-json). * Use the Playground to build and test a schema before adding it to your code. See [Schema Wizard](./ade-extract-playground). * Link extracted fields back to their locations in the original document. See [Link Extracted Data to Document Locations](./ade-extract-grounding-sample). # Link Extracted Data to Document Locations Source: https://docs.landing.ai/ade/ade-extract-grounding-sample Trace each extracted value back to its location in the source document using extraction metadata. ## Overview When you run the ADE Extract API, the response includes an `extraction_metadata` field with reference IDs that connect each extracted value back to its location in the original document. This tutorial shows you how to use those references. This tutorial uses the [ade-python library](./ade-python) and [ade-typescript library](./ade-typescript). In this tutorial, we will: * Parse this PDF: Pay Stub * Extract these fields: **Employee Name** and **Gross Pay** * Save a PNG of each extracted field's location * Save bounding box coordinates for each extracted field to a JSON file These examples require the [Python](./ade-python) or [TypeScript](./ade-typescript) client library. Before running a script, set your API key and install the library and any required dependencies. The Python script has been tested with PDF and PNG files and may work with other file types supported by Agentic Document Extraction. The TypeScript script is written specifically for PDF files. If you need to export crops from other file types, use it as a reference and adapt the image export logic. ## 1. Download the Document to Process Download the Pay Stub and save it to a local directory. ## 2. Create the Script Copy the script for your language and save it as `grounding.py` or `grounding.ts` in the same directory as the PDF. ```python Python [expandable] theme={null} import json import pymupdf from pathlib import Path from landingai_ade import LandingAIADE # Initialize client (uses VISION_AGENT_API_KEY environment variable) client = LandingAIADE() # Define the extraction schema schema = json.dumps({ "type": "object", "properties": { "employee_name": { "description": "The employee's full name", "type": "string" }, "gross_pay": { "description": "The gross pay amount", "type": "number" } } }) # Parse the document # save_to is optional, but saves the full parse response, which is useful for # keeping a record and for other downstream processing tasks parse_response = client.parse( document=Path("pay-stub.pdf"), model="dpt-2-latest", save_to="output" ) # Extract data extract_response = client.extract( schema=schema, markdown=parse_response.markdown, model="extract-latest" ) # Save the extraction results with open("output/pay-stub_extract_output.json", "w") as f: json.dump(extract_response.to_dict(), f, indent=2) # Open the PDF for PNG export pdf = pymupdf.open("pay-stub.pdf") # Link each extracted field to its location in the document grounding_results = {} for field_name, field_data in extract_response.extraction_metadata.items(): for chunk_id in field_data["references"]: # Skip table cell IDs not present in grounding if chunk_id not in parse_response.grounding: continue grounding = parse_response.grounding[chunk_id] # Collect extracted value and bounding box coordinates grounding_results[field_name] = { "value": extract_response.extraction[field_name], "page": grounding.page, "location": { "left": round(grounding.box.left, 3), "top": round(grounding.box.top, 3), "right": round(grounding.box.right, 3), "bottom": round(grounding.box.bottom, 3) } } # Crop the chunk and save as a PNG page_image = pdf[grounding.page].get_pixmap(dpi=150) left = int(grounding.box.left * page_image.width) right = int(grounding.box.right * page_image.width) top = int(grounding.box.top * page_image.height) bottom = int(grounding.box.bottom * page_image.height) crop = page_image.pil_image().crop((left, top, right, bottom)) crop.save(f"output/{field_name}.png") pdf.close() # Save grounding results to a JSON file with open("output/pay-stub_grounding_output.json", "w") as f: json.dump(grounding_results, f, indent=2) ``` ```typescript TypeScript [expandable] theme={null} import * as mupdf from "mupdf"; import LandingAIADE, { toFile } from "landingai-ade"; import fs from "fs"; // Initialize client (uses VISION_AGENT_API_KEY environment variable) const client = new LandingAIADE(); // Define the extraction schema const schema = JSON.stringify({ type: "object", properties: { employee_name: { description: "The employee's full name", type: "string" }, gross_pay: { description: "The gross pay amount", type: "number" } } }); // Parse the document // saveTo is optional, but saves the full parse response, which is useful for // keeping a record and for other downstream processing tasks const parseResponse = await client.parse({ document: fs.createReadStream("pay-stub.pdf"), model: "dpt-2-latest", saveTo: "output" }); // Extract data const extractResponse = await client.extract({ schema: schema, markdown: await toFile(Buffer.from(parseResponse.markdown), "document.md"), model: "extract-latest" }); // Save the extraction results fs.mkdirSync("output", { recursive: true }); fs.writeFileSync( "output/pay-stub_extract_output.json", JSON.stringify(extractResponse, null, 2) ); // Open the PDF for PNG export const pdfBuffer = fs.readFileSync("pay-stub.pdf"); const mupdfDoc = mupdf.Document.openDocument(pdfBuffer, "application/pdf").asPDF()!; // Link each extracted field to its location in the document const groundingResults: Record = {}; for (const [fieldName, fieldData] of Object.entries(extractResponse.extraction_metadata)) { for (const chunkId of fieldData.references) { if (!parseResponse.grounding?.[chunkId]) continue; const grounding = parseResponse.grounding[chunkId]; groundingResults[fieldName] = { value: (extractResponse.extraction as Record)[fieldName], page: grounding.page, location: { left: parseFloat(grounding.box.left.toFixed(3)), top: parseFloat(grounding.box.top.toFixed(3)), right: parseFloat(grounding.box.right.toFixed(3)), bottom: parseFloat(grounding.box.bottom.toFixed(3)) } }; // Crop the chunk and save as a PNG const scaleFactor = 150 / 72; const page = mupdfDoc.loadPage(grounding.page); const bounds = page.getBounds(); const fullWidth = Math.round((bounds[2] - bounds[0]) * scaleFactor); const fullHeight = Math.round((bounds[3] - bounds[1]) * scaleFactor); const left = Math.round(grounding.box.left * fullWidth); const top = Math.round(grounding.box.top * fullHeight); const right = Math.round(grounding.box.right * fullWidth); const bottom = Math.round(grounding.box.bottom * fullHeight); const cropPixmap = new mupdf.Pixmap(mupdf.ColorSpace.DeviceRGB, [left, top, right, bottom], false); cropPixmap.clear(255); const device = new mupdf.DrawDevice(mupdf.Matrix.scale(scaleFactor, scaleFactor), cropPixmap); page.run(device, mupdf.Matrix.identity); device.close(); fs.writeFileSync(`output/${fieldName}.png`, cropPixmap.asPNG()); } } // Save grounding results to a JSON file fs.writeFileSync( "output/pay-stub_grounding_output.json", JSON.stringify(groundingResults, null, 2) ); ``` ## 3. Run the Script Run the script from the same directory: ```bash Run Python theme={null} python grounding.py ``` ```bash Run TypeScript theme={null} npx tsx grounding.ts ``` ## 4. View Output The script saves the following files to the `output` folder: | File | Description | | -------------------------------- | ----------------------------------------------------------------- | | `pay-stub_parse_output.json` | Full parse response, including all chunks and grounding data. | | `pay-stub_extract_output.json` | Extraction results, including extracted values and reference IDs. | | `pay-stub_grounding_output.json` | Extracted values and bounding box coordinates for each field. | | `employee_name.png` | Cropped image of the chunk where the employee name was found. | | `gross_pay.png` | Cropped image of the chunk where the gross pay was found. | ### Chunk Coordinates Each entry in `pay-stub_grounding_output.json` includes the page number and bounding box coordinates. Coordinates are normalized values between 0 and 1, relative to the page dimensions: ```json theme={null} { "employee_name": { "value": "JANE HARPER", "page": 0, "location": { "left": 0.08, "top": 0.785, "right": 0.933, "bottom": 0.837 } }, "gross_pay": { "value": 452.43, "page": 0, "location": { "left": 0.306, "top": 0.331, "right": 0.438, "bottom": 0.345 } } } ``` ## Next Steps Now that you have a working script, you can: * Replace `pay-stub.pdf` with any document you want to parse and extract from. * Modify the `schema` dictionary to extract different fields. For guidance, see [Extraction Schema (JSON)](./ade-extract-schema-json). * Use the Playground to build and test a schema before adding it to your code. See [Schema Wizard](./ade-extract-playground). # Changelog Source: https://docs.landing.ai/ade/ade-changelog Learn about updates and new features in ADE. ## Updated DPT-2, Extract, and Split Models New snapshots of DPT-2, ADE Extract, and ADE Split run on an updated underlying model. One of our third-party model providers is retiring the model that earlier snapshots use. Test your own documents against the new snapshots before your organization moves: * ADE Parse: `dpt-2-20260903` * ADE Extract: `extract-20260903` * ADE Split: `split-20260903` * ADE Extract (ADE v2 API): `extract-20260903` * ADE Classify: `classify-20260903` To test a snapshot, set the `model` parameter to its value. The `dpt-2-latest`, `extract-latest`, and `split-latest` aliases do not change yet. ### What Changes * Output is tuned to match earlier snapshots. Some documents return different text or table formatting. * `dpt-2-20260903` does not return confidence scores. The `confidence` field in the Parse response is `null`. ### When Your Organization Moves Organizations on subscription and enterprise plans move to `dpt-2-20260903` and `extract-20260903` on October 7, 2026. After your organization moves, every DPT-2 and extraction model value, including pinned snapshots, runs on the new snapshots. For details, go to [Parsing Models](./ade-parse-models#dpt-2-20260903), [Extraction Model Versions](./ade-extract-models#extract-20260903), [Split Model Versions](./ade-split-models), [v2 Extract Model Version](https://docs.landing.ai/dpt3/extract-input#model-version), and [Classify](./ade-classify). ## Restrict API Access by IP Address Organizations on the Enterprise plan can now restrict their access to the ADE APIs to a set of approved IP addresses. When an allowlist is active, API requests from any other address are rejected. The allowlist applies to every request to the v1 and v2 APIs, no matter which API key is used. It does not restrict the Playground. To enable an allowlist, email [support@landing.ai](mailto:support@landing.ai) with the IPv4 or IPv6 addresses and CIDR ranges to approve. See [IP Address Allowlist](./ip-allowlist). ## ADE Extract Jobs The [ADE Extract Jobs API](./ade-extract-async) is the asynchronous alternative to the standard ADE Extract API. Instead of waiting for a single request to finish, you create a job, receive a `job_id` immediately, and retrieve the extracted fields when the job is complete. Use Extract Jobs for long-running extractions, such as extracting from long documents or when using large, complex schemas. ### Get Started * [Asynchronous Extraction (Extract Jobs)](./ade-extract-async) * [ADE Extract Jobs API reference](https://docs.landing.ai/api-reference/tools/ade-extract-jobs) ## Section Is Now Available in the Playground You can now use [ADE Section](./ade-section) in the [Playground](https://ade.landing.ai/). After you parse a file, add the **Section** tool to your project and ADE Section runs automatically on your files. In the Playground, you can: * Review the generated table of contents as a hierarchical tree, and toggle between **Formatted** and **JSON** views. * Refine the table of contents by submitting natural-language guidelines. * Export a ready-to-use script for the [API](./ade-section#section-with-the-api) or the [ade-python library](./ade-python#section-getting-started). For full details, go to [Section in the Playground](./ade-section#section-in-the-playground). Section in the Playground ADE Section is in Preview. This feature is still in development and may not return accurate results. Do not use this feature in production environments. ## New Config Drop-Down for Parse The **Parse** tool in the [Playground](https://ade.landing.ai/) now includes a **Config** drop-down for selecting the parsing model and applying a custom figure prompt to your project. When you change the model or the prompt, the Playground re-parses every file in the project. For more information, see: * [Set the Model in the Playground](./ade-parse-models#set-the-model-in-the-playground) * [Use Custom Prompts in the Playground](./ade-parse-custom-prompts#use-custom-prompts-in-the-playground) Configure Parse Settings ## Updated Playground Design The Agentic Document Extraction [Playground](https://ade.landing.ai/) has a new look. The updated design makes it easier to load files and get started, and surfaces more resources directly in the left side-navigation panel, including: * **APIs**: Quick access to the ADE API reference * **Plan & Billing**: View and manage your plan and billing information * **Events**: View your processing activity Two new APIs are now available in public preview: * [ADE Classify](#ade-classify) * [ADE Section](#ade-section) ## ADE Classify [ADE Classify](./ade-classify) classifies each page of a document by category. You provide a document and a list of classes, and the API assigns a class to each page concurrently. Use the results to route pages to downstream systems such as [Parse](./parse), [Split](./ade-split), or [Extract](./ade-extract). [Get started with ADE Classify](./ade-classify). ## ADE Section [ADE Section](./ade-section) generates a hierarchical table of contents from a previously parsed document. It accepts the Markdown output from ADE Parse (which contains reference anchors) and returns a flat, reading-order list of sections with their hierarchy levels and chunk references. [Get started with ADE Section](./ade-section). ## A Note About Public Preview These APIs are in Preview. These features are still in development and may not return accurate results. Do not use these features in production environments. ## New Parsing Model Snapshot: dpt-2-20260410 A new snapshot of DPT-2 is now available: `dpt-2-20260410`. `dpt-2-20260410` builds on previous versions with these improvements: * **Improved cell parsing in forms and tables**: Text positioned at different locations within a cell is now captured more completely. * **Improved column alignment in complex tables**: Cell data now more accurately aligns with its corresponding column headers. ### How This Affects Your Results If your code uses `dpt-2-latest` or `dpt-2`, it now points to this new snapshot and your parsing results may change. To receive the latest improvements automatically, continue using a `-latest` alias. To maintain consistent results over time, pin your code to a specific snapshot (for example, `dpt-2-20260302`). For more information, go to [Why Model Versioning Matters](./ade-parse-models#why-model-versioning-matters). This release includes a new extraction model version, an updated ADE Extract API with expanded schema support, the [ADE Build Extract Schema API](./ade-extract-schema-api) for programmatic schema creation, and a new projects experience in the Playground. It also introduces credit usage for AI-powered schema building tools. * [New Extraction Model: extract-20260314](#new-extraction-model-extract-20260314) * [Expanded Extraction Functionality](#expanded-extraction-functionality) * [Build Extract Schema API](#build-extract-schema-api) * [Projects in the Playground](#projects-in-the-playground) * [Schema Building Tools Consume Credits](#schema-building-tools-consume-credits) ## New Extraction Model: extract-20260314 All extraction improvements in this release require model `extract-20260314`. For a full list of what this model enables, see [extract-20260314](./ade-extract-models#extract-20260314). * **If you use `extract-latest`**: no changes needed. You already have access to the new model. * **If you specify a model version in your code**: update it to `extract-20260314` to access these improvements. ## Expanded Extraction Functionality The ADE Extract API no longer has limits on schema length, number of nested levels, or other schema constraints. ## Cross-Page Table Reconstruction Tables that span page breaks are now returned as a single array, with no post-processing needed. ## Long Document Support The ADE Extract API now supports documents of 1,000 or more pages, without splitting or merging files first. ## Build Extract Schema API The new ADE Build Extract Schema API lets you programmatically create and update extraction schemas, providing the same schema-building capabilities as the Playground. * [Build Extract Schema API reference](https://docs.landing.ai/api-reference/tools/ade-build-extract-schema) * [How to use the Build Extract Schema API](./ade-extract-schema-api) ## Projects in the Playground Files in the Playground are now organized into projects. Projects let you group similar documents together and create and apply extraction schemas across multiple documents at once. ## Schema Building Tools Consume Credits Running AI-powered schema building tools consumes credits. This applies to: * The **Refine Schema**, **View Suggested Fields**, and **Write a Schema Prompt** tools in the Playground * The ADE Build Extract Schema API This release changes how subscription plans handle usage beyond the credit allocation for your billing cycle. These changes ensure that exceeding your credits does not disrupt your service. * **No more overage charges.** Purchase prepaid credits in advance to cover usage beyond the credit allocation for your billing cycle. * **Auto Recharge as a buffer.** Automatically purchase credits when your balance falls below a set threshold. * **Explore credits count too.** If you upgraded from an Explore plan on or after April 2, 2026, your unused Explore credits are added to your buffer. Read on for details about each of these changes and other updates in this release. Get all pricing information in [Plans & Billing](./ade-pricing). ## Prepaid Credits Replace Overage Charges Overage charges for subscription plans have been eliminated. Previously, if you exceeded your allocated credits for a billing cycle, you were billed after the fact. You can now purchase "Pay-As-You-Go" credits in advance. If you exceed your allocated credits for a billing cycle, the prepaid credits are used automatically. This change goes into effect for your upcoming billing cycle. To learn more, go to [Overages](./ade-pricing#overages) ## Auto Recharge Now Available on Subscription Plans Auto Recharge was previously available only on the Explore plan. It is now also available on subscription plans. Auto Recharge is enabled by default on subscription plans. When your credit balance falls below a set threshold, credits are purchased automatically. To learn more, go to [Auto Recharge](./auto-recharge). ## Explore Credits Transfer When You Upgrade If you upgrade from a Personal account to a subscription plan on or after April 2, 2026, your unused credits transfer to your new organization and are added to your credit pool. This pool is drawn from if you exceed your credit allocation for a billing cycle, with credits that expire soonest consumed first. To learn more, go to [Upgrade Team Plans](./ade-pricing#upgrade-team-plans). ## Updated Credit Expiration Timeline When you create an Agentic Document Extraction account, you receive a set of free credits. These free credits expire 90 days after you create your account. ## Personal Accounts Are Now Organizations When you create an Agentic Document Extraction account, it is now automatically an organization. If you upgrade to a subscription plan, you keep the same organization. This means you get to keep your API keys, files, and settings. To learn more, go to [Organizations & Members](./ade-members). **Already on a subscription?** Your Personal account and subscription organization remain separate. This ensures that files and data in your Personal organization are not shared with members of your subscription organization. ## Custom Prompts for Figure Descriptions The ADE Parse and ADE Parse Jobs APIs include a new optional `custom_prompts` parameter that lets you tell Agentic Document Extraction how to describe figures during parsing. This is useful when the default figure descriptions do not fit your use case, such as for domain-specific charts or images unique to your organization. Pass your prompt in the `custom_prompts` parameter when calling the [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) or [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) APIs, or using the [Python](https://github.com/landing-ai/ade-python) and [TypeScript](https://github.com/landing-ai/ade-typescript) libraries. The `custom_prompts` parameter is only supported when using DPT-2. For more information, see [Custom Prompts for Figure Descriptions](./ade-parse-custom-prompts). ## SSO Support for SAML 2.0 and OIDC Enterprise plans now support single sign-on (SSO) via SAML 2.0 and OpenID Connect (OIDC). SSO allows your organization to manage Agentic Document Extraction access through your existing identity provider (IdP). To get started, see [Single Sign-On (SSO)](./ade-sso). ## New Parsing Model Snapshots A new snapshot of DPT-2 is now available: `dpt-2-20260302`. `dpt-2-20260302` builds on previous versions with several improvements, including: * **Table boundary detection**: Tables that were previously split into multiple chunks are now correctly identified as a single table. * **Improved large table accuracy**: Large tables are now parsed more accurately. * **Special characters returned as Unicode**: Characters such as asterisks are now returned as their Unicode characters (for example, `*`) rather than as spelled-out strings like `asterisk`. To learn more about parsing models and snapshots, go to [Document Pre-Trained Transformers (Parsing Models)](./ade-parse-models). ### How This Affects Your Results If your code uses `dpt-2-latest` or `dpt-2`, it now points to this new snapshot and your parsing results may change. To receive the latest improvements automatically, continue using a `-latest` alias. To maintain consistent results over time, pin your code to a specific snapshot (for example, `dpt-2-20251103`). For more information, go to [Why Model Versioning Matters](./ade-parse-models#why-model-versioning-matters). ## Parse Password-Protected Files Accounts with [Zero Data Retention (ZDR)](./zdr) enabled can now parse password-protected files. Pass the document's password in the `password` parameter when calling the [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) or [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) APIs, or using the [Python](https://github.com/landing-ai/ade-python) and [TypeScript](https://github.com/landing-ai/ade-typescript) libraries. For more information, go to [Parse Password-Protected Files](./ade-parse-password). ## LandingLens and LandingEdge Documentation Has Moved Documentation for LandingLens and LandingEdge has moved to [landinglens.docs.landing.ai](https://landinglens.docs.landing.ai/). Existing links to docs.landing.ai/landinglens and docs.landing.ai/landingedge will automatically redirect to the new site. ## Extraction Schema Validation Fix The ADE Extract API now correctly validates `anyOf` sub-schemas before processing begins. If a sub-schema within `anyOf` is missing both the `type` and `anyOf` keywords, the API returns a 400 error identifying the invalid path in the schema. Previously, this caused an unexpected extraction failure. For more information about extraction response statuses and errors, go to [Troubleshoot Extraction](./ade-extract-troubleshoot). ## Confidence Scores The parsed results now include **confidence scores** for text, marginalia, card, and table chunks, as well as table cells. Confidence scores measure the confidence level of parsed text in Markdown with respect to the actual text or visual data present in the document. Each score ranges from 0.0 (low confidence) to 1.0 (high confidence). Lower values indicate regions where the model was less certain about the output. The confidence score feature is in Preview. The numeric range and distribution may change as we continue to develop and improve the model. ### Use Confidence Scores in the Playground After parsing a document in the Playground, turn on the **Confidence** toggle (the toggle is only available when using DPT-2). In the **Markdown** tab, the confidence score displays next to the chunk type. Turn on confidence scores ### Review Low-Confidence Sections Low-confidence sections (with scores of 0.95 or lower) are highlighted in yellow in the Playground. Highlighting low-confidence sections helps you quickly identify content that may need review. * **Text, card, marginalia chunks**: Specific text spans within a chunk are highlighted. A single chunk can contain multiple highlighted spans. * **Tables**: Each cell has its own confidence score. If a cell has a low score, the entire cell is highlighted. Low confidence score #### Why is 0.95 the threshold for low confidence scores? The Playground highlights content with confidence scores of 0.95 or lower because this is the threshold used internally to evaluate parsing quality. This threshold works well for general review workflows, but your use case may require a different threshold. When [using the API](./ade-json-response#confidence-score), you can implement custom logic to identify and route content based on confidence scores that match your specific requirements. #### Why don't I see the confidence score for files I uploaded in the past? The confidence score displays for documents parsed on February 12, 2026 or later. If you parsed a document before that date, the Playground does not re-process documents. If you want to see the newest results for a file that you've already parsed, re-upload it to the Playground. ### Use Confidence Scores in the API Response The `grounding` object in the API response includes all the confidence information displayed in the Playground: * Confidence scores for each chunk and table cell * For text chunks with low-confidence spans: the text, confidence score, and character positions (`start`, `end`) for each span This allows you to programmatically identify and route low-confidence content for review in your applications. Learn more in [Confidence Scores](./ade-json-response#confidence-score). DPT-1 will experience a technology change on February 17, 2026 that may affect parsing results, and will be fully deprecated on March 31, 2026. If you are using DPT-1, update your code to use DPT-2. To learn more about DPT models, go to [Document Pre-Trained Transformers (Parsing Models)](./ade-parse-models). ## DPT-1 Underlying Technology Change: February 17, 2026 One of our underlying solution providers for DPT-1 is upgrading their technology on February 17, 2026. While DPT-1 will continue to function, table parsing behavior and results may change for some documents. ## DPT-1 Deprecation: March 31, 2026 Longer term, we plan to deprecate DPT-1. After March 31, 2026, DPT-1 will no longer be supported and will be scheduled for shutdown. ## Impacted Users and Next Steps Check the scenarios below to determine if you are impacted and what action to take. Complete any necessary migration before February 17, 2026. * [Scenario 1: You Specify DPT-1 as the Model Parameter](#scenario-1-you-specify-dpt-1-as-the-model-parameter) * [Scenario 2: You Use the Legacy API Endpoint](#scenario-2-you-use-the-legacy-api-endpoint) * [Scenario 3: You Use the Legacy Python Library](#scenario-3-you-use-the-legacy-python-library) We recommend that you test any changes in staging first, especially if you process table-heavy documents. After testing in staging, deploy changes to production. ### Scenario 1: You Specify DPT-1 as the Model Parameter You are in this scenario if: * You call the `/v1/ade/parse` or `/v1/ade/parse-jobs` endpoint AND * You set the `model` parameter to `dpt-1`, `dpt-1-latest`, or `dpt-1-20250615` **What to do:** Update your code to use `model=dpt-2-latest` or a specific DPT-2 snapshot. For example, run the command below to use the latest snapshot of DPT-2. ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest' ``` ### Scenario 2: You Use the Legacy API Endpoint You are in this scenario if you call the legacy endpoint: `v1/tools/agentic-document-analysis`. **What to do:** 1. Migrate to the `/v1/ade/parse` endpoint. To learn how to use this endpoint, go to [ADE Parse](./parse). 2. When calling the endpoint, use `model=dpt-2-latest` or a specific DPT-2 snapshot. For example, run the command below to use the latest snapshot of DPT-2. ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest' ``` ### Scenario 3: You Use the Legacy Python Library You are in this scenario if you use the legacy `agentic-doc` Python library. **What to do:** 1. Migrate to the [ade-python](https://github.com/landing-ai/ade-python) library. To learn how to use this library, go to [Python Library](./ade-python). 2. Update your code to use `model="dpt-2-latest"` or a specific DPT-2 snapshot when calling the `parse()` function. For example, use this code to use the latest snapshot of DPT-2. ```python theme={null} response = client.parse( document=Path("/path/to/file/document"), model="dpt-2-latest" ) ``` When using the Agentic Document Extraction [Playground](https://ade.landing.ai/), you can now load up to 10 files at once. After opening the Upload dialog box, navigate to and select multiple files or simply drag and drop the files. Upload multiple files ## Parsing Status After loading multiple files into the Playground, a floating dialog box appears in the bottom right corner, showing the parsing progress for each file. If a file fails to process, an error message displays in this area. Parsing status dialog showing upload progress ## Multiple File Upload Not Available with ZDR When [Zero Data Retention](./zdr) (ZDR) is enabled, only one file can be loaded at a time. ## Python and TypeScript Libraries Support Saving Responses to Local Directories The [ade-python](https://github.com/landing-ai/ade-python) and [ade-typescript](https://github.com/landing-ai/ade-typescript) libraries now support saving API responses directly to local directories as JSON files. The save parameter: * Creates the specified directory if it doesn't exist * Saves the response with the filename format: `{input_file}_{method}_output.json` * Works across all three core functions: parse, split, and extract ### Availability * Python library: v1.4.0 (parameter: `save_to`) * TypeScript library: v2.0.0 (parameter: `saveTo`) ### Example These examples show how to save the API response when parsing. ```python Python theme={null} from pathlib import Path from landingai_ade import LandingAIADE client = LandingAIADE() response = client.parse( document=Path("/path/to/document.pdf"), model="dpt-2-latest", save_to="output_folder" # optional: saves as {input_file}_parse_output.json ) ``` ```typescript TypeScript theme={null} import LandingAIADE from "landingai-ade"; import fs from "fs"; const client = new LandingAIADE(); const response = await client.parse({ document: fs.createReadStream("/path/to/document.pdf"), model: "dpt-2-latest", saveTo: "output_folder" // optional: saves as {input_file}_parse_output.json }); ``` For more information, go to [Python Library](./ade-python) or [TypeScript Library](./ade-typescript). ## Table Cell Position Information When you parse documents with tables, the ADE Parse API response now includes row and column position information for each table cell in the `grounding` object. This allows you to map parsed data back to specific cell locations in the original table. Each table cell in the `grounding` object now includes a `position` field with: * `row`: Row position (zero-indexed) * `col`: Column position (zero-indexed) * `rowspan`: Number of rows the cell spans * `colspan`: Number of columns the cell spans * `chunk_id`: Associated chunk identifier **Why this matters:** * **Precise cell mapping**: You can now identify the exact row and column for each piece of data in your table * **Merged cell detection**: The rowspan and colspan values indicate when cells are merged * **Easier data validation**: You can verify that extracted data came from the expected cell location For more information about the grounding object structure, go to [Table Cell Position Information](./ade-json-response#table-cell-position-information). This release includes a new metadata field for tracking extraction model fallbacks, improved HTTP status codes for parse jobs with partial results, improved spreadsheet parsing, and documentation updates to Parse Jobs endpoint names. ## Fallback Model Version Field The ADE Extract API response now includes a `metadata.fallback_model_version` field. This field shows which extraction model was actually used if the API falls back from your requested model. For more information about the response structure, go to [JSON Response for Extraction](./ade-extract-response). ## Parse Jobs: Partial Content Now Returns a 206 Status When you retrieve parse job results with the ADE Get Parse Jobs API, the API now returns a 206 (Partial Content) HTTP status code if some pages failed during processing. The `failed_pages` array and `failure_reason` field that were already in the API response continue to provide details about which pages failed and why. For more information, go to [Troubleshoot Parsing](./ade-parse-troubleshoot#status-206-partial-content). ## Improved Title Detection in Spreadsheets The ADE Parse API now better identifies titles in spreadsheets. When a spreadsheet has a title or text at the top, the API now returns: * The title as a separate text chunk * The table as its own chunk ## You Can Now Resubscribe and Cancel in Interface If you want to resubscribe to or cancel a subscription plan, you can now do so directly in the Agentic Document Extraction interface. For full details, go to [Plans & Billing](./ade-pricing#faqs). ## Updated API Endpoint Names We've updated the names of two Parse Jobs API endpoints: * "List Async Jobs" is now "**ADE List Parse Jobs**" * "Get Async Job Status" is now "**ADE Get Parse Jobs**" This is a documentation-only change. The endpoint URLs have not changed. Your existing API calls will continue to work without any modifications. ## Split Documents with the New Split API (Preview) We're releasing a Preview of the [ADE Split](https://docs.landing.ai/api-reference/tools/ade-split) API, which classifies and separates a parsed document into multiple sub-documents based on Split Rules you define. This is useful when you receive batched documents containing multiple document types or multiple instances of the same document type. For example, a financial institution processing KYC documentation might receive a single PDF containing bank statements, utility bills, and identification documents for a customer. The ADE Split API can automatically classify and separate each document type, enabling downstream processing systems to route each document appropriately. Get the full details in [Split](./ade-split). ADE Split is in Preview. This feature is still in development and may not return accurate results. Do not use this feature in production environments. ### How It Works 1. Parse your document using the [ADE Parse API](https://docs.landing.ai/api-reference/tools/ade-parse) to generate Markdown output 2. Define Split Rules that describe the document types or sections you want to identify 3. Call the ADE Split API with the parsed Markdown and your Split Rules 4. The API returns each classified sub-document with its full Markdown content For the complete workflow, go to [Process Overview](./ade-split#process-overview). ### When to Use Split Use the ADE Split API when you need to: * Separate batched documents containing multiple document types (invoices, receipts, contracts) * Split documents with repeated sections by unique identifiers (multiple pay stubs by date) * Organize multi-section documents into logical parts (academic articles with body, references, supplemental materials) * Route different document types to appropriate downstream systems For more use cases, go to [Example Use Cases](./ade-split#example-use-cases). ### How to Use Split The ADE Split API is available through multiple interfaces: * [Playground](./ade-split#split-in-the-playground): Interactively create and test Split Rules * [API](./ade-split#split-with-the-api): Integrate directly into your applications * [Python Library](./ade-python#split-getting-started): Integrate into Python-based application with our Python library * [TypeScript Library](./ade-typescript#split-getting-started): Integrate into TypeScript-based application with our TypeScript library ## Revamped Playground We've launched a complete redesign to our [Playground](https://ade.landing.ai/my/home)! The updated Playground now guides you through each step of the document processing process: **Parsing**, **Splitting**, and **Extraction**. Simply click a tile to get started! You can now see all the files you've processed on your Playground homepage, including which tools you've run on each file (parse, extract, split). We've also made it easier to get help with Agentic Document Extraction by adding **Product Update** and **Resources** panels. Revamped Playground ## The Parse Jobs API Supports up to 6,000-Page Documents The [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API now supports documents up to 6,000 pages long. Previously, the limit was 1,000 pages. For more information, go to [Rate Limits for ADE Parse Jobs](./ade-parse-async#rate-limits-for-ade-parse-jobs). ## Improved Support for Partial Content with the Parse Jobs API We've improved how the [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API handles partially parsed documents. Previously, if any pages failed to process, the job would fail with status `failed`. Now, the API processes all pages in the document. If some pages fail, the job completes with status `completed`, and the successfully processed pages are returned in the results. The `failed_pages` array in the metadata lists which pages failed, and the `failure_reason` field provides details about the failures. For more information, go to [Troubleshoot Parsing](./ade-parse-troubleshoot#status-206-partial-content). ## The Parse Jobs API Supports Additional Storage Providers for ZDR When calling the [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API with [zero data retention](./zdr) (ZDR) enabled, you must include the `output_save_url` parameter. We have now tested and confirmed support for Amazon S3, Azure Blob Storage, and Google Cloud Storage. Other storage providers that support PUT or CREATE operations via public or presigned URLs may also work. For detailed information, go to [ZDR Requirements](./ade-parse-async#zdr-requirements). ## Credit Rounding Updated Credit usage for the ADE Extract API is now rounded up to the nearest tenth decimal place instead of the nearest whole credit. For example, if a calculation results in 1.67 credits, the cost is now rounded up to 1.7 credits (previously would have been rounded up to 2 credits). For more information, go to [Plans & Billing](./ade-pricing). ## DPT-2 Is Now Generally Available DPT-2, the latest series of [parsing models](./ade-parse-models) for Agentic Document Extraction, is now generally available (GA). As part of going GA, we're releasing this new snapshot: `dpt-2-20251103`. This updated version offers improvements to table parsing, figure captioning, and chunk detection. For more information about parsing models, go to [Document Pre-Trained Transformers (Parsing Models)](./ade-parse-models). ### How This Affects Your API Calls The new snapshot `dpt-2-20251103` is now the default model. If you call the [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) or [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API without specifying a `model` parameter (or if you use `dpt-2-latest`), your API calls will automatically use this latest snapshot. Your parsing results may change with this update due to improvements in table parsing, figure captioning, and chunk detection. ### Choose Your Approach You can choose between two approaches when setting the `model` parameter: **Get automatic improvements**: * Omit the `model` parameter, or set it to `dpt-2-latest` * Your API calls will automatically use the latest snapshot * You'll receive parsing improvements as new snapshots are released * Parsing results may change when new versions are released ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-latest' ``` **Maintain consistent results**: * Set the `model` parameter to a specific snapshot (like `dpt-2-20251103`) * Your parsing results will remain consistent over time * You won't automatically receive improvements from new snapshots ```shell theme={null} curl -X POST 'https://api.va.landing.ai/v1/ade/parse' \ -H 'Authorization: Bearer YOUR_API_KEY' \ -F 'document=@document.pdf' \ -F 'model=dpt-2-20251103' ``` For more information about model versioning and when to use each approach, go to [Model Versions and Snapshots](./ade-parse-models#model-versions-and-snapshots). ## Spreadsheet Support Agentic Document Extraction can now parse the following file types: * CSV (comma-separated values) * XLSX (Microsoft Excel) For more information, go to [Supported File Types](./ade-file-types). ## Credits Are Now Rounded Up Credit usage for the ADE Extract API is now rounded up to the nearest whole credit. For more information, go to [Credit Consumption](./ade-credit-consumption#credit-costs-for-the-extract-api). ## Support for Text Documents & Presentations Agentic Document Extraction can now parse the following file types: * DOC (Word) * DOCX (Word) * PPT (PowerPoint) * PPTX (PowerPoint) * ODT (OpenDocument Text) For more information, go to [Supported File Types](./ade-file-types). ## Document Length Limit Increased to 100 Pages Agentic Document Extraction now supports documents with up to 100 pages in both the [Playground](https://ade.landing.ai/) and via the [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) API. Need to parse longer documents? Use the [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) API to parse documents that are up to 1,000 pages or 1 GB. For more information, go to [Rate Limits](./ade-rate-limits). ## Subscriptions Now Available for EU Users The EU-hosted version of [Agentic Document Extraction](https://ade.eu-west-1.landing.ai/) now offers monthly subscription plans. To see the plans and upgrade, go to the [EU Plans](https://ade.eu-west-1.landing.ai/plan) page. The credit-based monthly subscription plans are designed to deliver more value and features to your team. All EU users start on our pay-as-you-go plan that comes with free credits to help you get started! Once you’re ready for production, upgrade to a monthly subscription plan to get access to these features: * More credits per dollar * Organization management * Role-based access control (RBAC) * API key management ## New APIs for Parsing Large Documents We have released new APIs that allow you to create parsing jobs. These APIs allow you to process large documents without blocking other operations, improving performance and user experience. To learn more about this workflow, go to [Parse Large Files (Parse Jobs)](./ade-parse-async). ### API Reference To learn more, go to the reference pages for new APIs: * [ADE Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-parse-jobs) * [ADE Get Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-get-parse-jobs) * [ADE List Parse Jobs](https://docs.landing.ai/api-reference/tools/ade-list-parse-jobs) ## Document Pre-Trained Transformers: You Can Now Pick a Parsing Model In this release, we're previewing a concept called **Document Pre-Trained Transformer** (DPT). A DPT is the model that powers the parsing capabilities of the ADE Parsing APIs. The DPT identifies document layouts and chunks, then generates descriptive explanations (captions) for those chunks. The Agentic Document Extraction API initially launched with a single DPT model called **DPT-1**. Because there was only one DPT, it was not surfaced to users. We are now introducing **DPT-2**, which offers: * Improved performance for complex tables * Support for new chunk types (including barcodes and ID cards) * More precise captioning for figures With multiple DPT models now available, you can now select a DPT in both the Playground and when calling the API directly. For more information about Document Pre-Trained Transformer models and how to use them, go to [Document Pre-Trained Transformers (Parsing Models)](./ade-parse-models). ## ADE Parse and ADE Extract Are Now Generally Available The [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) and [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) APIs are now Generally Available (GA). We recommend using these endpoints moving forward. ## New Python Library We've launched a new Python library to support extending the Agentic Document Extraction APIs: the [ade-python](https://github.com/landing-ai/ade-python) library. Key benefits: * Support for the [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) and [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) APIs. * Support for setting the **Document Pre-Trained Transformer**. * The library is automatically generated from our API specification, ensuring you have access to the latest endpoints and parameters. * The library is lightweight, which makes it suitable for resource-constrained environments like AWS Lambda functions. ## agentic-doc Library Transitioned to Legacy Status The [agentic-doc](https://github.com/landing-ai/ade-cli/tree/legacy) Python library has been transitioned to legacy status. Migrate to the new [ade-python](https://github.com/landing-ai/ade-python) library, which is now the recommended Python library for Agentic Document Extraction. ## The tools/agentic-document-analysis Endpoint Is Now Legacy This Agentic Document Extraction endpoint has been transitioned to legacy status: `https://api.va.landing.ai/v1/tools/agentic-document-analysis`. Migrate to the new [ADE Parse](https://docs.landing.ai/api-reference/tools/ade-parse) and [ADE Extract](https://docs.landing.ai/api-reference/tools/ade-extract) APIs. ## Separate APIs for Parsing & Extraction In our original launch of Agentic Document Extraction, the field extraction function was part of the parsing function; every time you wanted to run extraction, you had to run parsing, even if you had already parsed the document. We are now introducing a Preview of two new endpoints that separate these functions: **ADE Parse** and **ADE Extract**. These APIs allow you to decouple parsing and extraction workflows for greater flexibility. You can now parse the document once with the **ADE Parse** API, and then use the **ADE Extract** API to run field extraction on that output multiple times. This is helpful if you want to experiment with different extraction schemas or you have multiple extraction tasks. To get detailed information about how to use these new APIs, go to [Parse Documents](./parse) and [Extract](./ade-extract). ## Monthly Subscriptions We’re excited to announce a major update to [Agentic Document Extraction](https://ade.landing.ai/demo/doc-extraction)! We’ve just launched credit-based monthly subscription plans designed to deliver more value and features to your team. Learn more about available plans in [Pricing](./ade-pricing). All users start on our pay-as-you-go plan that comes with free credits to help you get started! Once you’re ready for production, upgrade to a monthly subscription plan to get access to these new features: * More credits per dollar * Organization management * Role-based access control (RBAC) * API key management ## Organization Management Upgrading to a subscription or Enterprise plan automatically creates an organization. An organization contains all of the credits, members, API keys, and settings for the plan. To learn more, go to [Organizations & Members](./ade-members). ## Member Management: Role-Based Access Control (RBAC) Users on subscription and Enterprise plans can invite multiple users to their organization. These plans offer granular member controls, including the ability to: * invite members * assign roles to members that determine what functions they can perform * change member roles * revoke invitations * remove members To learn more, go to [Organizations & Members](./ade-members). ## API Key Management Users on subscription and Enterprise plans can create multiple API keys for their organization. These plans offer granular API key controls, including the ability to: * create API keys * revoke API keys To learn more, go to [API Key](./agentic-api-key). ## Agentic Document Extraction Now Available in Europe Agentic Document Extraction is now available in Europe. To learn more, go to [European Union (EU)](./ade-eu). Agentic Document Extraction in the EU provides: * **Data residency**: All data is stored and processed within the EU * **GDPR compliance**: Coming soon; learn more at our [Security and Data](https://landing.ai/security-at-landingai) page * **Regional performance**: Reduced latency for European users ## Improved Accuracy Agentic Document Extraction now delivers higher accuracy when extracting data from complex tables and multi-column layouts. ## Increased Processing Speed Agentic Document Extraction is now significantly faster than before, so you can process thousands of pages per minute. ## Process Longer Pages We've increased our page limits, so that you can process longer documents. For more information, go to [Rate Limits](./ade-rate-limits). ## Zero Data Retention Users on the Custom plan can enable a zero data retention policy. For more information, [contact us](http://landing.ai/contact-va). ## Consolidated Chunk Types We consolidated these chunk types into `page_header`: * `page_header` * `page_footer` * `page_number` We consolidated these chunk types into `form`: * `form` * `key_value` For more information, go to [Chunk Types](./ade-chunk-types).